
Why One Model Is Never Enough
Every generative video model has a personality. Some are lyrical with landscapes and terrible with hands. Some nail stylized motion but flatten faces into wax. Some render product shots with commercial-grade polish and fall apart the moment a character has to walk and talk in the same take. When you commit a whole project to a single model, you inherit its weaknesses on every single shot — and you spend your edit trying to hide the same flaw over and over.
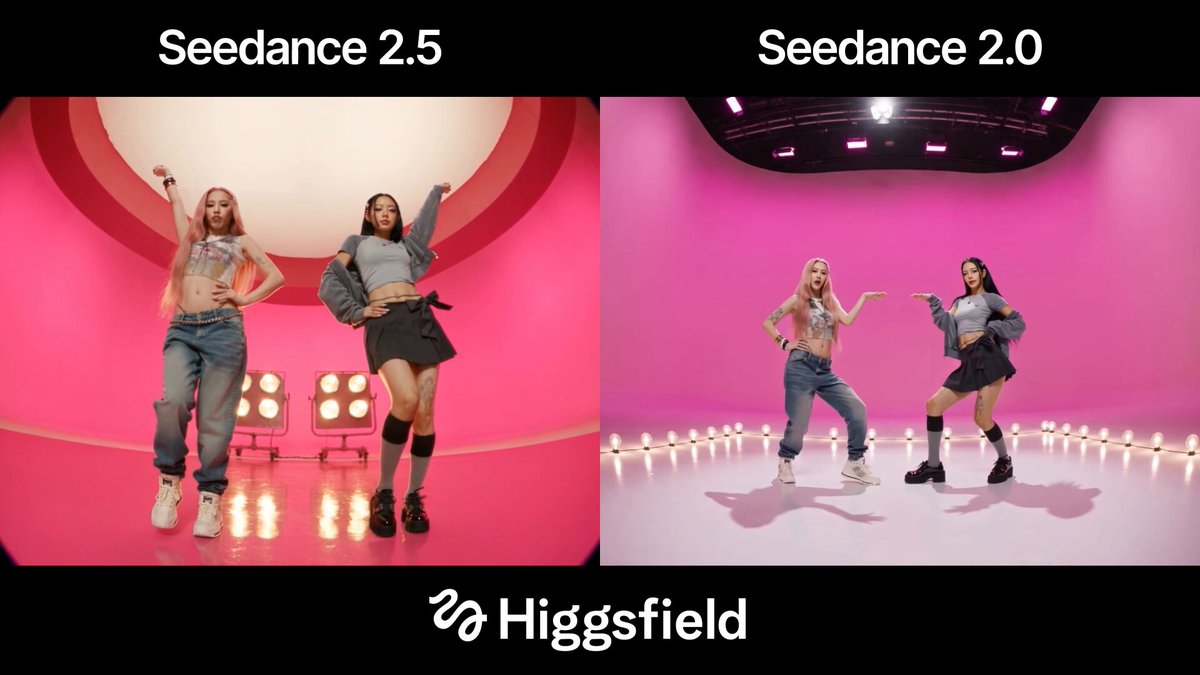
The more interesting approach is to stop thinking in terms of "which model is best" and start thinking in terms of a pipeline. A pipeline treats each model as a specialist: one generates the establishing shot, another handles the close-up dialogue beat, a third repairs motion blur, a fourth upscales the final frame. The output is not a collection of AI clips. It is a film, assembled from the strengths of several tools.
There is a second reason this matters. Audiences are now fluent in AI-generated footage. They recognize the tell-tale drift of a face changing shape, the over-smooth camera glide, the background that slowly melts. Novelty is no longer a selling point. Craft is. A multi-model workflow is the most practical way to raise the craft floor of a project without hiring a full production crew.
This guide walks through a complete multi-model video workflow: planning the shot list, choosing a model per shot, locking visual consistency, assembling the cut, handling sound, running quality control, and avoiding the mistakes that quietly consume entire evenings.
Know Your Model Families
Before you can orchestrate models, you need a working mental map of what each family does. Most confusion in AI video comes from asking one tool to do a job it was never designed for.
Text-to-video: the idea machine
Text-to-video models turn a written description into motion. They are at their best in the exploration phase, when you are trying to discover what a scene could look like. Feed them a paragraph, generate eight variations, and study what the model understood. Their weakness is control: you rarely get the exact camera angle, exact wardrobe, and exact timing you imagined. Use them to explore, not to deliver final shots, unless the shot is short, simple, and forgiving.
Image-to-video: the control engine
The moment a shot has a specific composition — a person at a particular window, a product at a particular angle — image-to-video becomes the workhorse. You supply a still frame, and the model animates it. Because you control the first frame, you control framing, costume, and lighting before generation begins. Most dialogue shots, product reveals, and brand-critical frames should come from this family.
Video-to-video and motion transfer: the repair shop
This family takes existing footage and transforms it: restyling live-action plates, transferring motion from one clip to another, extending a shot, or fixing a take that is 90 percent right. It is also the best tool for matching the look of a shot generated by a different model, because you can push an existing clip toward a target style instead of regenerating from scratch.
The enhancement layer
Upscalers, frame interpolators, and face restoration models sit above the generative layer. They do not create content, they rescue it. A 720p generation that has beautiful motion can often be pushed to a sharp, deliverable master. Skipping this layer is the single most common reason AI video looks like AI video.
Step 1: Plan the Shot List Before You Generate
Most wasted generation time comes from opening a model before you know what you are making. A shot list fixes this. Even a rough one — a spreadsheet with eight columns — will save hours.
Build your list with these fields: shot ID, duration in seconds, subject, action, camera move, lighting and time of day, required model family, and reference assets. Add two more columns that are easy to forget: seed value and prompt version. When a shot works, you need to know exactly how to reproduce it, and when it fails you need to know what changed.
Write each row as a shot description, not a mood. "Wide, low angle, slow dolly left, subject walks away from camera, dusk, warm streetlights" is useful. "Cinematic, epic, beautiful" is not — it gives the model nothing to latch onto and gives you nothing to evaluate.
Finally, mark which shots are hero shots and which are connective tissue. Hero shots deserve three times the iteration budget. Connective tissue — a hand opening a door, a passing car — should be generated quickly with forgiving settings. Treating every shot as a hero shot is the fastest route to burnout.
Step 2: Match Each Shot to the Right Model
With a shot list in hand, assign models. The decision criteria that matter most are consistency requirements, motion complexity, duration, and re-roll cost.
| Shot type | Best model family | Why |
|---|---|---|
| Establishing wide | Text-to-video | Exploration is cheap, precision is not needed |
| Character close-up | Image-to-video | Face and framing must be controlled |
| Product reveal | Image-to-video plus enhancement | Detail and brand accuracy matter |
| Stylized transition | Video-to-video | Restyling an existing plate is faster |
| Crowd or action beat | Text-to-video, short duration | Complex motion hides small errors |
| Signature hero shot | Two models, compared side by side | Quality justifies the extra pass |
Three practical rules follow from this. First, keep shots short. Most models degrade after a few seconds, and short clips are easier to cut around. Second, generate every hero shot with at least two different models and compare. The winner is rarely the one you predicted. Third, never judge a shot at full resolution on the first pass. Evaluate motion and composition at low resolution, then invest in the winners.
It also helps to group shots by model rather than by scene order. Running fifteen shots through one model in a single session keeps your prompting habits sharp and your parameters consistent, which pays off later when you need to match looks.
Step 3: Lock Consistency Before You Scale
Consistency is the difference between a demo and a deliverable. It is also the hardest problem in AI video, because models do not remember your characters. You have to build memory for them.
Start with a character sheet. Create one clean reference image per character — front, three-quarter, and profile — and keep them in a dedicated folder. Every shot featuring that character should start from one of those references in image-to-video mode. When a model supports multiple reference inputs, supply two or three angles at once; it dramatically reduces facial drift.
Next, build a style frame. Pick one generated image that represents the exact look you want: color palette, contrast, grain, lens character. Keep it visible while you prompt, and when you finish a sequence, run a quick grade pass that pushes every clip toward that frame using your editor's color tools.
Discipline around seeds matters too. When you find a seed that produces a stable, attractive result, write it down and reuse it with the same prompt structure. Changing one variable at a time is the only way to learn what a model responds to.
Finally, fix your technical specs up front: aspect ratio, frame rate, and duration range. Mixing 24fps and 30fps clips, or generating in three aspect ratios and cropping later, creates softness and judder that no amount of grading will fix.
Step 4: The Assembly Pipeline From Raw Clips to a Cut
A reliable assembly pipeline has five stages, and the order matters more than the tools.
Pass one: low-resolution exploration. Generate everything small. Review on a timeline, not in a folder — context changes your judgment. Kill anything that does not serve the story.
Pass two: regenerate the survivors. Take the shots that worked and re-run them with higher quality settings, ideally with slightly refined prompts. Do not start from scratch; start from the prompt and seed that already worked.
Pass three: repair and enhance. Run upscaling, frame interpolation, and face restoration on the final selections only. This is where a clip stops looking synthetic. Check for artifacts after each enhancement step rather than stacking three at once.
Pass four: edit for rhythm. Cut on motion, not on the model's natural clip boundary. Overlap clips by a few frames where possible so transitions feel intentional. Vary shot length; uniform three-second clips create a mechanical pulse that viewers feel even if they cannot name it.
Pass five: grade and unify. Apply one look across the whole piece. Slight grain, consistent contrast, and matched color temperature do more for perceived quality than another round of generation.
Keep a project log as you go: which clip came from which model, which seed, which prompt version. When a client asks for a change three weeks later, that log is the difference between a ten-minute fix and a full rebuild.
Step 5: Sound, Dialogue, and Final Polish
AI video projects are usually silent at the point of assembly, and silence makes even good footage feel unfinished. Sound design is also the fastest way to make a multi-model edit feel like a single coherent film, because audio glues cuts together.
Work in layers. Start with ambience: room tone, street noise, wind, crowd murmur. Then add foley — footsteps, cloth movement, object handling — timed to what is actually happening on screen. Only then add music. Music-first edits tend to force the picture into shapes the footage cannot support.
For dialogue, generate voice performances separately and time the visuals to the audio, not the other way around. If a character's mouth is visible, use a lip-sync pass on a locked clip; if the shot is a wide or a back-of-head angle, you can often skip it entirely and save a generation cycle. Always keep a version with no music for clients who want to re-cut later.
Finish with a mix pass: normalize loudness, check that no sound effect is masking dialogue, and listen on phone speakers. Most online viewers will hear your piece on a phone, and a mix that only works on studio headphones will feel thin to them.
Quality Control: The Pre-Delivery Checklist
Before you call a piece finished, run the same checks every time. Consistency beats inspiration at this stage.
- Face check: pause on every frame of every dialogue shot. Look for identity drift, teeth artifacts, and ear or jaw deformation.
- Hand and limb check: scan for extra fingers, merging limbs, and unnatural joint angles.
- Background check: watch for melting architecture, warping text, and objects that change between shots.
- Motion check: confirm that camera moves are smooth and that no clip has a visible speed change mid-shot.
- Continuity check: verify wardrobe, props, and time of day match across cuts.
- Technical check: confirm resolution, frame rate, aspect ratio, and audio loudness on the export.
- Playback check: watch the whole piece once without stopping. Errors that are invisible when you scrub become obvious in real time.
When something fails, resist the urge to regenerate the entire shot. Often a single repaired frame, an inserted cutaway, or a two-frame trim solves the problem at a fraction of the cost.
Common Mistakes That Cost the Most Time
Generating at maximum quality first. High-resolution passes are slow. Explore low, finish high.
Rewriting the whole prompt when one thing is wrong. Change one variable at a time, or you will never learn which word caused the improvement.
Ignoring reference images. Text-only prompting for character shots guarantees drift.
Skipping the shot list because the idea is "simple." Simple ideas are exactly where consistency problems hide.
Stacking enhancement passes blindly. Each upscale or interpolation step can add artifacts. Inspect after every one.
Not backing up seeds and prompts. Losing a working combination can cost an afternoon.
Editing before you have enough coverage. Generate extra takes of the shots around your hero moments. Flexibility in the edit is worth more than polish on a shot you end up cutting.
FAQ
How many models do I really need? Three well-understood models will outperform a scattered tour of fifteen. Most projects need one text-to-video model for exploration, one image-to-video model for controlled shots, and one enhancement pipeline.
Can I mix models in a single scene? Yes, and you should — but unify the look afterward with a shared style frame and a consistent grade. Matching color and grain is what makes a mixed-model scene feel seamless.
What is the biggest quality lever? Reference images. Supplying a strong first frame consistently improves results more than any prompt trick.
How long should an AI-generated shot be? As short as the edit allows. Two to four seconds is a comfortable range; longer clips tend to accumulate drift.
Should I generate at the final aspect ratio? Always. Cropping a wider frame down to a vertical format loses resolution and changes composition in ways you did not plan.
How do I handle client revisions? Keep the project log with model names, seeds, prompts, and asset versions. Revisions become targeted regenerations instead of rebuilds.
Is it worth learning every new model that launches? No. Track what is new, but only adopt a tool when it solves a specific problem in your existing pipeline. Depth in a small stack beats shallow familiarity with a large one.
The through-line in all of this is simple: treat AI video as production, not as a slot machine. Plan the shots, assign the specialists, protect consistency, assemble with intent, and check your work. The models will keep changing. The workflow does not have to.
