
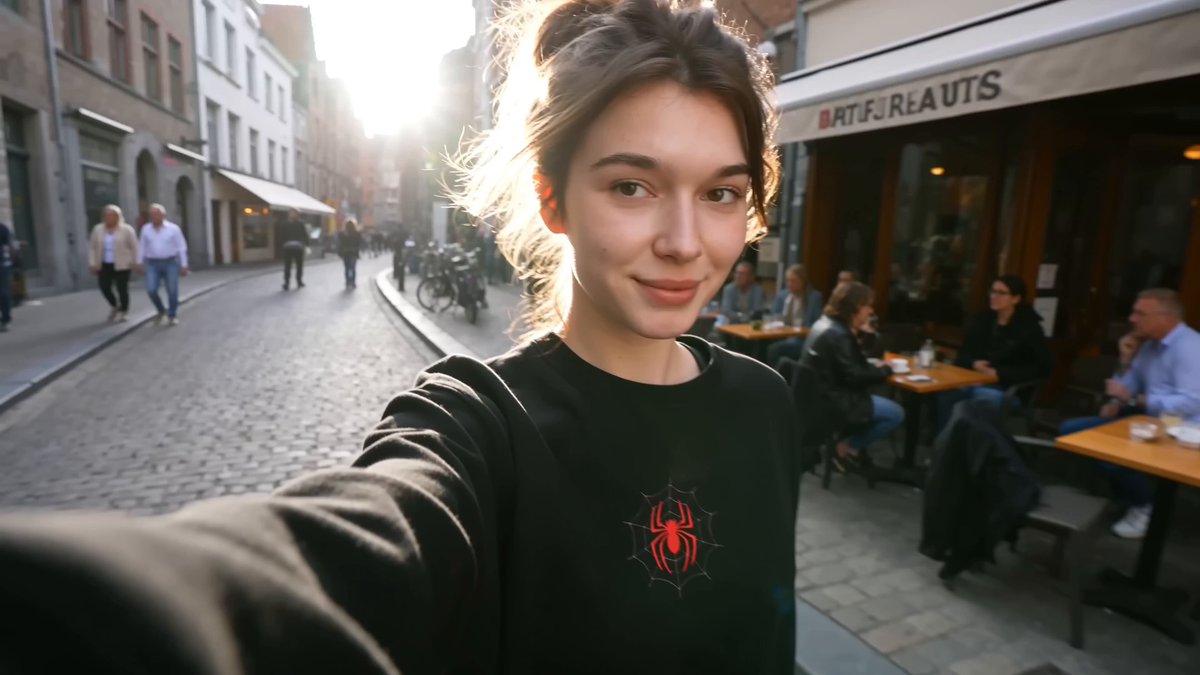
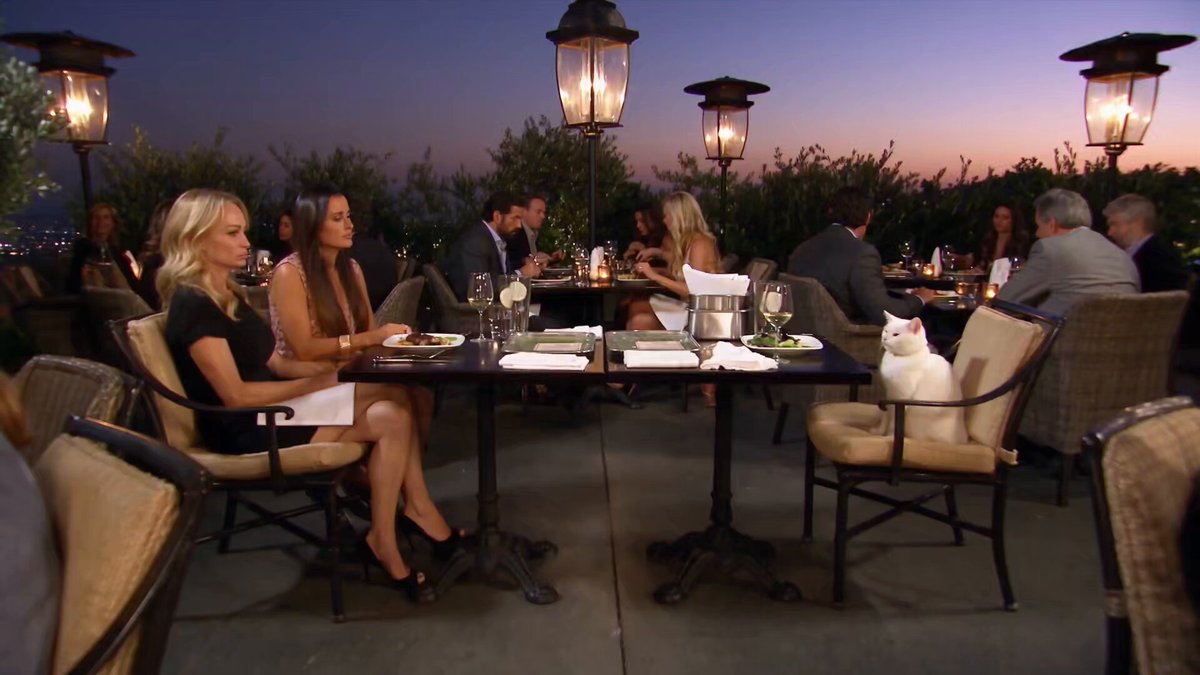
Photorealistic AI imagery has moved past the novelty stage. What used to require a render farm, a lighting team, and a week of iteration can now be approximated in an afternoon by a single person with a clear shot list and a sensible pipeline. The interesting problem is no longer whether a model can produce something that looks like a photograph. The interesting problem is producing a set of images or shots that look like they came from the same camera, the same location, and the same production — and doing it repeatably.
That shift changes what "skill" means. Prompt writing still matters, but it matters less than workflow design: how you lock references, how you sequence generations, how you grade and finish, and how you decide when a result is good enough to ship. This guide lays out a practical, tool-agnostic approach to photorealistic AI visuals, from brief to final delivery.
Why photorealism is now a workflow problem rather than a model problem
Most modern generative systems can render convincing skin, fabric, metal, and glass under the right conditions. Give any competent model a well-lit portrait prompt with camera language and it will produce something plausible. Give it a complex multi-shot scene with recurring characters, consistent light direction, and believable spatial relationships, and it will start drifting.
The drift is the real enemy. A character's jawline changes between frames. The window light flips from left to right. A jacket that was matte becomes glossy. Individually, each frame looks fine; assembled together, the sequence reads as synthetic immediately.
Experienced practitioners therefore treat photorealism as a production constraint rather than a model capability. They build habits that minimize variance:
- Lock before you explore. Establish a reference frame or two, then generate everything else against those anchors.
- Change one variable at a time. Adjusting pose, lighting, wardrobe, and camera angle simultaneously makes it impossible to diagnose what broke.
- Separate generation from finishing. Models produce the raw material; grading, grain, lens effects, and compositing produce the believability.
- Judge in sequence, not in isolation. A still that looks perfect may fail badly when placed next to nine others.
What "photorealistic" actually means in a production context
Photorealism is not a single quality. It is a bundle of signals that viewers read subconsciously. Understanding them lets you target your effort instead of hoping a bigger prompt fixes everything.
The signals viewers use to judge realism
Lighting logic. Shadows must agree with the light source in direction, softness, and color temperature. Mismatched shadow direction is the single most common tell in AI imagery.
Material response. Skin has subsurface scattering, fabric has weave and fuzz, metal has anisotropic highlights. When a model renders leather with the highlight sharpness of chrome, the eye notices even if it cannot articulate why.
Optical imperfection. Real photographs contain chromatic aberration, vignetting, sensor noise, and slight focus falloff. Perfectly clean digital images read as renders.
Environmental coherence. Reflections, contact shadows, and ambient bounce must be internally consistent. An object floating without a contact shadow destroys the illusion instantly.
Motion plausibility. In video, weight and inertia matter. Fabric that does not lag behind movement, or hair that does not settle, breaks photorealism faster than resolution ever could.
Where AI still breaks realism
Hands and complex grasping poses remain unreliable. Fine repeating patterns — brickwork, woven textiles, fences — often smear. Text in scene tends to degrade unless generated separately and composited. Crowds and multi-person interactions frequently produce anatomical nonsense. Reflections across curved surfaces rarely track correctly.
The practical response is not to avoid these elements but to plan for them. Shoot around hands, frame crowds in soft focus, generate signage as a separate layer, and keep reflective surfaces simple.
Choosing the right tool for each stage of the pipeline
A single tool rarely covers the whole job well. Thinking in stages makes tool choice obvious.
Concept frames and key art
Fast text-to-image models are ideal here. You want high iteration speed and low commitment. Generate twenty rough variations, pick two, then move on. Do not chase final quality at this stage — you are looking for composition and lighting direction, not pixel perfection.
Keyframes for motion
Once a composition is locked, regenerate it at higher fidelity using img2img or a reference-conditioned workflow. This is the frame that a video model will animate from, so it needs clean geometry, clear separation between subject and background, and no ambiguous edges.
Image-to-video and camera motion
Video models respond well to explicit camera language: slow dolly in, locked-off tripod, handheld drift, crane rise. Specify the motion and keep it modest. Aggressive camera moves expose every inconsistency in the underlying frame.
Upscaling and detail recovery
Dedicated upscalers outperform naive resizing by a wide margin. Use a model trained for photographic content rather than illustration, and upscale in stages (2x, then 2x again) rather than jumping straight to a final resolution.
Finishing and compositing
A traditional editor still does heavy lifting: grain, halation, subtle color shifts, lens distortion, and depth-of-field refinement. This is where an image stops looking generated and starts looking photographed.
A prompting framework built for realism
Prompts are not magic spells. They are specifications. The most reliable prompts are structured, specific, and boring.
Camera and lens language
Name a body and lens combination rather than a vibe. "35mm lens, f/2.0, shallow depth of field" tells the model far more than "cinematic." Add a distance cue — close-up, medium shot, wide establishing — and an angle: eye level, low angle, over-the-shoulder.
Making light the main subject
Describe the source, quality, and direction of light. "Soft north-facing window light from camera left, gently wrapping, warm practical lamp in background" is specific enough to constrain shadow direction. Vague terms like "beautiful lighting" invite randomness.
Materials and surfaces
Call out texture explicitly: brushed aluminum, worn cotton, weathered pine, damp asphalt. The more precisely you name the surface, the more likely the model produces appropriate specular behavior.
Constraints that actually help
Negative constraints work best when they target a specific failure mode rather than general quality. "No plastic skin, no over-sharpened edges, no HDR halos" is more useful than "not ugly." Keep the list short — long negative lists dilute each instruction.
Iteration discipline
Use fixed seeds when you find a composition you like. Change one element per generation. Save prompts alongside outputs with a consistent naming convention. Six weeks later, that discipline is the difference between reproducing a look and starting over.
Keeping visual consistency across an entire set
Consistency is what separates a portfolio of interesting images from a coherent body of work.
Character consistency
Build a character sheet first: three or four angles, neutral expression, consistent wardrobe, consistent light. Use those images as references for every subsequent generation. Where the tool supports it, train a small personal model on the character sheet — it pays for itself within a handful of shots.
Environment and palette consistency
Define a location bible: primary palette, dominant materials, typical light direction, and a small set of signature props. Then reuse those details verbatim in every prompt for that location.
Style locking with reference images
Reference-conditioned generation is far more reliable than describing a style in words. Feed one approved frame as a style reference and describe only what changes. This keeps grain, contrast, and color science stable across the set.
Handling multiple models in one project
If you use different tools for stills, video, and upscaling, expect color and contrast mismatches. Normalize output by applying a single look-up table or grade across everything at the end. A shared finishing pass hides a surprising amount of cross-tool inconsistency.
A step-by-step photorealism pipeline
Here is a workflow that scales from a single hero image to a twenty-shot sequence.
Step 1: Brief and shot list
Write down what each image needs to communicate, where it will be used, and its aspect ratio. A vertical social clip and a widescreen hero image need different compositions. Deciding this before generating saves a lot of cropping pain.
Step 2: Reference board
Collect real photographs that match your intended look. These are not for the model necessarily — they are for you. Explicit references make it much easier to spot when a generation has drifted.
Step 3: Rough keyframes
Generate quickly and cheaply. Twenty to forty variations across your shot list. Pick the strongest composition per shot and discard the rest without regret.
Step 4: Refinement pass
Regenerate selected frames at high fidelity with reference conditioning, locked seeds, and detailed prompts. Fix anatomical issues here, before motion is added, because video models amplify existing flaws.
Step 5: Motion
Animate keyframes with modest camera moves. Keep clips short — three to six seconds is usually enough. Longer clips accumulate drift.
Step 6: Grade and finish
Apply one consistent look across all assets: grain, slight lens vignette, gentle contrast curve, and chroma matching. Then add sound design. Audio does more for perceived realism than most visual tweaks.
Step 7: Quality control checklist
Before delivery, check every asset for: consistent light direction, matched skin tone and wardrobe, correct shadow contact, no warped hands or text, stable grain across cuts, and no flicker between frames. This checklist catches most embarrassing errors.
Common mistakes that quietly ruin realism
Over-prompting. Extremely long prompts pull the model in conflicting directions. Tighten and prioritize.
Chasing resolution. A 4K image with broken lighting looks worse than a 1080p image with coherent lighting.
Ignoring the background. Photorealism dies in the background. Blurry, structurally impossible backdrops undermine an otherwise perfect subject.
No finishing pass. Straight-out-of-model output almost always reads as generated. Ten minutes of grading changes the result dramatically.
Inconsistent aspect ratios. Mixing formats without planning creates awkward crops and lost composition.
No version control. Without naming conventions and saved prompts, iteration becomes guesswork.
Ethics, disclosure, and rights considerations
Photorealistic synthetic media carries obligations. Do not generate recognizable real people without permission. Avoid creating imagery that could be mistaken for documentary evidence of real events. Disclose AI involvement where your audience or platform expects it, and follow platform labeling rules for synthetic media.
Also check the licensing terms of every model you use, particularly for commercial work and for any personal-model training done on faces. Keep a record of which assets were generated with which tool and under what terms. This documentation becomes essential if a client or platform asks questions later.
FAQ
How many generations does a good photorealistic image usually take? For a single hero image, expect twenty to sixty iterations across rough and refined passes. Complex scenes with multiple subjects take considerably more.
Do I need a specific model to get photorealism? No single model is required. What matters is using a photographic-content model for upscaling, reference conditioning for consistency, and a disciplined finishing pass.
Why do my AI images look plasticky? Usually because of over-sharpening, absent grain, and lighting that lacks a clear directional source. Adding noise, softening highlights, and specifying light direction fixes most of it.
Should I use image-to-image or text-to-image for keyframes? Text-to-image for exploration, image-to-image or reference conditioning for refinement. Mixing them gives you both speed and control.
How long should AI-generated video clips be? Three to six seconds per shot is a reliable default. Cut between shots rather than generating long continuous takes.
Can I make a consistent character without training a custom model? Yes, with a well-made character sheet used as a reference on every generation. It is slower but workable for short projects.
What is the fastest way to improve realism overall? Improve your lighting description and add a finishing pass. Those two changes produce the largest visible gains.
The bottom line
Photorealistic AI visuals are a craft problem disguised as a technology problem. The models are already capable; the differentiator is the discipline around them — locked references, one-variable iteration, modest camera motion, and a finishing pass that adds the imperfections real cameras leave behind.
Start small. Pick one shot, build a reference board, generate rough frames, refine with locked seeds, then grade the result. Once that single shot survives the quality control checklist, scale the same process across a full set. Workflow consistency, not model selection, is what produces a body of work that reads as genuinely photographic.
