
Photorealism Is a Craft Problem Before It Is a Prompt Problem
Most AI images and clips that fail to convince fail for the same handful of reasons: vague lighting, plastic skin, no camera logic, and subjects described with adjectives instead of physical facts. Photorealism is not a keyword you append at the end of a prompt. It is the compound result of decisions about light, surface, optics, and imperfection — the same decisions a photographer or cinematographer makes on set before anyone presses record.
The useful news is that those decisions are learnable and repeatable. Once you know which part of a prompt controls which part of the output, prompting stops being a slot machine and becomes directing. The system below is designed to be portable: it works for still image generators, text-to-video tools, and image-to-video pipelines, and it survives model updates because it is based on how light and lenses behave rather than on a single model's quirks.
The Anatomy of a Photorealistic Prompt
A strong photorealistic prompt is a structured brief, not a sentence. Think of it as eight blocks that you can reorder or trim, but rarely skip. Consistency comes from keeping the block order stable across a project so you can compare outputs and change one variable at a time.
Shot Intent and Format
Start with what the shot is, not what it looks like. "Documentary still, 35mm, available light" gives the model a different target than "cinematic hero shot, anamorphic, shallow depth of field." State the framing (extreme close-up, medium shot, wide establishing), the orientation, and the intended use — editorial photo, product hero, film still, security-camera frame. Format language sets expectations for grain, sharpness, and color rendering before the model decides anything else.
Subject Specifics Instead of Adjectives
Replace "beautiful woman" with physical facts: approximate age, build, hair texture and length, skin tone, freckles or scars, clothing material and wear, posture, expression at a specific micro-moment. "A 40-year-old ceramicist, forearms flecked with dried clay, three-day-old cut on her left thumb, wiping a bowl with a damp sponge" gives the model something to render. Adjectives like "stunning" or "flawless" push toward synthetic beauty retouching, which is the opposite of photorealism.
Environment and Material Truth
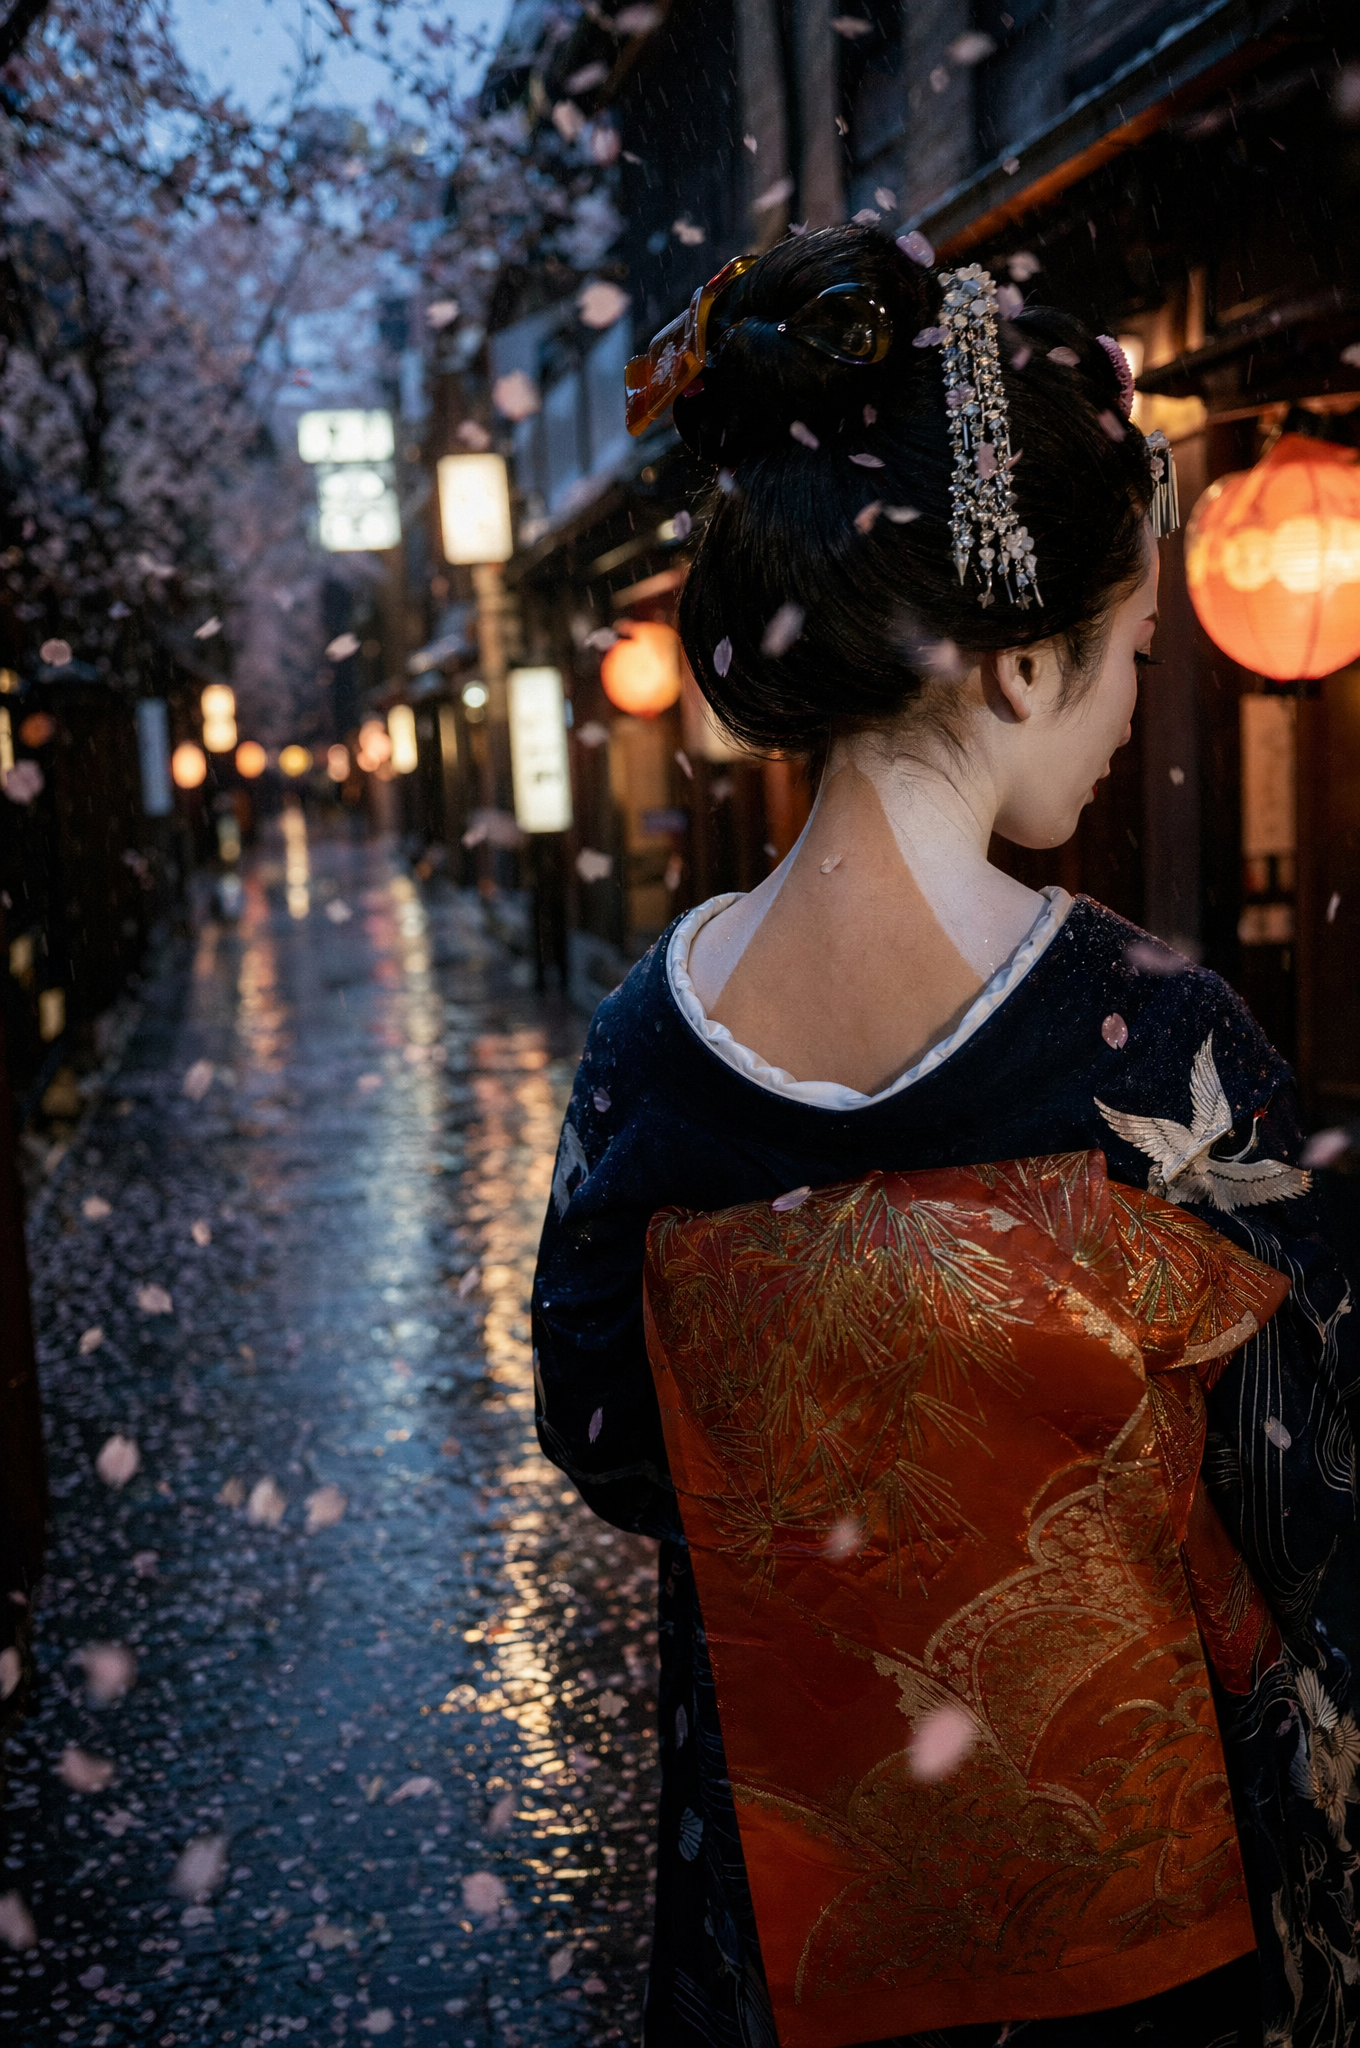
Every environment is made of materials, and materials have behavior. Say "wet asphalt reflecting a red shop sign," not "city street at night." Say "chipped enamel sink with a hairline crack, hard water staining around the drain." Include what is out of focus in the background, because real photographs have depth layers: foreground obstruction, mid-ground subject, distant texture. Naming two or three specific background elements is usually enough to stop the model from hallucinating a generic blur.
Light as the Primary Realism Lever
If you change only one block, change this one. Describe the source, quality, direction, color, and ratio:
- Source: window, overcast sky, bare bulb, phone screen, headlights, campfire, softbox, practical neon sign.
- Quality: hard, soft, diffuse, specular, dappled through leaves.
- Direction: backlit, side-lit from camera left, top-down, under-lit from a laptop screen.
- Color temperature: warm tungsten, cold blue dusk, mixed green fluorescent and orange streetlamp.
- Ratio: high contrast with deep shadow, or flat overcast light with almost no shadow detail.
Models respond strongly to "practical light sources inside the frame" and "visible falloff across the face." Both cues force physically plausible shading instead of the flat, evenly lit look that reads as computer-generated.
Camera, Lens, and Motion Language
Photorealism is partly a set of optical artifacts. Focal length, aperture, distance, and movement all leave signatures:
- 24mm close to the subject creates environmental distortion and a large nose-to-ear ratio.
- 50mm at eye level reads as neutral and documentary.
- 85mm to 135mm compresses features and isolates the subject with soft background falloff.
- Wide apertures produce shallow focus and round bokeh; small apertures produce deep focus and more visible texture.
- Slight motion blur, a shutter angle around 1/48 for video, and gentle sensor grain make a frame feel like a captured moment rather than a rendered one.
For video, describe the movement precisely: slow dolly in over six seconds, handheld micro-shake, gimbal glide following a walking subject, locked-off tripod with a subject crossing frame. Vague motion words like "dynamic" tend to produce warping and unstable geometry.
Texture, Imperfection, and Micro-Detail
This block is where most generations are won or lost. Ask for pores, fine lines, peach fuzz, split ends, fabric weave, denim twill, wool fiber, condensation on glass, dust motes in a light beam, fingerprints on a lens, scuffed boots, tarnished brass, uneven paint. Also ask for controlled imperfection in the capture: mild lens vignetting, a touch of chromatic aberration at the frame edge, slight highlight clipping on a bright window.
Color, Grade, and Atmosphere
Name a palette and a grade instead of a mood. "Desaturated teal shadows, warm skin tones, slightly lifted blacks, filmic highlight rolloff" gives a colorist's instruction. Atmosphere — haze, rain, smoke, steam, dust — adds depth separation, because particles scatter light between camera and subject. Keep the palette to two or three dominant colors; more than that and the model produces the muddy, over-saturated look typical of low-effort prompts.
Cinema Vocabulary That Actually Changes the Output
Some terms are decorative and some are functional. Functional terms describe physics: "hard key from camera left, soft fill from a bounce card, negative fill on the shadow side." Decorative terms describe taste: "moody," "epic," "award-winning." Use decorative words sparingly and always pair them with a physical instruction, otherwise they mostly add noise.
Useful functional vocabulary includes: key, fill, rim, kicker, practical, bounce, diffusion, falloff, specular highlight, contact shadow, ambient occlusion, depth layers, foreground framing, rack focus, parallax, shutter angle, sensor grain, halation around bright edges. Each of these has a visible consequence, so each one earns its place in the prompt.
One habit that pays off: after every generation, name the physical reason the result failed before you name the aesthetic reason. "Skin is waxy" is aesthetic. "No micro-shadow detail around the nostrils and no specular breakup on the forehead" is physical, and it tells you exactly what to add.
A Repeatable Prompt-Building Workflow
Step 1: Write the Shot Intent in One Sentence
Before prompting, write a plain sentence describing the moment: "A baker lifts a tray of bread from a rack in a small kitchen at dawn." This sentence is the spine. Everything else supports it.
Step 2: Assemble the Eight Blocks
Draft the prompt as labeled lines — intent, subject, environment, light, camera, texture, color, constraints. Labeling forces you to notice which block is empty. An empty light block is the most common cause of a flat, artificial result.
Step 3: Generate Fast Variants
Run the prompt in a fast or draft mode first and produce four to six variations. You are not looking for a finished frame; you are looking for which block is misfiring. Compare the set side by side rather than judging each one in isolation.
Step 4: Change One Variable at a Time
If the light is wrong, edit only the light line. If the skin is wrong, edit only the texture line. Changing three things at once makes the feedback loop useless, and you will not know which instruction to keep.
Step 5: Lock the Winner as a Reference
When a frame works, keep it. Use it as an image reference for later shots, note the exact prompt version, and record the seed if the tool exposes one. This is what turns a lucky generation into a repeatable look.
Step 6: Extract a Template
Rewrite the successful prompt as a template with replaceable slots: [SUBJECT], [ENVIRONMENT], [LIGHT], [LENS], [TEXTURE], [PALETTE]. Templates are how you keep a whole sequence visually coherent without retyping the same paragraph.
Step 7: Build the Shot List
For video projects, list shots with their framing, movement, and duration before generating anything. Twenty short clips with a consistent look beat one long clip that drifts in style halfway through.
Model-Agnostic Baselines and Model-Specific Tuning
Image Models vs Video Models
Still image models reward descriptive density and can hold a lot of texture detail in a single frame. Video models reward clarity of motion and stable composition; dense texture descriptions can cause temporal flicker because the model keeps reinterpreting small details between frames. For video, keep texture language shorter and put more weight on movement, framing, and lighting continuity.
Tuning to Different Engines
Most modern generators differ less in what they can render than in how they weight prompt order and how much they respond to cinematic jargon. Model families oriented toward film look respond well to lens and lighting vocabulary. Model families oriented toward illustration may need literal photographic language such as "35mm film scan, unretouched" to stay in the photoreal lane. Diffusion-based pipelines often respond strongly to negative constraints, while transformer-style video models usually respond better to positive statements of what should happen.
The practical approach: keep a model-agnostic baseline prompt and a short model-specific addendum. When you switch tools, keep the baseline and adjust the addendum only. This prevents you from rebuilding your language from scratch every time a new engine appears.
Reference Images and Image-to-Video
Reference images are the strongest realism control available, because they carry the exact lighting direction, palette, and lens character into the new generation. Use them when identity, wardrobe, or location must stay consistent. The trade-off is reduced creative range: the more reference weight you apply, the closer the output stays to the source and the less it can reinterpret the scene. Balance reference weight against prompt freedom depending on whether consistency or variety matters more for that shot.
Consistency Across a Shot Sequence
Sequence consistency has four layers, in order of importance: identity, wardrobe, location, and grade. Lock them in that order. Build a character sheet as a single reference image containing the subject in neutral light from two angles, then reuse it. Keep a written wardrobe list with material and color names so different shots do not drift between cotton and satin. Maintain a location bible with the same three or four background descriptors repeated in every prompt for that scene.
For color, pick a grade phrase and paste it into every prompt in the sequence — for example, "filmic grade, cool shadows, warm midtones, gentle highlight rolloff." It costs nothing and it does more for continuity than any post-production filter.
Common Failure Modes and Fixes
- Waxy, plastic skin: remove words like "flawless," "perfect," or "beauty retouch" and add visible pores, fine lines, and specular breakup.
- Over-sharpened, crunchy detail: request natural sharpness with mild motion blur or film grain, and avoid stacking five quality-boosting words.
- Floating subject: add a ground plane, contact shadows, and "weight settling into the surface."
- Endless shallow depth of field: specify an aperture and add "deep focus, background readable."
- Muddy color: cut the palette to two dominant colors plus one accent.
- Warped hands or props: simplify the pose, move hands out of the foreground, or supply a reference image.
- Flicker and identity drift in video: shorten texture language, slow the motion, lock the reference, and reduce action complexity.
- Unstable geometry in movement: replace "dynamic camera" with a specific move such as "slow 15-degree arc around the subject."
Quality Control Checklist Before You Render Final
Run this checklist on a draft frame: Does the light have a named source and direction? Do shadows fall consistently with that source? Is there contact shadow where the subject meets the ground? Does the skin show texture at 100 percent zoom? Do the background layers make sense as depth rather than as blur? Is the palette limited to three colors? Does the framing match the lens you asked for? If any answer is no, fix that block before generating more variations — more variations of a broken prompt only produce more broken frames.
Ethics, Likeness, and Practical Constraints
Photorealism carries responsibility. Do not generate identifiable real people without consent, be careful with minors, and avoid fake news-style imagery of real events. If you are producing commercial work, keep records of your prompts and references so you can explain how an image was made, and check the licensing terms of each tool you use for commercial output. For advertising and editorial contexts, disclosing AI involvement is increasingly a requirement rather than a courtesy.
FAQ
Do longer prompts always produce more realistic results?
No. Structure matters more than length. A 60-word prompt with a named light source, a lens, and texture cues will beat a 300-word prompt that repeats quality adjectives.
Are negative prompts necessary for photorealism?
They help most in diffusion-based image tools and least in video models. Keep negatives short: "no plastic skin, no over-saturation, no text, no watermark" is usually enough.
Does naming a real camera brand improve results?
Sometimes, because brand names act as shorthand for a look — but the effect is model-dependent and unreliable. Describing the look directly ("fine grain, neutral color, high dynamic range") is more portable.
How do I keep a character consistent across many shots?
Lock a reference image, a seed where available, a written wardrobe list, and a single repeated grade phrase. Then change only the environment and framing between prompts.
What is the fastest route to cinematic video?
Start from a strong still image, animate it with a simple, physically plausible camera move, and keep each clip short. Complex action in a first attempt rarely holds together.
Why does my video flicker when my image looks fine?
Video models reinterpret detail between frames. Reduce micro-texture density, slow the movement, and specify lighting continuity across the shot.
