
Why Seconds-Level Rendering Changed the Production Workflow
A few years ago, generating a convincing photorealistic image meant waiting minutes, sometimes longer, and then accepting whatever the model decided to give you. Iteration was expensive. You planned three variations instead of thirty, because each one cost you a coffee break. That constraint shaped how people wrote prompts, how they scoped projects, and how much experimentation they allowed themselves.
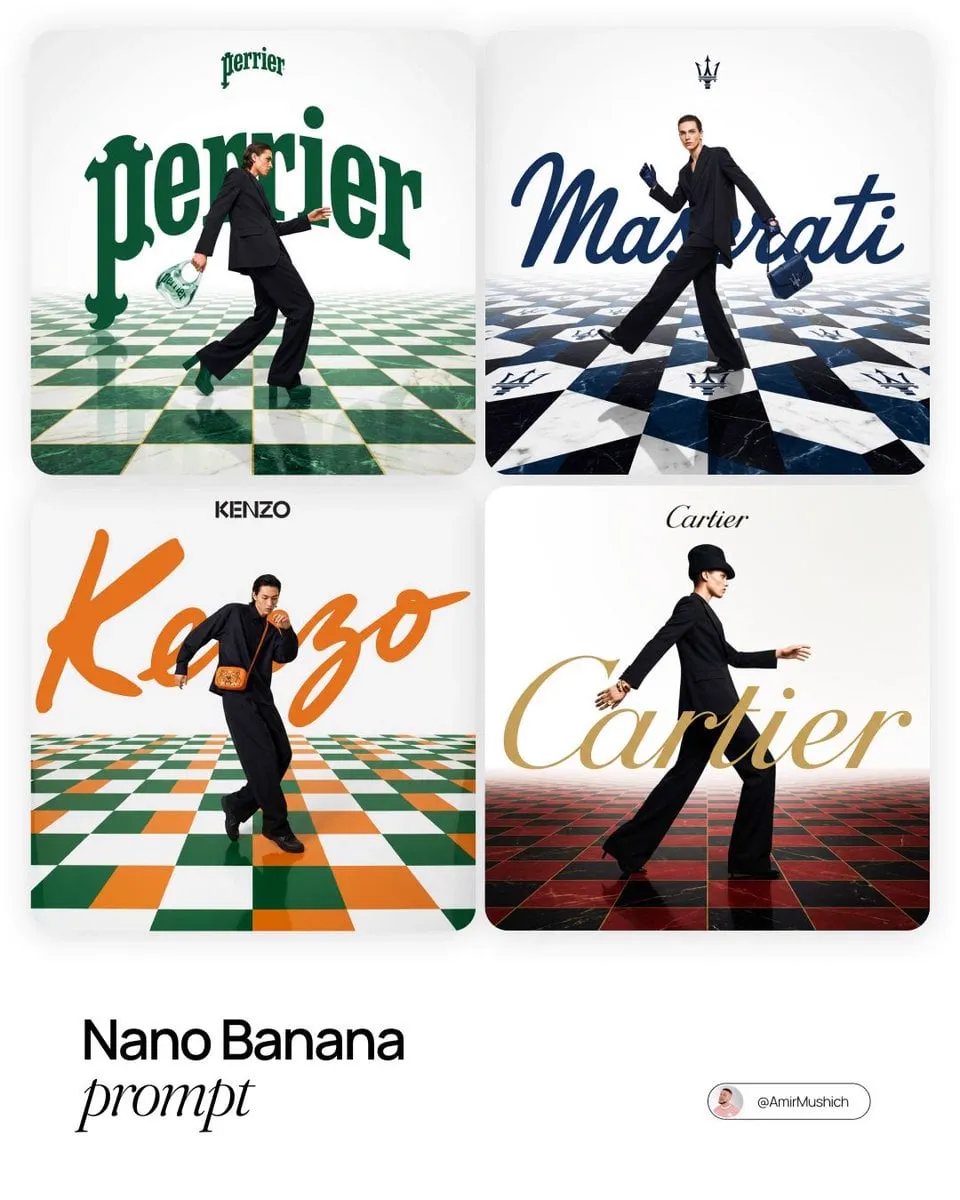
Today the arithmetic is different. When a high-quality frame lands in a handful of seconds, the bottleneck moves. It is no longer compute. It is your decision-making. You can explore lighting directions, wardrobe options, camera angles, and color grades at a pace that matches your thinking rather than fighting it. The practical consequence is that the creative process becomes conversational: you react to what you see, refine, and react again.
That shift sounds like a pure upgrade, and in many ways it is. But speed also exposes weak workflow habits. Teams that never defined a visual brief now generate hundreds of frames with no through-line. Photorealism at high speed makes it easier than ever to produce polished-looking assets that do not belong to the same project. This guide is about building a workflow that takes advantage of fast rendering without drowning in output.
We will cover what photorealistic actually means in a generative context, where latency comes from, how to pick the right model for a job, how to keep characters and products consistent across shots, how to move from stills into motion, and the mistakes that quietly wreck quality.
What "Photorealistic" Actually Means to a Generative Model
Photorealism is not one property. It is a bundle of visual cues that human viewers read almost instantly, often without being able to explain why. Understanding the bundle helps you diagnose why an image feels slightly off even when the resolution is high.
The core cues are:
- Lighting behavior. Real light falls off, bounces, casts soft shadows, and creates subtle color spill. Models that flatten lighting produce images that look rendered rather than captured.
- Material response. Skin has subsurface scattering and tiny imperfections. Metal has anisotropic highlights. Fabric has fuzz and directional sheen. Generic surface treatment is the single most common giveaway.
- Optical realism. Depth of field, lens flare, chromatic aberration, sensor noise, and slight vignetting are all fingerprints of a real camera. A little of each goes a long way.
- Micro-detail at the edges. Hair strands, dust, fingerprints, seam stitching, and the imperfect boundaries between objects are where the eye hunts for fraud.
- Contextual plausibility. A perfectly lit subject in an impossible environment breaks the illusion faster than any rendering artifact.
When you write prompts, you are essentially negotiating which of these cues the model should prioritize. Vague prompts let the model default to its training bias, which is usually a glossy, over-smoothed look. Explicit prompts about lens, light source, and material push it toward something that reads as a photograph.
It is also worth separating photorealistic from hyperrealistic. Hyperrealism pushes contrast, saturation, and detail beyond what a camera would capture. It looks impressive in a thumbnail and exhausting over a full sequence. If your goal is documentary credibility or product accuracy, aim for restraint.
Where Latency Comes From and How to Reduce It
Speed is not a single number. It is the sum of several stages, and knowing which stage you are waiting on determines the fix.
Sampling steps and guidance
Diffusion-style generation refines noise over a series of steps. Fewer steps means faster output but softer detail. Modern schedulers can produce acceptable results in far fewer steps than older ones, which is a large part of why generation feels instant now. Distilled and turbo variants push this further by training a model to reach a good result in a very small number of passes.
Resolution and tiling
Cost scales roughly with pixel count, and attention mechanisms scale worse than that. Generating a small composition and upscaling in a second pass is almost always faster than rendering a huge canvas in one shot. It also gives you a checkpoint to reject bad compositions before spending time on detail.
Conditioning and reference images
Adding reference images, pose guides, or depth maps costs time but usually saves more than it spends, because it reduces the number of attempts needed to hit the target. A ten-second generation that works beats four two-second generations that do not.
Queueing versus interactive generation
Batch job queues optimize throughput across many requests. Interactive generation optimizes for the next result arriving quickly. These are different engineering goals. If you are exploring, you want interactive latency. If you are producing fifty final assets, a queue with predictable ordering is better than a fast but erratic stream.
Upscaling and finishing
The final polish — denoise, detail enhancement, color correction — is a separate cost center. Keep it out of the exploration loop and apply it only to approved frames.
Choosing the Right Model for the Job
There is no universally best model. There is a best model for a specific shot on a specific deadline. A practical decision framework looks at four dimensions.
Fidelity ceiling. How convincing does the final image need to be at full resolution? Editorial photography and product hero shots have a much higher bar than background plates for a social video.
Prompt adherence. Some models are beautiful but interpretive, drifting away from your instructions. Others follow instructions precisely but produce flatter aesthetics. Know which failure mode you can tolerate.
Consistency support. If you need the same person across twelve shots, pick a model or pipeline with strong reference-image and identity-locking behavior, even if it is slightly slower per frame.
Cost predictability. Per-image, per-second, and subscription pricing models behave very differently at volume. Model your actual monthly volume before committing, and remember that iteration count — not final asset count — drives the bill.
A reasonable default strategy is to keep two or three models in rotation: a fast drafting model for exploration, a high-fidelity model for finals, and a specialized model for whatever your project leans on most, whether that is people, products, architecture, or stylized realism.
A Practical Workflow From Brief to Final Frame
The following pipeline works for anything from a single hero image to a multi-shot campaign. It is deliberately front-loaded, because clarifying intent early is cheaper than fixing drift later.
Step 1: Write a one-page visual brief
Before generating anything, write down the subject, the environment, the emotional tone, the lighting logic, the lens character, the color palette, and three adjectives that describe the feeling. This document is your tiebreaker. When you have forty candidate images and cannot decide, the brief tells you which ones are actually on target.
Step 2: Build a reference board
Collect real photographs that match the brief. Not AI images — real ones. Real photographs carry authentic optical and material cues that you can describe in prompts. Look at them and write down what specifically makes them work: the light direction, the shadow softness, the background compression, the skin tones.
Step 3: Draft fast and wide
Use your quickest model and lowest acceptable resolution. Generate a wide spread of compositions and lighting setups. Do not polish. The goal of this phase is to eliminate directions, not to choose a winner. Most teams find that twenty to forty low-cost drafts are faster than five careful attempts.
Step 4: Lock the direction
Pick one or two compositions. Now raise the resolution and switch to your higher-fidelity model. Refine lighting, framing, and material detail. This is where you spend your quality budget.
Step 5: Lock identity and continuity
If the project has recurring elements — a character, a product, a location — create a locked reference now and reuse it for every subsequent shot rather than re-describing it in text. Text descriptions drift; reference images hold.
Step 6: Finish and deliver
Apply upscaling, subtle grain, color grading, and any compositing. Deliver at the aspect ratios and crops your channels need, and keep an untouched master file.
Keeping Characters, Products, and Locations Consistent
Consistency is the hardest problem in AI production and the one most likely to derail an otherwise strong project. Fast rendering makes it worse, because you can accumulate hundreds of near-miss variations before noticing the drift.
There are three practical levers.
Reference conditioning. Feed the model one or more approved images of your subject alongside the prompt. This anchors identity far more reliably than adjectives. Keep a small, curated reference set rather than a large messy one — conflicting references produce averaged, generic faces.
Structural guides. Depth maps, pose skeletons, and edge maps constrain geometry while leaving style free. Use them when composition matters more than spontaneity, such as matching a storyboard frame or placing a product in a specific position.
Naming and versioning discipline. Save every approved asset with a clear identifier, and treat that asset as your canonical reference for the project. Teams that skip this step end up with five slightly different versions of the same character and no idea which one is current.
For products specifically, prioritize shape accuracy over surface beauty. A gorgeous render of the wrong bottle silhouette is worse than a plain render of the right one. Where accuracy is legally or commercially critical, use AI for the environment and lighting, and composite the real product photography in.
Moving From Still Frames to Motion
The same speed gains that transformed still image generation have arrived in video. Instead of animating frame by frame, modern video models accept an image or a text description and generate coherent motion across time, with camera movement, subject motion, and ambient change handled together.
A workflow that works well:
- Perfect the first frame. Since many video models animate from a still, that still becomes the visual contract for the whole clip. Get it right first.
- Describe the camera, not just the action. A slow dolly-in, a handheld push, a static locked-off shot — camera language drives perceived realism more than subject motion does.
- Generate short and extend. Short clips are cheaper to iterate and easier to reject. Once a clip reads well, extend it or generate adjacent shots from the same reference set.
- Mind temporal artifacts. Watch for warping faces, morphing hands, flickering textures, and background elements that change shape between frames. These are the current weak points, not the still-image detail.
- Grade for coherence. Shots generated separately often differ in color temperature and contrast. A unified grade pulls them into one world.
For social and advertising work, a two-to-five second clip with a single clear camera move is usually more convincing than a longer, busier sequence. Restraint reads as production value.
A Quality Control Checklist
Run every candidate through the same checks before it enters your library. Consistency of process is what separates a professional pipeline from lucky output.
- Anatomy and hands. Fingers, ears, teeth, and joints. Check at 100 percent zoom.
- Text and logos. Generated text is often subtly malformed. Replace it in post unless it is intentionally decorative.
- Reflections and shadows. Do they match the light source? Are they physically plausible?
- Edge integration. Hair, glasses, and thin objects against busy backgrounds.
- Background logic. Cables that go nowhere, duplicated objects, impossible architecture.
- Color continuity. Compare against the previous and next shot in the sequence.
- Resolution and artifacts. Look for oversharpening halos, banding, and compression artifacts introduced during upscaling.
- Rights and provenance. Confirm you can legally use every reference, and keep a record of which model and prompt produced each final asset.
Common Mistakes and How to Fix Them
Chasing resolution instead of lighting. A 4K image with flat light looks fake. Fix the lighting language first, then increase resolution.
Over-stuffing prompts. Long prompts dilute attention. Keep the subject, lighting, lens, and mood tight; move other details into a reference image.
Iterating on the wrong image. If a composition is wrong, do not refine it — discard it and generate a new spread. Refining a bad composition is the most common way to waste a fast rendering budget.
Forgetting the sequence. Every shot is evaluated alone, then the sequence looks disjointed. Review your selects as a contact sheet before approving finals.
Ignoring the defaults. Most models have a house style — glossy, warm, slightly over-saturated. If you want something else, you must explicitly ask for it.
Skipping the negative constraints. Mentioning what should not appear is often more effective than adding more positive detail.
Treating speed as an excuse to skip the brief. Speed multiplies whatever direction you already have. With no direction it multiplies noise.
FAQ
Do I need a powerful local machine?
Only if you want offline control, custom models, or strict data handling. Cloud generation removes hardware concerns entirely but introduces network latency and subscription costs.
How many drafts should I generate per final asset?
For exploratory work, expect ten to thirty drafts per keeper. For well-scoped repeat work with a locked reference set, three to five is realistic.
Can I use generated images commercially?
That depends on the model's license and your jurisdiction, and it changes over time. Read the terms for the specific model you use and keep documentation of your generation process.
Why does the same prompt give different results every time?
Sampling is stochastic by design. Fix the seed when you need reproducibility, and treat variation as a feature during exploration.
How do I stop faces from drifting between shots?
Use reference images, keep the reference set small and consistent, avoid re-describing the face in text, and lock a single canonical image per character.
Is faster always better?
No. Speed is valuable during exploration and low-stakes iteration. For final assets, spend the extra seconds on higher-fidelity passes and finishing work.
Putting It Together
Seconds-level photorealistic rendering is not a novelty — it is a change in how production time is allocated. When generation is nearly free, the value moves to direction, curation, and consistency. The teams that benefit most are not the ones generating the most images; they are the ones with a clear brief, a small set of locked references, and a disciplined review process.
Start small. Pick one project, write the brief, build a reference board, draft wide with a fast model, and finish with a high-fidelity pass. Document what worked. Within a few projects you will have a repeatable pipeline that turns speed into quality rather than volume.
