
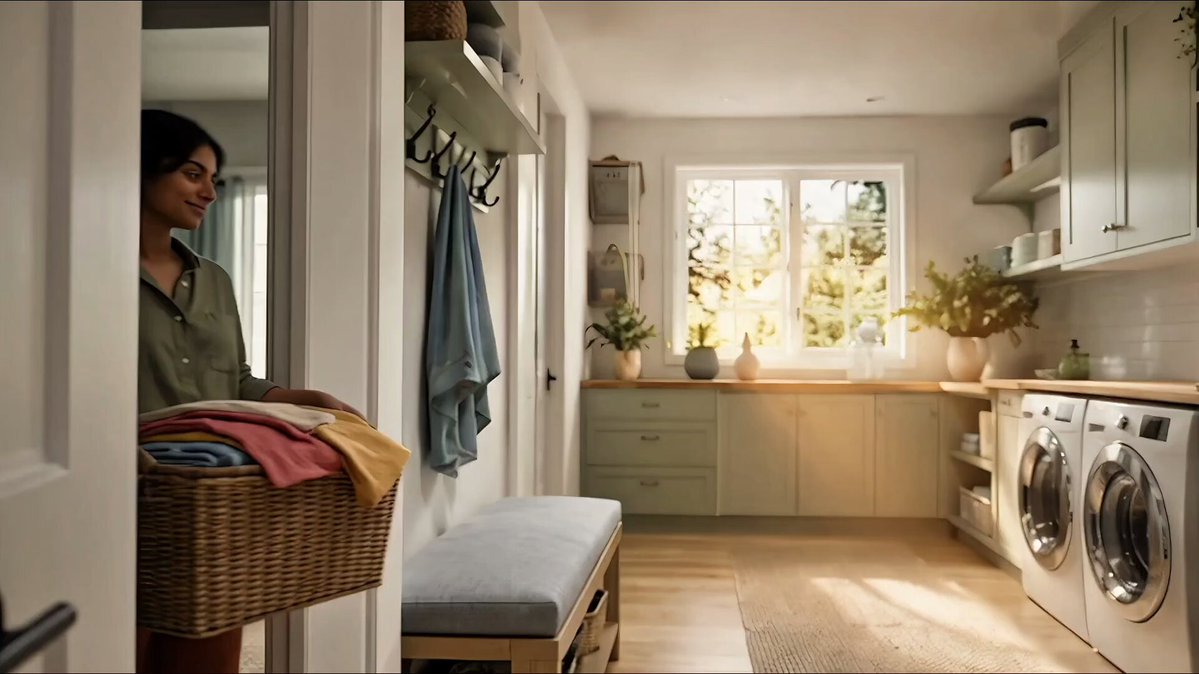
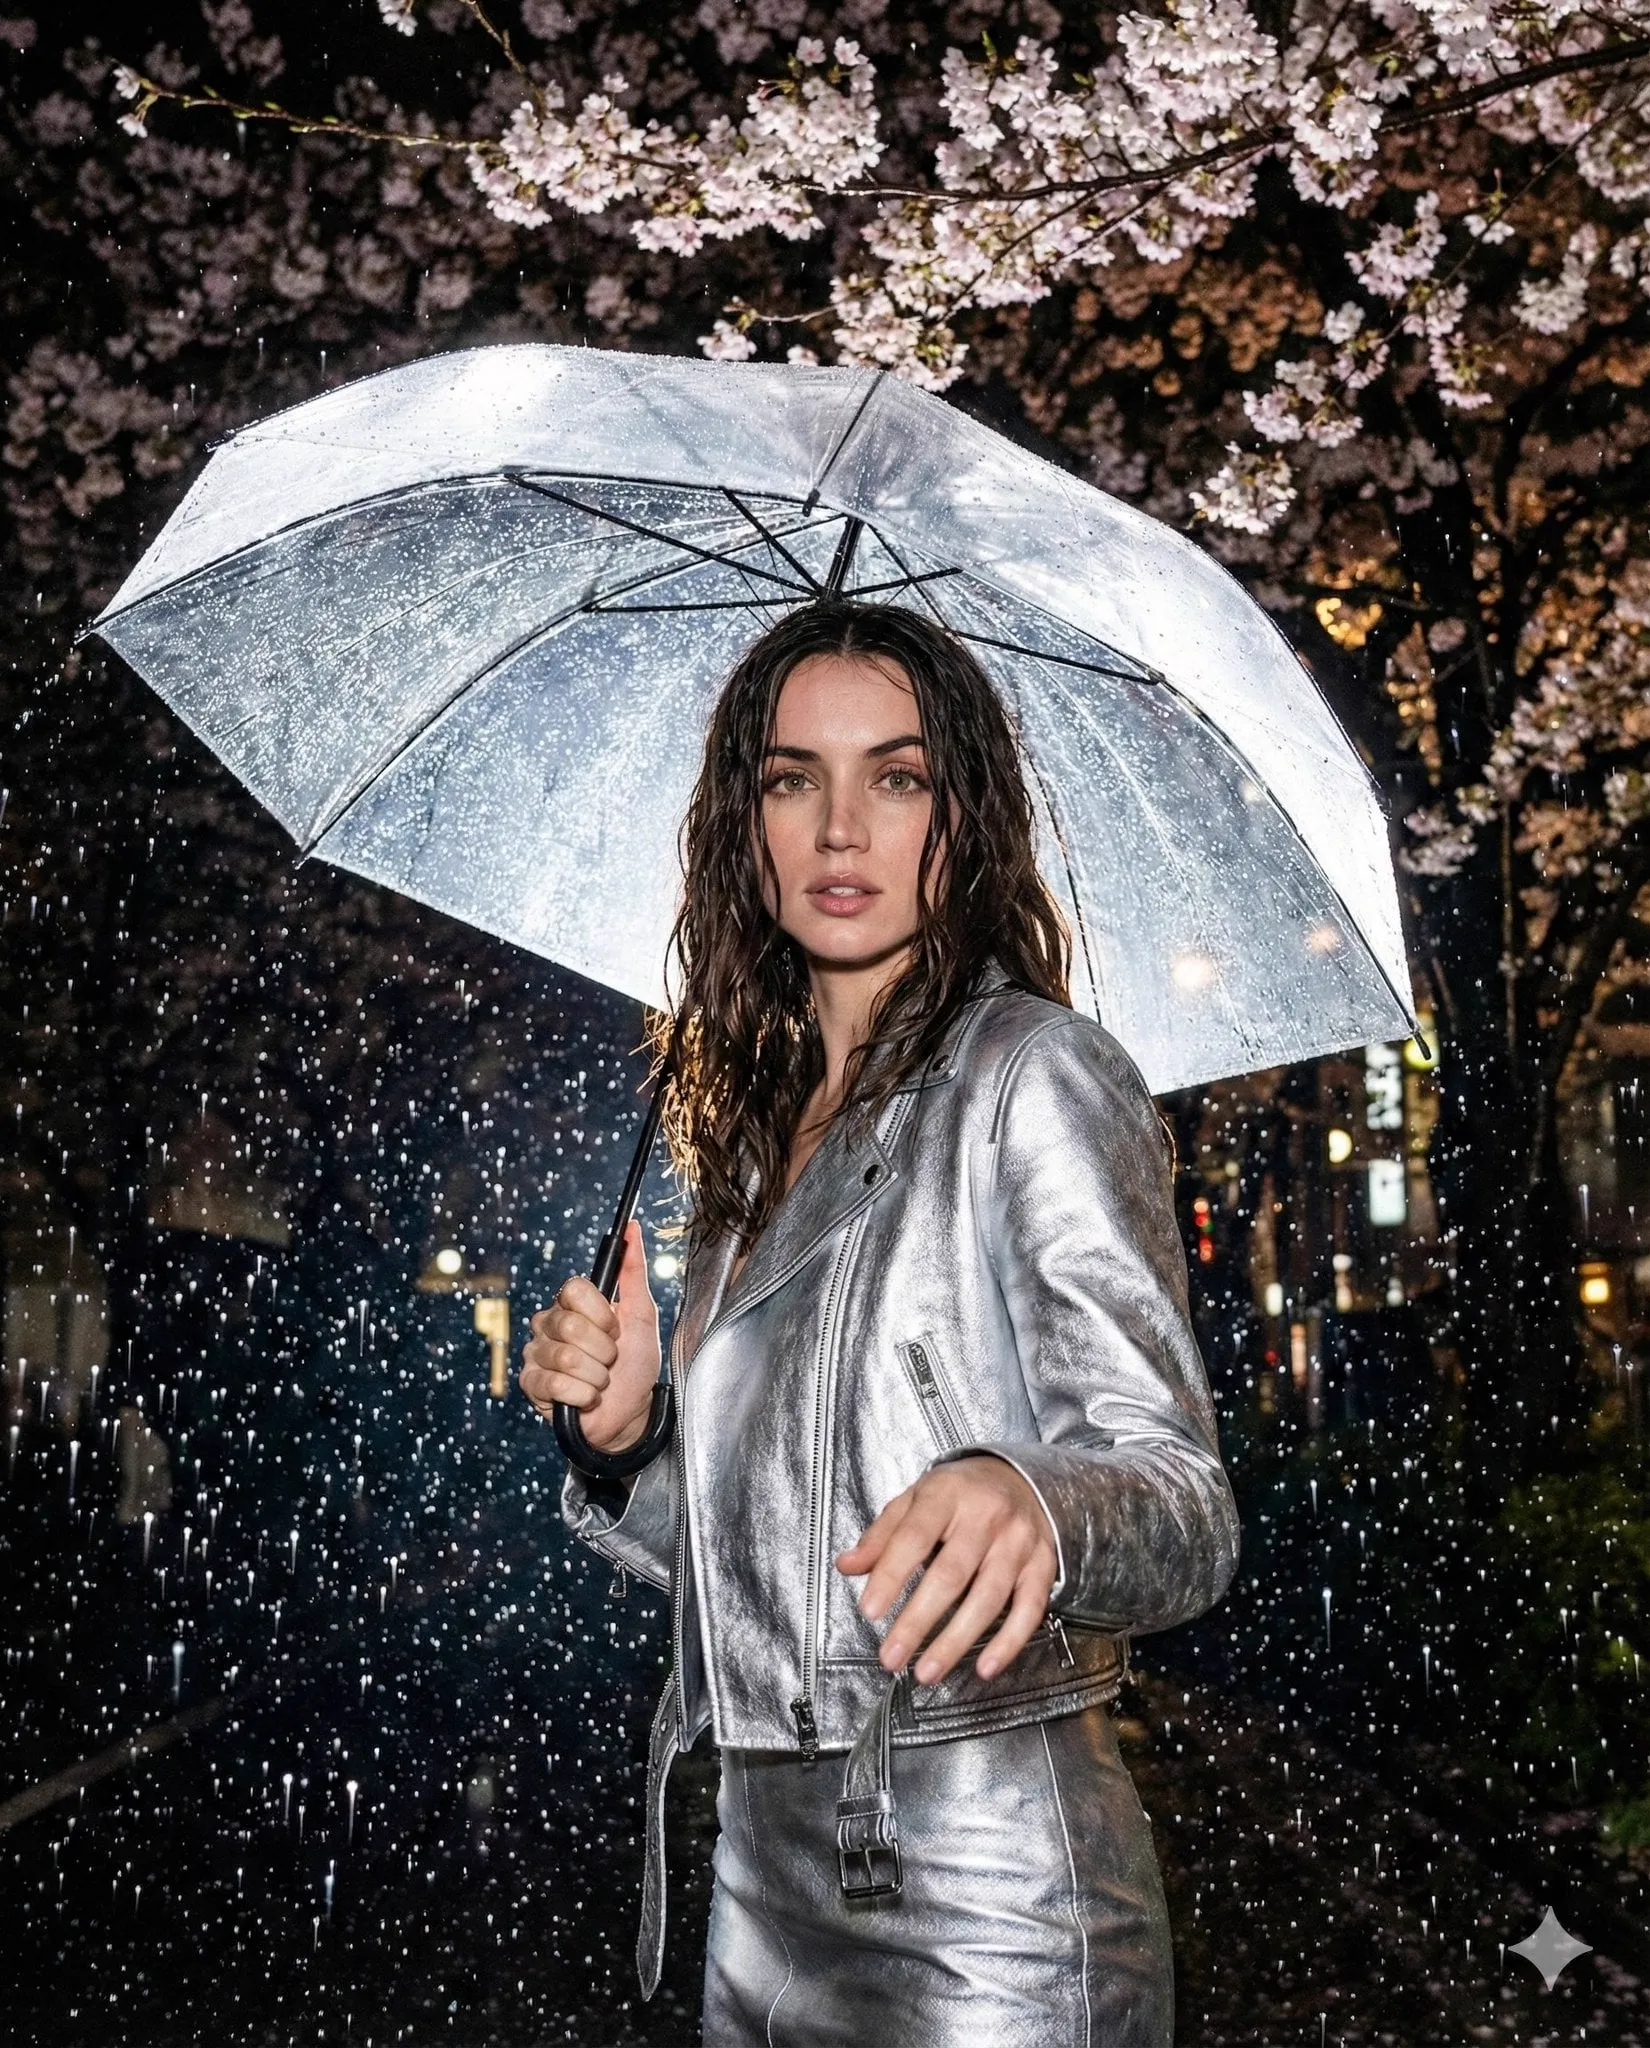
Why Photorealism Is Now the Baseline Expectation
A few years ago, AI-generated footage announced itself. Skin had a waxy sheen, hands melted, and backgrounds dissolved into mush whenever the camera moved. Viewers learned to spot the tell within two seconds, and that tell was usually enough to kill the credibility of an entire spot.
That window has closed. Modern diffusion and transformer-based video models produce frames that survive close inspection: pores, fabric weave, condensation on glass, the faint chromatic fringing of a cheap lens. The practical consequence is that believability is no longer a bonus — it is the entry ticket. Whether you are producing a product launch, a documentary insert, a social ad, or a pre-visualization for a live-action shoot, the audience assumes the footage could have come from a camera.
The interesting part is that photorealism is rarely about the model alone. Two people using the same engine can produce wildly different results, because realism emerges from a chain of decisions: how you condition the generation, how you describe light, how you handle motion, and how much post-processing discipline you apply. This guide walks through that chain end to end so you can build a workflow that produces consistent, defensible results rather than occasional lucky frames.
What Photorealism Actually Means for Moving Images
In a still image, photorealism is mostly detail and light. In motion, it is four separate problems stacked on top of each other.
Material accuracy. Real surfaces scatter light in specific ways. Skin has subsurface scattering, so shadows on a face are warmer and softer than shadows on a wall. Brushed metal smears highlights along its grain. Denim absorbs light while nylon bounces it. Models that get material response wrong produce the plastic look audiences instinctively distrust.
Light behavior. Single-source lighting, practical fixtures in frame, bounced fill from a bright floor, and believable falloff all signal authenticity. So do optical imperfections: slight vignetting, mild barrel distortion on wide lenses, motion blur that matches shutter angle, and sensor noise that increases in shadows.
Motion plausibility. Weight and inertia are the hardest thing to fake. A character who turns without shifting their center of mass reads as animated, no matter how detailed the skin. Hair and cloth need secondary motion that lags behind the body.
Temporal stability. This is where video generation diverges most from still generation. Textures must not crawl, identity must not drift between frames, and edges must not boil. Temporal coherence is the single biggest differentiator between a clip that passes as footage and one that does not.
If you treat these four as separate quality gates, you can diagnose failures precisely instead of re-rolling prompts and hoping.
The Building Blocks of a Photorealistic Pipeline
Generation backbones
Most current systems rely on latent diffusion, increasingly combined with transformer components that model long-range relationships between tokens in space and time. In practice, you do not need to know the architecture, but you do need to know its consequences: diffusion models reward precise language, they respond strongly to reference imagery, and they degrade when a prompt tries to control too many independent variables at once. Newer video-native architectures handle longer shots with fewer identity breaks, which matters greatly for dialogue scenes.
Conditioning and control layers
Raw text prompting gives you a suggestion; conditioning gives you a specification. Depth maps, pose skeletons, edge maps, segmentation masks, and camera-motion trajectories let you lock composition while the model handles surface detail. This is the difference between hoping the subject stands in the right third of the frame and guaranteeing it. If your pipeline does not include at least one structural conditioning pass, adding it is usually the highest-leverage upgrade available.
Motion and temporal models
Frame interpolation smooths a low frame rate into a high one; optical-flow-based retiming can rescue a shot that stutters. Identity-preserving modules keep a face consistent across cuts. Together these tools let you generate shorter, higher-quality segments and assemble them into something that feels continuous — a strategy that outperforms generating one long clip and praying.
Matching the Model to the Shot
No single engine wins every category. Build a small stable and route shots accordingly.
Character close-ups and dialogue
Prioritize identity consistency and skin rendering. Look for strong reference-image support so you can feed the same portrait across multiple shots. Test with a three-shot sequence: medium, close-up, and over-the-shoulder. If the jawline or eye spacing shifts between them, the model is wrong for this job regardless of how good a single frame looks.
Product, food, and tabletop
Here, precision beats atmosphere. You want crisp micro-detail, controlled specular highlights, and reliable macro depth of field. Models that over-stylize will invent textures on packaging. Generate a clean hero frame first, then animate with a gentle camera move — a slow dolly or a subtle parallax push. Product footage rarely needs dramatic motion; it needs flawless surfaces.
Environment and architecture
Wide shots reward models with strong geometric reasoning. Watch for warped verticals, impossible window counts, and staircases that bend. Conditioning on a line drawing or depth map solves most of this. Atmospheric effects — haze, rain, dust — hide small geometry errors and add realism cheaply, which is why moody weather is a favorite in AI-heavy productions.
Hybrid: stills into motion
The most reliable approach for commercial work is hybrid. Generate or photograph a keyframe, refine it in an image editor, then use image-to-video to add motion. You keep full control of composition and grading, and the model only has to solve the motion problem. Most teams that struggle with pure text-to-video find their quality jumps immediately when they adopt this pattern.
A Repeatable Prompt Framework
The six-slot structure
Write every prompt in the same order so you can debug systematically: subject, action, lens and camera, lighting, environment and atmosphere, and render notes. For example: a woman in her thirties, mid-sentence, slight head turn; 50mm lens at f/2, handheld; warm window light from camera left with soft fill; small apartment kitchen, late afternoon; natural skin texture, subtle grain, shallow depth of field. Slot-based prompts make it obvious which element caused a bad result.
Negative prompts that earn their place
Keep the negative list short and specific. Long lists of vague dislikes confuse the model. Useful entries target recurring artifacts: extra fingers, warped text, duplicate limbs, plastic skin, oversaturated highlights, watermark, blown-out sky. Update the list per project, not per prompt.
Reference conditioning
Use one image per concept. If you supply three portraits as a style reference, expect the model to blend faces. Feed a single clean reference for identity and describe wardrobe and environment in text. This one habit prevents a large share of consistency problems.
End-to-End Workflow: Brief to Locked Clip
Step 1 — Shot list and style bible
Write down every shot with its duration, framing, and purpose. Add a style bible: two or three reference frames, a lighting rule, a color palette, and a stated lens family. Ten minutes here saves hours of re-generation later, and it is what allows two operators to produce visually matching work.
Step 2 — Keyframe generation and selection
Generate stills first. Produce eight to twelve candidates per shot, then select one and refine it in an image editor: fix hands, adjust contrast, clean up edges. This frame becomes your control document. Resist the urge to accept a merely acceptable keyframe — every flaw you accept here will be amplified in motion.
Step 3 — Motion pass
Animate the approved keyframe with a modest camera instruction. Short segments of three to five seconds are more reliable than long ones. Generate three variations, then pick the one with the cleanest temporal behavior rather than the most dramatic movement.
Step 4 — Assembly, upscale, interpolate, grade
Assemble in an editor, upscale each segment, interpolate to your target frame rate, then grade the whole sequence as a unit. Grading last is essential: applying a single film emulation, grain plate, and contrast curve across every shot is what makes a sequence feel like one camera shot it.
Step 5 — Review loop
Review at full size, then at thumbnail size, then muted. Problems invisible at full size often scream in a small preview, and vice versa. Log each defect with the step that caused it so the fix goes to the right stage instead of triggering a full re-generation.
Lighting and Camera Language That Sells Realism
Choose a lighting motivation before you write a prompt. A single motivated source — a window, a practical lamp, a doorway — immediately reads as real, while even, directionless light reads as rendered. Then decide the contrast ratio: high-key for commercial cleanliness, low-key for drama, and soft fill for anything involving faces.
Camera language matters just as much. Pick a lens family and stay in it. A 35mm reportage look with slight handheld drift is easier to keep consistent than a mix of wide and telephoto shots. Add one imperfection per shot and no more: a little lens flare, a touch of noise in the shadows, or a small focus miss. Real footage is imperfect in small, consistent ways.
Finally, respect shutter logic. Motion blur should correspond to a plausible shutter angle, and fast pans should smear. Footage with perfectly crisp motion at high frame rates looks like a rendering, not a recording.
Quality Control, Responsible Use, and Disclosure
Artifact checklist
Before a clip leaves your desk, check: hands and fingers, teeth, eyes and pupils, hair edges against background, text on signage, reflections and shadows matching light direction, and any background faces. Also scan for texture crawl across ten consecutive frames — freeze-frame stepping is the fastest way to catch it.
Consistency across a sequence
Build a continuity sheet listing wardrobe, hair, props, weather, and time of day. Compare the first and last frame of every cut side by side. Most continuity errors come from regenerating a shot without re-reading the sheet, not from the model.
Likeness, consent, and disclosure
If a generated person resembles a real individual, stop and reassess. Use synthetic identities, keep signed releases for any real person's likeness, and avoid placing generated people in contexts that imply they said or did something they did not. Label synthetic footage where your audience, client, or platform expects it, and follow local rules on political and advertising content. Ethical guardrails are not just compliance — they protect the client relationship that makes the workflow sustainable.
Common Mistakes That Break the Illusion
- Overloading a single prompt. Five simultaneous changes produce an average of all five. Change one variable per iteration.
- Skipping the keyframe stage. Motion generation cannot repair a weak still.
- Ignoring scale. A coffee cup the size of a bucket destroys believability instantly. Anchor scale with a known object in frame.
- Uniform sharpness. Real footage has depth of field. Everything in focus looks artificial.
- Neglecting audio. Even simple room tone and foley do enormous work in making generated visuals feel captured rather than composed.
- Editing before grading. Grading last keeps the sequence coherent; grading per clip creates a patchwork.
FAQ
How long should a generated clip be?
Three to five seconds per segment is the sweet spot for most models. Longer shots are possible but usually cost more attempts than they save in editing.
Do I need a powerful local machine?
Not necessarily. Cloud generation removes hardware constraints, while local setups offer privacy and unlimited iteration. Many teams hybridize: local for iteration, cloud for final high-resolution renders.
Why do my faces drift between shots?
Usually because each shot was generated fresh from text. Fix it by reusing a single identity reference image and conditioning the pose for each shot.
How do I make AI footage match live-action plates?
Match three things: lens distortion, grain, and color. Apply the same grain plate and grade to both, and add slight motion blur to the generated footage if the plate was shot at a conventional shutter angle.
Is upscaling enough, or do I need to re-render?
Upscaling recovers resolution, not structure. If details are wrong, re-render the segment at the keyframe stage — upscaling will simply produce a sharper version of the mistake.
Final Checklist Before You Publish
Confirm the keyframe is clean, the motion has no crawl, textures do not boil, and hands, eyes, and text have been inspected frame by frame. Verify continuity against your sheet, apply the sequence grade and grain pass, add room tone, and check the clip at thumbnail size on a phone. Finish by logging the prompt, model, and settings for every shot — a documented pipeline is the only thing that turns a lucky result into a repeatable one.
