
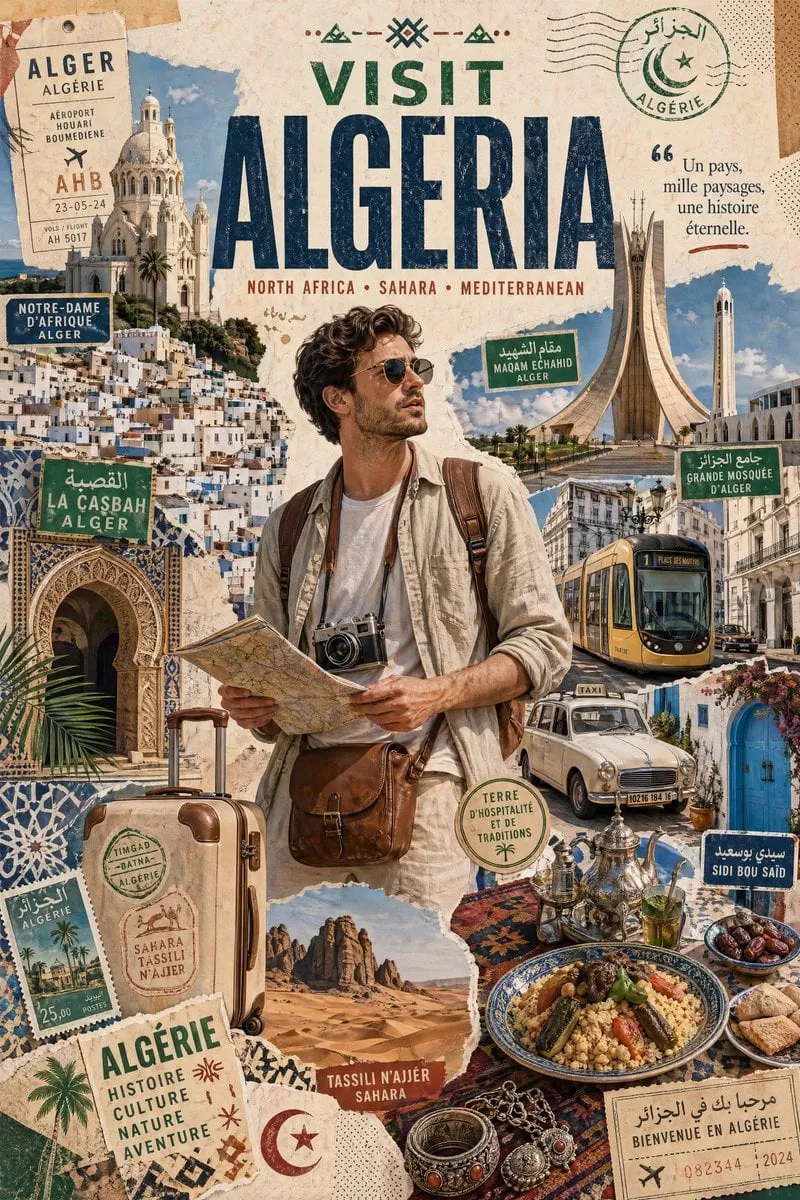
The Pixel Lego Effect is less a filter and more a way of thinking about composition. Instead of asking a model to invent an entire scene from a single sentence, you build the scene from small, reusable visual modules — a face, a costume, a light direction, a color palette, a background plate — and then snap those modules together to produce every new frame. The result looks deliberate and consistent, the way a Lego model looks like one object even though it was assembled from hundreds of identical studs.
This guide walks through the full workflow: what the technique actually is, why it solves the style-drift problem in long-form AI video, how to build a reusable piece library, how multi-image fusion behaves in practice, how to write prompts that keep pieces aligned, how to animate the result, and which mistakes waste the most time. Everything here is tool-agnostic; the same logic applies whether you are working in a browser-based generator, a node-based pipeline, or a desktop editing suite.
What the Pixel Lego Effect Really Means
The term gets used in two different ways, and mixing them up causes confusion.
The first meaning is literal and aesthetic: an image or video that looks assembled from visible blocks and studs, like a mosaic, a pixel-art render, or a stop-motion build made of plastic bricks. That look is fun for thumbnails and short social clips, but it is a style choice, not a technique.
The second meaning — the one that actually changes how you work — is compositional. Here, a "Lego piece" is any small element you can define once and reuse indefinitely across shots:
- An identity block: the subject's face, hairline, eye shape, and skin tone.
- A wardrobe block: jacket cut, fabric weave, color, and wear pattern.
- A palette block: five to seven swatches that define the whole project's color range.
- A light block: key direction, softness, contrast ratio, and color temperature.
- An environment block: architecture, ground texture, weather, and background depth.
- A camera block: focal length feel, framing, and subject scale in frame.
When you lock those blocks, every subsequent shot is a recombination rather than a fresh invention. The model is not asked to imagine a character; it is asked to place an already-approved character into a new arrangement. That single shift is what produces continuity across dozens of stills and several minutes of video.
The practical definition, then: the Pixel Lego Effect is the practice of decomposing a visual identity into reusable modules and recombining them through multi-image reference fusion, so that consistency is engineered rather than hoped for.
Why Style Drift Breaks Long-Form AI Video
Every generation is an independent sample. Even with an identical prompt, a model will land on slightly different proportions, slightly different fabric folds, and slightly different lighting. Individually those differences are invisible. Stacked across twenty shots, they become a different character.
Three failure modes show up again and again:
Identity drift. The jaw narrows, the eyes widen, the hair color warms by a few degrees. By shot twelve the subject reads as a cousin rather than the same person.
Wardrobe drift. A jacket gains a zipper it never had, then loses a pocket, then changes from charcoal to slate blue. Viewers may not name the problem, but they feel the discontinuity.
Atmosphere drift. Color temperature creeps from warm amber to cool cyan, and the film stops feeling like one world.
Audiences are extremely sensitive to these breaks. A face that changes between cuts reads as a production error, and production errors cost attention. The Pixel Lego approach attacks all three at once by turning loose adjectives into concrete reference images that the model must respect.
The deeper principle: consistency is a constraint problem, not a creativity problem. Constraints do not reduce quality — they concentrate it. When the identity is fixed, creative energy goes into staging, action, and rhythm instead of re-solving the character every time.
The Modular Mindset: Thinking in Snap-Together Pieces
Before generating anything, define the pieces. This planning step takes thirty minutes and saves hours.
Palette, light, and framing decisions
Pick a limited palette and write down the swatches. Five to seven colors is plenty: a base, a shadow tone, a highlight, an accent, and one or two environment tones. Note the approximate hex values if your tool supports color references, and keep the same list in every prompt.
Then decide the light once. Key direction (left, right, top, back), softness (hard-edged sun versus overcast diffusion), and color temperature (warm interior tungsten versus cool daylight). Lighting is the single most underrated consistency anchor because it affects every surface in frame.
Finally, fix framing rules: aspect ratio, subject scale in frame (for example, head-and-shoulders occupies roughly one third of frame height), and camera height (eye level, slightly low, slightly high). Never mix these casually mid-project.
Building a reusable piece library
Create a folder per project and save approved assets as you go. A working library usually contains:
- Hero portrait — front-facing, neutral expression, clean light.
- Three-quarter portrait — the workhorse angle for dialogue and action.
- Profile portrait — needed for walking and driving shots.
- Full-body turnaround — front, side, back, if the character moves.
- Costume detail crops — collar, cuffs, belt, boot, fabric close-up.
- Prop references — phone, bag, weapon, tool, book.
- Environment plate — the empty location with correct light.
- Texture swatch — ground, wall, or water material.
- Palette card — a simple grid image of your swatches.
Aim for eight to twelve approved assets minimum. Name them by function, not by date, so you can find the "three-quarter neutral" in two seconds at hour three of a session.
Step-by-Step: Assembling a Pixel Lego Scene
The workflow below takes a scene from idea to a consistent set of shots.
1. Write a shot list, not a prompt
Describe the sequence in plain language first: who is in frame, what they do, where the camera sits, and what changes between shots. For example, "Detective crosses a wet neon alley, stops under a flickering sign, looks up, then walks out of frame left." Four shots, each with a clear purpose. Writing the list first prevents the common trap of generating attractive images that do not connect.
2. Generate and approve a hero frame
Build one image that establishes identity, wardrobe, palette, and lighting at the same time. Iterate until you would be happy to see this exact character in twenty more frames. This frame becomes your master reference — treat it as locked. Any change later multiplies across every downstream shot.
3. Slice the hero frame into modules
Use an image editor to crop and export the pieces you will need: a tight face crop, a torso crop showing the jacket, a crop of the background wall, a crop of the ground. These crops are now individual Lego bricks. Small crops are often more effective than the full frame because they direct the model's attention to one attribute at a time.
4. Recombine with multi-image fusion
Feed the crops back in as references for the next shot, together with a short prompt describing the new action and camera angle. The identity crop holds the face, the torso crop holds the wardrobe, the environment crop holds the location, and the palette card holds the color range. You are not describing the character anymore — you are placing them.
5. Lock the style before moving on
Once shot two matches shot one, save the seed, the reference set, and the prompt skeleton. Every remaining shot reuses that exact combination with only the action and camera lines edited. If a shot fails, change one variable at a time: first the action wording, then the reference order, then the weighting.
Multi-Image Fusion in Practice: Weighting and Ordering
Fusion is the engine that makes snap-together composition work, and it has quirks worth knowing.
Three to five references is the sweet spot. With fewer, the model improvises. With many more, references start competing: two different face crops can average into an unfamiliar third face. If you must supply six or more, keep them in clearly distinct categories — one identity, one wardrobe, one environment, one palette — rather than several of the same kind.
Order matters. Most implementations weight earlier slots more heavily. Put identity first, wardrobe second, environment third, stylistic extras last. If your tool exposes explicit weights, start near 0.7 for identity, 0.5 for wardrobe, 0.4 for environment, and adjust from there.
Conflicts resolve unpredictably. A warm-lit portrait and a cool-lit portrait used together will not blend politely; they will fight. Audit your reference set for lighting and color contradictions before blaming the prompt.
Fusion is not a guarantee of pixel-level identity. It produces a strong family resemblance. For exact facial continuity across shots, combine fusion with a face-consistency utility, a trained subject embedding, or a cleanup pass in an editor where you composite the approved face back onto the generated body.
A practical routine: generate at low cost and low resolution, evaluate identity match, then re-render the approved composition at final resolution with the same reference set. Never polish a shot whose identity you have not verified.
Prompt Patterns That Keep the Pieces Aligned
Prompts do not need to be poetic. They need to be structured and repeatable. A reliable template:
[identity block] + [wardrobe block] + [action] + [environment] + [light and palette] + [camera] + [style anchors]
Concretely, the identity and wardrobe blocks stay verbatim across every shot of a scene. Only the action and camera lines change:
Shot A: woman, early thirties, dark curly hair, olive skin, freckles across nose; charcoal wool coat, brass buttons, black turtleneck; standing still; rain-soaked alley behind a diner; warm amber sign light from the left, deep shadows; medium shot, eye level, subject one third of frame; cinematic, subtle grain
Shot B: same text, with standing still replaced by walking toward camera, hands in pockets and medium shot replaced by wide shot, slightly low angle.
Rules that keep this stable:
- Never rewrite the identity block mid-scene. Copy and paste it.
- Keep total prompt length moderate. Long prompts dilute attention; let the reference images carry detail.
- Avoid stacking multiple style anchors. "Cinematic" plus "anime" plus "watercolor" produces mush.
- Put negative constraints where they help: no extra fingers, no text, no watermark, no duplicate limbs.
- If your tool supports seeds, reuse one seed for a scene and change only the prompt lines.
Animation: Turning Snap-Together Stills Into Motion
Once your stills are consistent, animation becomes an extension of the same idea. Each animation is another brick, so keep motion small and purposeful.
Animate from the approved still, not from the prompt. Image-to-video preserves identity far better than text-to-video because the first frame is already correct.
Use short shots. Three to four seconds per clip is enough to establish action and keeps drift low. Assemble a longer sequence in the edit, not in the generator.
Describe one motion per clip. "She turns her head left and exhales" is one clip. "She turns, walks, opens a door, and sits" is four clips that will each drift differently.
Repeat camera moves as a motif. If you use a slow push-in, use a slow push-in. Matching the speed and direction of camera movement across shots creates the impression of a single camera crew, which is a huge part of perceived consistency.
Match cut on shape and color. Cut from the curve of a neon sign to the curve of a shoulder, or from an amber wall to an amber jacket. These transitions make modular footage feel authored rather than assembled.
Do a stabilization and grain pass at the end. Apply the same grain, sharpening, and color grade across every clip in a timeline. A uniform finishing pass hides small differences between generations better than any prompt tweak.
Quality Control Checklist Before You Render
Run this list on every shot before exporting. It takes ninety seconds and prevents expensive re-renders.
- Face match: eye spacing, jaw width, hairline, and skin tone against the hero frame.
- Wardrobe match: garment count, fasteners, color, and wear detail.
- Palette match: does the frame read within your swatch set, or has a new color entered?
- Light match: key direction and shadow softness consistent with the previous shot.
- Horizon and scale: subject height and ground line consistent across cuts.
- Hands and teeth: check for melting or duplicate digits, the two most common artifacts.
- Background continuity: window positions, signage, and street furniture stable.
- Resolution and aspect: same output dimensions for every clip in the sequence.
- Motion smoothness: no warping at the edges during camera moves.
- Audio readiness: if there is dialogue, leave headroom in pacing for the lines.
Common Mistakes and How to Fix Them
Too many references. Symptoms: blurry identity, averaged faces, muddy wardrobe. Fix: cut to three or four references, one per category.
Mixing styles mid-project. Symptoms: one shot photoreal, the next illustrated. Fix: remove competing style anchors from the prompt skeleton and rely on the reference images.
Regenerating instead of editing. Symptoms: ten outputs, none quite right. Fix: take the closest result into an image editor, composite the approved face, paint the wardrobe, then re-render only if needed. Editing is faster than another roll of the dice.
Ignoring seeds and settings. Symptoms: a great shot you can never reproduce. Fix: log seed, model version, reference list, weights, and prompt text in a project notes file. Future you will need it.
No piece library. Symptoms: rebuilding the character from scratch at every session. Fix: export and organize assets the moment a frame is approved.
Over-detailed prompts. Symptoms: inconsistent micro-detail, ignored instructions. Fix: shorten the prompt, let images carry the specifics, keep the identity block verbatim.
Fixing everything at once. Symptoms: you cannot tell what helped. Fix: change one variable per iteration, then compare side by side.
FAQ
Is the Pixel Lego Effect the same as pixel art or mosaic filters? No. The blocky aesthetic is one possible output, but the technique is about modular composition. You can apply it to photoreal footage and nobody will see a single visible brick.
How many reference images do I actually need? Three to five for most shots: identity, wardrobe, environment, and optionally a palette card. Add a prop reference only when the prop is story-critical.
Can I use this for a talking-head video with one character? Yes, and it is the easiest case. Lock one identity crop and one wardrobe crop, then vary only the background and camera angle between takes.
What if the model keeps changing the hairstyle? Create a dedicated hair crop at higher zoom and place it first in the reference stack. Hair is a strong identity signal, so a tight crop usually fixes it faster than any adjective.
Should I train a custom subject model? Only if you need dozens of shots across multiple sessions. For a single short project, reference fusion plus an editing pass is usually faster to set up.
How do I keep color consistent between clips generated at different times? Grade everything in one timeline at the end. Export a still of your first approved shot, keep it on a reference layer, and match each new clip against it visually.
Can I combine this workflow with stock footage? Yes. Match the generated palette and grain to the stock, then use the same color grade across both. The eye forgives a lot when tone and grain agree.
What is the fastest way to start today? Generate one hero frame, crop it into a face, a torso, and a background plate, then generate a second shot using those three crops. If shot two reads as the same person in the same world, you have the workflow. Everything else is refinement.
