
What "Pixel Lego" Means in an AI Video Pipeline
Pixel Lego is not a product, a plugin, or a specific model. It is a working method: treating every image you generate as a set of small, reusable, precisely controlled units that can be assembled, disassembled, and reassembled across an entire video. Think of a plastic brick system. Each brick is simple on its own, but because the bricks are standardized, you can build a house, tear it down, and rebuild a spaceship from the same parts.
In generative video, the "bricks" are pixels, patches, and latent regions. A character's face is a brick cluster. A jacket is a brick cluster. A background plate, a lighting direction, a lens character — all bricks. The Pixel Lego approach says: do not generate a whole new world for every shot. Generate a stable set of bricks once, then reassemble them shot by shot so the sequence reads as one continuous world.
This matters because most AI video fails not at the level of a single frame, but at the level of a sequence. A clip can look stunning in isolation and still destroy a film, because the audience is tracking continuity across minutes, not seconds. Pixel Lego is the discipline of protecting that continuity through deliberate, modular image processing.
Why Shot-to-Shot Consistency Is the Real Bottleneck
When you generate each shot independently from a fresh text prompt, you are asking the model to re-invent your protagonist dozens of times. Small reinterpretations compound:
- The cheekbones shift slightly between shot 3 and shot 9.
- The jacket changes from navy to almost-black to steel blue.
- The window light moves from the left in one angle to the right in the reverse angle.
- The film grain disappears in wide shots and returns in close-ups.
- Hair length drifts by a few centimeters per generation.
Individually, none of these is fatal. Together, they read as amateur inconsistency, and viewers disengage long before they can articulate why.
Long-form AI video also multiplies the problem. A 30-second social clip can survive on novelty. A three-minute narrative, a product explainer, or a training module cannot. The longer the runtime, the more the audience builds a mental model of your world — and the more painful every deviation becomes.
The Pixel Lego mindset solves this by moving the creative decision earlier. Instead of re-deciding the character in every shot, you decide once, freeze that decision as reusable assets, and then only vary the things that should vary: camera angle, action, pacing, and emotional beat.
The Three Layers of a Pixel Lego Block
Before you can assemble anything, you need to know what your raw materials actually are. In practice, AI video work operates on three layers of granularity, and good pipelines address all three.
Layer 1: Pixel-level blocks
These are the finest units: masked regions, alpha mattes, depth maps, normal maps, and edge maps. You rarely hand-edit these, but you generate and reuse them constantly. A character matte extracted from a hero frame becomes a pixel-level block you can composite into new shots. A depth map from one angle can guide parallax in another.
Layer 2: Patch-level blocks
Patches are semantic chunks: a face, a hand, a jacket, a chair, a doorframe, a patch of forest floor. Segmentation tools let you isolate these cleanly. Once isolated, a patch can be re-conditioned into a new composition, recolored, relit, or held frozen while everything around it changes.
Layer 3: Latent-level blocks
This is where consistency is truly won. Latent representations, reference embeddings, and conditioning images carry the visual identity of an asset into a new generation. You are not pasting pixels; you are instructing the model to preserve a visual identity while changing pose, framing, or environment. Latent-level control is softer than pixel-level control, but it is far more flexible for motion.
Building your reference kit
A usable reference kit for a short film usually contains:
- A character sheet: front, three-quarter, profile, back, plus two extreme close-ups of the face.
- A wardrobe sheet: each outfit isolated on a neutral background, with fabric texture details.
- A prop sheet: only the objects that appear in more than one shot.
- An environment sheet: wide establishing plate, mid plate, and a detail texture crop.
- A lighting and lens note: key direction, contrast ratio, color temperature, focal length feel, and film grain intensity.
Ten to twenty well-chosen references will out-perform a folder of two hundred random stills. Curation is the work.
Multi-Image Fusion: How References Keep Characters Stable
Multi-image fusion is the technical heart of the Pixel Lego method. Rather than conditioning a generation on a single reference, you supply several references simultaneously and let the model reconcile them into one coherent frame.
The most useful fusion patterns are:
Identity plus pose. One reference carries who the character is; a second carries the body position or camera angle you need. This is how you get a character to raise an arm without the face drifting.
Character plus environment. A character sheet plus a background plate, so the model places the person into a location instead of inventing a new one.
Style plus structure. A style reference (painted, photographic, stop-motion) plus a structural guide (depth, pose skeleton, edge map) so the composition obeys your blocking while the rendering obeys your art direction.
First frame plus last frame. When a shot needs to begin exactly where the previous one ended, generate the handoff frames first and interpolate the motion between them. This single habit removes most of the jarring cuts that plague AI sequences.
A practical rule: never ask one reference to do two jobs. If a single image is supposed to define both the character and the lighting, the model will compromise on both. Split the responsibilities across separate references.
Designing a Cross-Style Keyframe Set
Style consistency is not the same as image consistency, and mixing them is a common failure. You can keep a character perfectly stable and still produce a sequence that feels like four different films stitched together.
The fix is to separate your keyframes into a neutral base and a style layer.
Step 1: Build neutral keyframes. Generate your hero frames in a plain, low-stylization look. Flat lighting, neutral color, minimal grain. The goal is not beauty; the goal is a clean structural reference that describes pose, framing, and costume accurately.
Step 2: Define the style layer once. Write down the style as a compact, repeatable specification: rendering medium, palette, contrast curve, grain, edge treatment, and any signature artifacts. Turn it into a reusable prompt block plus one or two style reference images.
Step 3: Apply the style layer uniformly. Re-render every neutral keyframe through the same style specification. Because the structure came from stable references, the style application does not need to re-solve identity, and drift drops sharply.
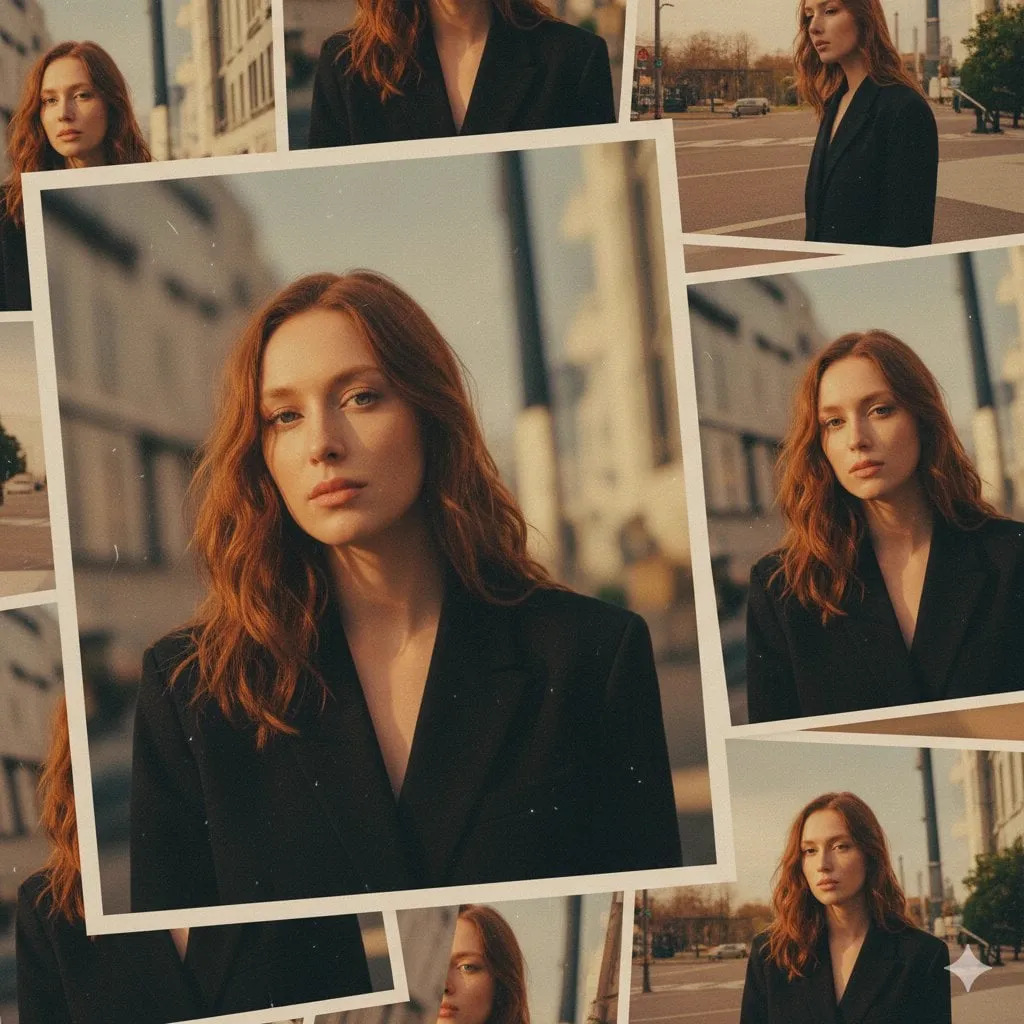
Step 4: Verify with a contact sheet. Lay all styled keyframes side by side in a single image. This is the fastest quality check in the entire pipeline. Inconsistencies that are invisible when you watch shots sequentially become obvious when the frames sit in a grid.
This base-plus-style split is what makes it realistic to produce, say, a painted storybook sequence and a photoreal version of the same story from one set of assets — without rebuilding the project from scratch.
A Practical Workflow, Start to Finish
1. Lock the visual bible
Write down, in plain language, who the characters are, what they wear, where the scenes happen, what time of day it is, and how the camera behaves. Two pages is enough. The visual bible becomes the source of truth you check against whenever a generation looks slightly off.
2. Build the reference kit
Create the ten to twenty curated references described earlier. Name files systematically — character_outfit_angle_variant — so you can find them under time pressure.
3. Block out the sequence with an animatic
Before generating any final imagery, build a rough animatic using stills, placeholders, or very cheap drafts. Cut it against your audio. Most continuity problems are actually editing problems, and they are far cheaper to fix here than after twenty polished shots.
4. Generate keyframes first, then motion
Produce a polished keyframe for every shot boundary: opening frame, closing frame, and any beat where the composition changes meaningfully. Do not start generating motion until the keyframe grid reads cleanly as a sequence.
5. Bridge shots with first-and-last-frame interpolation
Feed the closing keyframe of shot N and the opening keyframe of shot N+1 into an interpolation step. The motion between them becomes a connective tissue that hides the seam between independent generations.
6. Assemble, grade, and sound
Bring everything into your editor. Apply one unified grade across the whole timeline rather than grading shots individually — a single curve applied globally will do more for perceived consistency than hours of per-shot fiddling. Add sound early; audio continuity carries visual continuity more than most people expect.
7. Iterate selectively, not globally
When something is wrong, replace one shot, not the sequence. Resist the urge to re-roll everything. Selective iteration is the entire economic argument for a modular pipeline.
Control Techniques That Reduce Drift
Beyond reference images, a handful of habits reliably tighten consistency.
Seed discipline. Lock a seed for a shot family and vary only the prompt slots that must change. Randomizing seeds on every generation is the fastest way to guarantee drift.
Prompt skeletons. Build a reusable prompt template with fixed identity, wardrobe, and lighting clauses, plus empty slots for action and camera. Fill the slots; never rewrite the skeleton.
Negative prompt libraries. Maintain a shared list of unwanted artifacts — extra fingers, warped hands, watermark text, plastic skin, oversaturated highlights — and apply it consistently. Inconsistency in what you suppress is as damaging as inconsistency in what you request.
Motion magnitude limits. Large motion values force the model to invent detail, and invented detail drifts. Keep motion moderate and use more shots rather than one aggressive move.
Global color treatment. A single look-up table or grade applied to the finished timeline unifies subtle hue and contrast mismatches that survived generation.
A restoration pass. A light upscale-and-detail pass at the end of each shot can smooth compression artifacts and micro-flicker, making independently generated clips feel like they came from one camera.
Common Mistakes and How to Fix Them
Overloading one reference. If the model must infer face, wardrobe, environment, and lighting from a single image, it will compromise. Fix: split references by responsibility.
Skipping the animatic. Generating before editing guarantees wasted work. Fix: cut the sequence with placeholders first.
Chasing perfection in a single shot. Polishing shot 4 for an hour while shot 5 remains a draft destroys schedule predictability. Fix: get every shot to 80 percent, then raise the floor.
Inconsistent aspect ratio and resolution. Mixing output sizes forces rescaling and softens detail unevenly. Fix: decide the delivery format before you generate anything.
Ignoring audio. Silence makes visual cuts feel harder than they are. Fix: lay in scratch audio before final generation.
No version control. Overwriting good assets with experimental ones is unrecoverable. Fix: keep an approved folder that is never edited directly.
Choosing Tools: Practical Decision Criteria
Tool selection matters less than pipeline discipline, but the differences are real. Evaluate any AI video tool on these axes:
- Reference capacity. How many simultaneous image references can condition a single generation? Multi-image conditioning is the single most important capability for consistency.
- First-and-last-frame control. Can you specify both endpoints of a shot? This is what makes seamless bridging possible.
- Structural guidance. Does the tool accept depth, pose, or edge inputs so composition obeys your blocking?
- Duration per generation. Longer native clips reduce the number of seams you must hide, but they also make drift more visible; balance accordingly.
- Output resolution and frame rate. Match your delivery target to avoid soft rescaling.
- Batch and iteration speed. Fast drafts matter more than slow perfection at the start of a project.
- Local versus hosted execution. Local gives privacy and cost predictability but demands hardware; hosted gives speed but requires upload discipline.
- Licensing terms. Confirm commercial rights before you build a client deliverable on any engine.
A sensible approach is to combine two or three engines: one for keyframe image generation, one for image-to-video motion, and one for interpolation or upscaling. No single tool is best at all three, and a modular pipeline makes swapping engines painless.
Quality Control Checklist Before You Export
Run this list on every project:
- Contact sheet of all keyframes reviewed as a grid.
- Character identity verified across at least three different shots.
- Wardrobe and props checked for color and shape continuity.
- Light direction checked against the scene's established key.
- Motion direction and screen direction checked for continuity.
- Single global grade applied to the full timeline.
- Audio mixed and lip or action sync verified.
- Output resolution, frame rate, and aspect ratio matched to delivery spec.
- Approved assets archived separately from working files.
FAQ
Is Pixel Lego a specific software feature?
No. It is a methodology for organizing AI image and video generation around small, reusable visual units. You can apply it with any combination of generation, segmentation, and editing tools.
How many reference images do I actually need?
For a short narrative, ten to twenty curated references covering character, wardrobe, props, environment, and lighting are usually sufficient. More references help only if each one has a distinct, clearly defined job.
Can I keep consistency without first-and-last-frame control?
You can get close, but the work becomes manual. Without endpoint control you end up trimming and cross-dissolving to hide mismatches, which costs more editing time than generating handoff frames would have.
Does this method work for animation styles, not just photorealism?
Yes, and it often works better. Stylized rendering gives the model less room to invent plausible detail, so drift is more visible and therefore easier to correct. The base-keyframe-plus-style-layer approach handles style shifts cleanly.
What is the biggest time sink to avoid?
Re-rolling entire sequences when one shot is the problem. Build your pipeline so you can replace a single shot without touching anything else. That single capability separates projects that ship from projects that stall.
How do I know when consistency is good enough?
When a viewer stops noticing the seams. Play the sequence once at normal speed with audio, then once at half speed. If nothing catches your eye on the second pass, you are done.
