
Most people who try AI video generation for the first time follow the same path: write one long prompt, hit generate, and hope the result looks like the movie playing in their head. Sometimes it works. Usually it does not. The clip is beautiful but generic, the character changes faces between shots, and the story never accumulates the way a real film does.
Prompt chaining solves this. Instead of treating generation as a single act of luck, you break the work into a sequence of connected steps where each output becomes the context for the next. The result is not just better clips — it is an actual narrative with continuity, pacing, and intent.
Why Single-Prompt Video Fails at Story Scale
A single prompt asks one model to do five jobs at once: establish a character, design a shot, describe lighting, imply a mood, and suggest camera motion. Models handle this by averaging. You get a competent-looking frame that satisfies every constraint vaguely rather than any constraint precisely.
The problem compounds across shots. If shot one and shot eight are generated from separate prompts with no shared context, nothing forces the character's jawline, jacket color, or the direction of the sunlight to match. Viewers may not articulate why something feels off, but they notice. Continuity errors read as amateurism even when the individual frames are stunning.
There is also a cost dimension. Long, overloaded prompts are harder to debug. When a shot comes out wrong, you cannot tell whether the failure came from the character description, the camera instruction, or the style tags fighting each other. Short, single-purpose prompts in a chain fail in diagnosable ways, which makes iteration dramatically faster.
Finally, single prompts do not scale to duration. A six-second clip from one prompt is a postcard. A three-minute story needs twenty to forty shots, consistent characters, deliberate transitions, and audio that tracks the emotional arc. That is a production problem, not a prompting problem — and production problems get solved with pipelines.
What a Prompt Chain Actually Is
A prompt chain is a sequence of generation steps where the result of each step becomes structured input for the next. That input can take several forms: a text description of what was produced, a reference image, a depth map, a motion vector, or a written continuity note that you feed into the following prompt.
The key word is structured. A chain is not just "generate, then generate again." It is a defined handoff. You decide in advance what travels forward: the character's appearance, the color palette, the lens choice, the time of day, the emotional temperature. Everything else is free to change.
The Layers of a Workflow Chain
Most practical chains have four layers:
- Story layer — beat sheets, scene descriptions, dialogue intent. Human-written, never generated.
- Design layer — character sheets, location references, color scripts, style anchors. Often image-generated, then curated by hand.
- Shot layer — individual clips generated with the design layer pinned as reference.
- Assembly layer — editing, sound, color, and pacing decisions that bind the shots into a scene.
Beginners collapse all four into one prompt. Professionals keep them separate, because each layer fails differently and needs different fixes.
How Long Should a Chain Be?
Longer chains are not automatically better. Each link adds latency, cost, and a new place for drift to enter. A useful rule: add a link only when it removes ambiguity that a human editor would otherwise have to fix in post.
For a talking-head explainer, three links may be enough. For an animated short with recurring characters and shifting locations, fifteen to thirty links is normal. If your chain exceeds roughly forty steps for a two-minute piece, you are probably over-engineering and should consolidate.
Designing the Chain: Roles, Order, and Handoffs
Before generating anything, write the chain down. A simple table works: step number, purpose, input, output, and what gets passed forward. This document is the difference between a pipeline and an afternoon of random clicking.
Order matters more than most people expect. Establish look and character before motion. Establish motion before sound. Establish sound before final timing. If you generate music first, you will end up cutting visuals to fit the audio, which is fine for music videos but painful for narrative work.
Defining the Handoff Contract
Each step in the chain should specify exactly what it hands to the next:
- Identity tokens — a short, stable description of recurring characters, reused verbatim.
- Reference frames — one to three images pinned as visual anchors.
- Continuity notes — plain-language reminders, such as "same overcast light as shot 4" or "jacket now wet."
- Negative constraints — what must not appear, which is often more powerful than positive description.
Treat these like a contract. If a generated clip violates the contract, you regenerate that link rather than patching the next one and letting the error propagate.
Versioning Your Chain
Keep every iteration. Naming convention matters: scene02_shot07_v03_approved. When a later shot drifts, you will want to know which earlier version anchored the look. Without versioning, you cannot reproduce a result you liked an hour ago, and reproducibility is the entire point of a pipeline.
Model Selection: Matching the Tool to the Link
Different generative video systems excel at different things. Some produce the most realistic human motion. Others handle stylized animation, camera movement, or long-duration coherence better. A chain gives you the freedom to route each step to the model that suits it.
Practical selection criteria:
- Duration limits — can the model produce the shot length you need, or must you stitch?
- Reference conditioning — does it accept image, pose, or style references, and how strongly do they bind?
- Motion coherence — how well does it handle complex action over five or more seconds?
- Determinism — can you lock a seed for repeatable results?
- Iteration speed — how fast is a rejected take, since you will produce many?
A common pattern is to use a fast, cheap model for blocking and composition tests, then a higher-fidelity model for the approved shots. Another is to generate keyframes in an image model and animate them in a video model, which gives you far more control over framing than text-to-video alone.
When to Split the Model Chain
Split when quality is uneven, when a shot type consistently fails, or when one model's stylistic fingerprint begins to dominate the whole piece. Blending two or three systems across a project is normal in professional work — the goal is a consistent look, not a single vendor.
Character Continuity Across Shots
The single hardest problem in AI video storytelling is keeping a character recognizably the same person across many shots, angles, and lighting conditions. Text descriptions alone rarely hold. You need anchors.
Build a Character Sheet First
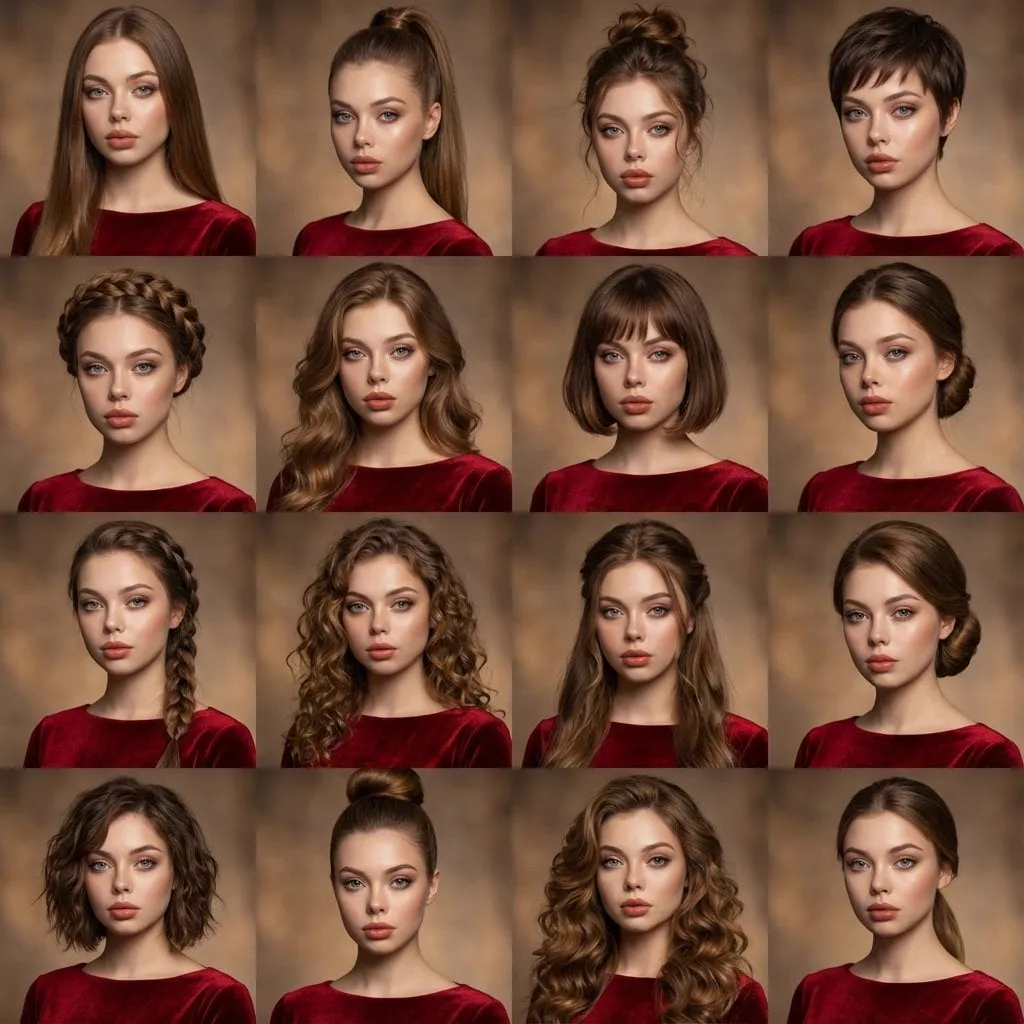
Create a reference set before generating any scene footage: front, three-quarter, and profile views; neutral expression plus two emotional states; two lighting conditions. Generate these in an image model and curate the best four to six frames.
From those frames, write a short identity token — a compact description of fixed traits only: face shape, hair, age range, build, signature clothing. Keep it under forty words. Long descriptions introduce competing details that models resolve inconsistently.
Handle Wardrobe and Lighting Drift
Wardrobe changes between scenes are fine and even desirable, but they must be deliberate. Log every change in the continuity notes. Lighting is subtler: if a scene is established as golden hour, every shot must carry that same warm cast, or the sequence will feel assembled from different films.
For shots where the face is small in frame, lean on silhouette and clothing rather than facial features. For close-ups, pin the reference image and lower the model's creative latitude. The closer the camera, the tighter the constraints should be.
The Consistency Audit
After generating a scene, line up the shots as thumbnails and review them side by side. Look for: hair length, jacket color, skin tone under the same lighting, and eyeline direction. This five-minute audit catches more errors than any amount of post-production fixing.
Scene Transitions, Environment Shifts, and Pacing
Transitions are where chains most often break, because a location change resets the model's context. The chain must explicitly carry the old environment forward long enough to make the cut feel motivated.
Matching on an Anchor
A useful technique is anchor matching: end one shot and begin the next with a shared visual element — a color, a shape, a movement direction. If a character walks left-to-right out of a shot, the next shot can open with the same directional motion in a new space. The eye reads this as continuity even when everything else changes.
Shot Length Rhythm
AI video tends to produce shots of uniform length, which feels flat. Vary deliberately: short shots (two to three seconds) for tension, longer holds (six to eight seconds) for reflection. Plan this in the beat sheet, not in the edit, because generation time and duration constraints will shape what is possible.
Environment Consistency
When a location appears more than once, generate it once, save the best frame, and reuse it as a reference for every subsequent visit. This applies to interiors especially, where furniture placement and window light become continuity traps across multiple scenes.
Audio as Part of the Chain
Sound is not a post-production afterthought in a well-designed chain. Voice, ambience, and music each carry continuity the visuals cannot.
Voice and Dialogue
If your characters speak, lock a voice reference early. Generate scratch dialogue before final visuals so you know the actual timing of each line. Cutting picture to match audio is far easier than stretching audio to match a clip that is already generated.
Ambience and Room Tone
Every location needs a consistent ambience bed. A forest scene with birdsong in one shot and near-silence in the next reads as an editing error. Save ambience presets per location and reuse them.
Music as a Structural Tool
Music marks act breaks and emotional turns. Rather than scoring the finished cut, define the emotional shape first: where does the tension peak, where does it release? Then generate or license music in sections that match those beats, and cut visuals to the sections rather than the reverse.
Feedback Loops and Self-Correction
A chain without review is just an assembly line producing errors faster. Build explicit checkpoints.
The Two-Pass Review
Pass one is technical: resolution, frame artifacts, hand and face anomalies, motion judder. Pass two is narrative: does this shot advance the story, is the eyeline correct, does the emotion match the beat?
Separating these matters because they trigger different fixes. Technical failures mean regenerate the same link. Narrative failures mean the chain's design is wrong — rewrite the link's purpose rather than rerolling it.
Automated Consistency Checks
Where available, use reference-based validation: compare generated frames to your character sheet programmatically for color and composition drift, or use a vision model to describe each shot and compare the descriptions against your continuity notes. This catches drift that the eye forgives after staring at a sequence for an hour.
Knowing When to Abandon a Link
If a shot fails more than five times with the same approach, the prompt is not the problem — the approach is. Change the model, change the framing, or cut the shot and solve the story problem elsewhere. Persistence on a broken link is the most common way a project dies.
A Complete Workflow: From Beat Sheet to Final Cut
Here is a chain structure that works for a two-to-three-minute narrative short.
Stage 1 — Story. Write a twelve-to-eighteen beat sheet. Each beat gets one sentence of action and one of emotional intent.
Stage 2 — Design. Generate character sheets for every recurring character, plus one master reference frame per location. Curate ruthlessly; these frames will constrain everything downstream.
Stage 3 — Blocking. Use a fast model to produce rough versions of every shot at low resolution. This is your animatic. Fix pacing problems now, when a change costs seconds rather than hours.
Stage 4 — Production. Regenerate approved blocking shots at full quality, pinning character and location references. Enforce the handoff contract at every step.
Stage 5 — Audio. Generate dialogue and ambience to finished picture timing, then compose or place music against the emotional beats.
Stage 6 — Assembly. Edit for rhythm, apply a consistent color treatment across shots, and add transitions that match on visual anchors.
Stage 7 — Audit. Watch the whole piece without pausing, then again with a notepad. Fix only what a first-time viewer would notice.
The stages are sequential but not rigid. Design often needs revision once blocking reveals that a shot does not work — budget for one loop back to Stage 2.
Common Mistakes, Decision Criteria, and FAQs
The most frequent errors are predictable, which means they are avoidable.
Overloaded prompts. Asking one prompt to define character, camera, lighting, and mood produces averages. Split them.
Skipping the animatic. Generating final-quality shots before the pacing works wastes the most expensive part of the pipeline.
No negative constraints. Models fill empty space with invention. Tell them what to exclude.
Treating consistency as a post fix. Color grading cannot repair a character who changed face shapes between shots.
Endless rerolling. Rerolling without changing the prompt is gambling, not iteration.
Decision criteria to keep at hand: if a shot is technically flawed, regenerate. If it is narratively flawed, redesign. If two models are equally good, choose the one with faster iteration. If you cannot explain why a shot exists, cut it.
Frequently Asked Questions
Do I need multiple AI video models? No, but most serious projects end up using two: a fast one for iteration and a high-fidelity one for finals.
How do I keep a character consistent without image references? It is possible but unreliable. Text-only identity tokens drift noticeably after roughly ten shots. Invest in reference frames.
How many shots should I generate per usable one? Plan for three to six generations per approved shot, more for complex action or crowds.
Is prompt chaining worth it for short social clips? For anything under fifteen seconds, a single well-crafted prompt is often faster. Chaining pays off when continuity or duration matters.
What if my chain produces a great shot I did not plan? Keep it, note what changed, and update your design layer so the rest of the sequence matches. Accidents are only useful if they become part of the system.
Can I reuse a chain across projects? Yes — save your character sheets, continuity note templates, and negative constraint lists. The reusable scaffolding is often worth more than any individual clip.
The discipline of linking prompts turns video generation from a series of bets into a repeatable craft. Start with three links, keep a written handoff contract, and audit your continuity before you celebrate a finished scene. The chains you build early will carry every project you make afterward.
