
Why prompt engineering still matters
Image models have become remarkably good at guessing. Type a loose sentence into any modern generator and you will usually get something usable. That convenience hides a hard truth: the gap between a "usable" image and an "on-brief" image is almost entirely a prompting problem. When a model produces something close but not right, the fix is rarely a better model. It is a better description.
Prompt engineering is not a trick or a secret code. It is the practice of translating a visual intention into language precise enough for a statistical model to reconstruct it. That involves decisions about subject, framing, light, materials, mood, and rendering style — the same decisions a photographer or art director makes, expressed as text.
Good prompting pays off in three concrete ways. First, it reduces iteration time: fewer generations needed to reach a final frame. Second, it increases consistency: the same character or product looks the same across a hundred images. Third, it makes results reproducible: you can hand a prompt to a teammate and get comparable output. Those three benefits compound when you move from a single still image into a video sequence or a full campaign.
This guide walks through how models interpret prompts, how to construct them layer by layer, how to control style and consistency, and how to adapt the same skills to motion. It is written for people who are new to generative tools but want a workflow they can keep using as the tools change.
How image models interpret your words
Diffusion-based generators do not understand language the way a person does. They map text into a mathematical space and then progressively refine random noise toward something that matches that representation. Two consequences follow from this.
First, concrete nouns and visible attributes carry far more weight than abstract intentions. "A lonely mood" gives the model very little to work with. "A single figure on an empty platform, cold blue light, heavy fog" gives it a lot. Emotion is best expressed through physical evidence: posture, spacing, weather, palette, and light direction.
Second, the model has no memory of your intent. It only sees the tokens in the prompt. If you forget to mention that the scene is indoors, nothing in the prompt contradicts the model's assumption that it might be outdoors. Omissions are not neutral — they are invitations for the model to fill gaps with whatever its training data suggests is most common.
There is also a well-documented positional effect: text near the beginning of a prompt tends to influence the result more strongly than text near the end. Front-load the elements you cannot compromise on, and let stylistic flourishes trail behind. If your subject is a specific garment or product, describe it before you describe the lighting.
Finally, understand that different models have different strengths and quirks. Some follow long, detailed prompts faithfully. Others respond better to short, punchy descriptions and become confused by too many clauses. Some are tuned for photorealism, others for illustration or anime. Treat every model as a collaborator with its own temperament, and test a small set of prompts before committing to one.
The anatomy of a strong image prompt
The most reliable way to build prompts is to think in layers. You do not need every layer every time, but knowing the layers helps you diagnose what is missing when an image feels wrong.
Subject and action
Start with who or what is in the frame and what they are doing. Be specific about count, age range, clothing, material, and pose. "A woman" is weaker than "a woman in her thirties wearing a wool overcoat, mid-stride, one hand holding a folded newspaper." Action verbs give the pose direction.
Environment and setting
Where does this happen, at what time of day, in what weather, and what surrounds the subject? Include foreground and background cues if they matter: wet pavement, stacked crates, distant hills, a blurred crowd. Setting establishes depth and story.
Lighting
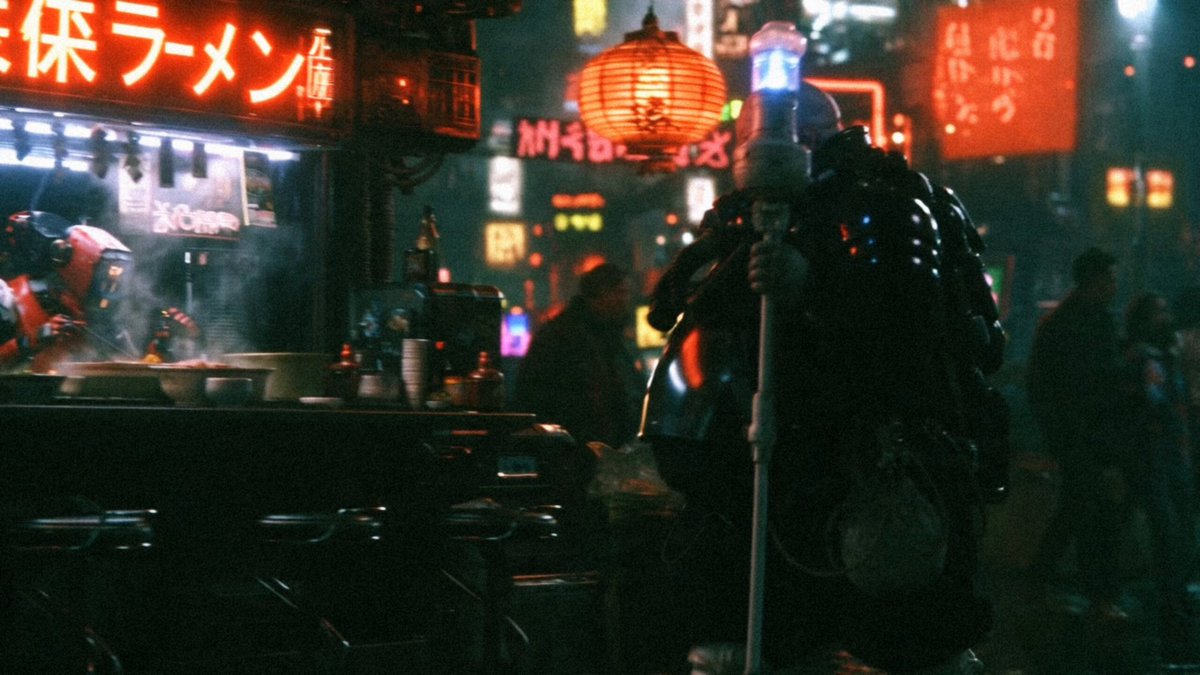
Lighting is the single highest-leverage layer. Specify direction (backlit, side-lit, overhead), quality (soft, hard, diffused), color (warm tungsten, cold daylight, neon magenta), and time (golden hour, overcast midday, blue hour). Most "flat" or "boring" outputs are lighting problems, not subject problems.
Camera and composition
Describe the lens and framing: wide-angle, 35mm, 85mm portrait, macro, drone shot, low angle, eye-level, extreme close-up. Mention depth of field, motion blur, and whether the frame is symmetrical or off-center. These cues shift the image from a generic render toward something that looks deliberately photographed.
Style and medium
Name the rendering language: editorial photograph, watercolor illustration, cel-shaded animation, claymation, isometric vector art, 1990s film scan. You can reference a genre or era rather than a living artist. Genre references are safer, more reusable, and less likely to produce a pastiche that misses the point.
Technical quality cues
Terms like sharp focus, high dynamic range, natural skin texture, film grain, subtle chromatic aberration, or clean line art steer the final polish pass. Use them sparingly. Stacking twenty quality words produces mush.
A layered prompt reads naturally: subject and action, then setting, lighting, camera, style, and a short quality tail. That order is not magic, but it mirrors how a viewer reads an image — main subject first.
Weighting, emphasis, and exclusion
Most image tools give you some way to say "this matters more" or "leave this out." The exact syntax varies, so check your tool's documentation, but the concepts are universal.
Weighting. Some interfaces let you wrap a phrase in parentheses or attach a numeric multiplier to push an element forward or pull it back. Use this when a model keeps under-serving a detail, such as a specific color of jacket or a particular architectural feature. Weighting is a correction tool, not a design tool. If you need heavy weighting on five different elements, the prompt is trying to do too much.
Negative prompts. A negative field tells the model what to avoid: extra fingers, text, watermarks, cluttered background, distorted perspective. Negative prompts are most useful for recurring failure modes you have observed in your own outputs. Copying a giant list of negatives from the internet usually does little and can hurt, because some of those terms are semantically adjacent to concepts you actually want.
Reinforcement through redundancy. Instead of cranking weights, describe the same idea twice in different words — "overcast sky" and "soft, flat ambient light" reinforce each other naturally. This tends to produce more balanced results than aggressive numeric weighting.
Iteration discipline. Change one variable per generation. If you alter lighting, camera angle, and style simultaneously, you learn nothing about which change produced the improvement. Keep a running note of what you changed and what it did. Over a week, this habit builds an intuition that no tutorial can give you.
Style control across genres
Style is where beginners lose the most time, because style words interact unpredictably. A few patterns hold across most tools.
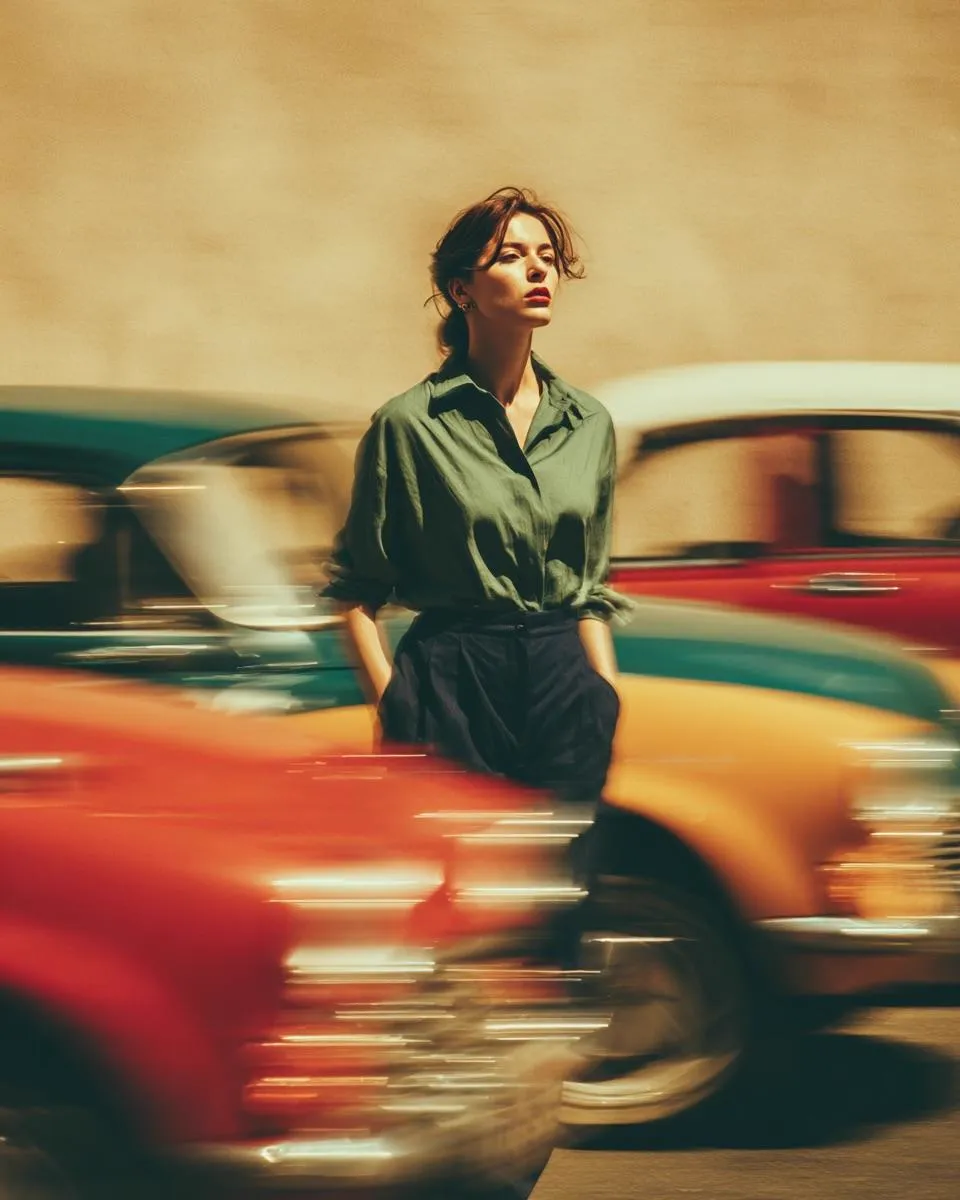
Photorealism. Focus on light behavior and imperfections: natural skin texture, slight motion blur, imperfect framing, lens flare, believable shadows, mixed color temperatures. Paradoxically, adding flaws makes images look more real. Overly clean renders read as computer-generated even when the geometry is correct.
Illustration and concept art. Specify the medium and edge quality: gouache on textured paper, bold ink outlines, flat shapes with limited palette, painterly brush strokes. Mentioning the substrate — canvas, newsprint, risograph — instantly changes the result.
Anime and manga styles. Describe line weight, shading approach, and eye rendering rather than naming a studio. Terms like clean line art, cel shading, expressive large eyes, and soft gradient backgrounds communicate the look without leaning on a specific production.
3D and product renders. Talk about materials and studio setup: matte plastic, brushed aluminum, softbox top light, seamless gradient backdrop, subtle reflection on a glossy floor. Product work rewards precision more than mood.
Retro and analog looks. Film stock characteristics, halation, grain structure, faded contrast, and dated color grading produce a convincing period feel. Combine one analog cue with one modern sharpness cue so the image does not look simply low quality.
The core rule: pick a lane. Prompts that blend three unrelated styles usually produce a muddled middle. If you want a hybrid, blend two adjacent styles and describe how they combine.
Consistency across a series
Single images are easy compared to series. The moment you need the same character, product, or location across multiple frames, small prompt variations cause visible drift.
Build a reusable block. Write a fixed paragraph describing your subject's defining traits — hair, build, wardrobe, distinguishing features — and paste it verbatim into every prompt. Do not paraphrase it. Paraphrasing changes tokens, and changed tokens change the face.
Separate the constant from the variable. Keep a template with clearly marked slots: [SUBJECT BLOCK], [ACTION], [LOCATION], [LIGHTING], [CAMERA], [STYLE]. Fill the slots differently for each shot while the subject block stays identical.
Use reference images where supported. Many tools accept an image input to guide character or product appearance. Combine image reference with a fixed text block; the text stabilizes details the reference may not cover, such as wardrobe or expression range.
Control the seed. If your tool exposes a seed value, reuse it when you want to keep background structure and composition stable while changing pose or lighting.
Lock your style tail. The last few words — the film grain, the palette, the rendering notes — should be identical across the whole set. Consistency in a series is largely the art of freezing everything except the one thing you intend to change.
From stills to motion: adapting prompts for video
Moving from images to video changes what a prompt must carry. A still image needs one decisive moment. A shot needs a beginning, a change, and an end.
Add motion verbs. Describe what moves and how: camera slowly pushes in, subject turns to face the lens, steam rises, fabric ripples in wind. Without motion language, video models tend to produce near-static clips with drifting artifacts.
Specify camera behavior explicitly. Distinguish subject motion from camera motion. "The camera orbits left while the subject remains still" is clearer than "dynamic movement," which models often interpret as chaotic motion everywhere.
Keep shots short and simple. One action per clip works far better than a compound sequence. If you need a character to walk, open a door, and sit down, that is three shots, not one prompt.
Describe continuity. Note the lighting direction and wardrobe in every shot of a sequence, because video models have no memory of the previous clip. Frame-to-frame stability depends on you repeating the anchors.
Consider audio and pacing cues. Where a tool supports them, pacing language — slow reveal, quick whip pan, steady locked-off shot — gives editors predictable material to cut with.
A repeatable workflow
1. Write a one-sentence brief
Before touching a prompt field, write one plain sentence describing the image's job: "A wide shot establishing a rain-soaked city street at night for a mystery story cover." This becomes your reference point when you evaluate results.
2. Draft the layered prompt
Fill the layers: subject and action, setting, lighting, camera, style, quality tail. Keep it under roughly 60–80 words for most models. Longer is not better; denser is better.
3. Generate a batch
Produce four to eight variations without changing the prompt. Models are stochastic; one good result out of six is normal and expected.
4. Diagnose, do not redraw
Compare results against your one-sentence brief. Identify the single largest mismatch — usually lighting or composition — and fix only that.
5. Lock the variables
Once the look is right, freeze the subject block, style tail, and seed. From here, only change the variables your series requires.
6. Document what worked
Keep a simple text file of final prompts with a note about what each one solved. Over a month, this file becomes more valuable than any tutorial, because it encodes your specific visual taste.
7. Scale carefully
When producing a large set, generate in batches and review in passes: first for composition, then for anatomy or material errors, then for style consistency. Reviewing everything at once makes you blind to systematic problems.
Common mistakes and how to fix them
Too many ideas in one image. Symptom: cluttered, incoherent output. Fix: cut the prompt to a single subject and a single action.
Vague mood words. Symptom: generic, flat results. Fix: replace mood adjectives with physical evidence — light direction, palette, weather, posture.
Style stacking. Symptom: muddy hybrid rendering. Fix: choose one primary style and at most one secondary influence.
Ignoring lighting. Symptom: images look like flat renders. Fix: always define direction, quality, and color of light.
Changing everything at once. Symptom: you cannot tell what improved the image. Fix: one variable per iteration.
Copying negative prompt lists wholesale. Symptom: unexpected omissions and strange artifacts. Fix: build negatives from your own observed failures only.
Paraphrasing your character description. Symptom: the face changes every frame. Fix: paste the identical subject block every time.
Expecting one generation to be final. Symptom: frustration. Fix: treat generation as sampling and plan for multiple attempts.
FAQ
How long should a prompt be? For most tools, 40–80 words of dense, specific description outperforms a 300-word paragraph. Add length only when each added clause carries distinct information.
Do I need to learn weighting syntax? No, but knowing it helps when a specific element keeps getting ignored. Start with plain language and reach for weighting only as a correction.
Can I use the same prompt across different tools? The structure transfers well; the phrasing does not. Expect to re-tune style and quality words for each model's preferences.
How do I get consistent characters? Use an identical subject block, a fixed style tail, a stable seed where available, and image references if the tool supports them.
Why do my images look artificial? Usually because lighting is generic and surfaces are too clean. Specify light direction, add believable shadows, and allow small imperfections like grain, blur, or uneven framing.
What is the fastest way to improve? Iterate with one change at a time and keep a written log of prompts and outcomes. Deliberate practice beats prompt collecting.
Do I need different skills for video? The fundamentals are the same, but you must add motion verbs, camera behavior, and shot-level simplicity, and you must repeat continuity details in every prompt.
How many generations should I expect per final image? For straightforward subjects, a handful. For complex compositions or strict brand requirements, expect several rounds with small adjustments between them.
