
Why Photorealism Became the Default Expectation
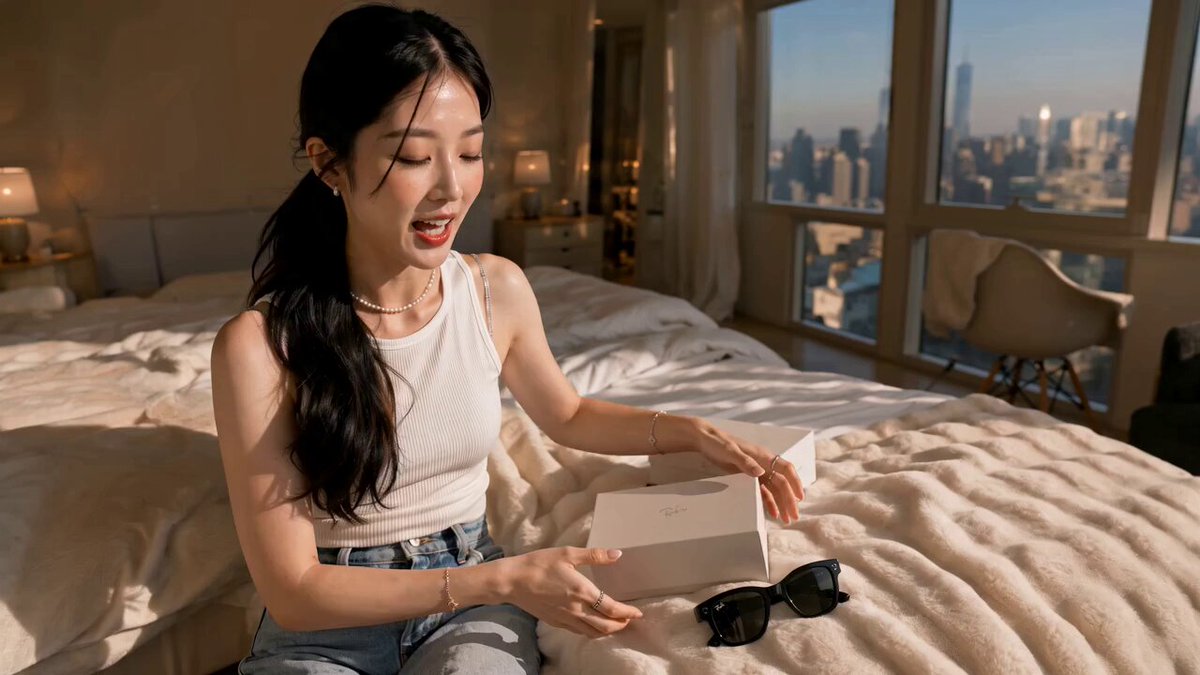
A few years ago, an AI-generated image announced itself. Hands melted, eyes drifted in different directions, and skin looked like polished plastic. Audiences learned to spot the tell instantly, and that tell became a punchline. That era is over. Today, a well-constructed prompt combined with the right model produces stills that survive a side-by-side comparison with studio photography — at least until you look at the metadata.
The shift matters because the audience has changed too. Viewers now scroll past synthetic imagery without registering it as synthetic. That raises the bar rather than lowering it: if your output looks almost real, the small flaws become the entire story. A jawline that is slightly too smooth, a background that refuses to resolve into real objects, a shadow pointing the wrong direction — these are the new giveaways.
So the goal is not simply to generate images. The goal is to build a workflow where realism is repeatable, not accidental. That means understanding how these systems work, how to write prompts that behave predictably, how to select a model for a specific shot, and how to carry a photorealistic still into motion without losing the qualities that made it convincing in the first place.
This guide covers that full path: still generation, motion, finishing, and quality control. It is written for marketers, independent filmmakers, and designers who need output they can publish, not just images they can admire.
How Realistic Image Generation Actually Works
You do not need a mathematics degree, but you do need a working mental model. Most modern generators are diffusion systems: they learn to reverse a process that turns a clean image into noise, then apply that reversal to a field of random static guided by your text prompt. Realism emerges from the training data — billions of photographs with their lighting, grain, and lens artifacts intact.
Latent space and why resolution alone is not quality
Most systems do not diffuse in pixel space; they work in a compressed latent representation. This is why pushing a generator to enormous resolution often produces anatomy errors and repeated textures. The model is reasoning at a smaller scale and then upscaling. Treat resolution as a finishing step, not a generation setting.
Text encoders shape everything
Your prompt is not read like a sentence. It is converted into embeddings that steer each denoising step. Short, concrete prompts give the model a narrow path; long, contradictory prompts give it several and let it average them into mush. A useful mental rule: the model can hold roughly one subject, one environment, one lighting condition, and one camera description at a time.
Seeds, samplers, and controlled variation
A seed fixes the starting noise. Keep it and change your prompt to explore variations of the same identity, framing, and composition. Change the seed and keep the prompt to explore different faces and layouts. Mixing both at once makes iteration feel random. Separating them is the single biggest productivity improvement most beginners can make.
Building a Prompt Stack That Produces Photographic Results
Think of the prompt as four stacked layers, written in a fixed order. A consistent order makes your results comparable, so you can change one variable at a time.
Layer one: subject and action
Name the subject, the action, and the moment. "A ceramicist lifting a freshly thrown bowl from the wheel" outperforms "a potter" because it defines a specific instant the model can render. Include age range, clothing, and expression only when they matter.
Layer two: environment and time of day
Realism lives in the environment. "A workshop at 7 a.m., dust suspended in low sun through a side window" gives the model physical cues — particulate haze, hard directional light, a defined window. Vague settings produce vague physics.
Layer three: camera and lens language
This is where realism is won. Specify a focal length and aperture: 35mm for environmental context, 85mm for portraits with compressed backgrounds, 100mm macro for product detail. Add "shallow depth of field, f/1.8" and the model stops rendering everything equally sharp — which is exactly how real lenses behave.
Useful camera vocabulary to mix in deliberately: handheld, tripod-mounted, over-the-shoulder, low angle, Dutch tilt, anamorphic flare, 35mm film grain, digital noise at ISO 3200, slight motion blur.
Layer four: finish and medium
Decide whether the image reads as a photograph, a film still, or a scanned print. "Kodak Portra color response," "desaturated documentary grade," and "black-and-white with deep contrast" each push the output in a different direction. Without this layer, many models default to a glossy, over-saturated look that reads as synthetic.
Negative prompts still matter
Use them for structural problems, not for taste. "Extra fingers, fused limbs, duplicate subjects, watermark, text, plastic skin, oversharpened, HDR halo" is a working baseline. Do not stack thirty complaints; the model weights all of them and dilutes the ones that count.
Model Selection: Matching the Engine to the Shot
Not every generator is good at every subject. Building a small personal roster and knowing which tool to reach for will improve your output more than any single prompt trick.
Photoreal portraits and character work
Prioritize models with strong facial anatomy and skin texture. Look for visible pores, uneven skin tone, and fine hair detail in the output. Weak models smooth everything, which is the fastest route to uncanny territory.
Product, food, and commercial stills
Here you need material accuracy: reflective metal, translucent glass, crumb structure, condensation. Test each model with a single reference object — a glass of water with ice is a brutal test. If the refraction is wrong, the model will struggle with every commercial brief.
Environments, architecture, and establishing shots
Wide shots demand geometric consistency. Lines must converge correctly, and repeated elements like windows and floor tiles must stay aligned. Generators that excel at faces sometimes fail badly here.
Stylized and hybrid looks
If you need illustration, anime, or painterly output, choose a model tuned for it rather than fighting a photoreal model with heavy style prompts. Fighting the base model costs time and rarely produces a coherent aesthetic.
A practical selection rule
Run the same prompt across three models and compare four things: skin or material texture, lighting logic, background coherence, and how much text you had to write to get there. The model that needs the fewest words to reach usable output is usually the right default for that subject category.
From Still to Motion: A Practical AI Video Workflow
A photorealistic frame is the foundation, not the product. Most short-form video work now runs image-first: generate a strong still, then animate it. This section walks through the pipeline in the order you would actually execute it.
Step 1: Lock the script and shot list before generating anything
Write the sequence as a list of shots with a stated purpose: establish location, introduce character, show the product, land the emotional beat. Generating before planning produces beautiful clips that cannot be edited together.
Step 2: Generate a hero frame per shot
One strong still per shot, matched for lighting direction and color temperature across the sequence. If shot one is lit from the left, shot two should not flip. Consistency at this stage is cheaper than fixing it later.
Step 3: Build a character or product reference sheet
For recurring subjects, create a small set of approved images — front, three-quarter, and profile for people; three angles for products. Feed these as image references in every subsequent generation. This single habit prevents the drifting-face problem that ruins multi-shot sequences.
Step 4: Write motion prompts that describe physics, not adjectives
"She turns her head slowly to the left, hair moves with the turn, dust drifts through the light" works. "Cinematic, beautiful, dynamic" does not. Describe what changes between the first and last frame: a hand opening, steam rising, a camera pushing in.
Step 5: Control the camera deliberately
Choose one movement per clip. A slow dolly in, a slight handheld sway, a gentle pan — pick one. Stacking movements produces a nauseating, artificial feel that reads as generated.
Step 6: Keep clips short and cut on motion
Three to six seconds is the sweet spot. Longer clips accumulate small errors in anatomy and background stability. Cutting while motion is still happening hides imperfections and keeps pacing tight.
Step 7: Upscale, then stabilize
Run a detail upscale on the final frames rather than the raw generation, and apply light stabilization only where it is needed. Aggressive stabilization flattens the natural micro-movement that makes footage feel filmed.
Lighting, Color, and Finishing in Post
Generated footage almost never arrives graded. A short finishing pass is what separates hobby output from publishable work.
Start with exposure and contrast. Generated images tend toward crushed blacks and clipped highlights; pull both back slightly so you retain information in shadows and skin. Then neutralize color temperature across every shot in the sequence — mixed white balance is the most common giveaway in AI video.
Add grain. Real footage has noise; algorithmic output is often suspiciously clean. A subtle film grain layer at low opacity, matched across the timeline, unifies shots that came from different generations.
Sharpen last and lightly. Over-sharpening produces halos around edges and instantly reads as synthetic, especially on faces and hair.
Finally, handle audio. Ambient beds, footsteps, and room tone do more for perceived realism than another hour of image tweaking. An audience forgives a slightly soft frame; it does not forgive a silent room.
A Quality Control Checklist Before You Publish
Run this pass on every deliverable. It takes two minutes and catches most embarrassment.
- Hands and teeth. Check finger count, joint direction, and whether teeth resolve into individual shapes.
- Shadows and light direction. Every shadow should agree with your stated light source.
- Reflections and glass. Look for mirrored objects that do not match the scene.
- Background text. Signs, labels, and screens should be blank or replaced. Never ship garbled lettering.
- Consistency across shots. Same face, same wardrobe, same light temperature, same grade.
- Motion plausibility. Hair, fabric, and liquid should move with weight, not float.
- Edge artifacts. Zoom to 200% on hair, foliage, and grid patterns for smearing.
Common Mistakes That Kill Realism
Over-prompting. Thirty descriptors force the model to average unrelated ideas. Cut anything that does not change the image.
Ignoring lens logic. Without focal length and aperture, everything is sharp, and everything sharp looks fake.
Chasing resolution early. Generating at maximum size produces duplicated features and broken symmetry. Generate at a moderate size, upscale after.
Changing too many variables at once. Adjust the prompt, or the seed, or the model — not all three. Otherwise you learn nothing from the result.
Skipping reference images. Identity drift across a sequence is the most visible flaw in multi-shot AI video, and it is entirely preventable.
No finishing pass. Raw generations tend to be over-saturated and over-sharpened. A short grade is not optional polish; it is part of production.
Trusting the first good frame. Generate at least four candidates per shot. The first acceptable result is rarely the best one.
A Two-Hour Project Walkthrough
Suppose you need a forty-second product film for a small skincare brand, shot in a bathroom at dawn.
Minutes 0–20: write the shot list. Six shots — establishing bathroom, product on the counter in window light, hands uncapping, texture close-up, model applying, closing logo frame. Decide the light direction: soft window light from the left, cool ambient fill.
Minutes 20–50: generate hero frames. Use a 35mm lens description for the establishing shot, 100mm macro for the texture close-up, 85mm for the model. Keep the seed stable across the model shots and feed a reference image of the product in every prompt.
Minutes 50–80: animate. One movement per clip: slow push in for the product, gentle handheld drift for the hands, static with moving steam for the macro. Keep each clip at four seconds.
Minutes 80–100: assemble and cut. Order the shots, trim on motion, and confirm the color temperature matches end to end.
Minutes 100–120: finish. Grade, add grain, layer ambient room tone and a single soft music bed, and run the quality checklist. Export at the aspect ratio the platform requires.
The value of this structure is not the specific timings — it is that planning, generation, motion, and finishing stay in separate phases. Mixing them is what turns a two-hour project into a two-day one.
Frequently Asked Questions
How many words should a realistic image prompt be?
Usually between fifteen and forty. Enough to define subject, environment, light, and lens; short enough that no two instructions compete. If you cannot explain why a word is there, remove it.
Why do faces change between shots even with the same prompt?
Because text alone cannot lock an identity. Supply reference images, keep the seed fixed when only motion changes, and describe the subject identically in every prompt.
Is a higher resolution setting always better?
No. Generating at extreme sizes often introduces duplicated limbs and repeated textures because the model is working in a compressed space. Generate at a moderate size and upscale in a dedicated pass.
How long should an AI-generated video clip be?
Three to six seconds for most work. Longer clips accumulate stability and anatomy errors, and short clips cut together more naturally with music and voiceover.
Do I need different tools for images and video?
Not necessarily, but most creators use one generator for photoreal stills and another for animation. Test each candidate on your specific subject — a glass of ice water for products, a close portrait for people — rather than trusting generic comparisons.
What is the fastest way to make output look less artificial?
Three things, in order: add a grade with reduced saturation, add subtle grain matched across all shots, and add ambience audio. Each takes minutes and each has an outsized effect on perceived realism.
Can AI visuals replace a photoshoot entirely?
For concept work, social content, and many product placements, yes. For shots requiring exact real-world packaging, legal claims, or human talent likeness, use generation for planning and previsualization, then shoot the final assets.
The through-line is simple: realism is a process, not a setting. Build a prompt structure you reuse, keep a small roster of models you know well, plan your shots before you generate, and never skip the finishing pass.
