
Why Photorealism Changes What You Can Ship
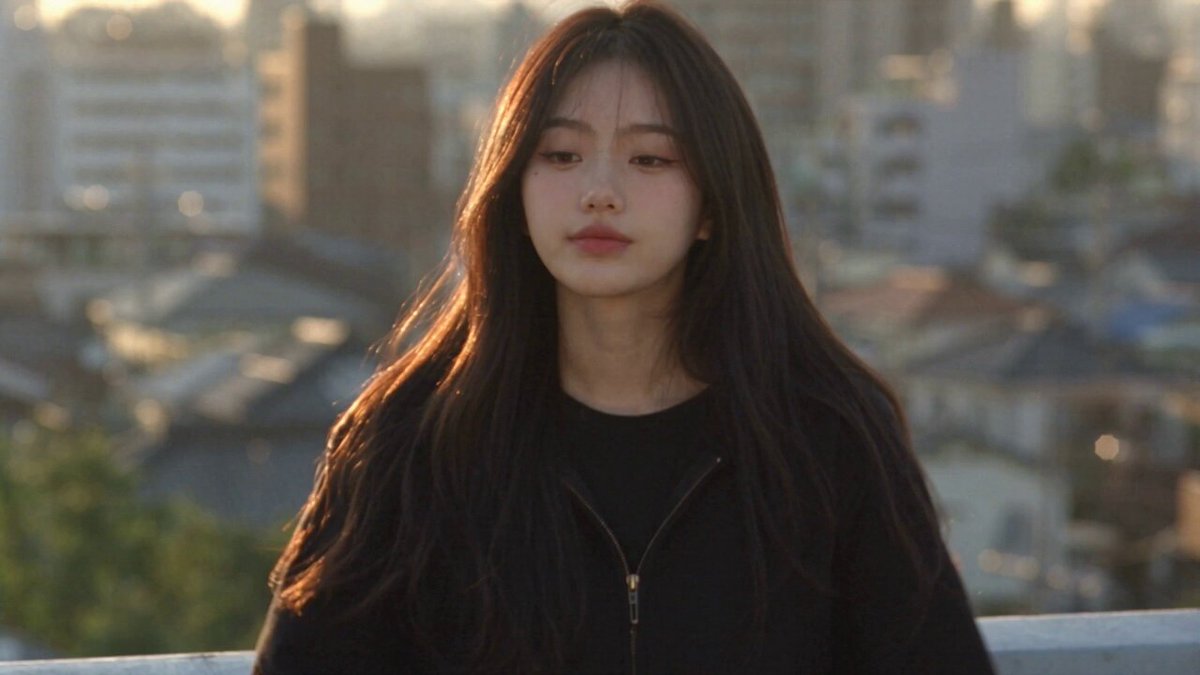
A decade ago, a photorealistic product shot required a studio, a lighting kit, a stylist, and a retoucher. Today a careful prompt can produce an image good enough to pass on a phone screen, and an image-to-video pass can make that image move. The interesting part is not that it is impressive. The interesting part is that it changes what a small team can attempt.
A solo marketer can now prototype ten visual directions before lunch. A documentary editor can build a period-accurate establishing shot without a location scout. An e-commerce brand can show a product in five environments without shipping physical samples. A game studio can previsualize a cutscene without blocking out a full 3D scene.
The catch is that realism is fragile. An image that looks convincing as a still can fall apart the moment it moves: skin becomes waxy, hands morph, background details drift, and camera motion reveals that the scene was never really three-dimensional. Most of the work in a reliable AI video pipeline happens before you ever press generate on a video model.
This guide walks through that pipeline. It covers what photorealism actually means, how to write prompts that survive the jump to motion, how to pick between image and video models, how to keep characters consistent across shots, and the mistakes that waste the most time.
What "Realistic" Actually Means in Practice
Photorealism is not one quality. It is a bundle of separate problems, and each one fails independently. If you can name which one is failing, you can usually fix it with a targeted prompt change instead of regenerating blindly.
Light, skin, and material behavior
The most common tell in AI imagery is light that does not behave like light. Real light falls off with distance, bounces off surfaces, wraps around skin, and casts soft shadows with a visible direction. AI models often produce flat lighting with no clear source, or dramatic lighting with shadows pointing in contradictory directions.
Fix it by specifying the light source explicitly: overcast daylight from a north-facing window, a single softbox at 45 degrees, golden hour backlight, practical tungsten lamps in a dim interior. Mentioning the direction, quality (hard versus soft), and color temperature solves more realism problems than any style keyword.
Skin is the second major tell. Real skin has subsurface scattering, visible pores, slight asymmetry, and small imperfections. Prompts that ask for flawless skin produce the plastic look that reads as artificial. Words like natural skin texture, visible pores, slight freckles, and subtle facial asymmetry tend to help far more than cinematic beauty.
Materials matter too. Fabric should have weight and weave. Metal should reflect its environment. Glass should refract. When a prompt says nothing about materials, the model defaults to a generic smoothness that looks synthetic at full resolution.
Camera language and lens behavior
A huge share of AI images look "AI-generated" because they have no coherent camera. Real photographs have a focal length, an aperture, a shutter speed, and a distance from the subject.
Specifying a camera language gives you three benefits at once: it improves the still, it reduces the number of plausible completions the model can choose from, and it gives your video model clear motion cues. A prompt that mentions a 50mm lens at f/1.8 from a chest-height angle tells the video model that shallow depth of field and slight handheld drift are appropriate. A prompt that says nothing invites teleporting cameras and warping geometry.
Useful vocabulary: wide-angle environmental shot, 85mm portrait compression, macro detail, low-angle hero shot, over-the-shoulder, drone orbit, static tripod. Pair each with a distance (close-up, medium, wide) and you have a shot, not just an image.
Writing Prompts That Survive the Jump to Video
A prompt that produces a beautiful still is not automatically a prompt that produces a usable clip. The video model needs to understand what moves, what stays still, and what the camera does. Build that information into the prompt from the start.
The five-slot prompt framework
Use a consistent order so you can debug one slot at a time:
- Subject — who or what, with age, wardrobe, and distinguishing detail.
- Action or state — what the subject is doing, or how they are posed.
- Environment — location, time of day, weather, background elements.
- Camera — angle, distance, lens, movement.
- Light and mood — source, quality, color, atmosphere.
A weak prompt mixes these into a soup of adjectives. A strong prompt reads like a shot description from a storyboard. For example: "A woman in her early thirties in a charcoal wool coat, standing still and looking slightly off-camera, on a wet city street at dusk with blurred neon signage behind her, medium shot on a 50mm lens at f/2, slow push-in, soft blue ambient light with warm rim light from a shop window."
That prompt is long, but every clause does a job. The subject is specific, the action is minimal, the environment is grounded, the camera is defined, and the light has a direction.
Keep motion small and singular
One of the most common mistakes is asking for too much motion. A clip where a character walks, turns, speaks, and gestures in four seconds will almost always break. Video models handle a single, slow, well-defined motion far better than a busy sequence.
The practical rule: one subject action plus one camera action. A blink and a slight head turn. A gentle push-in. Steam rising in the background. Hair moving in the wind. These small motions read as real because they match what the eye expects from a photograph that has come alive.
If you need a complex beat, break it into multiple short clips and cut them together. Three four-second clips with clean motion will always beat one twelve-second clip full of artifacts.
Choosing the Right Model for Each Stage
Different stages of the pipeline reward different model characteristics. Matching the model to the task is faster than trying to force one tool to do everything.
Image stage
For photorealistic stills, prioritize models with strong text rendering, good hands, and stable anatomy. Diffusion-based image models with instruction-following tuning tend to be the most controllable: they respond to precise language about lighting and materials instead of only to style keywords.
If you need a specific person, product, or location to appear consistently, look for models or add-ons that support reference images, identity conditioning, or inpainting. A model that can hold a reference face is worth more than a model that produces marginally prettier default output.
Video stage
For image-to-video, evaluate three things: motion realism, temporal stability, and duration per generation. Motion realism matters most for people and animals. Temporal stability matters most for architecture and product shots, where flicker and warping are immediately obvious.
Some models excel at cinematic camera movement and struggle with faces. Others are strong on talking subjects and weak on environmental motion. Keep two or three options available and test the same still across them rather than committing to one.
A quick decision shortcut
Ask three questions before choosing a model: Does the shot contain a human face in close-up? Does it require precise text or logos? Does it need more than five seconds of continuous motion? Faces favor identity-capable models, text favors strong text rendering, and long durations favor models built for longer sequences or a planned multi-clip edit.
The Step-by-Step Workflow
Step 1: Lock the look with a still
Generate stills first, always. Video generation is expensive in time and compute, and a bad still guarantees a bad clip. Produce five to ten variations of your key shot, then pick one and refine it with targeted edits rather than full regeneration.
Sign off on framing, lighting direction, wardrobe, and background before moving on. Changing any of those later invalidates the motion work.
Step 2: Write a motion brief per shot
For each chosen still, write one sentence describing the motion and one sentence describing the camera. Keep it in the same document as your shot list. This forces you to think in terms of coverage rather than single clips, and it makes the edit predictable.
A realistic motion brief for a product shot might read: "Slow 15-degree orbit, product stays still, subtle reflection shifts across the surface, no change in lighting." That is achievable. "Camera flies around the product while the label animates" is not, at least not in one pass.
Step 3: Generate in short takes and select
Generate several variations at the shortest usable duration, usually three to five seconds. Review them at full speed, then at half speed. Half-speed review exposes warping, jitter, and geometry changes that disappear at normal playback.
Keep a rejection log. Note which prompts produced morphing hands, which produced flicker, and which produced camera drift. Patterns emerge quickly, and the log becomes your personal troubleshooting reference.
Step 4: Assemble, sound, and grade
Editorial is where AI footage stops looking like AI footage. Cut on motion so that transitions hide imperfections. Add sound design early — footsteps, room tone, fabric rustle — because audio anchors realism more than any visual tweak.
Finish with a grade that unifies the clips. Slight grain, consistent contrast, and a shared color temperature make separately generated shots feel like they came from the same camera. A single film grain overlay across a whole sequence does more for believability than another round of regeneration.
Keeping Characters and Scenes Consistent
Consistency is the hardest problem in multi-shot AI video, and the solution is mostly bookkeeping. Maintain a character sheet with a fixed reference image, a locked description, and a list of wardrobe states. Copy that description verbatim into every prompt rather than paraphrasing it.
For scenes, lock the geography. Decide where the door, window, and light source are, and repeat those details in every shot set in that location. Video models will happily invent a second window if you do not specify the room.
When consistency still drifts, fix it in the still stage. Regenerating an image with a stronger reference is faster than trying to correct identity drift inside a video model.
Common Mistakes and How to Fix Them
Asking for too much in one clip. Split into multiple takes and cut them together.
Using style keywords instead of light descriptions. Replace moody, cinematic, and beautiful with specific light sources and directions.
Ignoring aspect ratio and delivery format. Decide whether you are delivering vertical, square, or widescreen before generating. Cropping after the fact destroys framing you carefully built.
Skipping the half-speed review. Most artifacts are invisible at full speed and obvious when you slow things down.
Over-retouching. Aggressive sharpening and noise reduction reintroduce the plastic look you were trying to escape.
Not saving prompts. A prompt library with notes on what worked is the single highest-value asset in an AI video workflow.
Legal, Ethical, and Brand-Safety Checks
Before publishing, confirm you have the rights to any reference images you used, especially faces. Avoid generating recognizable real people without consent, and avoid depicting real brands or logos you do not own.
Disclose synthetic imagery where audiences could reasonably be misled, particularly in news, political, or testimonial contexts. In most markets, misleading synthetic depiction of real events carries real legal risk, and platform policies are tightening quickly.
Keep a lightweight provenance habit: store the prompt, the model, and the date alongside each final asset. It takes seconds and saves hours when a client asks how an image was made.
Frequently Asked Questions
How long should a single generated clip be?
Three to six seconds is the sweet spot for most models. Longer clips accumulate drift. Build longer sequences through editing.
Can I get perfect hands and faces?
Usually yes, with patience. Generate more variations, keep hands smaller in frame or partially occluded, and fix stills before animating them.
Do I need a video model at all?
Not always. Simple parallax, scale, and opacity moves applied to a high-quality still can look convincing for many social formats and cost far less time.
Why does my clip look fine on my phone but wrong on a monitor?
Small screens hide artifacts. Always review at the largest size you can and at half speed before approving.
How do I keep a series looking uniform?
Lock a prompt template, a grade, a grain overlay, and a sound palette. Uniformity comes from repetition of constraints, not from luck.
A Practical Practice Plan
Spend one week on stills only. Pick a single subject and generate it in ten lighting conditions, noting which phrases actually changed the output. Spend the second week on motion: take your three best stills and produce five clips each, logging failures. Third week, edit a thirty-second sequence with sound design and a unified grade. Fourth week, repeat the whole pipeline for a client-style brief with a deadline.
By the end you will have a prompt library, a failure log, and a reliable sense of which model to reach for. That combination — not any single tool — is what turns realistic AI images into finished video you can actually publish.
