
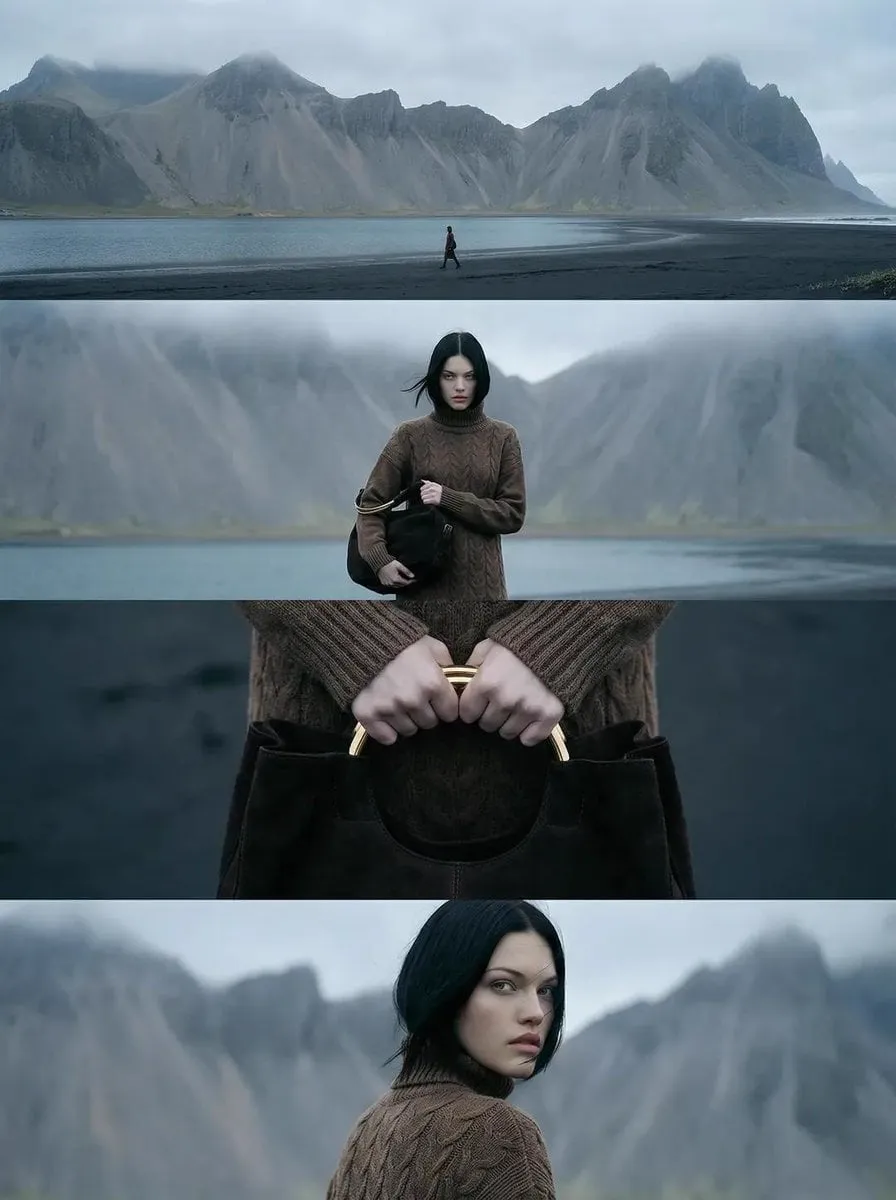
Text-to-video generation stopped being a novelty the moment teams realized that one beautiful clip does not make a video. The hard part is the tenth shot matching the first, the lighting staying consistent across a scene change, and the finished cut actually communicating something. This guide covers a practical pipeline for producing photorealistic AI video from a written script: how to judge candidates, how to prompt, how to keep continuity, and how to repair the artifacts that still appear in every model family.
Realism Is a Pipeline Problem, Not a Model Problem
Most comparisons of video models focus on single outputs. A cherry-picked five-second clip can look astonishing, but a production needs twenty shots that hold together in sequence. That is a different problem, and it is solved with process more than with model choice.
Think of the work as three layers stacked on top of each other. The base layer is generation: turning text into moving pixels. The middle layer is control: camera motion, subject blocking, timing, and continuity between shots. The finishing layer is craft: stabilization, upscaling, frame interpolation, color, sound, and edit rhythm. Weak base generation cannot be rescued by finishing, but strong base generation is routinely ruined by skipping control and finishing.
A second reality check is the demo trap. Models are usually demonstrated on subjects they handle well: slow camera moves, single subjects, soft natural light, landscapes, and wide shots with little fine detail. Your script probably contains hands, crowds, text, mirrors, fast motion, and dialogue. Plan for the shots that are genuinely hard instead of assuming the demo performance transfers.
What "Realistic" Actually Means: Four Criteria to Judge
"Photorealistic" is not one quality. Two clips can both look convincing in a screenshot and behave completely differently once they move. Use four separate criteria when you evaluate candidates, and score them independently.
Motion realism
Watch how weight transfers. Does a person's foot plant before the body shifts? Does a cup placed on a table settle, or float a centimeter above it? Does fabric move with air resistance? Weak motion models produce a subtle gliding quality: everything slides rather than steps. Motion realism is the single most reliable differentiator between generations of models, more so than resolution.
Material and lighting realism
Skin, metal, glass, water, and hair each fail in characteristic ways. Skin goes waxy or oversharpened. Metal loses its reflection continuity. Glass bends the background incorrectly. Lighting that does not change as the camera moves is the giveaway that a scene is synthetic, so check how shadows behave across a slow pan.
Continuity realism
This is the criterion that decides whether you have clips or a film. Does the same character keep the same face shape, hairline, jacket, and body proportions two shots later? Do props stay in the same hand? Does time of day remain consistent? Continuity is where cheap workflows collapse and where a deliberate reference system pays off.
Temporal coherence at the edges
Look at the last ten frames of any generated clip. Models frequently destabilize near the end: faces drift, backgrounds warp, motion accelerates unnaturally. If you plan to cut on motion, generation quality at the tail matters as much as quality at the start.
Matching the Shot Type to the Right Tool
No single model wins every category, and switching models mid-project is normal. Build a simple mapping between shot archetypes and tool families, then test that mapping on your own footage rather than trusting general rankings.
Dialogue and performance beats
Close-up performance depends on facial micro-movement, lip sync, and eye direction. Some models specialize in this; others produce a slight uncanny stillness. If your script has people speaking, generate short takes, then align audio in your editor rather than expecting perfect synchronization out of the box. Expect to generate four to eight takes per usable beat and select from them.
Product, macro, and landscape shots
These are the most forgiving categories and the best place to start. Products benefit from controlled studio lighting described explicitly in the prompt. Landscapes reward panoramic camera language and high detail settings. Macro shots are harder than they look because shallow depth of field must be described, not discovered.
Action, crowds, and effects-heavy setups
Crowds, fight choreography, explosions, and complex physics remain the weakest area across the board. Treat these shots as composites: generate the plate, then add crowd layers, particles, and effects in a compositing tool. Trying to force a single model to nail a twenty-person action beat in one pass is the fastest way to burn a week.
The hybrid approach
Use one model as your workhorse for the majority of connective shots and a second model only for the hero moments where its specific strength matters. Splitting by strength rather than loyalty to a single vendor also protects you when a model changes or becomes unavailable.
The Prompt Structure That Holds Up in Production
Free-form poetry prompts produce interesting accidents, not repeatable results. Production prompting is closer to writing a shot list that a very literal crew will follow.
The five-slot template
Write every prompt in five ordered slots: subject, action, environment, camera, and finish. Subject describes who or what, with age, wardrobe, and expression. Action describes one clear physical verb. Environment covers location, time of day, and weather. Camera specifies shot size, angle, lens feel, and movement. Finish describes light quality, color palette, and texture. Keeping the order fixed makes prompts comparable and makes debugging fast, because you can change exactly one slot at a time.
Camera language with intent
Vague words like "cinematic" contribute little. Specific terms do work: slow push-in, locked-off tripod, handheld with subtle drift, low-angle tracking, 35mm equivalent with shallow depth of field. If you want a static frame, say the camera is locked off and the subject moves; otherwise the model will invent movement.
Negative constraints and shot length
State what you do not want: no text overlays, no lens flare, no extra limbs, no background pedestrians. Also state duration intent in your planning even if the interface locks clip length, because a four-second clip needs a simpler action than an eight-second one. Reduce ambition per clip rather than reducing quality per clip.
Seed discipline
Record the seed, model version, and prompt for every accepted shot in a simple spreadsheet or notes file. When you need a variant of an approved shot six days later, that log is the difference between a five-minute fix and a full reshoot of the sequence.
A Shot-by-Shot Workflow From Script to First Cut
This is the loop that consistently produces usable footage without infinite iteration.
Step 1: break the script into beats of four to eight seconds
Mark every beat that changes subject, location, or action. If a beat needs two actions, split it. A typical two-minute piece lands around twenty to thirty beats, which sounds like a lot until you remember that most are short and many can be generated from the same reference set.
Step 2: build a reference kit before generating anything
Collect or generate still images for each character, location, and key prop. Front, three-quarter, and profile views for people. Wide, medium, and detail frames for locations. This kit does three things: it anchors visual consistency, it gives you image-to-video inputs that are far more controllable than text alone, and it forces you to decide what things look like before you spend time generating motion.
Step 3: generate in passes
First pass: composition tests at low quality, short duration, one per beat. Second pass: motion tests on approved compositions, still low quality, checking whether the action reads. Third pass: final quality renders only for shots that survived the first two passes. This staged approach contrasts sharply with generating finals immediately, which is where most wasted effort happens.
Step 4: repair, upscale, and interpolate
Repair first, then upscale, then interpolate frames. Correcting a warped hand before upscaling is cheaper and cleaner than fixing it afterward. Keep source clips at native frame rate if your final deliverable is standard 24 or 30 frames per second; interpolation is for smoothing motion in specific shots, not for blanket processing.
Step 5: assemble, grade, and sound
Cut your first assembly with temporary music and no sound design. This exposes pacing problems while changes are still cheap. Then grade: unify white balance and contrast across shots generated by different models, because mismatched color temperature is the most common tell in AI-assembled footage. Finally, add ambience and foley. Sound does more for perceived realism than resolution ever will.
Keeping Characters and Locations Consistent
Consistency comes from constraint, not from luck. Generate from reference images rather than pure text whenever a recurring character appears. Keep wardrobe descriptions literal and short, since long descriptions give the model more ways to drift. Reuse the same location prompt with only the camera slot changed. Where available, use face or identity reference features and character-locking tools rather than hoping the same prompt produces the same person.
For recurring locations, decide on three anchor details: one architectural element, one color accent, and one light source direction. If those three stay stable, viewers accept minor variation in everything else. For props, keep a still reference and prefer image-to-video for any shot where the prop is in the foreground.
Planning Time, Compute, and Review Cycles
Estimate generously until you have your own data. A useful starting assumption for a beginner: ten to fifteen generated clips for every finished clip in a dialogue-heavy scene, and three to five for landscape or product shots. Track your own acceptance rate per shot type after the first project; it usually improves fast and then plateaus.
Structure review cycles around batches, not individual clips. Generate a full scene's worth of options, review them together in a single session, and make one consolidated list of changes. Reviewing clips one at a time destroys your sense of pacing and doubles iteration count, because you lose the context of how shots sit next to each other.
Common Failure Modes and How to Fix Them
| Symptom | Likely cause | Practical fix |
|---|---|---|
| Faces drift across a clip | Clip too long, no reference image | Shorten to 4-6 seconds, generate from a still reference |
| Hands warp or multiply | Complex action combined with close framing | Crop wider, simplify the action, or hide hands behind objects |
| Background pedestrians melt | Crowd density in the prompt | Generate an empty plate and composite figures in post |
| Text on signs is garbled | Models remain weak at rendering lettering | Add signage as a graphic layer in the edit |
| Motion glides unnaturally | Weak temporal model or too fast an action | Reduce action speed, split into two shots, try a different model |
| Color shifts between shots | Mixed models or mixed prompts | Grade each shot to a shared reference still before the final pass |
| Wind or hair moves against the light | Inconsistent prompt slots | Lock environment and camera wording, change only the action |
Two habits prevent most of these. First, simplify rather than re-roll: if a shot fails three times with the same prompt, the prompt is the problem, not the model's mood. Second, keep an approved-shot log so that when something does go wrong you can reproduce the good version instead of guessing.
Rights, Disclosure, and Review Before Delivery
Check the license terms of whatever you generate with, especially for commercial delivery, and keep a record of which model produced which shot. If your footage includes a recognizable person, obtain consent for their likeness, and do not generate a real person's face from reference images without permission. Many broadcasters and platforms now expect disclosure of synthetic footage, so build a short internal note listing the generated shots and the tools used; it takes minutes and prevents awkward questions later. Finally, run a human review pass on any claim, logo, or statistic that appears on screen in a generated or designed element.
Frequently Asked Questions
How long should a single AI video clip be? Four to eight seconds is the practical sweet spot. Shorter clips keep coherence high; longer clips increase drift. Extend a shot by cutting to a second angle rather than generating a twelve-second take.
Can I get photorealistic results without any image references? Yes, for landscapes and product shots. For people or recurring characters, references are close to mandatory if you want continuity across more than two shots.
Do I need a powerful local GPU? Not necessarily. Cloud generation handles most work. A local machine with a mid-range GPU is still useful for upscaling, stabilization, and editing, and it keeps iteration fast for finishing tasks.
Why do my results look worse than the examples I saw? Demo reels use forgiving subjects, short durations, and heavy curation. Your script probably includes hands, crowds, and dialogue. Judge models on your own hardest beat, not on a highlight reel.
Should I generate audio with the video? Use native audio only for reference. Replace it with recorded or designed sound in the edit. Audio quality drives perceived realism, and finished sound design is almost always better than generated ambience.
How do I handle a shot that keeps failing? Change one variable: shot size, action speed, or model. If three attempts fail, cut the shot or replace it with an insert. A new angle solves more problems than a new prompt.
Key Takeaways
- Treat text-to-video as three layers: generation, control, and finishing. Skipping control or finishing is what makes projects fail.
- Judge models on motion, materials, continuity, and clip-end stability, not on stills.
- Map shot archetypes to tools, and use a hybrid approach instead of forcing one model to do everything.
- Write prompts in fixed slots, keep a seed and prompt log, and generate in three passes: composition, motion, final.
- Build a reference kit before generating motion, and repair before upscaling.
- Grade across shots and invest in sound design; both do more for realism than extra resolution.
- Track your own acceptance rate per shot type and plan review in batches, not clip by clip.
