
Why "Best Model" Is the Wrong Question
For a couple of years, choosing an AI video generator looked like a spec-sheet exercise. Compare render quality, compare clip length, compare prompt adherence, pick a winner, move on. That framing has quietly collapsed. The practitioners who ship finished sequences on a schedule are not loyal to a single renderer. They treat generative models as interchangeable rendering engines inside a pipeline that is anchored to something far more stable: approved reference imagery.
That shift changes what you evaluate. Instead of asking which model produces the best-looking five-second clip, you start asking which combination of reference assets, renderers, and editing habits gets you twelve consistent shots with the least rework. Those are different questions with different answers. A model that wins a demo reel can lose a production schedule the moment a character has to appear in four scenes wearing the same jacket.
This guide covers the two renderers that dominate most shortlists, Runway and Kling, then walks through the workflow layer that solves what neither one fully solves alone: reference-image fusion, where multiple visual anchors are blended into a conditioned generation so identity, wardrobe, and environment stay locked across an entire sequence.
The Failure Modes That Kill Multi-Shot Projects
Single shots lie. A five-second clip of a figure walking through rain can look genuinely cinematic in isolation. The trouble starts at cut three, when the same character has a slightly narrower jaw, a jacket that shifted from charcoal to navy, and a background that teleported from a neon alley into a generic European plaza.
These failures are predictable, which means they are preventable. Here is what actually goes wrong, in rough order of how often it destroys a sequence:
Facial drift. Eye spacing, nose width, cheek volume, and apparent age wobble between generations. The character stays recognizable but stops being the same person. This is the single most common reason AI-assisted narrative projects get abandoned in post.
Wardrobe mutation. Logos vanish, fabric sheen changes, buttons migrate, scarves gain or lose stripes. Viewers may not name the problem, but they register it as sloppiness.
Environment teleportation. Props rearrange, windows move, signage changes language inside what is meant to be one continuous location.
Style slippage. Grain, contrast, saturation, and color temperature drift, so consecutive cuts feel like footage pulled from different productions.
Motion artifacts. Hands melt, teeth smear, hair fuses with background, and fast pans dissolve into mush. Small text and reflections are the other reliable tell-tale zones.
Camera-language inconsistency. One shot is handheld and intimate, the next is a locked-off wide with completely different lens character. Cut together, it reads as an accident rather than a choice.
Delivery-spec mismatches. Mixed aspect ratios and frame rates create letterboxing and judder that no amount of grading fixes cleanly.
Text prompts cannot fully repair these problems, because language is a lossy description format for faces and spaces. A phrase like "mid-thirties, sharp cheekbones, dark curly hair, olive field jacket" maps to millions of possible humans and thousands of possible jackets. Every renderer samples that ambiguity differently, and it samples it differently again on the next generation. Reference images collapse the ambiguity. When you hand a model three clean photographs of one person plus a wardrobe plate and a location still, you have converted a fuzzy verbal guess into a concrete visual anchor that can be reapplied shot after shot.
Runway: Cinematic Control and Repair Depth
Runway is the tool people reach for when they want footage to feel directed rather than merely generated. Its advantage is not raw prompt obedience. It is the surrounding control surface and, just as importantly, the repair layer that lets you fix a bad clip instead of discarding it.
Where Runway Earns Its Place
Region and motion control. You can define which part of the frame moves and roughly how. For product shots, dialogue-adjacent scenes, and anything where a subject must stay still while the environment breathes, this changes the output dramatically.
Keyframe interpolation. Supplying a first and last frame gives you precise control over how a shot begins and ends. That precision is what makes editing bearable, because clips land on the frame you planned for.
Style references. Uploading a look reference steers grading and texture across a whole sequence, which is the closest thing to a consistent film stock that generative video currently offers.
Post-generation repair. Inpainting, extend, and selective re-rendering let you patch a broken hand or a corrupted background plate without regenerating the entire shot. On a tight schedule this capability is worth more than a marginal quality edge.
A mature editing environment. Generated clips sit alongside imported footage, so you can treat output as rushes rather than finished assets.
Where Runway Pushes Back
The learning curve is real and it bites early. New users frequently produce worse material than they would on a simpler tool because the number of parameters invites over-tinkering. Every extra control is another chance to fight the model instead of collaborating with it.
Iteration cost also compounds. When a fix requires re-rendering a full clip rather than patching a frame, small corrections get expensive fast. And crucially, character consistency still depends on you supplying strong reference material. The tool will not invent a stable identity on your behalf, no matter how well you write the prompt.
A Concrete Example
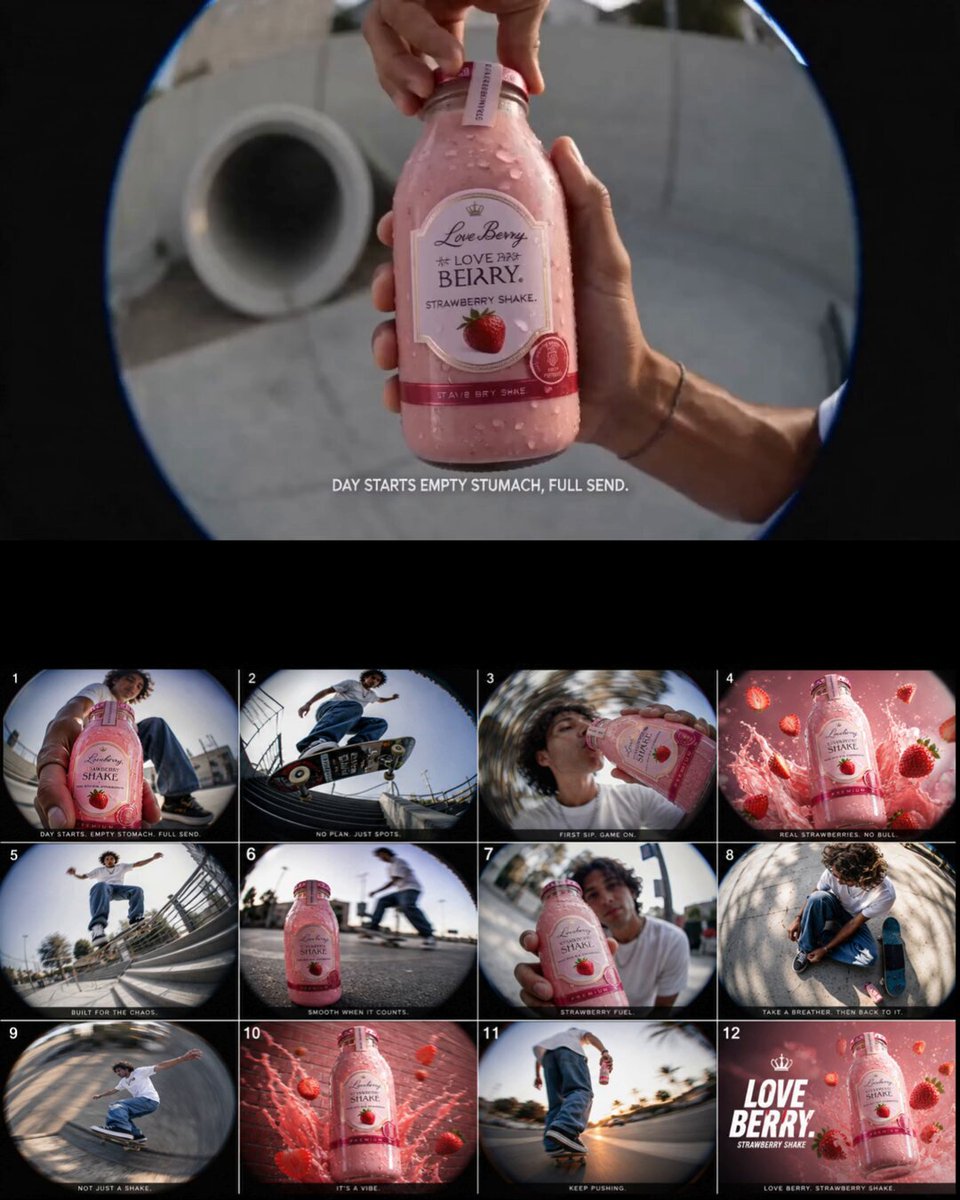
Picture a thirty-second spot for a ceramic kettle. The camera should push in slowly while steam rises and the background stays soft. In a pure text-to-video approach, you will burn many attempts getting the push speed right while the kettle's lid handle subtly changes shape between takes. In a keyframe-first approach, you generate one still of the kettle, approve it, then animate from that still with a defined end frame. The lid never mutates because it was never re-imagined. The camera move becomes a parameter instead of a prayer.
Kling: Prompt Adherence and Motion Fluency
Kling built its reputation on two things: understanding longer, more specific prompts, and rendering human movement that does not look like a puppet being dragged through space.
Where Kling Earns Its Place
Descriptive accuracy. Complex, multi-clause prompts survive better here than on most competitors. If your shot description includes a subject, an action, a wardrobe detail, and a lighting condition, the model tends to honor more of that list rather than collapsing it into a generic interpretation.
Human and physics-driven motion. Body movement, fabric reactions, splashes, and weight transfer read convincingly. For dance, sport, cooking, and any shot where momentum has to feel plausible, this is a meaningful advantage.
Image-to-video as a first-class entry point. Starting from a still is not an afterthought, which is exactly what consistency-focused pipelines need. You can approve a frame and then ask for motion.
Fast iteration. Quick turnaround encourages exploration. Creative teams that can test five ideas in the time it takes to test one will find better ideas, and that matters more than most people admit when they are comparing feature lists.
Where to Plan Around Limits
Kling is stronger at generating than at repairing. The editing and compositing layer is thinner, so complex post-generation fixes often mean exporting into another application. Budget for that handoff in your schedule rather than discovering it mid-project.
Availability and queue behavior can also affect deadline work, since load varies by region and time. Expressive close-ups are good but not flawless: emotion-heavy shots may need several attempts, and each attempt consumes time you should have reserved in advance.
Reference-Image Fusion: A Pipeline Layer, Not a Model
Here is the mental shift that resolves most consistency problems. Stop thinking of fusion as a feature you buy and start thinking of it as a stage in your pipeline, one that sits between asset preparation and rendering.
A fusion workflow takes multiple reference inputs, such as a face, an outfit, a prop, a location plate, and a color script, and combines them into a single conditioned generation. The renderer then animates that conditioned frame rather than inventing a new subject from a sentence.
The Four Mechanics
Multi-angle identity extraction. Instead of trusting one photograph, the pipeline reads identity from several angles of the same subject. Front, three-quarter, and profile views together describe a face far more completely than any single image, and they reduce the chance that a stray shadow becomes a permanent feature.
Scene-level conditioning. Identity alone is not enough. Location, lighting direction, time of day, and wardrobe are combined with the subject so the character sits inside a coherent world rather than being pasted onto a background.
Per-shot re-anchoring. Every new shot is re-anchored to the same reference set. Drift cannot accumulate across a sequence because each generation starts from the same approved source of truth rather than from the previous clip.
Temporal smoothing. Frame-to-frame flicker is reduced before you ever open an editor. This saves hours that would otherwise disappear into stabilization and noise reduction.
Why This Changes Your Evaluation Criteria
The practical benefit is psychological as much as technical. Once an anchor exists, you stop judging each clip on whether it looks impressive and start judging whether it matches the approved reference. That single change in criteria eliminates most of the back-and-forth that burns render budgets, because "close enough to the anchor" is a decidable question and "is this good?" is not.
Building a Character and Asset Bible
This is the highest-leverage hour you will spend on any AI video project. Build it once, reuse it for months.
Face Sheet
Collect three to four clean views of the character: straight-on, three-quarter, profile, plus one neutral expression with no dramatic lighting. Avoid sunglasses, heavy shadows, and extreme angles. If a character appears in tight close-ups, add two more views with different lighting conditions so the pipeline understands how the face behaves in shadow.
Wardrobe and Props
Photograph each outfit flat or on a mannequin, front and back. List every prop that must remain identical on screen, and give each one its own reference image. A watch, a phone, a bag, a weapon, a piece of signage: anything a viewer might track across cuts deserves its own plate.
Locations and Lighting
Create a location plate for each setting, ideally at the time of day you intend to shoot. If a scene moves from morning to evening, make two plates. This prevents the classic problem of a room that is warm and golden in one shot and cold and blue in the next.
Style, Lens, and Palette
Write down your color script, target contrast level, grain preference, and preferred focal length. Attach a still that represents the look. Anyone joining the project can then match the tone without a meeting.
Naming and Storage Conventions
Use predictable filenames such as character-aria-face-front.png and location-diner-morning.png. Keep the folder in a shared location. A reference library that only one person can find is not a reference library; it is a rumor. Version it, and note which references were used for which shots so you can reproduce a result weeks later.
A Complete Production Workflow, Still by Still
This sequence works for narrative shorts, product spots, and serialized social content alike.
1. Lock the script and shot list first. Generative video rewards planning more than any other medium. Write the beats, then break them into individual shots with duration estimates and a note about whether each shot is a hero moment or connective tissue.
2. Generate stills before motion. Create and approve a keyframe image for every shot. Stills are cheap to iterate; clips are not. This is the step people skip and later regret.
3. Approve anchors explicitly. Get sign-off on the character's face, wardrobe, and location look before animating anything. Say the approval out loud, in writing, in the project file.
4. Animate from approved frames. Use image-to-video so the model inherits identity instead of guessing it. This is the core of consistency, and it costs nothing except discipline.
5. Generate coverage, not just hero shots. Overshoot wides, inserts, and reaction beats. Editing needs options, and a sequence assembled only from planned shots always feels stiff.
6. Cut in an editor, not in the generator. Treat output as rushes. Assemble, trim, and test rhythm before polishing anything. You will often discover that a shot you almost re-rendered works perfectly at a different length.
7. Patch surgically. Re-render only the broken shot, with tighter references and a sharper prompt. Regenerating an entire scene to fix one hand is the most common way to waste a day.
8. Add sound and color last. Audio and grading hide more sins than extra render passes ever will. A believable room tone plus a deliberate grade can rescue a shot that looks mediocre raw.
9. Archive references and prompts. Store the reference set, the prompt text, and the model settings next to the final edit. The next project then starts at double speed.
10. Do a continuity pass. Watch the sequence with the sound off and list every visual inconsistency. Then decide which ones are worth fixing and which ones nobody will ever notice.
11. Deliver in the right spec. Confirm aspect ratio, frame rate, and loudness targets before export. Mixed delivery specs are a self-inflicted wound.
12. Keep a decision log. One line per shot noting what worked and what failed. Over three projects this becomes your personal playbook, and it is worth more than any feature comparison.
Choosing the Right Approach: Project Fit, Scoring, and Team Reality
Different formats reward different strategies. Rather than declaring a universal winner, match the method to the job.
| Project type | Recommended path |
|---|---|
| Talking-head explainer | Locked still plus image-to-video with strong face references |
| Cinematic narrative short | Keyframe-first with deliberate camera control and per-character anchors |
| Fast social series | Fixed template prompt and one reusable character bible |
| Product spot | Controlled camera moves, plate references, minimal subject motion |
| Abstract or mood piece | Text-to-video exploration, then convert the winners into reference stills |
| Documentary-style montage | Mixed sources plus a unifying grade and consistent grain |
How to Score Output Fairly
Stop evaluating clips in isolation. Score them against your anchor set:
- Identity fidelity across shots. Does the character read as the same person at cut three and cut nine?
- Motion plausibility. Do weight, momentum, and contact with surfaces make sense?
- Prompt adherence. Did you get the action, framing, and mood you asked for?
- Camera control. Can you specify movement, or are you at the model's mercy?
- Artifact profile. Hands, teeth, small text, and reflections are the usual failure zones.
- Repairability. Can a bad frame be patched, or does the whole clip need a redo?
- Cost per usable second. This is the metric that matters, not cost per generation.
The last point deserves emphasis. A cheaper option that yields one keeper out of ten attempts is more expensive than a pricier option that yields a keeper on the second try. Track usable seconds per session, not raw clip count, and you will make better decisions within a week.
Team Fit
A solo creator can tolerate a fiddly interface if it produces better footage. A five-person team cannot. If handoffs are frequent, favor tools with shareable projects, consistent export settings, and predictable file naming. Document your anchor conventions so a new collaborator can match the look without asking. And keep an eye on your plan's usage allowance so a heavy week does not stall production unexpectedly; read the terms before the deadline week, not during it.
Common Mistakes and How to Avoid Them
Most wasted hours come from process, not from model choice.
Chasing one perfect mega-prompt. Long prompts dilute control instead of increasing it. Build the look with references and keep the prompt focused on action and camera.
Animating before approving stills. You will re-render the same broken shot five times. Approve the frame first.
Switching renderers mid-sequence. Style continuity suffers. Finish a sequence on one engine whenever possible, and if you must switch, re-anchor to the same reference set so only the texture changes.
Ignoring aspect ratio and frame rate. Mixed specs create letterboxing and judder in the final export, and fixing them after the fact is painful.
Neglecting wardrobe locks. A jacket that changes color between shots is more distracting than a slightly stiff walk cycle.
Regenerating instead of patching. Surgical fixes are almost always faster and cheaper than full re-renders.
Skipping sound design. Audio sells a cut more effectively than another render pass. Room tone, footsteps, and a clean music bed do enormous work.
Not archiving prompts and references. Rebuilding a character from memory costs a full day and rarely matches the original.
Over-directing the model. If a shot keeps failing, the problem is usually that two of your requirements contradict each other. Simplify one element and let the model solve the rest.
FAQ
Do I need both Runway and Kling?
Not strictly, but many teams use one for motion-heavy hero shots and the other for rapid exploration. The pipeline matters more than the roster. If you only run one renderer, invest the saved time in a better asset bible.
How many reference images per character is enough?
Three to four clean angles usually stabilize identity. Add more if the character appears in extreme close-ups or under very different lighting conditions.
Can reference-image fusion fix a sequence I already generated?
Partly. You can re-anchor individual shots, but rebuilding from approved stills produces cleaner continuity than patching finished clips. Treat retrofitting as a rescue operation, not a workflow.
Is text-to-video still useful?
Yes, for exploration and abstract work. Use it to find a look, then convert the winners into reference stills for the actual sequence.
What is the fastest way to improve output quality?
Approve stills before animating. That single habit eliminates most re-renders, and it costs nothing but patience.
How many attempts should I budget per shot?
Assume two to three attempts for straightforward shots, and add a thirty percent buffer for the ones that misbehave. Complicated hands, crowds, and fast camera moves deserve more.
Should I generate audio in the same tool?
Generate dialogue and effects separately when you can, then mix in an editor. Native audio is improving but still constrains how freely you can cut.
What if my character drifts in only one shot?
Re-render that shot with an additional close-up reference and a tighter prompt. Do not rebuild the whole scene, and do not switch renderers out of frustration.
How do I keep a series visually consistent across episodes?
Freeze the anchor set. Same face references, same wardrobe plates, same palette notes, same lens preference. Change the story, not the visual grammar.
When should I accept a flawed shot?
When the flaw is invisible at delivery speed and the fix would cost more than it improves. Perfectionism at the frame level rarely survives contact with a deadline.
