
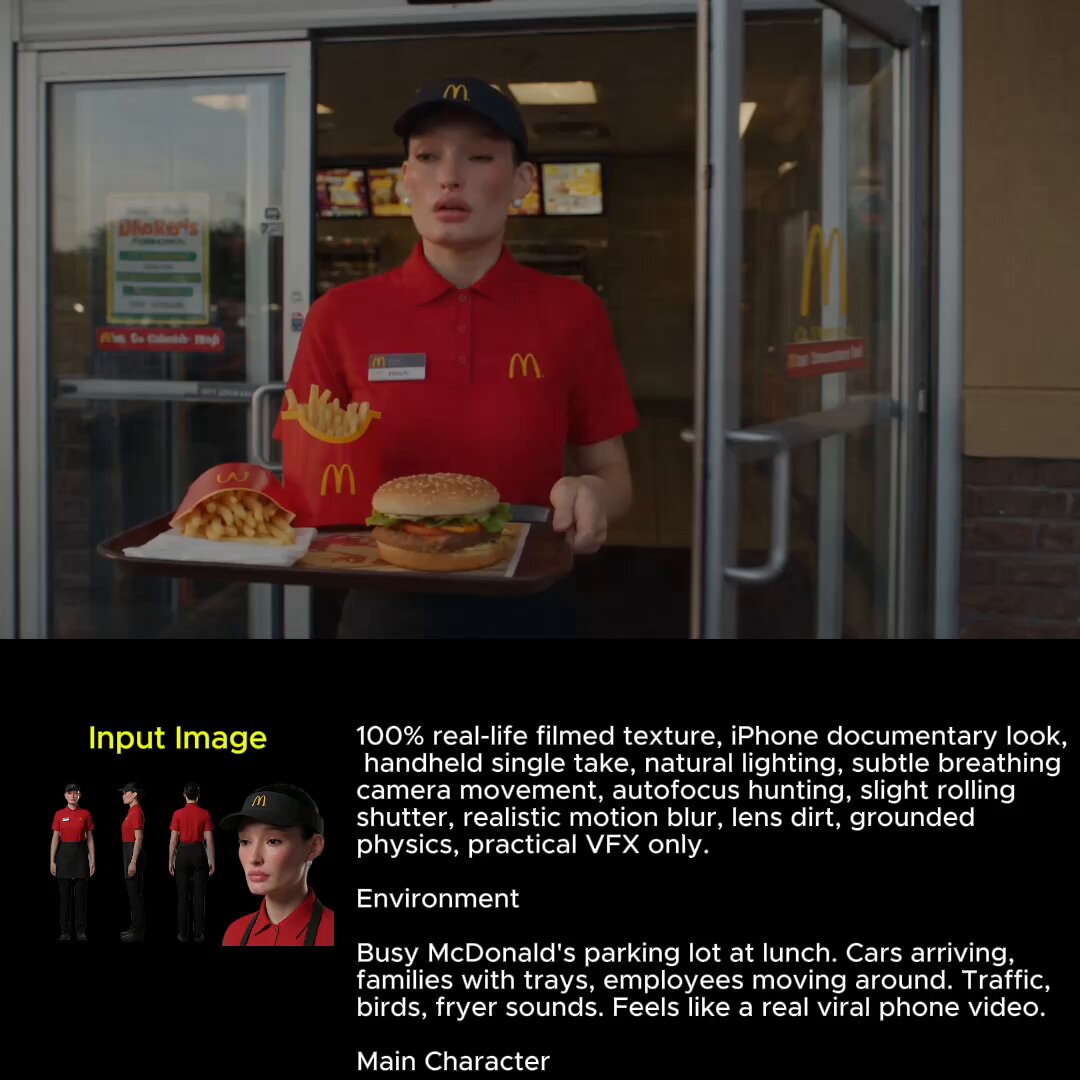
Cinematic AI video has quietly stopped being a novelty. What used to be a five-second curiosity with melting faces and drifting backgrounds is now a legitimate production stage: writers, editors, and solo creators are turning scripts into watchable footage without a camera, a crew, or a location budget.
The interesting part is not the generation itself. It is that the craft has split into recognizable stages — script breakdown, look development, keyframe generation, motion generation, assembly, and sound — each of which can be improved independently. That is exactly how conventional post-production works, and it is why the results have gotten so much better so quickly.
This guide walks through a complete, repeatable workflow for turning text into cinematic video. It is tool-agnostic on purpose: the same structure holds whether you are generating a 30-second product film, a short narrative scene, or a series of social cutdowns.
Why Text-to-Video Finally Looks Like Filmmaking
The leap is architectural, not magical. Modern pipelines separate what happens from how it looks from how it moves.
Language models handle structure: they can break a script into beats, propose shot lists, estimate pacing, and rewrite a scene for a tighter runtime. Image models handle aesthetics: lighting, lens character, color palette, costume, and set design. Video models handle motion: camera moves, subject performance, physics, and temporal consistency. Edit and audio tools handle rhythm.
When you keep those layers separate, problems become diagnosable. If a shot looks flat, the fix lives in the keyframe or the look direction, not in the motion model. If a shot looks good but feels wrong, the fix lives in the edit or the sound, not in the generation. Filmmakers who treat AI video as one big prompt-and-pray box get inconsistent output; filmmakers who treat it as a pipeline get controllable output.
The second shift is continuity tooling. Keyframe conditioning, reference images, and multi-image fusion let you lock a character's face, wardrobe, and environment across multiple shots. That single capability is what turns disconnected clips into something that reads as a scene.
The Six-Stage Workflow, End to End
Before diving into details, here is the full arc. Every stage produces an artifact you can review, reject, or iterate on.
Stage 1 — Script to shot list
Take your written piece and break it into shots with an intent attached to each one. A shot is not a sentence; it is a camera decision. One line of prose might become three shots, or three lines might collapse into a single slow push-in.
For each shot, write: subject, action, camera behavior, lens feel, lighting, and duration. That is your shot card. If you cannot fill in those six fields, the shot is not ready to generate.
Stage 2 — Look development
Generate 4–8 still keyframes for the most important shots. Do not generate video yet. Compare them side by side. Ask whether they could plausibly come from the same film: same grade, same lens family, same contrast curve.
This stage is cheap and fast, and it prevents the most expensive mistake in AI video — generating ninety seconds of footage with five different visual identities.
Stage 3 — Keyframe locking
Once the look is approved, produce a locked keyframe for every shot. These become the start frames for motion generation. Where a shot involves a big move or a transformation, generate an end frame as well and interpolate between them.
Stage 4 — Motion generation
Now generate video. Keep clips short — three to eight seconds — and generate two or three variants per shot. Choose on motion quality, not on whether it matches your mental image; that is a job for the keyframe stage.
Stage 5 — Assembly
Cut the clips on a timeline. This is where pacing lives. A shot that felt slow in isolation often reads as confident and deliberate once it has music under it. Conversely, an action beat that felt snappy alone can feel frantic in sequence.
Stage 6 — Sound and finishing
Add ambience, foley, dialogue, and score. Apply a unified grade and grain pass across all clips so the AI-generated seams disappear. Export at your target delivery specs.
Writing Prompts That Behave Like Shot Notes
The single biggest quality lever is prompt discipline. Vague prompts produce generic footage because the model fills gaps with statistical averages. Specific prompts produce specific footage.
A workable prompt structure, in order:
- Shot type and angle — wide establishing, medium two-shot, tight over-the-shoulder, macro insert.
- Subject and wardrobe — age, build, clothing material, distinguishing details.
- Action in the present tense — one verb, one motion.
- Camera behavior — slow dolly left, handheld follow, static locked-off, crane up.
- Lens and format — 35mm spherical, anamorphic flare, shallow depth of field.
- Lighting and time of day — overcast dawn, tungsten practicals, hard midday sun.
- Grade and texture — muted teal shadows, warm highlights, fine grain, no digital sharpening.
Keep it to roughly 60–120 words. Longer prompts dilute attention; shorter prompts leave too many decisions to chance.
Use negative guidance sparingly and specifically. "No text overlays, no watermarks, no extra limbs" is useful. "No bad quality" is not — the model has no stable definition of the term.
Finally, name a style reference rather than a brand. "1970s documentary realism" produces a coherent look. Copying a named studio's house style produces a muddled pastiche and often trips content filters.
Holding Continuity Across Many Shots
Continuity is the difference between a demo reel and a scene. Four techniques do most of the work.
Lock the character first
Generate a clean, front-facing, evenly lit portrait of each principal character. That image becomes a reference for every subsequent shot. Reuse it rather than regenerating from text, because text-to-image is nondeterministic.
Reuse the environment
Generate one wide establishing shot per location and use it as a style anchor. When you cut to a close-up, keep the same light direction and color temperature. Continuity failures are usually lighting failures, not face failures.
Protect the 180-degree line
Track which direction characters face relative to each other. If a character faces right in the wide shot, they should still face right in the coverage. AI models have no blocking awareness; the ask has to be explicit.
Carry the grade forward
Apply one look-up table or grade stack to every clip. This is the cheapest continuity fix available and the most frequently skipped. Thirty seconds in a color tool will do more for perceived quality than thirty extra generations.
Choosing the Right Model for Each Shot Type
No single video model is best at everything. A practical split:
- Dialogue and performance — prioritize models with strong facial consistency and subtle micro-expression handling. Expect to accept slightly less dynamic camera work.
- Landscapes and establishing shots — prioritize models with strong environment detail and convincing atmospheric depth. Slow, low-motion prompts work best here.
- Action and physical stunts — prioritize models with strong motion coherence. Keep shots under five seconds and cut fast; long action takes still break.
- Product and tabletop — prioritize models with stable geometry and accurate reflections. Locked-off camera with a subtle push is the safest recipe.
- Stylized and illustrative — prioritize models with strong artistic interpretation and loosen the continuity requirements.
A useful rule of thumb: match the model to the hardest constraint in the shot. If the shot needs a recognizable face, optimize for identity. If it needs a sweeping camera move, optimize for motion. Trying to satisfy both with one model usually degrades both.
A Practical Tool Stack for a Solo Creator
You do not need a studio to run this pipeline. A lean stack looks like:
- A script editor for breakdown and shot cards (a plain spreadsheet works well).
- A language assistant for beat analysis and prompt drafting.
- An image generator for keyframes and character references.
- Two or three video generation models rather than one, so you can route shots.
- An editor with solid proxy handling and audio tools.
- A color tool or a built-in grade stack.
- A sound library or a music generator for score and ambience.
- A folder structure that separates references, keyframes, raw clips, selects, and finals.
The folder structure matters more than people expect. AI projects generate hundreds of files quickly, and the difference between a smooth edit and a lost afternoon is often just naming discipline.
Budgeting Time Instead of Money
Compute allowance is the practical constraint on AI video work, so think in time, not currency. For a 60-second finished film, a realistic breakdown looks like this:
- Script and shot list: 60–90 minutes
- Look development and keyframes: 2–3 hours
- Motion generation and variant selection: 3–4 hours
- Assembly and rough cut: 1–2 hours
- Sound and finishing: 1–2 hours
That is roughly one focused day for a minute of polished output, and it drops by half once you have a repeatable shot-card template. Beginners typically spend 70% of their time in the motion stage because they skip the keyframe stage. Do not skip the keyframe stage.
If you are on a limited generation allowance, spend it in this ratio: 15% keyframes, 65% motion, 20% re-doing shots that failed continuity. The last bucket is not waste — it is inevitable.
Common Mistakes and How to Fix Them
Generating video before approving stills. The most expensive error. Fix: never generate motion until your keyframes look like they belong in the same film.
Overlong prompts. Fix: cut to one action and one camera move per shot. Split anything complex into two shots.
Overlong clips. Models drift after six to eight seconds. Fix: cut earlier than feels natural, then let the edit create the sense of duration.
Inconsistent lighting between shots. Fix: state light direction and color temperature explicitly in every prompt, and unify with a grade pass.
Ignoring sound until the end. Sound carries continuity more than picture does. Fix: lay in ambience early, even as a placeholder, so you can judge pacing honestly.
Chasing a perfect single shot. Fix: generate three variants, pick one, move on. Perfectionism at the shot level destroys projects at the sequence level.
No negative prompts. Fix: add a short, specific negative line addressing artifacts you actually saw in prior generations.
A Quality-Control Checklist Before You Export
Run this pass on every project. It takes ten minutes and catches most visible problems.
- Does every clip match the film's grade and grain?
- Is the light direction consistent within each scene block?
- Do characters keep the same wardrobe, hair, and accessories?
- Are there any hands, teeth, or text artifacts in close-ups?
- Does dialogue sync within a frame or two at the cut point?
- Do camera moves have a reason — motivated by the action?
- Is the runtime within 5% of target?
- Does the first three seconds work with sound off?
- Are audio levels consistent at -14 to -16 LUFS for web delivery?
- Is every shot exportable at the target resolution without upscaling artifacts?
Anything that fails a check goes back one stage, not to the beginning. That is the whole benefit of a staged pipeline: you fix the smallest unit that is broken.
Frequently Asked Questions
Do I need a storyboard artist?
No, but you do need a shot list. Even a rough one prevents the most common failure mode in AI video: footage that looks good but does not cut together.
How long should each generated clip be?
Three to eight seconds for most work. Very static shots can run longer; anything with subject motion should be cut short and extended through editing.
Can I get consistent characters across many shots?
Yes, if you lock a reference image and reuse it as a conditioning input rather than re-describing the character in text each time. Text descriptions drift; reference images do not.
Is it better to use one model or several?
Several. Routing shots by their hardest constraint consistently outperforms forcing one model to handle everything.
What resolution should I target?
Generate at or above your delivery resolution. Upscaling generated footage tends to amplify artifacts rather than resolve them.
How do I handle dialogue?
Generate the performance without relying on lip-sync accuracy, then either dub clean audio over a cutaway, or use a lip-sync pass in post. Writing around dialogue is the more reliable strategy for longer pieces.
Where This Workflow Goes Next
The direction of travel is clear: more control surfaces, not fewer. Keyframe conditioning, depth and motion hints, pose references, and multi-image fusion are all converging on the same idea — give the creator the same levers a physical camera department has, and let them make decisions in the order a film is actually made.
That means the most valuable skill in AI video is not prompt trivia. It is production literacy: knowing why a shot is a close-up and not a wide, why a scene cuts on a look and not a line, why a grade unifies footage that came from five different sources.
Start with a 30-second scene. Break it into eight to twelve shots. Approve your keyframes. Generate short, cut fast, and unify with sound and color. Then run the same pipeline again and watch how much faster and better it gets the second time — that repetition, not any single model, is what turns text into something that genuinely feels like cinema.
