
Why text-to-video is finally a practical production method
A script used to be the cheapest part of video production and the furthest thing from the finished frame. Everything between the page and the screen — casting, locations, lighting, cameras, crew — carried the real cost. Generative video collapses that distance. You can describe a scene in a sentence, wait a minute, and watch something move that resembles the picture in your head.
That collapse is useful, but it is not magic. The gap between someone who generates a few impressive clips and someone who ships watchable videos every week is process, not luck. Random prompting produces random results: a character changes jackets between shots, a camera move fights the subject, a ten-second clip contains two seconds of usable footage. A repeatable workflow removes most of that friction.
This guide covers a practical text-to-video pipeline you can run alone or with a small team: the stages from script to export, how to choose a generation approach, how to hold characters and locations steady, what to do about sound, and the mistakes that burn the most time. Treat the models as interchangeable parts. Names change every few months; the method does not.
The pipeline at a glance: five stages from script to screen
Most failed AI video projects skip a stage. They jump from idea straight to generation, then try to fix structural problems in the edit — the most expensive place to fix anything. Keep decisions in the order below, where they are cheapest.
Stage 1: Script compression
Read your script out loud and mark every sentence that changes what the viewer knows or feels. What remains is your beat map. A two-minute video usually holds six to twelve beats. More than that feels breathless; fewer drags.
Write each beat as a plain sentence: "Maya opens the box and finds the note." That is not a prompt yet. It is a production instruction that tells you what the shot has to accomplish.
Stage 2: Shot list and visual grammar
Turn beats into shots. Decide scale (wide, medium, close), angle, and movement (static, push in, pan, handheld). Keep one movement per shot; two movements in a five-second clip read as chaos, because the model invents continuity it cannot see. Lock your aspect ratio and frame rate here too. Changing them later forces you to re-generate framing decisions.
Stage 3: Style and character locking
Before generating anything, write two blocks. The style block is a fixed sentence describing rendering, lighting, lens, and palette. The character block describes each recurring person in identical words — age range, hair, wardrobe, distinguishing features. Keep both in a text file and paste them into every prompt. Consistency is boring administrative work, and it is the highest-leverage habit in AI video.
Stage 4: Generation passes
Generate in passes instead of one final clip at a time. First pass: rough versions of every shot at low resolution or short duration to confirm composition. Second pass: regenerate only the failures, keeping what works. Third pass: upscale and extend the approved shots. It sounds slower than generating final quality immediately. It is far faster, because you are not discarding finished renders over a framing mistake.
Stage 5: Assembly and finishing
Cut approved clips against a scratch track — music or a narration read. Rhythm problems become obvious in seconds. Trim, reorder, and only then invest in sound design, grade, and titles.
Writing prompts that survive generation
A prompt is a shot description plus a style contract plus a technical constraint. Most prompts fail because they carry too much narrative. A model cannot render "she realizes she has been betrayed." It can render "close-up of a woman's face, eyes widening slightly, slow push in, soft window light."
Use a consistent order so you can debug fast:
- Subject and action — who or what, doing one verb.
- Shot and lens — close-up, 35mm, shallow depth of field.
- Lighting — golden hour backlight, overcast diffusion, practical neon.
- Environment — rain-slick street, cluttered workshop, empty lobby.
- Motion — slow dolly left, handheld follow, static tripod.
- Style block — your fixed rendering sentence.
- Negatives — text overlays, warped hands, extra limbs, watermarks.
Two rules save the most time. One action per shot. And describe what the camera sees, not what the character thinks. Models are literal in unpredictable ways; ambiguity produces drift.
Keep a prompt log. When a shot works, save the exact prompt, seed, model, and settings. That log turns luck into a reusable asset, and it is the only reliable way to reproduce a look months later.
Text-to-video, image-to-video, or hybrid: choosing the right approach
Not every shot should be generated from text. Picking the wrong entry point is the second most common source of wasted hours.
Text-to-video suits establishing shots, abstract sequences, environments, and any moment where exact identity does not matter. It is fast and flexible, and it struggles with faces that must match an earlier shot.
Image-to-video suits anything where composition or identity matters. Generate a still first — in an image model, or by grabbing a frame you like — then animate it. You control framing, wardrobe, and lighting before motion enters the equation. For character-driven work, most shots should start as images.
Hybrid work mixes both: text for atmosphere, images for recurring people and products, and real footage where authenticity matters. A chair, a keyboard, a coffee cup on a desk: you can shoot those with a phone in thirty seconds and they will look better than any generation.
The decision rule is simple. If a viewer could identify the shot as "that person" or "that product," start from an image. If not, text is fine.
Consistency techniques that reduce visual drift
Drift is the slow erosion of identity across shots. Faces soften into generic features, jackets change color, a room rearranges itself. You cannot eliminate it, but you can hold it down.
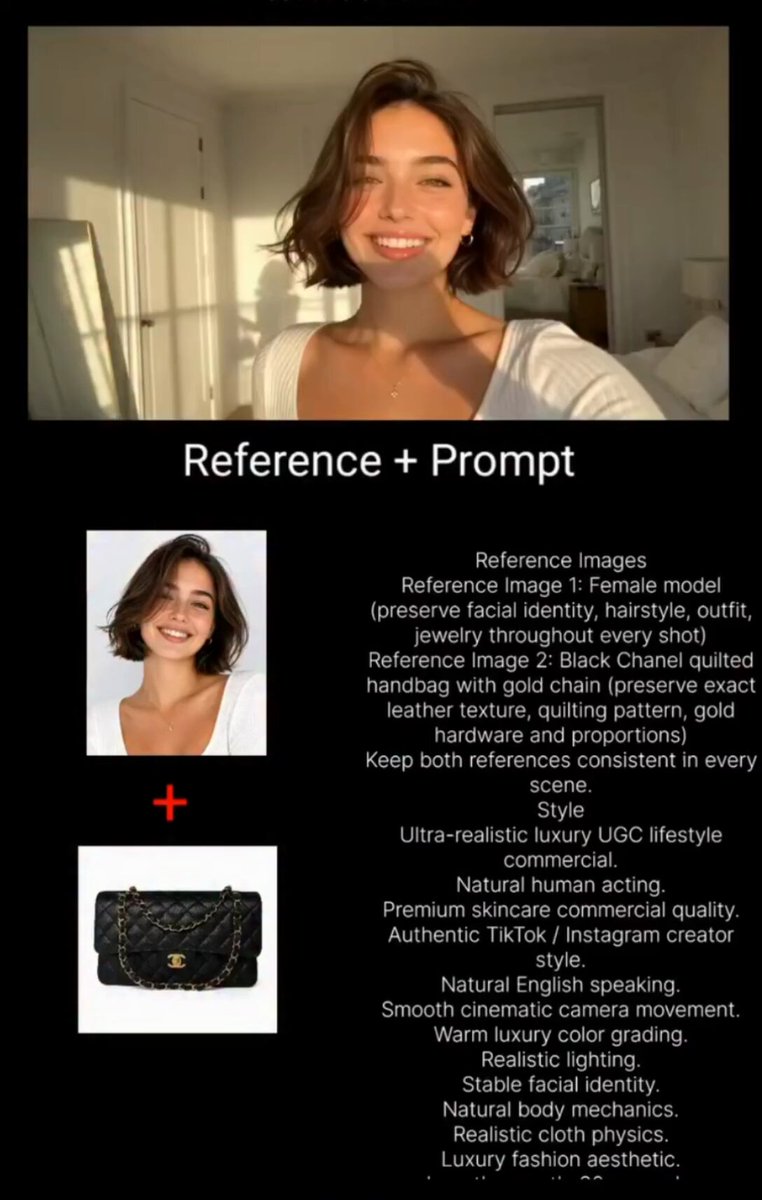
Anchor frames. Lock one reference image per character and location and feed it into every generation. Models that accept reference images or character locking preserve far more than text alone.
Keyframe control. For tricky sequences, generate the first and last frame of a shot, then let the model interpolate the middle. That is how a camera move lands where you want instead of drifting off target.
Short clips. A five-second clip holds together better than a fifteen-second one. Build long takes from short pieces and hide the seams with match cuts, occlusion, whip pans, or cuts on a beat.
Wardrobe and location bibles. One outfit per character per scene, described identically every time. Four fixed details per location — wall color, key light direction, one hero prop, flooring — repeated verbatim. Those details carry scene recognition.
Seed reuse. When a model supports seeds, reuse the seed within a scene. It nudges grain, texture, and color toward consistency even as composition changes.
Voice, sound, and lip sync
Silent AI video feels like a screensaver. Sound is what makes it feel authored, and there are three layers to plan.
Narration is the easiest win. Generate a voice track from your script, or record it yourself with a decent USB microphone. Self-recorded narration beats synthetic voice for anything with a personal or brand voice, and it gives you exact timing to cut against.
Dialogue and lip sync are harder. If a character speaks, generate audio first, then animate the mouth to match, or pick a model with built-in lip sync. Keep talking shots short and close. Wide shots with dialogue are a trap: the mouth is too small to read and the mismatch becomes obvious.
Music and effects carry the most emotion per minute of effort. Lay ambience first — room tone, traffic, wind, rain — then spot effects for actions, then music. Music tells the audience how to feel; ambience tells them where they are.
A reliable order of operations: lock picture, lay ambience, add effects, add music, mix dialogue to sit above everything, then normalize to a consistent loudness target.
Post-production: making generated footage feel intentional
Raw generations share a signature look: over-smooth motion, shallow contrast, and a slight dreaminess that reads as artificial. A short finishing pass removes most of it.
Rate and motion. Small speed changes, gentle frame blending, or rendering at 24 fps with a touch of motion blur make generated movement feel photographic. Do not overdo it; over-processed footage smears.
Grade and grain. A single color grade across all shots unifies footage from different models. Add a little grain and halation. Contrast and grain disguise generation artifacts better than any upscaler.
Cut rhythm. Generated clips often lack internal rhythm, so the edit supplies it. Cut on action, cut on beat, and use reaction shots to cover weak motion. A close-up of a face is almost always more convincing than a wide shot of a crowd.
Titles and graphics. Clean typography, consistent spacing, and a restrained palette signal that a human finished the job. Skip decorative animated text templates.
For tools, use what you already know: DaVinci Resolve or Premiere Pro for cutting and grading, After Effects or Fusion for cleanup and tracking, and a dedicated detail upscaler for final polish. The tool matters less than doing the pass.
Common mistakes and how to fix them
Prompting a story instead of a shot. Fix: one action, one camera instruction, one lighting description per clip.
Generating final quality on the first pass. Fix: draft low, approve compositions, then commit.
Revising the style block mid-project. Fix: freeze it after the first approved shot, and only change it deliberately for the whole project at once.
Skipping the rough edit. Fix: assemble a cut with music before generating more. You will discover which shots you actually need.
Too many wide shots. Fix: think in close-ups, inserts, and details. Faces and hands are more believable than full-body motion.
No sound plan. Fix: decide narration, ambience, and music before the final generation pass so pacing matches.
No record of what worked. Fix: keep prompts, seeds, model names, and reference images in a project file. Recreating a shot from memory rarely works.
Ignoring usage terms and disclosure rules. Fix: confirm commercial usage rights for every model and voice you use, and check synthetic media disclosure requirements in your market.
Quality control checklist before publishing
Run this in order, before export:
- Watch the whole piece at normal speed with sound, then muted. Both versions should hold attention.
- Check character continuity shot by shot: hair, wardrobe, age, hands.
- Check location continuity: light direction, wall color, props.
- Check motion plausibility: no sliding feet, morphing objects, or extra fingers.
- Check audio sync, loudness consistency, and that narration sits above the mix.
- Check text legibility on a phone at arm's length.
- Check the first two seconds. If the hook is unclear, fix it there rather than in the middle.
- Check exports: aspect ratio, bitrate, frame rate, captions burned in or uploaded.
FAQ
How long does a one-minute generated video take? Plan two to six hours for a polished minute once your workflow is established. Most of that time goes to regeneration, sound, and editing rather than initial generation.
Do I need more than one model? Most creators keep two: one for realistic, controllable shots and one for stylized or fast iteration. Matching the model to the shot is faster than forcing one tool to do everything.
How do I stop faces from changing between shots? Start from a fixed reference image, describe the character identically every time, keep clips short, and favor medium and close framing. If a face still drifts, replace the shot with an insert, a reaction, or a silhouette.
Is vertical video worth the trouble? Yes, if that is where your audience is. Compose for a tall frame from the start, keep subjects centered with headroom, and burn in captions — most vertical viewing happens muted. Re-framing horizontal generations wastes detail.
How much should I rely on upscaling? Treat it as final polish, not rescue. If the motion is broken or the composition is wrong, upscaling makes it bigger, not better.
Where should a beginner start? Pick one thirty-second scene with two shots and no dialogue. Take it through all five pipeline stages. You will learn more from finishing one small piece than from generating fifty clips.
Putting the pipeline to work
The shift from filming to generating does not remove craft; it relocates it. Story still decides whether anyone watches. Rhythm still decides whether they stay. The difference is that your hours now go into decisions instead of logistics, and decisions scale.
Build the habit of working in stages: script, shot list, style lock, generation passes, finish. Keep a prompt log. Keep reference images. Keep one movement per shot. Treat sound as part of the plan rather than an afterthought. Do that, and the models stop behaving like a slot machine and start behaving like a crew that needs clear direction.
