
Why Visual Consistency Decides Whether an AI Video Works
Ask any editor who has assembled a long-form piece from generated clips what the hardest part was, and the answer is rarely the quality of any single shot. It is the moment the hero's jacket changes from charcoal to navy between two cuts, or when a character's face subtly shifts shape three seconds after the camera moves. Audiences forgive imperfect rendering. They do not forgive a story that appears to be about a different person every twelve seconds.
Consistency is not a cosmetic detail. It is the load-bearing wall of narrative video. When a viewer's brain registers that a person, place, or object has changed without a story reason, attention splits: half of the audience is following the plot, and half is quietly cataloguing errors. That split is fatal for short-form brand films, explainer videos, serialized social content, and anything with a recurring character.
So the practical question is not "which generator makes the prettiest frame?" It is "which workflow keeps a cast of characters, a set of locations, and a visual language stable across 40 shots, two rounds of revisions, and three different editors?" That question is answerable, and the answer has very little to do with luck.
This guide walks through a repeatable text-to-video production method: how to build references before you generate, how to structure prompts that stay on-model, how to condition a model with multiple reference images, how to run quality control at scale, and how to choose between different model families when a shot demands something specific. Treat it as a production handbook rather than a list of tricks.
How Modern Text-to-Video Pipelines Actually Work
Before optimizing anything, it helps to know which stage of the pipeline is responsible for which kind of failure. Most consistency problems are traceable to a specific stage, and each stage has a different remedy.
From prompt to latent space
Text encoders convert your written prompt into a numerical representation. That representation guides a diffusion or transformer-based generator through a series of denoising steps in a compressed "latent" space. Text alone gives the model broad creative latitude, which is why two runs of the same prompt produce two different characters. The moment you add image references, you constrain a large part of that latitude. Most modern systems accept one or several reference images, and the number you supply changes how strongly the output is anchored.
Temporal coherence and motion priors
The model must also decide how pixels should move. Some systems predict motion implicitly inside a single generation pass; others generate keyframes and interpolate between them. Either way, the model applies learned "motion priors" — assumptions about how hair, fabric, smoke, and human limbs typically behave. These priors are excellent at natural movement and terrible at unusual choreography. If you ask for something the priors have not seen, you get warping, melting, or an unintended camera move.
Post-generation refinement
Upscaling, frame interpolation, color grading, and compositing all happen after the model is done. This is where you can rescue a slightly soft shot — but this stage cannot fix an identity change. If a face does not match across cuts, no amount of sharpening will save it. That is why reference discipline happens upstream, not in the edit suite.
Building a Reference Kit Before You Generate Anything
Amateur workflows start with a prompt. Professional workflows start with a folder. A reference kit is the small set of images, descriptions, and rules that every prompt will point back to. Build it once, reuse it for the entire project.
Character reference sheets
For every recurring character, collect four to six images that cover the essentials: a clean front-facing portrait, a three-quarter view, a profile, a full-body shot showing wardrobe silhouette, and at least one image under the lighting condition you plan to use most often. Angles matter more than beauty. A stunning portrait shot from an unusable angle is less useful than a plain shot that reveals jawline, hairline, and shoulder width.
Add a short written spec for each character: hair color and texture, eye color, distinguishing marks, wardrobe items, and any prop they always carry. Written specs are what let a different team member reproduce your result months later.
Location and prop locks
Locations drift just as characters do, and the drift is easier to miss because viewers have fewer anchors. Lock down architecture before production: which side of the room the window is on, what the floor material looks like, whether the door is on the left or right. Prop locks matter for anything that recurs — a phone model, a book cover, a vehicle. Generate a clean "establishing" reference for each set and keep it in the kit.
Style anchors
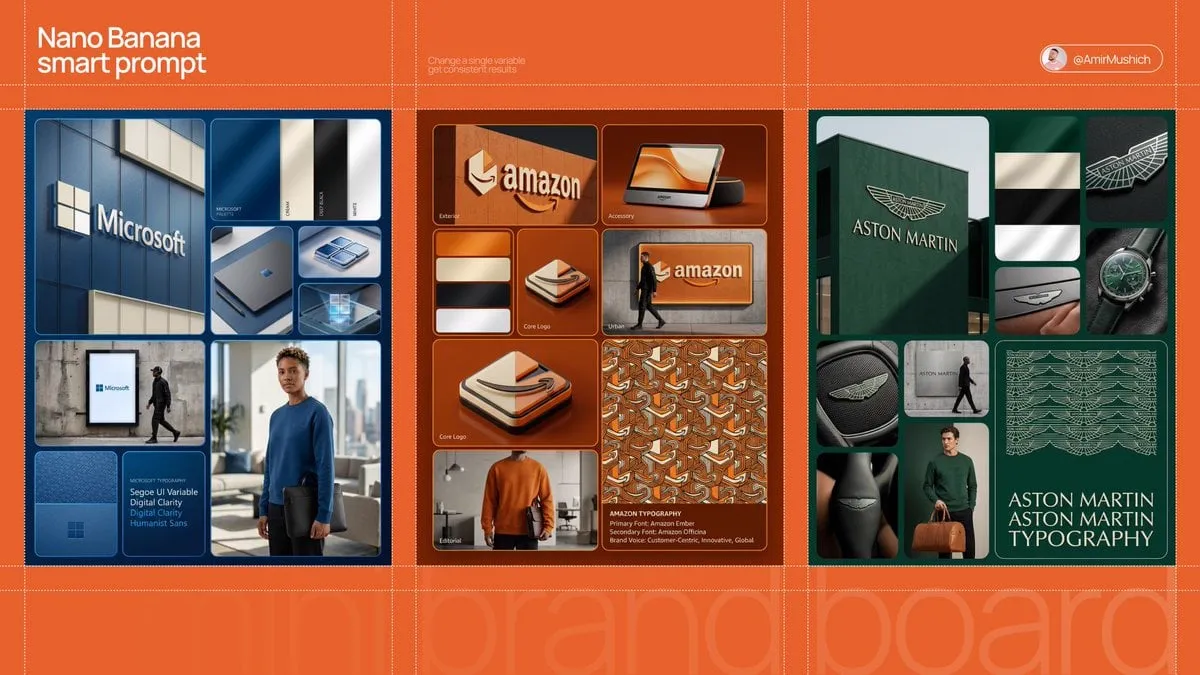
Style is the third axis of consistency: color palette, contrast, grain, lens character, and animation language. Choose two or three images that represent your target look — they can be frames you generated, stills you admire, or concept art — and treat them as fixed references for every prompt. Without style anchors, individual shots will be technically correct and collectively incoherent.
From Script to Shot List: Prompts That Stay On-Model
The bridge between a script and a generated shot is the shot list. A good shot list converts narrative intent into structured, repeatable prompt blocks.
The four-part prompt formula
Write every prompt in four parts, in the same order, every time:
- Subject block — who or what, described in the exact wording of your character spec.
- Action block — a single, clear motion verb with a duration hint. One action per shot.
- Environment block — location, time of day, weather, and the lighting reference.
- Camera block — shot size, angle, lens feel, and movement.
Keeping the order fixed makes prompts comparable across a project and makes debugging trivial: if a shot fails, you can isolate which block caused it.
Camera and lens language
Vague camera words produce vague results. "Cinematic" tells the model almost nothing. "Slow dolly-in, 50mm, shallow depth of field, eye level" tells it a great deal. Use a small vocabulary of camera terms and reuse them: slow push-in, lateral tracking shot, static medium close-up, handheld follow, crane rise. Reusing a limited vocabulary itself improves consistency, because the model's behavior becomes predictable.
Prompt hygiene
Three rules prevent most prompt-related drift. First, never contradict yourself — asking for both "soft diffused light" and "harsh sunlight" produces an average of the two, which reads as neither. Second, avoid stacking more than two or three descriptors per noun. Third, keep a canonical spelling for every proper noun in the project glossary and copy-paste it rather than retyping it.
Reference Conditioning and Multi-Image Fusion in Practice
Reference conditioning is where consistency is actually won. The principle is straightforward: instead of describing a character in words and hoping, you show the model the character and ask it to preserve identity while changing pose, angle, and action.
Single reference versus multi-image conditioning
A single reference image is fast and cheap and works well for simple, near-identical shots. It struggles the moment you need a new angle or a different expression, because the model has only one view to extrapolate from. Supplying multiple references — face, wardrobe, full body, plus a style image — gives the model enough information to hold identity through significant pose changes. This multi-image approach is the single biggest quality jump available in most text-to-video pipelines, and it is worth the extra setup time on any project with recurring characters.
Weighting references
When a system lets you influence how strongly each reference applies, use it deliberately. A face reference should carry more weight than a background reference. A style reference should carry enough weight to unify color and grain without overriding wardrobe details. If a character starts looking generic, raise the face weight. If the output becomes rigid and lifeless, lower it slightly and add textual energy instead.
Practical guardrails
Use reference images that are clean, well lit, and free of clutter. Crop out competing subjects. Avoid references with heavy filters, because the model will faithfully reproduce the filter as part of the character's identity. And always test a new reference kit on three quick shots before committing to a full batch — a bad kit multiplied across forty generations is an expensive lesson.
Continuity Across Shots: Lighting, Camera, Wardrobe, Motion
Continuity has four dimensions, and problems in any one of them break the illusion.
Lighting continuity is the most visible. Decide early whether your project is warm and soft, cool and contrasty, or neutral and documentary. Create one prompt phrase for that look and paste it into every shot. When a scene takes place at a different time of day, change the phrase wholesale — never partially.
Camera continuity governs how the audience reads space. Establish a consistent screen direction: if the character walks left to right, keep them walking left to right until the geography changes on purpose. Keep shot sizes varied but the lens feel constant. A project shot entirely at 35mm with one 85mm close-up reads as intentional; a random mix reads as inconsistent.
Wardrobe continuity is the most error-prone dimension in generated video. Models enjoy "improving" clothing between shots. The fix is to describe wardrobe explicitly in every prompt and to include a wardrobe-focused reference image, even when the shot is a tight face close-up.
Motion continuity concerns how much movement happens and how fast. Set an energy level per scene — calm, conversational, urgent — and let the camera and action blocks reflect it. A cut from an energetic handheld shot to a completely static one will feel like a jump between two different films.
A Complete Production Workflow, Step by Step
Step 1: Pre-production and the kit
Write the script, break it into shots, and build the reference kit. Specify characters, locations, props, style, and the palette. Assign each shot an ID like S03_SH07 and store prompts in a spreadsheet or text file rather than in your head.
Step 2: Test generation
Generate one shot per character and one per location at low resolution. Review identity match, lighting match, and motion plausibility. Adjust references and prompt blocks here — changes cost minutes now and hours later.
Step 3: Batch production
Generate the full shot list. Produce two or three variations per shot where the runtime allows it; having options during the edit is worth more than saving a few minutes in generation. Keep a naming convention that ties every file to its shot ID and variation number. Log which references and prompt version produced each accepted clip.
Step 4: Assembly and sound
Edit for rhythm, then add sound design, music, and voice. Audio is a powerful continuity tool: consistent ambience and a recurring musical motif make viewers far more forgiving of small visual differences between shots. Color grade at the end, applying one look to the whole timeline.
Step 5: Archive
Save the reference kit, prompt list, and accepted clips as a project template. The second video you make in this world will take a fraction of the time, and a client who wants a follow-up will get it in days instead of weeks.
Quality Control: The Continuity Checklist
Run this checklist on every assembled cut before you send it anywhere:
- Does the character's face, hair, and skin tone match across every shot in a scene?
- Is wardrobe identical at every cut, including accessories?
- Does the light direction stay consistent within a scene?
- Does screen direction remain stable, or does it break for an intentional reason?
- Is the color palette consistent outside of deliberate scene changes?
- Do motion speed and camera energy match the scene's tone?
- Are prop details — labels, logos, screens, signage — stable and legible?
- Do hands, teeth, and eyes survive close inspection?
Track failures by category. If most of your fixes are wardrobe, strengthen the wardrobe reference. If most are lighting, tighten the lighting phrase. Patterns are cheaper to fix than individual clips.
Choosing the Right Model Family and Scaling Your Templates
Different shot types reward different model behavior, and mature workflows route shots accordingly rather than using one engine for everything.
Photorealistic models excel at human faces, skin, and natural light. They are the default for brand films, testimonials, and anything with close-up humans. Expect to rely heavily on multi-image conditioning here.
Stylized and illustrative models handle strong art direction, animation-adjacent looks, and graphic worlds. They tolerate looser references but demand a strict style anchor, since their internal style is more opinionated.
Motion-heavy models are built for dynamic camera work — chases, sports, dance, action. Their strength is movement; their weakness is facial detail, so save them for wide and medium shots.
Fast iteration models are low-resolution and quick, and their real value is exploration: testing a look, a camera move, or a costume before committing to a slower, higher-quality pass.
Match the model to the shot, not the other way around. A single scene can legitimately use three different engines, as long as the style anchor and grading keep the result unified.
Scale comes from templating. Build a prompt template with fixed blocks and variable fields, save a reference kit per character and per location, and document your naming conventions. Once that exists, adding a new scene is a matter of filling in fields rather than starting over. Common mistakes at this stage include skipping test generations to save time, changing references mid-project without telling collaborators, and letting each editor invent their own prompt wording. All three destroy consistency faster than any model limitation.
Frequently Asked Questions
How many reference images do I actually need per character?
Four to six is the sweet spot. Fewer than three makes new angles unreliable; more than eight rarely improves output and slows down your process.
Why does my character look right in wide shots and wrong in close-ups?
Close-ups expose facial detail that wide shots hide. Add a dedicated face reference at high resolution and increase its influence, then re-test before regenerating the whole scene.
Can I fix an inconsistent shot in post-production?
Small issues like color and grain mismatch, yes. Identity changes, no. Regenerate the shot with better references — it is almost always faster than rotoscoping or face replacement.
How do I keep style consistent across different model families?
Use one style anchor image plus a fixed color-grading pass applied to the entire timeline. Grade after assembly, never per clip, so the whole piece shares one look.
What is the biggest beginner mistake?
Generating a full shot list before testing the reference kit. Three quick test shots will save you dozens of wasted generations.
How do I keep a long-running project consistent months later?
Archive the reference kit, the prompt template, the model settings, and the grading settings together. A project is only as reusable as its documentation.
Consistency is not a feature you switch on; it is a discipline you build into the pipeline. Lock your references, structure your prompts, test before you scale, and review against a checklist. Do that, and the technology stops being a slot machine and starts behaving like a studio tool.
