
Why AI video has become a normal part of production
A few years ago, generating a moving image from a sentence felt like a party trick. Today it is a routine step in real production pipelines. Ad agencies build concept animatics before a camera ever leaves the case. YouTube creators prototype intros in an afternoon. Product teams turn a static render into a looping hero clip for a landing page. Educators illustrate abstract ideas without booking a studio. The technology did not replace filmmakers; it compressed the distance between an idea and something you can actually watch.
The practical consequence is that video work now happens in two directions at once. You can start from language and describe a scene, or you can start from a still image and ask a model to bring it to life. Those two paths, text-to-video and image-to-video, behave very differently. They fail in different ways, they reward different kinds of planning, and they fit different stages of a project. Teams that understand the difference ship faster and waste far less time regenerating shots that were never going to work.
This guide walks through a complete workflow: choosing your starting point, planning shots, writing prompts that read like camera directions, holding visual consistency across a sequence, controlling motion, handling audio, finishing in the edit, and running a quality check before anything goes public. It is tool-agnostic on purpose. The names of the current leading models change every few months, but the workflow underneath them is stable.
Text-to-video vs image-to-video: choosing the right starting point
The first decision in any AI video project is where the pixels come from. Both approaches generate motion, but they place control in different hands.
When text prompts are the better fit
Text-to-video is unbeatable for exploration. You have a concept, not an asset. You want to see five interpretations of "a lone lighthouse in heavy fog, slow push-in, cinematic" before committing to an art direction. Text generation is also the right choice when the subject does not exist yet in any form: an impossible landscape, a stylized character, a surreal transition between two worlds.
The trade-off is variance. Each generation is a fresh roll of the dice, and small wording changes can move the result dramatically. If a client has approved a specific look, pure text prompting makes it hard to reproduce that look on demand.
When a still image should seed the shot
Image-to-video takes an existing frame and animates it. That frame can come from a photo shoot, a 3D render, a hand-drawn storyboard, or a text-to-image model. Because composition, color, and subject identity are already locked, the model only has to solve motion. That is a much smaller problem, and it usually produces a more controlled result.
Use image-to-video when:
- A character must look the same across multiple shots.
- A product shot must match an approved render exactly.
- You are animating a storyboard panel to test pacing.
- You need a specific composition that text prompting keeps missing.
- You are extending an existing live-action plate.
Hybrid pipelines are the norm
Most real projects mix both. A common pattern: generate a wide establishing shot with text-to-video to find the mood, then generate a keyframe with a text-to-image model, refine it in an image editor, and animate that keyframe with image-to-video for the hero shots. The first pass is cheap exploration; the second pass is controlled execution.
A second pattern works in reverse. Animate a still with image-to-video, pull the best frame out of the result, and use that frame as the seed for the next shot. This is how you build a sequence that feels like one continuous world rather than a slideshow of unrelated clips.
Step 1: Build a shot list before you open any tool
The single biggest time saver in AI video work is a shot list written before any generation begins. Without one, you generate attractive clips that do not cut together.
A usable shot list has one row per shot and at least these columns:
- Shot number – matches your edit timeline naming.
- Duration – target seconds, usually 3–8 for AI-generated footage.
- Shot size – wide, medium, close-up, insert.
- Subject and action – who does what, in one sentence.
- Camera movement – static, push in, pull out, pan, orbit, handheld.
- Lighting and time of day – overcast, golden hour, hard noon, practical neon.
- Source method – text-to-video, image-to-video, or live action.
- Audio note – dialogue, ambience, or music-only.
Two habits make this list far more useful. First, write the action as a single dominant movement per shot. Models handle one clear motion well and multiple simultaneous motions poorly. Second, decide the camera movement before you generate, not after. If you discover the movement while reviewing outputs, you will end up rebuilding the sequence around whatever the model happened to do.
For a 30-second promo, a realistic shot list runs 6 to 10 shots. For a 90-second explainer, expect 20 to 30. Budget roughly three to five generations per shot for text-to-video and one to three for image-to-video seeded from a good keyframe.
Step 2: Write prompts that behave like camera directions
A prompt is not a wish. It is a compact technical brief. The most reliable prompts share a consistent internal order, so that you can change one variable at a time when iterating.
Subject, action, camera, light, texture
A dependable template looks like this:
[shot size] of [subject with two or three concrete visual traits], [single action in present tense], [camera movement and speed], [lighting and time of day], [lens and film texture], [color palette]
An example: "Medium close-up of a woman in her sixties with short silver hair and a wool coat, turning slowly to look over her shoulder, camera pushes in gently, overcast winter daylight, 50mm lens with soft grain, muted blue and grey palette."
Notice what is doing the work. The shot size sets framing. The traits set identity. The action is singular. The camera instruction is explicit. The lighting removes ambiguity. The lens and texture references push the result away from the default glossy look that most models drift toward.
Specificity beats adjectives
Words like "beautiful," "epic," and "stunning" carry almost no information. Replace them with observable facts:
- Instead of "dramatic lighting," write "single hard key from camera left, deep shadows, no fill."
- Instead of "futuristic city," write "wet asphalt reflecting magenta signage, cable-strung towers, low fog at street level."
- Instead of "fast motion," write "subject crosses frame left to right in under two seconds."
Keep a prompt sheet
Track every generation in a spreadsheet or a notes file with the prompt, the seed if the tool exposes one, the source image path, and a one-line verdict. When a shot finally works, you want to be able to reproduce it next week and to explain to a colleague exactly what changed.
Step 3: Lock visual consistency across a sequence
Consistency is where amateur AI sequences give themselves away. A character's jacket changes color, the architecture shifts, the lighting temperature jumps between shots. There are several practical ways to hold a look together.
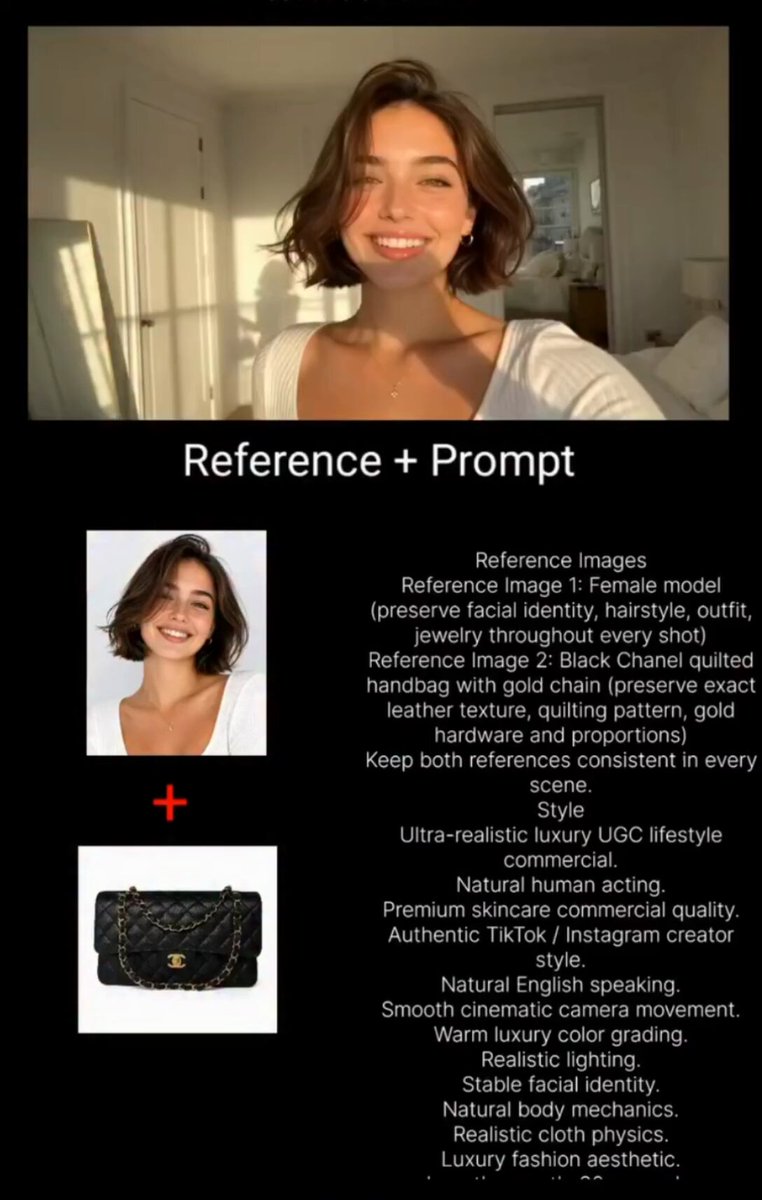
Anchor with one strong keyframe. Generate a single reference image that defines wardrobe, palette, and lighting, then derive every shot from it through an image-to-video pass. Even shots that need a different angle can start from a re-framed variant of the anchor.
Reuse texture language. Keep a fixed phrase for lens, grain, and grade, and paste it into every prompt. "35mm, fine grain, slightly desaturated teal shadows" repeated across ten prompts does more for cohesion than any single clever description.
Constrain the palette. Name two or three colors and stick to them for the whole sequence. Models respect an explicit palette far more reliably than vague mood words.
Control the environment, not the whole world. Describe the specific location traits that must repeat: the same window shape, the same floor material, the same weather. Global descriptions like "a city" invite the model to reinvent everything.
Accept controlled variation. Real footage has variation. Perfect uniformity reads as synthetic. Letting light shift slightly between wide and close shots is fine; letting a character's face change is not.
Step 4: Motion control, frame rates, and shot length
Motion is the hardest part of any generated video, and it is where most disappointing outputs originate.
Match motion to the shot's job
Slow, single-direction motion is almost always more convincing than fast, complex motion. Save rapid movement for moments where the audience will read it as energy rather than inspect it as detail. For dialogue scenes, keep the camera nearly static and let micro-movements in the subject carry the shot.
Respect the 3–8 second sweet spot
Most current models produce their most coherent output in short bursts. Long generations tend to drift: faces melt, backgrounds warp, physics loosen. Plan the edit around short clips and let pacing, not duration, create continuity. Two four-second shots cut together often feel more cinematic than one eight-second shot that sags in the middle.
Use speed and interpolation deliberately
If a shot feels slightly stiff, a modest optical-flow interpolation can smooth it — but heavy interpolation creates smeared artifacts around hands and hair. Test at low resolution before committing to a full render.
Watch the frame rate decision
Generate at the frame rate you intend to deliver, or at double it and conform down. Mixing 24fps and 30fps material in one timeline creates judder that no amount of grading will fix. Pick a base rate at the start of the project and note it in the shot list.
Step 5: Audio, dialogue, and lip sync
Audio is the fastest way to make an AI video feel finished — or obviously fake.
Voice. If a shot needs spoken dialogue, decide early whether you will generate a synthetic voice or record a human one. Synthetic voices are fine for narration and rough cuts. For anything customer-facing, a recorded performance usually reads better, and it lets you cut the visuals to the audio rather than the reverse.
Lip sync. Generate the visual with a closed-mouth or profile performance if you plan to dub later; open-mouth shots are far harder to match. Where lip sync is essential, keep the head relatively still and the shot tight, because wide shots give the sync error more visible room.
Ambience. Add a continuous background layer under every scene: room tone, distant traffic, wind. Silence between cuts is the clearest signal that a sequence was assembled from fragments.
Music. Choose or compose the track before final picture lock. Cutting picture to music yields better rhythm than dropping a track over a finished edit, and it exposes shots that are the wrong length much earlier.
Levels. Keep dialogue around −12 to −6 dBFS with music sitting several decibels beneath it during speech. A simple limiter on the master prevents the harsh clipping that generated audio sometimes carries.
Step 6: Assemble, color, and finish in the edit
By the time you reach the edit, the creative decisions should already be made. The edit is about rhythm and repair.
Organize by shot number, not by generation. Name files with the shot number and take letter. You will generate many more clips than you use, and untangling a folder of generic exports is a guaranteed afternoon lost.
Cut on motion. Trim so that movement continues across the cut: a push-in followed by a push-in, or a subject exiting frame left followed by one entering from the right. Continuous motion masks the seam between unrelated generations.
Grade for unity. A single adjustment layer with matched contrast, a shared color balance, and a subtle vignette will do more for cohesion than per-clip correction. Match your most reliable shot and pull everything toward it.
Add grain and texture. A light film grain pass softens the over-clean quality that synthetic footage often has, and it helps generated shots sit next to live-action material.
Check your exits and entrances. Review every cut at half speed once. Errors that are invisible at full speed become obvious when you slow down, and it is much cheaper to fix them before publishing than after.
Quality control checklist before you publish
Run every sequence through the same short checklist. It takes ten minutes and catches the majority of embarrassing defects.
- Faces and hands – pause on every frame where a person is prominent. Look for warping, extra fingers, or shifting features.
- Text in frame – signage, labels, and screens almost always contain garbled characters. Replace with clean graphics in the edit.
- Physics – check liquid, fabric, and reflections. Inconsistent gravity is a giveaway.
- Continuity – wardrobe, props, time of day, and weather match across cuts.
- Audio sync – dialogue matches mouth movement within a frame or two.
- Aspect ratio and safe area – titles and logos survive cropping on vertical and square formats.
- First three seconds – does the opening shot earn attention without a caption explaining it?
- Rights and likeness – every source image, voice, and music bed has a documented basis for use.
Common mistakes and how to fix them
Generating before planning. The fix is boring and effective: write the shot list first, even a rough one. Twenty minutes of planning routinely saves hours of regeneration.
Changing five prompt variables at once. When a shot fails, change one thing. Otherwise you learn nothing from the next attempt.
Chasing a perfect single shot. If a shot has failed four times, the concept is probably fighting the model. Re-frame it, change the shot size, or solve it with an insert or a graphic instead.
Ignoring the edit until the end. Test-assemble early with placeholders. Rhythm problems are creative problems, and they are much easier to fix before you have generated thirty final clips.
Over-relying on one model. Different tools handle different subjects better. Keep two or three options available and route each shot to whichever handles its content type best.
Skipping audio until the end. Bad audio makes good picture look unfinished. Build the sound bed as you go.
FAQ
How long does a typical AI video sequence take? A 30-second piece with 8 shots usually needs one to two days of focused work for someone experienced with the tools: planning, generation, selection, and a first edit. Complex character continuity or dialogue can double that.
Do I need a powerful local machine? Not necessarily. Many tools run in the browser, and local generation requires a capable GPU with substantial video memory. For most teams, hosted tools are faster to start with, while local setups win on volume and privacy.
Can AI video replace a camera crew? For abstract concepts, animatics, explainers, and social content, often yes. For documentary interviews, live performance, and anything requiring verifiable real-world capture, no. The strongest results usually combine both.
How do I keep a character consistent without training a custom model? Build one strong anchor image, derive every shot from it through image-to-video, and repeat the same texture and palette language in every prompt. That combination covers most continuity needs.
What resolution should I generate at? Generate at the largest size your tool handles reliably, then downscale for delivery. Downscaling hides small artifacts far better than upscaling invents detail.
Is generated footage safe to publish commercially? That depends on the tool's terms and the material you fed it. Read the license, avoid uploading copyrighted stills or recognizable faces without permission, and keep a record of your sources for every project.
How many takes should I expect per shot? Budget three to five for text-to-video and one to three for image-to-video from a strong keyframe. If you are consistently exceeding that, the prompt or the concept needs rework, not more attempts.
The workflow above is not glamorous, but it is what separates a demo reel from deliverable work. Plan the shots, control the starting frame, constrain the motion, build the sound, and check every cut before it ships. The models will keep improving; the discipline is what makes the output usable.
