
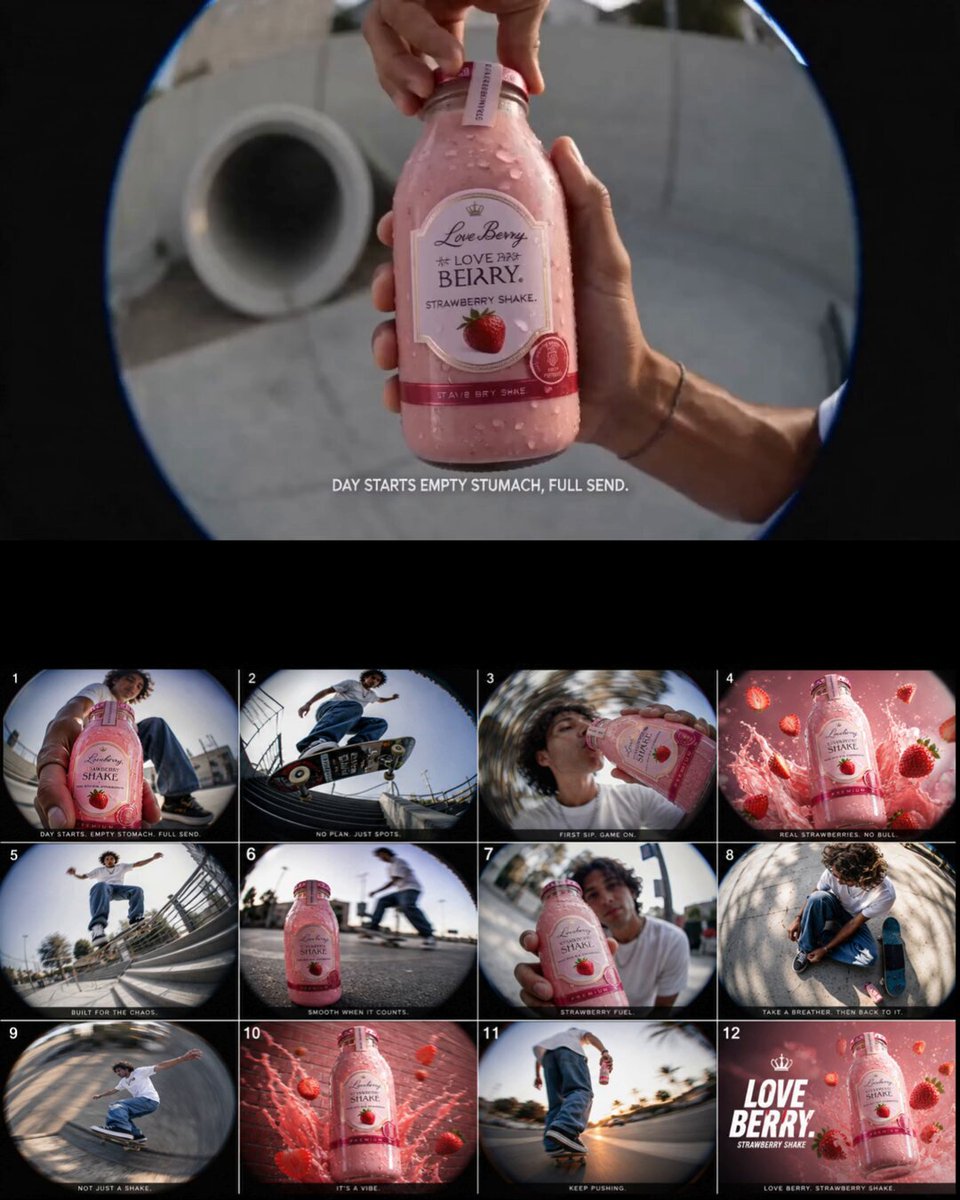

Why realism became the deciding factor in AI video
Early text-to-video tools were judged on a forgiving curve. If a clip produced a recognizable subject that did not dissolve into visual soup within four seconds, it counted as a success. That standard is gone. Generated footage now sits beside professionally shot footage in the same feed, the same ad slot, and the same client review, and viewers apply the same instant judgment to both.
Three forces pushed realism to the top of the priority list. Distribution came first: short-form platforms reward footage that reads clearly in the first second, which means clean subject separation, believable motion, and stable identity. Second came the cost of rework. A clip that looks almost right is often worse than an obviously stylized one, because it invites another round of revisions instead of a decision. Third came workflow integration. AI clips are now used as B-roll, animatics, product teasers, and localized social cutdowns, so they have to survive editing, color correction, and repeated viewing on a small screen.
The uncomfortable implication for tool enthusiasts is that model choice matters less than the process around it. A disciplined workflow on a mid-tier model beats a careless prompt on the most hyped model almost every time. The rest of this guide breaks realism into measurable parts, then builds a production process around them.
The four pillars of realistic AI video
Realism is not a single quality. Split it into four pillars and you can diagnose failures instead of guessing at them.
Pillar 1: Temporal and subject consistency
This is the pillar viewers notice first and forgive least. Consistency failures look like a face that subtly changes shape across three seconds, hands that gain or lose fingers, a jacket that shifts from navy to charcoal, background extras who melt into the wall, or a necklace that migrates across a collarbone. None of these break a shot on their own. Together they create the uncanny feeling that the footage is wrong without an obvious reason.
The fixes are mostly structural. Keep individual generations short, usually three to six seconds, and let the edit carry continuity instead of asking one render to do everything. Keep one subject per shot and avoid crowds, animals interacting with props, or two people shaking hands in tight framing. Anchor appearance in concrete, repeatable language: "same red canvas jacket, short black hair, silver hoop earrings" works far better than "stylish woman." When the model supports it, start from a still reference frame or use first-and-last-frame conditioning so the beginning and end of the motion are pinned. Finally, reuse the same seed and prompt skeleton across a sequence so the model has fewer variables to improvise with.
Pillar 2: Camera control and composition accuracy
Many clips fail not because the subject is wrong but because the camera is undefined. The model defaults to a generic drifting push that reads as amateur footage. Generated video obeys cinematic vocabulary surprisingly well, but only if you supply it. Useful terms include slow dolly in, truck left to right, crane up, orbit right, static tripod, handheld with subtle sway, 35 mm anamorphic, shallow depth of field, eye-level medium shot, low-angle wide shot, and subject on the left third with negative space on the right.
The single most effective rule is one camera move per shot. Asking for a dolly in while the camera cranes up and the subject turns produces a smeared, unreadable few seconds. Locked-off shots are the easiest to generate cleanly and the easiest to cut, so use them when the subject performance carries the scene. Move the camera only when the movement itself communicates something: revealing a product, following a walk, or building tension before a cut.
Pillar 3: Physics, lighting, and materials
This pillar separates clips that look expensive from clips that look synthetic. Physics covers cloth, hair, liquids, smoke, fire, glass, and reflections. Models handle cloth well and liquids poorly. Water pouring into a glass, coins landing on a table, or a spinning object without motion blur are still high-risk requests. If a shot depends on a physics interaction, simplify it into a shot that implies the interaction: a hand resting on a full glass rather than pouring into it, steam rising from a mug rather than a liquid splash.
Lighting is the highest-leverage fix available. Say where the light comes from, what quality it has, and what color it is. "Warm practical lamp from camera left, soft top light, cool rim light from behind, slight haze in the room" gives the model a physical scene to render. Vague wording like "cinematic lighting" produces a generic contrast curve that looks the same in every clip. Materials deserve explicit vocabulary too: brushed steel, matte ceramic, worn denim, wet asphalt with mirror reflections, frosted glass, and dusty leather all pull the render toward a specific texture rather than a plastic average.
Pillar 4: Runtime efficiency and iteration speed
The model you can run ten times in an afternoon usually wins, even if its best output is slightly behind a slower competitor. Iteration speed comes from several factors: clip length ceiling, maximum resolution, whether batch generation is available, whether a clip can be extended or must be restarted, queue latency during peak hours, and how predictably the model responds to the same seed. A tool that looks five percent better but triples your feedback loop will lose on any real deadline.
Track two numbers for every model you use: minutes per usable clip and usable clips per ten attempts. Those two figures predict your schedule far better than any leaderboard. If a shot type has a low hit rate, either change the approach or route it to a different model.
How to choose a model for a realistic shot
Stop looking for a single best model. Build a small stack and route shots by type. The criteria below cover almost every practical decision.
- Shot type and motion intensity: locked-off dialogue, product rotation, walking follow, or action beat.
- Realism profile: documentary naturalism, commercial polish, or stylized cinematic.
- Control surface: text only, image-to-video, first-and-last-frame, motion brush, camera path, or depth pass.
- Clip length and extension behavior: how long a single generation runs and whether you can continue a scene.
- Aspect ratios and resolution: vertical, square, and widescreen support without re-framing artifacts.
- Consistency tooling: reference images, character locking, seed reuse, and style presets.
- Audio: native sound generation, lip sync, or a clean export for external sound design.
- Throughput: how many usable clips you get per hour of work.
In practice, most teams end up with two or three models. Generalist cinematic models such as Kling and Sora handle polished hero shots and stylized scenes with strong motion. Control-focused editors like Runway are good for shot-level direction and cleanup passes. Image models in the Flux class are best used upstream as frame generators, because a strong reference frame eliminates half the consistency problem before generation begins. Fast multimodal models in the Vidu and PixVerse family are useful for high-volume social cutdowns and stylized sequences where turnaround matters more than photoreal detail. Luma, Pika, Hailuo/MiniMax, and Wan-class models fill specific niches, and it is worth testing one new model per quarter against your two weakest shot types.
| Shot requirement | Best fit | Why |
|---|---|---|
| Hero product shot, slow orbit | Generalist cinematic model | Strong material and light rendering |
| Talking character, tight framing | Image-to-video with reference frame | Locks identity before motion starts |
| Fast social cutdown, stylized | Fast multimodal model | Cheaper iterations, quick turnaround |
| Complex camera path | Control-focused editor | Explicit camera and motion controls |
| Establishing landscape | Any strong model, locked-off | Simple motion, forgiving physics |
A repeatable workflow from brief to finished clip
Step 1: Lock the shot list before you prompt
Write the sequence as shots, not as a paragraph. Each line should contain one subject, one action, one camera move, one location, and a duration. A thirty-second piece usually breaks into six to nine shots. This step prevents the most common beginner mistake: trying to describe an entire scene in a single prompt and getting a confused, middle-of-nothing clip as a result.
Step 2: Write prompts in layers
Build every prompt in a fixed order so you can debug one layer at a time:
- Shot size and subject
- Action, stated as a single continuous motion
- Camera move and lens
- Lighting and color
- Environment and background behavior
- Style and texture anchors
- Negative instructions: no text overlays, no extra limbs, no camera cuts
Keeping the order identical across a project means that when a clip fails, you can change one layer and know what caused the shift.
Step 3: Generate in batches and label everything
Generate four to six variants per shot with the same prompt and different seeds. Name files with the project, shot number, variant letter, and a two-word description of what changed. Unlabeled generations become unusable within a day, and teams frequently regenerate work they already own because they cannot find it.
Step 4: Screen with a five-point test
Score each variant from one to five on identity stability, motion believability, camera accuracy, lighting quality, and editability. A clip with a beautiful look but a drifting face scores low, because fixing it costs more than regenerating. Keep the top two per shot and archive the rest.
Step 5: Extend, stitch, and stabilize
Extend a clip only from a frame where the subject is centered and unobstructed. When stitching, cut on motion or on an object entering frame, and keep the camera direction consistent across the join. If a slight jitter remains, a subtle stabilization pass and a two percent speed adjustment often hide it better than another render.
Step 6: Sound design, then re-cut
Sound changes pacing decisions. Lay in ambience, foley, and music before you finalize cuts, then trim every shot to the beat of the audio rather than to its own natural length. Generated footage rarely has a strong internal rhythm, so the soundtrack has to supply it.
Prompt patterns that raise realism
These two structures cover most realistic shots and are worth adapting rather than copying.
Medium shot, single female presenter standing beside a matte ceramic bowl on a wooden counter.
Action: she slowly lifts the bowl and turns it toward camera, one continuous motion.
Camera: static tripod, 50 mm lens, shallow depth of field, subject on the left third.
Light: warm practical lamp from camera left, soft top light, cool rim light from behind.
Environment: quiet kitchen, slight steam in the background, no other people.
Style: documentary naturalism, fine grain, natural skin texture.
Avoid: text overlays, camera cuts, extra hands, warped reflections.
Wide establishing shot of a rain-soaked city street at dusk, no people in frame.
Action: rain falls steadily, a distant traffic light cycles once.
Camera: slow dolly in, 35 mm anamorphic, slight lens flare from the right.
Light: cool blue ambient with warm sodium street lamps, wet asphalt mirror reflections.
Style: cinematic naturalism, gentle film grain, deep shadows.
Avoid: moving vehicles with unreadable wheels, floating objects, flickering signage.
Notice how much of each prompt describes light and texture rather than story. Realism lives in those details. Story is carried by the edit.
Troubleshooting the most common failure modes
| Symptom | Likely cause | Fix |
|---|---|---|
| Face changes across the clip | Long generation, no reference frame | Shorten to five seconds, use image-to-video |
| Hands distort | Hands large in frame or interacting with objects | Reframe, use medium shots, hide hands |
| Motion appears to slow down and speed up | Conflicting camera and subject motion | One camera move, one action per shot |
| Everything looks plastic | No material or lighting vocabulary | Specify light source, texture, and grain |
| Background flickers | Complex environment, many elements | Simplify set, reduce extras, add haze |
| Prompt ignored in later half | Overloaded prompt | Cut to the essential layers, split the shot |
Most failures are structural, not model-specific. Before switching tools, reduce the shot to its simplest possible version and confirm the model can render that. If it can, the original prompt was overloaded. If it cannot, that is a real model limitation and a good reason to reroute the shot.
A pre-publish checklist
- Watch the clip once at full speed without pausing. If anything feels wrong, it is wrong.
- Watch it muted, then watch it on a phone at arm's length.
- Check the first and last frames for identity continuity with neighboring shots.
- Confirm the camera direction matches the shots before and after it.
- Verify skin tone, brand colors, and product details against reference stills.
- Confirm no accidental text, watermarks, or unreadable signage appears in frame.
- Check that motion blur looks natural at the cut points.
- Export at the highest resolution you will need, then downscale per platform.
FAQ
How long should a single generated clip be?
Three to six seconds for anything with a person in frame, up to ten for landscapes and product shots. Longer generations almost always drift in identity or motion. Build length through editing, not through one ambitious render.
Do better prompts really beat better models?
Up to a point. A well-structured prompt on a competent model will beat a vague prompt on a top-tier model. But no prompt fixes a model that cannot render hands, liquids, or crowds, so route those shots to a tool that handles them.
Should I generate at the highest resolution available?
Generate at a resolution that supports your delivery format with a little headroom, then upscale or downscale as needed. Very high resolutions often slow iteration enough to hurt overall quality, because you get fewer attempts per hour.
How many variants should I generate per shot?
Four to six. Fewer and you accept a weak take; more and you spend time screening instead of improving the prompt. If none of six variations work, the prompt, not the seed, is the problem.
How do I keep a character consistent across an entire sequence?
Create a clean reference still first, use image-to-video for every shot featuring that character, keep framing tight, reuse the same seed family, and describe wardrobe in identical words every time. Consistency is a production discipline more than a model feature.
When should I stop iterating?
When a clip passes the five-point screen and survives a muted phone-screen viewing. Further tweaks usually produce diminishing returns, and a fresh shot list will improve the final piece more than a seventh version of the same clip.
Key takeaways
- Realism breaks into four testable pillars: consistency, camera control, physics and lighting, and iteration speed.
- One subject, one action, and one camera move per shot is the highest-value rule in the entire workflow.
- Light source, direction, quality, and color temperature do more for perceived realism than any style keyword.
- Route shots by type across two or three models instead of searching for one perfect tool.
- Generate in labeled batches, screen against a fixed rubric, and let the edit and sound design carry continuity.
- Measure minutes per usable clip and hit rate per ten attempts; those numbers decide your schedule.
