
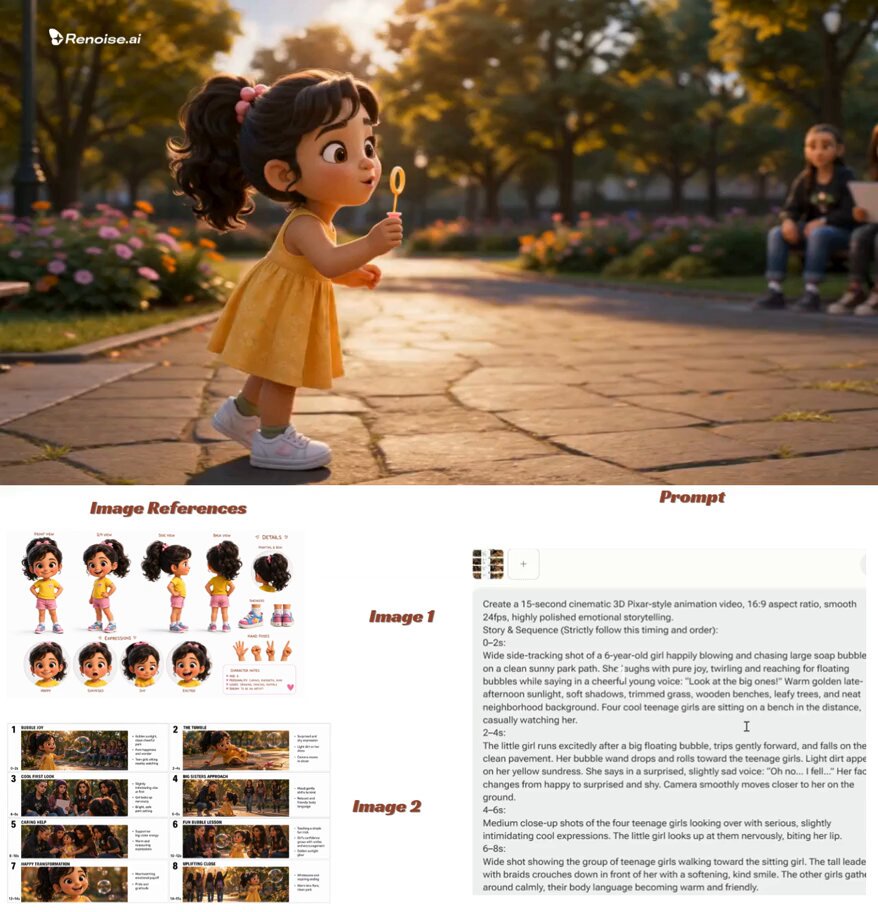
Turning a script into moving images used to require a camera, a crew, permits, and weeks of scheduling. Text-to-video models compress that work into a tight loop of writing, generating, reviewing, and editing — but they do not remove craft. The creators who get cinematic results treat generation as one stage inside a production pipeline rather than a magic button that replaces one.
This guide walks through that pipeline from start to finish: choosing a model that matches your narrative style, writing shot prompts that behave like direction, keeping characters and locations stable across dozens of clips, and finishing a sequence with sound and pacing that make it feel deliberate rather than assembled from lucky accidents.
What text-to-video tools actually do well
Text-to-video models are exceptional at a specific class of shot: one subject, one clear action, one defined camera move, and one coherent light source. A figure walking through neon rain, a drone glide along a coastline at dawn, a product rotating on a turntable — these clips read as expensive footage because the model only has to solve a single visual problem at a time.
They struggle with a predictable set of things. Multi-character scenes with physical contact break down fast. Hands and fingers still drift. Rendered text, logos, and signage come out garbled, which is why most professionals overlay titles in an editor instead of asking the model for a caption. Long uninterrupted takes lose coherence after the first few seconds as the model's memory of the frame fades. Precise choreography, sports mechanics, and dance are hit-or-miss. And continuity across a cut — the same jacket, the same coffee cup position, the same time of day — has to be engineered rather than assumed.
The practical consequence is simple: plan in shots, not scenes. A scene is a narrative unit; a shot is a generation unit. If you sketch your scene as five or six short, purpose-built shots, you give the model tractable problems and give yourself edit points when a clip goes wrong.
It also helps to accept that the model does not know your story. It knows your prompt and the pixels it just produced. Every piece of narrative context you leave out of the prompt is context the model invents for you, usually badly.
Choosing a generation model for your narrative style
The foundation model you pick shapes the visual identity of your film more than any other single decision. Reality and style are not on a single quality scale — they are different tools for different jobs.
Realism versus stylization
If your goal is documentary texture, brand films, or anything meant to read as captured footage, favor models tuned for photoreal skin, natural optics, and believable handheld motion. Sora, Veo, Kling, and Runway's flagship models all sit in this family, with different personalities: some favor cinematic depth of field, others favor crisp, phone-camera realism.
If your goal is illustration, anime, painterly fantasy, or a graphic, motion-design look, look for models that handle stylized rendering without smearing line work. Animated styles hide a lot of realism errors, which is one reason explainer videos and children's content are such good fits for text-to-video: a slightly odd elbow does not break the illusion when everything is already stylized.
Motion complexity and shot length
Different models tolerate different amounts of movement. Some handle a single slow dolly beautifully but fall apart during a fast whip pan. Others are built for dynamic action and lose subtlety in quiet, static frames.
Test each candidate model on the hardest shot in your project before you commit. Generate the same prompt three times and compare: subject stability, background drift, edge warping, and whether the motion completes the action you asked for. Ten minutes of testing saves hours of re-rendering later.
Audio, dialogue, and lip sync
Some models output synchronized audio, dialogue, and ambient sound directly. That is transformative for talking-head explainers and short character beats, but it also locks your edit to the generated performance. When you need precise line readings, record voice separately and animate to the audio rather than the other way around.
Matching the model to the project
A quick rule set: locked-off product shots and interior dialogue favor realism-first models; sweeping establishing shots favor models with strong camera-move control; montage-heavy social edits favor fast, cheap iterations; stylized sequences favor animation-capable models. Many teams keep two or three models in rotation and route each shot to whichever handles it best. Diversity of output is a feature, not indecision.
Prompting like a director, not a describer
The most common failure mode is descriptive prompting: "a sad man in a city." That produces a stock image that happens to move. Directional prompting produces a shot.
The five-part shot prompt
Build every prompt from five blocks, in this order:
- Subject — who or what, with specific, casting-relevant detail: age range, wardrobe, hair, distinguishing features.
- Action — one measurable verb in present tense: she lifts the envelope, he turns toward the window.
- Camera — shot size, angle, and movement: medium close-up, slight low angle, slow push in.
- Light and atmosphere — source, direction, color, weather, air quality.
- Style and format — lens character, film grain, aspect ratio, reference genre.
A finished example: "A woman in her thirties with short dark curls and a charcoal wool coat lifts a sealed envelope from a mailbox, medium close-up, slight low angle, slow push in, overcast morning light with soft blue shadow, 35mm film look, shallow depth of field, 16:9."
Camera, lens, and lighting language
Vocabulary does real work here. "Slow dolly in," "handheld follow," "static wide," "crane up," and "orbit left" are instructions the model can act on. So are lens terms — 24mm for environmental scale, 50mm for neutral, 85mm for flattering isolation, macro for texture. Lighting terms matter just as much: golden hour backlight, top-light through blinds, practical neon from screen left, hard midday sun with deep shadows.
Avoid stacking contradictory instructions. "Handheld drone orbit with locked-off stability" gives the model nothing to resolve. Pick one intention per shot.
Negative constraints and iteration discipline
Most interfaces accept some form of exclusion. Useful exclusions include text overlays, watermarks, extra limbs, distorted faces, lens flares, and abrupt cuts. Keep the list short — long negative lists tend to degrade overall image quality.
Then adopt a reroll policy and stick to it: generate three or four variations per shot, review them against the shot list, keep one, and move on. Endless rerolling is the single largest source of wasted time in AI video production. If a shot fails four times, the prompt is wrong, not unlucky — rewrite the action, simplify the camera, or split the shot in two.
Structuring a story across multiple shots
Narrative coherence does not come from any individual clip. It comes from how clips are sequenced and what they imply between each other.
From beat sheet to shot list
Start with a beat sheet: the emotional turns of the story in plain sentences. Then convert each beat into one to three shots. As a sizing guide, a 30-second explainer usually needs 8 to 12 shots, a 60-second brand film 15 to 20, and a 90-second narrative short 25 to 35. Anything longer should be built in episodes.
For each shot, record: duration, subject, action, camera, and the transition into the next shot. This document is your production plan — and your prompt library.
The continuity bible
Write a short reference document describing your characters, locations, palette, and time of day. Include the exact phrases you will reuse for each element. Reusing identical wording across prompts is one of the cheapest consistency tricks available: identical description text biases the model toward identical visual interpretation.
Pacing and cut rhythm
AI clips tend to feel slow because each one completes a motion. Counteract that in the edit. Cut on movement, cut before the action finishes, and vary shot length deliberately — two seconds, two seconds, five seconds, one second. Insert close-up inserts (a hand, an eye, a screen) as connective tissue; they are easy to generate reliably and they carry emotional weight.
Keeping characters and worlds consistent
The most technically demanding part of AI video is continuity. There are four levers worth pulling.
Identity references
Whenever the platform supports it, drive character shots from a reference image rather than text alone. Generate a clean, well-lit portrait first, then use image-to-video or a character-reference feature for every subsequent shot. Where available, lock the seed and keep prompt structure identical between shots so only the action and camera change.
For recurring characters in a large project, training a small style or character adapter on a set of consistent images gives the strongest identity lock. It costs setup time and pays it back across every shot.
World-building rules
Write explicit visual rules for each location and follow them: architecture style, dominant colors, weather state, time of day, signage, and props. If a hallway is fluorescent green in shot one, it must be fluorescent green in shot nine. Environment drift is the fastest way to make a sequence look like unrelated stock footage stitched together.
Wardrobe, props, and hands
Limit costume changes to story beats you can motivate. Keep hero props simple in shape and color; complex jewelry, patterned fabrics, and reflective accessories wobble between shots. Frame hands at a distance or partly out of frame — a close-up of fingers is still a coin flip.
Fixing drift in post
When a character's face shifts slightly, subtle tools help more than regeneration: a light color-match to a hero frame, a stabilized crop, or a short reframe that keeps the character large in frame where small differences are less visible. Cutting on motion a few frames earlier than instinct suggests also hides continuity gaps remarkably well.
From raw clips to a finished sequence
Generation is roughly a third of the work. The rest happens in the edit.
Assembly
Import every keeper into a timeline in shot-list order. Watch it once without fixing anything. Then trim: most generated clips have dead frames at the head and tail, and cutting 6 to 10 frames from each end tightens the whole piece dramatically.
Sound design and music
Sound is the fastest credibility upgrade available. Lay in ambience for every environment — room tone, street air, wind, hum — then add spot effects that match on-screen actions. Choose music after the picture lock, not before, so the cut drives the score instead of the reverse.
Voice, dialogue, and captions
Record narration in a treated space or use a dedicated speech synthesis tool for consistent tone. Keep one narrator voice across the project. Burn in captions for social cuts, and export a subtitle file for platform-native display. Add titles, lower thirds, and end cards in the editor, never in the generation prompt.
Grade, then export
A single shared grade — slight contrast curve, unified white balance, consistent grain — makes clips from different models look like one film. Export masters at your target resolutions and aspect ratios, and keep a textless version for localization.
A repeatable end-to-end workflow
- Write the logline and beat sheet. One paragraph, then six to ten beats.
- Convert beats into a shot list with duration, action, camera, and transition.
- Build the continuity bible with reusable description phrases and visual rules.
- Test three candidate models on your hardest shot before committing.
- Generate hero frames for characters and key locations; approve them before animation.
- Produce shots in batches of three to four variations, keeping one per shot.
- Assemble a rough cut with placeholder audio to validate pacing early.
- Record narration and design sound, then lock picture.
- Grade, caption, export, and archive prompts and seeds alongside the project files.
That last step matters more than it sounds. Saving the exact prompt, seed, model version, and settings for each approved shot turns a one-off project into a reusable production system.
Common mistakes and how to avoid them
- Prompting a scene instead of a shot. If the prompt contains "then" or two camera moves, split it into two shots.
- Chasing perfection on one clip. Four attempts is the ceiling; fix the prompt instead of rerolling.
- Ignoring the edit until the end. Assemble a rough cut at 30 percent completion to catch pacing problems early.
- Mixing styles casually. Two photoreal models with different color science will look mismatched until a unifying grade fixes them.
- Neglecting sound. Silent AI video feels synthetic; sound design is what sells the realism.
- Forgetting continuity documentation. Without a bible, consistency decays across every session.
- Generating text in-frame. Overlay it in post where you control typography.
Quality checklist before you publish
Run this pass on every finished piece: the first three seconds contain a clear hook; every clip is trimmed of dead frames; no frame shows distorted hands or faces; color and grain are consistent end to end; audio levels sit in a normal broadcast range with music ducked under narration; captions match the spoken track exactly; and the ending includes one clear action or call to action.
If a shot makes you wince, cut it. Shortening a weak sequence almost always improves it, and AI video gives you cheap replacements — the constraint is judgment, not footage.
FAQ
How long should each generated clip be?
Generate five to ten seconds and cut to two to five seconds in the edit. Longer generations tend to drift, and shorter trims give you flexibility when pacing changes.
Do I need a paid plan for professional work?
Most serious pipelines use at least one higher-tier plan for higher resolution, faster queues, and commercial usage terms. Check each provider's licensing before client delivery — that detail matters more than render speed.
Can I use text-to-video for a talking-head explainer?
Yes, and it works best when you record the script first, then animate to the audio. Models with native dialogue output are an option, but separate recording gives you editorial control over every pause.
How do I keep the same character across twenty shots?
Use a reference image for every shot, reuse identical description text, lock seeds where supported, and keep wardrobe and lighting stable. Accept small variations and unify them with a shared grade.
What resolution should I target?
Generate at the highest resolution you can afford, then deliver at 1080p for web, 1080x1920 for vertical social, and 4K only when a client explicitly requires it. Upscaling tools close most of the remaining gap.
Is text-to-video replacing traditional filming?
It replaces certain categories of shot — establishing footage, abstract sequences, stylized inserts, and anything impossible to shoot practically. Live-action remains better for performance, dialogue, and complex physical interaction. Most strong work now blends both.
How do I avoid looking like everyone else's AI video?
Write your own shot list, pick a specific palette and lens character, and cut faster than the default clip length encourages. Distinctive choices in pacing and framing do more for originality than any single model upgrade.
