
Why Custom Video Models Change the Production Workflow
Generic text-to-video tools are extraordinary at producing one striking shot and surprisingly bad at producing the second one. The character's jawline drifts, the jacket changes from charcoal to navy, the alley behind them rearranges itself between cuts. This is not a bug in any single tool; it is structural. A general model is optimized for plausibility across everything it has ever seen, so nothing in particular stays stable.
Training a custom model flips that equation. Instead of re-describing your hero in every prompt and hoping the sampler cooperates, you teach the model once, then invoke that knowledge with a short trigger phrase. The result is not just prettier output, it is a different kind of production. Shots that used to require a dozen rerolls now land in two or three attempts. Sequences that used to read as a slideshow of unrelated clips start to feel like footage from a single shoot.
This guide walks through the whole pipeline in practical terms: what a training run actually consists of, how to build a dataset that teaches the model something useful, how to choose between lightweight adapters and heavier fine-tunes, how to keep characters and props consistent across dozens of shots, and how to fold all of it into a repeatable workflow you can run again next week.
If you are a solo creator, a small studio, or a branded-content team, the value is the same: you stop renting consistency from a prompt and start owning it in a model file.
The Anatomy of a Video Model Training Pipeline
Every custom video model, whether it is a tiny style adapter or a full fine-tune, moves through the same five stages. Understanding them separately makes debugging far easier, because most disappointing results come from stage one or three, not from the training loop itself.
Stage 1 — Data collection
You gather 20 to 200 short clips or high-quality stills that represent what you want the model to learn: a face, a costume, a product, a rendering style, a specific lighting setup. For video, clips of two to six seconds are usually better than long takes, because they give the trainer more distinct moments per unit of storage.
Stage 2 — Cleaning and curation
You strip the dataset to only examples you would be happy to show a client. Blurry frames, motion-blurred hands, inconsistent white balance, and half-cropped subjects all get deleted. Curation is tedious and it is the single highest-leverage hour you will spend.
Stage 3 — Captioning
Each example gets a text description. Captions are how the model learns which words map to which visual features. If every caption mentions "cinematic lighting," the model will fuse that phrase into your character instead of treating it as a separate, controllable variable.
Stage 4 — Training
You run the trainer for a set number of steps at a chosen learning rate, saving checkpoints along the way. This is mostly waiting, punctuated by occasional judgment calls.
Stage 5 — Evaluation
You generate a fixed battery of test prompts across every checkpoint and compare them side by side. The best-looking single sample is almost never the best checkpoint; the best checkpoint is the one that holds up across the whole test set.
Building a Dataset That Actually Teaches Something
The instinct when starting out is to gather as much material as possible. In practice, variety in framing matters far more than raw volume, and discipline in captioning matters more than both.
Shot selection: variety beats volume
A useful dataset covers the subject from multiple angles (front, three-quarter, profile, back), in multiple lighting conditions (soft daylight, harsh sun, indoor practicals, low key), and at multiple distances (close-up, medium, wide). If your dataset is forty near-identical portraits taken in one room, your model will learn that room and that lighting far more strongly than the person in it.
Aim for balance instead of abundance. Eighteen to thirty well-chosen examples frequently outperform a hundred redundant ones, and they train faster.
Caption structure that conditions well
Write captions in a consistent order so the model can parse them structurally. A reliable pattern is: subject trigger, appearance details, action, environment, lighting, camera. Keep anything you want to control later out of the trigger token. If you write "a soft-spoken archivist named Rin with silver hair," then you have accidentally made personality and hair color inseparable from the name. Better to reserve the trigger for identity and describe mood, wardrobe, and setting as separate phrases you can swap.
Also vary the non-essential words. If every caption says "standing," the model will refuse to sit. If every caption is a medium shot, wide shots will fight you.
Consent, licensing, and likeness
Training on a real person's face without permission is a legal and ethical problem regardless of how the output is used. Use your own likeness, licensed performers with signed releases, or synthetic identities you design yourself. For branded work, confirm that you have the rights to any product imagery or logo you train on. Building a small documentation habit here — a folder with releases and asset provenance — will save you a painful conversation later.
Choosing a Training Approach: Adapters, LoRA, and Full Fine-Tunes
There is a spectrum of customization, and picking the wrong rung wastes either time or quality.
Reference-image conditioning requires no training at all. You supply one or more reference images at generation time and the model tries to carry them forward. It is fast, cheap, and ideal for one-off shots or early exploration. Its weakness is that fidelity decays over long sequences and it cannot encode anything the reference images do not show.
Adapters and LoRA-style tuning train a small set of additional weights that modify the base model's behavior. You get real, persistent learning — a trigger word that reliably produces your character — at a fraction of the cost and time of a full fine-tune. For most creators this is the right default. A LoRA trained on 20 to 40 curated examples can be produced in a single sitting and iterated on the same day.
Full fine-tunes update the entire model. They can capture a distinct visual language that adapters struggle with, but they demand more data, more compute, more storage per version, and more care to avoid overfitting. Choose this only when you need a genuinely novel aesthetic or a highly specialized domain, and when you can commit to maintaining multiple checkpoints.
A practical decision rule: start with reference conditioning, graduate to an adapter the moment you need the same character in more than a handful of shots, and consider a full fine-tune only when adapters have demonstrably plateaued.
Consistency Across Shots: Characters, Props, and Style
Consistency is where AI video projects live or die. Three mechanisms do most of the work.
The character bible
Before generating anything, write a one-page specification for each recurring subject: height and build, hair, wardrobe palette, signature accessories, posture, and the three adjectives that describe their energy. Then generate a small set of approved reference stills that match that description and treat them as canon. When a shot drifts, you compare it against the bible rather than against your memory of the last clip.
Reference-image conditioning and multi-image blending
Feeding two to four reference images at once — a face, a costume detail, a lighting reference — gives the model more to anchor on than any single image can. This is especially powerful for props and environments: a hero car, a specific interior, a recurring logo treatment. Keep each reference tightly cropped to the feature you actually want carried over, because the model will inherit everything in the frame, including things you did not intend.
Style locking
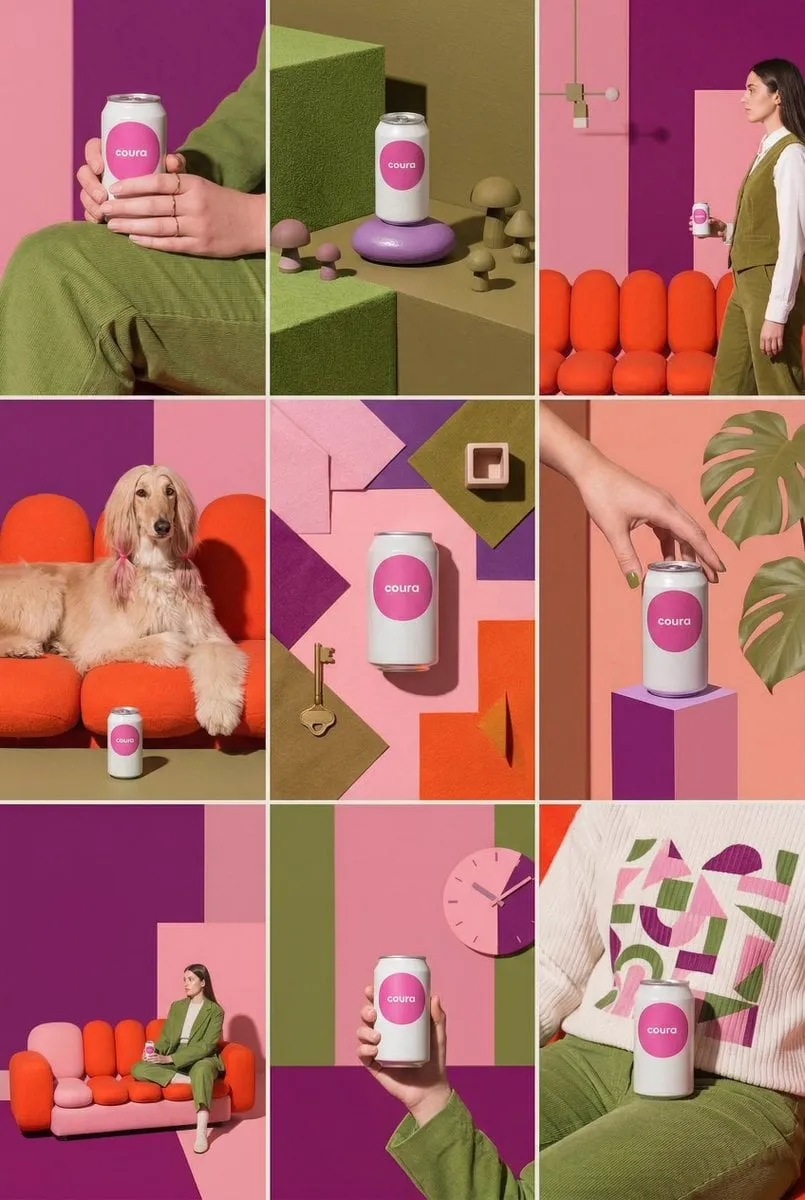
If your project has a look — grainy 16mm, cool corporate minimalism, painterly anime — encode it consistently in captions and in a fixed prompt suffix. Do not let style live in the same token as your character, or you will never be able to change the look without losing the face. Keep identity, wardrobe, environment, lighting, and style as five separate controllable layers, and your prompt becomes a small, editable configuration file rather than a paragraph of prose.
Prompting and Directing a Trained Model
Once your model knows your subject, prompting shifts from description to direction.
Motion vocabulary
Be specific about what moves and how much. "She turns her head slowly toward the window while her hair settles" gives the model a clear physical event. "Cinematic movement" does not. Useful motion verbs include drift, settle, sweep, jolt, sway, stride, recoil, and unfurl. Specify amplitude and speed where it matters: a slight tilt reads differently from a full-body spin.
Camera and lens language
Treat the camera as a second character. Slow dolly in, handheld follow, locked-off tripod, crane rise, rack focus from foreground to background. Mentioning a lens character — wide, telephoto compression, shallow depth of field — steers composition far more reliably than generic adjectives like "epic."
Negative prompts and failure modes
Keep a running list of what your model gets wrong: extra fingers, rubbery hands, melting backgrounds, text on signage, flickering shadows. Put those into a negative prompt template you reuse across every generation. When a new failure appears, add it immediately. Over a few projects your negative template becomes one of your most valuable assets.
Post-Production: Upscaling, Interpolation, and Audio
Raw model output is an intermediate, not a deliverable. Three passes close most of the gap.
Upscaling lifts resolution and often repairs detail in faces and textures. Run it after you have locked the shot, not before, because upscaling doubles the cost of every subsequent revision.
Frame interpolation raises a low frame rate to something that reads as smooth footage. Use it carefully: aggressive interpolation on fast motion creates smeared, soap-opera artifacts. On slow, deliberate shots it is nearly invisible and very effective.
Audio is where AI video most often falls apart in the edit. Generate or record dialogue, then add room tone, foley, and a light music bed. Silence between clips makes cuts feel like glitches; continuous ambience makes them feel intentional. A two-second ambient crossfade under every cut solves more problems than another round of regenerating video.
A Repeatable Production Workflow, Step by Step
Here is the sequence that keeps a multi-shot project manageable.
- Write the shot list first. Every shot gets one sentence: subject, action, environment, camera. You cannot evaluate a model against a shot list that does not exist.
- Lock references. Approve character stills and prop references before spending any time on motion.
- Build or reuse your model. Reuse an existing adapter when the subject matches; train a new one only when you need a genuinely new identity or style.
- Run the test battery. Generate the same eight to twelve prompts across all checkpoints. Pick the checkpoint that is most consistent, not the one with the best single image.
- Generate low-resolution drafts. Block the entire sequence at draft quality so you can judge pacing and continuity before polishing anything.
- Fix continuity issues at the draft stage. Swapping a shot is cheap now and expensive later.
- Lock, then upscale and interpolate. Do the expensive passes once, on final shots only.
- Assemble and sound-design. Cut to a temp track, then replace with final audio and ambience.
- Archive the model and dataset. Store the adapter, the checkpoint number, the caption file, and the prompt templates together. Future-you will want to reproduce a shot from six months ago.
Common Mistakes and How to Avoid Them
Overfitting to a single look. If every test prompt returns the same lighting and framing, you trained too long or your dataset was too uniform. Add variation and stop training earlier.
Trigger-word soup. Cramming identity, wardrobe, and mood into one token makes the model rigid. Separate your controls.
Training before curating. A model trained on mediocre frames will produce confident, detailed mediocrity.
Judging by the best sample. Cherry-picked outputs hide instability. Score your checkpoints on consistency across the whole test set.
Ignoring the sound design. Viewers forgive soft image quality far more readily than bad audio.
Skipping versioning. Name every model file with the dataset version and training step. Untraceable models become unusable the moment you want to change something.
Chasing resolution too early. Draft quality is for decisions; high quality is for delivery. Mixing the two is how projects burn their schedule.
FAQ
How much data do I need to train a usable model?
For a character adapter, 18 to 40 carefully curated examples is a realistic starting range. More data helps only if it adds genuine variety. A hundred near-duplicate frames will teach the model less than twenty diverse ones.
How long does training take?
Lightweight adapters often finish in under an hour on a modern GPU, and much faster on rented hardware. Full fine-tunes can take many hours. Budget more time for evaluation than for training itself; the comparison pass is what determines quality.
Can I train on video clips instead of stills?
Yes, and it usually improves motion realism. Extract frames or use short clips directly, but curate aggressively — motion blur and compression artifacts in training data show up in your outputs.
What if my character still drifts between shots?
Check three things in order: whether your trigger token also encodes wardrobe or mood, whether your reference images show the character from multiple angles, and whether your captions use consistent phrasing. Drift is nearly always a captioning or dataset-diversity problem rather than a training-step problem.
Do I need a powerful local machine?
Not necessarily. Many creators rent GPU time by the hour for training and generate on consumer hardware. If you train frequently, a local GPU pays for itself quickly; if you train once a month, renting is usually more sensible.
How do I keep a project's look consistent across a long series?
Treat it like a brand system: fixed prompt templates, fixed negative prompts, a locked reference set, and a versioned model file. The fewer variables you change between episodes, the more the series feels like one production.
Is it worth training a model for a one-off project?
Usually not. Reference-image conditioning is faster for a single sequence. Train when you expect to reuse the subject or style across multiple projects, because the payoff compounds with reuse.
How do I know when to stop training?
Generate your test battery every few hundred steps. When new checkpoints stop improving consistency and start reproducing dataset quirks — the same background, the same pose — you have passed the useful point. Roll back one or two checkpoints and keep that one.
