
Why AI video crossed the usability threshold
For years, text-to-video was a demo category. Clips lasted three or four seconds, faces melted between frames, and anything resembling a camera move turned into a smear of pixels. The technology was impressive in a lab and nearly useless on a timeline.
That changed with the current generation of diffusion transformer models, often grouped together as "Veo-class" systems. Three things improved at once, and their combination is what made the leap feel sudden:
- Temporal coherence. Models now maintain object identity and lighting across a full take rather than redrawing the world every frame. A jacket stays the same jacket.
- Prompt adherence. Camera language, lens behavior, and pacing instructions are respected far more literally. If you ask for a slow dolly-in with shallow depth of field, you usually get something close to it.
- Native audio. Several models generate synchronized dialogue, ambience, and effects alongside the picture, which removes an entire synchronization pass from the pipeline.
For a solo creator or a small studio, the practical consequence is simple: AI video is now good enough to be edited. Not good enough to replace a crew, but good enough to produce a credible 60-second piece with a coherent visual identity, real sound, and a handful of shots that hold up on a phone screen and a laptop screen alike.
The catch is that quality is uneven. The same model that produces a stunning wide shot can produce a nightmarish close-up of hands holding a coffee cup. The rest of this guide is about building a workflow that maximizes the good outputs and hides the bad ones.
What Veo-class models do well — and where they fail
Before you write a single prompt, it helps to have an honest map of model strengths. Every AI video project is really a negotiation with these limits.
Strengths: motion physics, camera language, and light
Modern models handle natural motion beautifully. Water, smoke, fabric, hair, crowds, and vehicle movement all read as physically plausible. Camera language is another genuine strength: dolly, crane, handheld, whip pan, and drone-style orbits are all available as prompt vocabulary. Lighting is where these models are arguably best — golden hour, neon practicals, overcast diffusion, hard rim light, all rendered with cinematic taste that would take a human crew hours to light.
Weaknesses: precise action, text, and long takes
Expect trouble with:
- Fine motor detail. Fingers, cutlery, tools, and small props remain unreliable.
- Legible text. Signs, screens, and labels usually degrade into plausible-looking nonsense.
- Choreographed interaction. Two characters shaking hands, passing an object, or making eye contact on cue is still a coin flip.
- Takes beyond roughly ten seconds. Coherence drifts; the model invents new details to fill the gap.
The three-take rule
Budget mentally for three generations per usable shot. If a shot needs five or more attempts, the prompt is wrong or the shot is beyond the model's ability. Rewrite the prompt before you keep rerolling — and if it still fails after a rewrite, redesign the shot. An over-the-shoulder framing might work where a full-body action beat does not.
Choosing the right model for each shot
There is no single best model. There is only the right model for a given shot, and routing between them is a core skill.
Match the model to the shot type
| Shot type | What to look for |
|---|---|
| Cinematic wide, landscape, atmosphere | Strong physics, long take stability |
| Character close-up with dialogue | Native audio, facial fidelity, lip sync |
| Product macro, controlled studio light | Prompt precision, clean backgrounds |
| Stylized animation or illustration | Strong aesthetic bias, consistent art direction |
| Fast social cutdowns | Vertical framing, quick iteration speed |
In practice, most creators keep two or three models in rotation: one for photoreal hero shots, one for stylized or animated sequences, and one fast, cheap option for testing ideas and building animatics.
The usable-output ratio
Track how many generations it takes to get one shot you would actually put in the edit. A model that produces gorgeous footage 20 percent of the time can be more efficient than one that produces acceptable footage 80 percent of the time, because the ceiling of the final film matters more than the average.
Multi-model routing in practice
A realistic routing plan for a 60-second piece:
- Animatic stage. Use the fastest model available at low resolution to block out timing and camera moves. Do not chase quality here.
- Hero shots. Generate on the highest-quality photoreal model, three takes each, and select immediately.
- Secondary shots. Use a mid-tier model where the shot is on screen for under two seconds or will be heavily cropped.
- Inserts and texture. Generate abstract b-roll — light flares, hands-free environments, sky, traffic — with any model. These are continuity insurance.
Pre-production: scripts, shot lists, lookbooks
AI video rewards preparation more than traditional filmmaking does, because every prompt is a mini production decision. Sloppy pre-production shows up as wasted generations.
Write for the format
A script intended for generation should be built from beats that fit into six-to-eight-second units. If a scene is a three-minute conversation, you are not making one video, you are making a sequence of shots with sound bridges between them. Restructure dialogue so that each line can live inside a single take.
Build a shot list in a spreadsheet
Columns that matter:
- Shot number and duration
- Description of action and framing
- Model chosen and why
- Prompt draft
- Reference image or style anchor
- Status (blocked, generating, selected, rejected)
- Notes on what to avoid
The last column is the most valuable and the most often skipped. Writing "no hats, no crowd, keep left side empty for text" saves you from repeating the same mistake twenty times.
Create a lookbook before you generate anything
Collect eight to twelve reference stills — color palette, contrast, lens character, wardrobe, set dressing. Then write a single paragraph describing the look, and paste that paragraph into every prompt. This is the cheapest continuity tool available: consistent adjectives produce consistent footage.
A reusable prompt framework
Good AI video prompts read like shot descriptions written for a cinematographer, not like wishes.
The six-part structure
- Subject — who or what, with two or three specific visual details.
- Action — one clear verb, present tense, no compound choreography.
- Camera — framing plus movement ("medium close-up, slow push in, eye level").
- Lens and depth — "50mm, shallow depth of field, soft background falloff."
- Light and color — "overcast daylight, cool shadows, muted teal palette."
- Mood and texture — "documentary realism, subtle grain, natural skin texture."
A single sentence combining all six consistently outperforms a paragraph of vague adjectives.
Negative prompts and guardrails
List what you never want: extra limbs, warped faces, floating objects, text overlays, logos, rapid cuts, camera shake. Keep the list short and specific. Long negative lists tend to fight the positive prompt and flatten the image.
Seeds, references, and controlled iteration
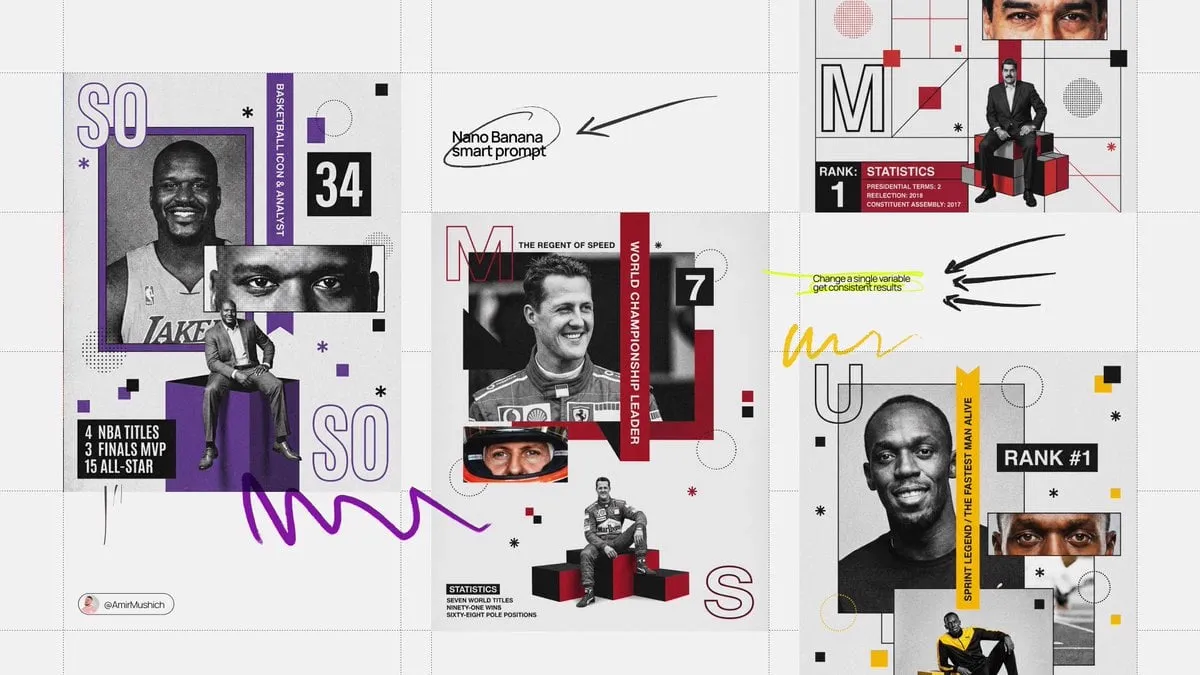
Once you get a take you like, change exactly one variable at a time. Lock the seed, then adjust the camera move; lock the camera, then adjust the light. Changing three things at once makes it impossible to learn what the model responded to — and turns a five-minute task into an hour of guessing.
Continuity across shots
The single hardest problem in AI video is making shot two look like it belongs to shot one.
Character consistency
Use image references wherever the model supports them. Generate a clean character sheet first: front, profile, three-quarter, and a full-body frame in costume. Reuse those images as conditioning input for every shot featuring that character. Keep wardrobe descriptions verbatim across prompts — a jacket that is "olive canvas" in one prompt and "green jacket" in the next will change color.
Environment and lighting continuity
Generate a wide establishing shot early and treat it as the visual anchor for the scene. Then constrain all subsequent prompts to that palette and light direction. If the scene is lit from the left with warm practicals, say so every time.
Edit around discontinuities
Not every inconsistency needs to be solved at the generation stage. A cut to a reaction shot, an insert, a sound bridge, or a brief text card will hide a mismatch more convincingly than another ten generations. Editors solve continuity problems all day; borrow their tricks.
Sound design and dialogue
Audio is where amateur AI films fall apart, and also where a modest amount of work produces the biggest perceived quality jump.
Native audio versus layered post audio
If your model generates synchronized dialogue, use it for lip-sync-critical shots. For everything else, generate the picture silently and build the sound in post. Layering gives you control over balance, and it lets you replace a weak generated ambience with a clean library track.
A practical sound stack
- Dialogue — generated or recorded, cleaned with light de-essing and compression.
- Room tone — a continuous bed under every scene, even quiet ones.
- Foley — footsteps, fabric, door closes, cup sets. Small and specific.
- Ambience — location atmosphere, low in the mix.
- Music — one cue per emotional beat, not one track for the whole film.
Lip sync workflow
Generate the line, isolate the vocal, then align the picture. If sync drifts, cut to the listener's reaction for a beat instead of fighting the render. Viewers forgive a cutaway; they do not forgive a rubber mouth.
Post-production, finishing, and delivery
Editing rhythm
AI shots often feel slightly too long because they were expensive to make. Resist that instinct. Cut on motion, keep the average shot under three seconds for social formats, and let the strongest frame carry the moment. If a shot only works for one second, give it one second.
Upscaling, interpolation, and grain
Most models output below final delivery resolution. Run a dedicated upscaler, but avoid aggressive frame interpolation — it creates a soap-opera smoothness that reads as synthetic. If motion looks steppy, try a low interpolation setting first. Finish by adding a light, uniform grain layer; it unifies shots generated by different models and hides minor artifacts.
Color, captions, and delivery specs
Apply one grade across the entire piece rather than correcting each shot individually. Then export per platform: vertical 9:16 for short-form feeds, 16:9 or 2:1 for web and presentation, and square crops where the algorithm still favors them. Burn in captions for social, and ship a clean version without them for clients who will re-edit.
Rights, disclosure, and platform policy
Check the commercial terms of every model you use before publishing to a client channel. Keep a simple asset log: which model generated which shot, which references you supplied, and which audio libraries you pulled from. Disclose synthetic media where platforms or jurisdictions require it, and never generate a recognizable real person's likeness for commercial use without written permission. If your footage depicts a real location, product, or brand, get clearance or reframe it.
Common mistakes and a sample production week
Mistakes to avoid
- Prompting the plot instead of the shot. "A woman realizes her brother lied" is a story beat, not a generation prompt.
- Overloading a single take. Split complex action into multiple shots with cuts between them.
- Chasing perfection on a throwaway shot. A two-second transition does not need five rounds of refinement.
- Ignoring audio until the end. Sound changes pacing decisions, so build it alongside the picture.
- Generating without a shot list. You will end up with beautiful footage that cannot be assembled into a story.
A repeatable production week
- Day one: script, beat sheet, shot list, lookbook.
- Day two: animatic with a fast model; lock timing and camera plan.
- Day three: generate hero shots and character sheets; select and log.
- Day four: generate secondary shots, inserts, and b-roll.
- Day five: assemble the edit, build the sound stack, add music.
- Day six: upscale, grade, add captions, deliver and archive assets.
This cadence produces a reliable two-to-three-minute finished piece with a single editor, and it scales cleanly if you add a second person for sound or grading.
FAQ
How long should a single AI-generated shot be?
Aim for four to eight seconds. Beyond roughly ten seconds, coherence drifts and models start inventing details. If a moment needs to run longer, cut between two takes rather than extending one.
Do I need multiple AI video models?
Most creators benefit from two: a high-quality photoreal model for hero shots and a fast, inexpensive one for animatics and testing. Stylized projects often add a third with a strong art-direction bias.
Why do my characters change between shots?
Because text descriptions are not enough. Use image references for the character, keep wardrobe and lighting language identical across prompts, and generate a character sheet before you start the scene.
Can AI video hold up for client work?
Yes, for short-form advertising, social content, explainers, mood pieces, and animatics. For narrative work with dialogue-driven performances, treat AI as one tool in a hybrid pipeline rather than a full replacement for production.
What about generated audio quality?
Native audio is good enough for ambience and effects, and increasingly good for short dialogue. For anything on camera for more than a few seconds, consider recording the line separately and syncing it in post.
How do I keep costs and time predictable?
Standardize your prompt template, track usable-output ratios per model, and route shots to the cheapest model that can achieve the required look. Predictability comes from process, not from the tool you pick.
Should I disclose that a video is AI-generated?
Follow platform rules and local regulations, and expect disclosure requirements to tighten. When in doubt, a short on-screen note or description line costs you almost nothing and protects your credibility.
The through-line in all of this is unglamorous: preparation, routing, continuity discipline, and sound. Veo-class models have removed the technical barrier to producing cinematic footage. What remains is the craft of turning that footage into something an audience will actually finish watching.
