
Why Native 9:16 Generation Changed the Workflow
For most of the last decade, vertical video was a compromise. You shot or rendered in 16:9, then chopped the sides off and hoped the subject stayed centered. Motion that worked beautifully in landscape — a sweeping lateral pan, a wide establishing shot — fell apart the moment it hit a phone screen. Editors spent hours nudging crops frame by frame.
Native 9:16 generation removes that compromise at the source. Modern text-to-video and image-to-video engines accept the aspect ratio as a first-class input, which means the model composes the scene for a tall frame from the first frame onward. Camera moves are planned for a narrow field of view. Subjects are placed with the understanding that the top and bottom of the frame will often be covered by interface chrome, captions, and buttons.
The practical result is that a single creator can now produce a week of vertical content in an afternoon, and a small team can produce localized variants of the same clip for several markets without reshooting anything. That shift is why the question of which engine to use has become a real production decision rather than a novelty.
This guide focuses on what actually matters when you generate vertical video: framing behavior, motion quality, character consistency, duration limits, and the post-production reality that no model removes. Tool names appear where they illustrate a capability tier — not as an endorsement ranking.
What Actually Changes Inside a Tall Frame
Before comparing engines, it helps to understand why 9:16 is not just 16:9 rotated. The geometry changes what the audience perceives, and models that ignore this produce technically correct but emotionally flat clips.
The framing math is different
A vertical frame has roughly 56% of the horizontal information of a 16:9 frame at the same diagonal. That means less room for background storytelling and much more weight on the subject. Wide establishing shots feel claustrophobic unless you deliberately use depth staging — foreground element, mid-ground subject, distant background — to create layers inside the narrow column.
The safe-zone constraint compounds this. On most short-form platforms, the top 10–15% and bottom 20–25% of the frame sit under interface elements. Effective creators compose the subject's eyes in the upper third and keep critical action between roughly the 15% and 75% vertical marks.
Motion reads differently
Lateral pans in a tall frame feel faster than they actually are because the subject exits the frame sooner. Vertical movements — a rise, a fall, a tilt up a building — feel more natural and cinematic. Push-ins and pull-outs are the safest dramatic moves. If a model defaults to a horizontal dolly, the shot will often feel like it is running away from the viewer.
Prompting needs spatial language
Generic prompts like "a woman walking through a market, cinematic" produce generic results in any aspect ratio. In vertical, you get better output by naming the framing directly: shot size, subject placement, camera height, and lens character. A prompt such as "medium close-up, subject centered slightly below the top third, 35mm lens, shallow depth of field, slow push-in, warm practical lighting" gives the model far more to work with than adjectives alone.
The Generator Landscape: Four Practical Tiers
Engines cluster into four functional tiers. Understanding the tiers matters more than memorizing model names, because names change faster than the capabilities underneath them.
Tier 1: Fast, stylized engines
These are built for short takes, strong visual identity, and rapid iteration. They typically handle 5–10 second clips well and offer stylized presets that make output look intentional without heavy prompting. PixVerse and Pika sit here, as do the turbo modes of larger systems. This tier is ideal for hook-driven content: quick, punchy, visually distinct shots that survive a two-second scroll decision.
The tradeoff is control. Fine camera work and long-form narrative continuity are weaker. Use this tier to find the idea, not to finish it.
Tier 2: Cinematic control engines
Runway's Gen family, Luma's Ray models, and the Sora line represent engines designed for shot-level control. They respond well to detailed camera language, hold lighting and color across a take, and handle more complex motion — a character turning, interacting with an object, or moving through a lit environment.
This tier is where vertical work starts to look like an actual film rather than a generated clip. It is also where render times and iteration cost climb, so prompt discipline pays off.
Tier 3: Budget realism engines
Kling's standard modes and MiniMax Hailuo are strong examples of engines that produce high-fidelity realism at a lower operational cost. They are particularly good at skin texture, fabric movement, and natural light. For talking-head-adjacent content, product beauty shots, and lifestyle footage, this tier often delivers the best quality-per-render ratio.
Tier 4: Pipeline and API engines
The most underrated category. Engines that expose a stable API — and image models such as the Flux family that generate clean vertical keyframes — let you build a repeatable production line: generate a keyframe grid, feed each frame into image-to-video, produce twenty variants of a shot, and select in an editor rather than in a browser tab.
If you produce more than a handful of vertical clips per week, this tier is where the real efficiency gain lives. The bottleneck stops being the model and becomes your selection process.
Decision Criteria: Choosing the Right Engine for the Shot
Stop asking which engine is best. Ask which engine is best for this specific shot under this specific deadline. These six criteria resolve most decisions.
1. Native 9:16 versus reframing
Some engines generate natively in vertical; others render wide and let you crop. Native generation almost always produces better composition. Check this first — it eliminates an entire class of post-production work.
2. Camera control granularity
Can you specify a push-in, a tilt, a handheld feel? Engines in the cinematic tier give you this. Fast stylized engines mostly give you motion energy rather than direction. Match the tool to whether the shot needs a specific move.
3. Character and scene consistency
If your clip has the same person across three shots, consistency is the deciding factor. Image-to-video with a locked reference frame is currently the most reliable path. Pure text-to-video still drifts in facial features and clothing between takes.
4. Duration and extendability
Five seconds is a hook. Fifteen seconds is a story. If you need longer, check whether the engine supports extension or whether you need to stitch takes in an editor. Stitching is usually cheaper than extending, and it gives you more editorial control.
5. Motion realism at speed
Fast motion — running, dancing, sports — is the hardest test for any engine. Hands, limbs, and fabric are where artifacts appear first. Always test your specific motion type before committing a full production to an engine.
6. Output resolution and codec
Deliver at 1080x1920 minimum. Upscalers can help, but they cannot recover detail that was never generated. If your workflow includes text overlays, generate at higher resolution than you need and scale down.
Prompt Patterns That Hold Up in Vertical
Prompting is the highest-leverage skill in this workflow. These patterns consistently produce better vertical output.
Name the shot size first. "Close-up," "medium shot," "wide" — leading with framing anchors the model's composition before it starts interpreting style.
Anchor the camera vertically. Words like "eye level," "low angle," "overhead" matter more in a tall frame than in a wide one, because the vertical axis is the dominant visual line.
Describe one motion, not three. A single clear action — "she turns toward the camera and smiles" — outperforms a paragraph of simultaneous activity. Models distribute attention poorly across competing actions.
Specify light direction. "Light from the left, window practical, soft shadow on the right cheek" gives depth cues that read strongly in a narrow column.
Keep continuity tokens stable. If you generate a series, reuse identical character and wardrobe descriptions word for word. Small phrasing changes produce visible drift.
A weak vertical prompt looks like: "cinematic woman in city, beautiful, 4k, trending." A strong one looks like: "medium shot, subject centered in the upper third, eye-level camera, slow push-in, 50mm lens, overcast daylight from behind camera, subject in a dark green coat, empty wet street at dawn." The second prompt gives the model composition, camera, lens, light, wardrobe, and setting. That is why it produces a usable take.
A Repeatable End-to-End Workflow for 9:16 Clips
This workflow scales from a solo creator to a small team. It assumes you generate clips and finish them in an editor.
Step 1: Write the hook before the shot list
Decide the first two seconds. What does the viewer see, and what question does it raise? Every generation decision flows from this. If the hook is a face, generate close-ups. If it is movement, generate the motion first.
Step 2: Build a shot list with safe zones marked
Sketch 4–8 shots on a timeline. Mark the top and bottom safe zones on a 1080x1920 canvas. Note which shots need a specific camera move and which can accept any energetic motion. This determines which engine tier you use per shot.
Step 3: Generate in clusters, not one at a time
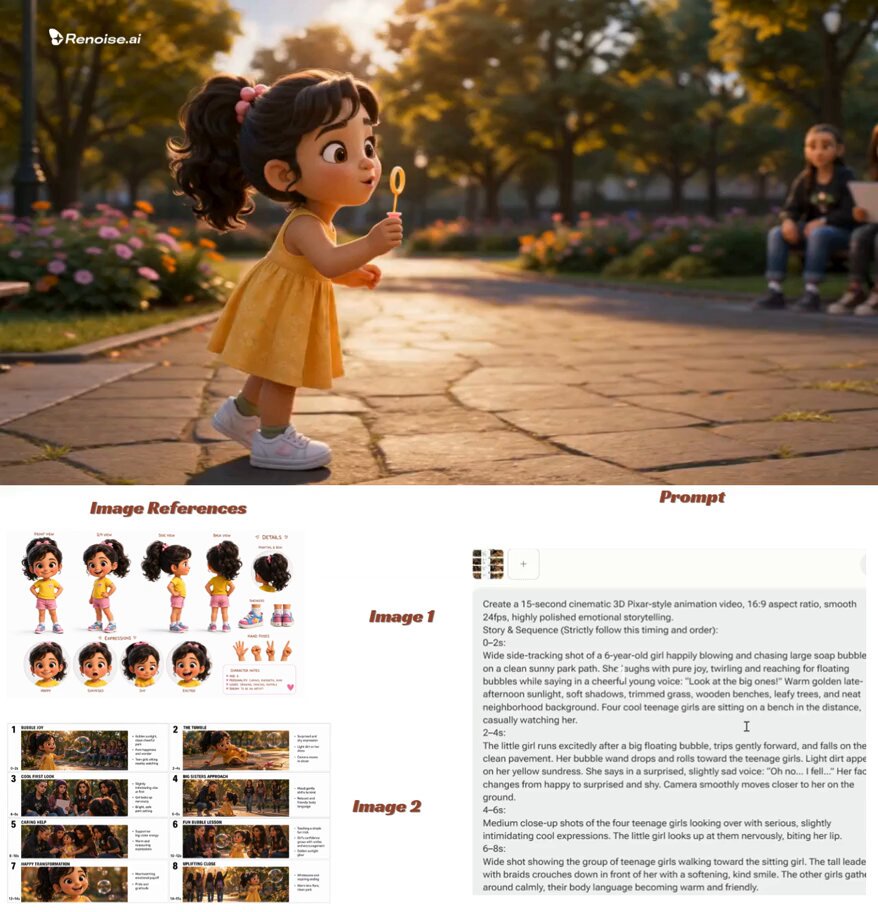
Generate 4–8 takes per shot in one session. Vary one variable per take — camera move, lighting, or wardrobe — rather than scrambling everything. Clustered generation makes selection fast because you are comparing controlled differences.
Step 4: Select ruthlessly
Most takes fail for one of three reasons: the motion stutters, the face drifts, or the composition breaks the safe zone. Reject instantly. A take you hesitate over is a take you will replace later.
Step 5: Finish in the editor
Stabilize if needed, color-match across takes, cut on motion, and place captions inside the middle band. Add sound design — ambience, impacts, music — because audio contributes more to perceived quality than most creators admit.
Step 6: Export variants for testing
Produce two or three versions with different hooks, text overlays, or pacing. Vertical platforms reward iteration more than perfection. One clip tested three ways beats three clips tested once.
Post-Production: The Step That Separates Scroll-Stoppers From Slop
No model outputs a finished vertical video. The gap between raw generation and publishable content is filled by four tasks:
Pacing. AI clips often start a beat too late and end a beat too late. Trim hard. Cutting two frames off the front of a shot can make the whole sequence feel intentional.
Color continuity. Takes generated in separate sessions rarely match in color temperature. A simple correction layer across the sequence unifies them.
Caption placement. Burned-in captions must sit inside the safe band. If you plan captions, generate with slightly more headroom so the text does not cover the subject's mouth or hands.
Sound. Layer at least three elements: a bed (music or ambience), accents (whooshes, clicks, impacts), and voice if present. Muted-first viewing is the norm, so captions and visual rhythm carry the message — but sound determines whether people stay.
Common Mistakes and How to Avoid Them
Generating before deciding the format. If you plan to publish vertical, generate vertical. Reframing a beautiful 16:9 take almost always loses more than it gains.
Chasing model novelty. A new engine releases every few weeks. Switching tools mid-project destroys consistency. Pick a tier per shot type and stay there for the project.
Overloading prompts. Long prompts with contradictory style words produce averaged, bland output. Constrain instead of decorating.
Ignoring hands and fast motion. Test the hardest motion in your clip first. If it fails, restructure the shot rather than burning time on retries.
Forgetting the thumbnail frame. The first frame is a poster image on many platforms. Generate with that in mind or add a designed cover.
Publishing without a hook test. Watch the first two seconds with fresh eyes. If nothing happens, nothing will happen for the audience either.
Quality Control Checklist Before Publishing
- Aspect ratio is exactly 9:16, not an approximation
- Subject's eyes sit in the upper third, clear of interface chrome
- No visible artifacts in hands, teeth, or fine fabric
- Color temperature matches across all shots
- Motion cuts land on movement, not mid-pause
- Captions sit inside the safe band and are legible at small size
- Audio peaks are controlled and dialogue is intelligible
- First frame works as a standalone cover image
- Duration matches platform expectations for the format
- A variant exists for testing a different hook
FAQ
Do I need different tools for vertical and horizontal?
Not strictly, but check that your chosen engine accepts the aspect ratio as an explicit parameter. Engines that only render 16:9 will force you into cropping, which costs quality and composition control.
How long should a generated vertical clip be?
Most engines produce the strongest output between 5 and 10 seconds. Build longer pieces by stitching takes in an editor rather than extending a single generation, unless the extension feature is specifically reliable for your content type.
Why do faces change between shots?
Text-to-video has no persistent memory of a character. The fix is image-to-video: generate or select a clean reference frame, then drive each shot from it with consistent wardrobe and lighting language.
Is a fast stylized engine good enough for client work?
For hook-driven social content, often yes. For anything requiring precise camera work, continuity across many shots, or high realism, the cinematic and API tiers will save you more time in revisions than they cost in render time.
What resolution should I deliver?
1080x1920 is the practical baseline for vertical delivery. If you plan heavy overlays or zoom moves in the edit, generate at a higher source resolution and scale down so text and detail stay crisp.
How many takes should I generate per shot?
Four to eight is a workable range for most shots. Fewer and you accept compromises; many more and selection becomes the bottleneck. Vary one variable per take so comparison stays meaningful.
Can I reuse prompts across engines?
Partially. Structure — shot size, subject placement, camera move, lighting — transfers well. Style vocabulary does not. Expect to rewrite the descriptive layer for each engine family and keep the structural layer intact.
What is the single biggest quality lever?
Post-production. Trimming, color matching, and sound design consistently elevate average generations more than switching engines does. Master the finishing workflow before chasing the next model release.
