
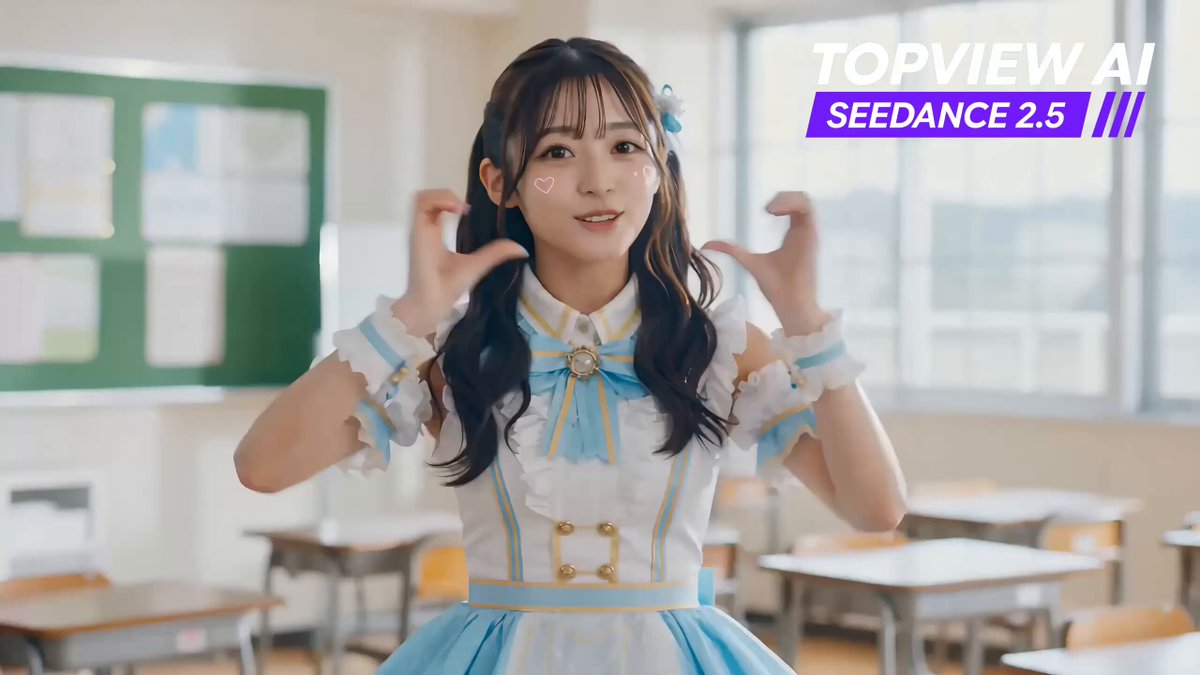
Every few months, a new generation model makes it possible to produce footage that would previously have required a crew, a location, and a serious budget. The practical consequence is that the bottleneck in short-form video has moved. It is no longer whether you can shoot something. It is whether you can decide what deserves to be seen, and whether you can hold a viewer past the first second.
This guide lays out a complete workflow for creating viral-oriented AI videos, from concept development and prompt design through generation, editing, packaging, and quality control. The emphasis is on the decisions that reliably change outcomes: which model suits which shot, how to keep characters and locations consistent across clips, how to build a shot list that survives generation, and how to package a finished file for each platform's distribution logic.
It is written for creators, small studios, marketers, and solo editors who want a repeatable system rather than a lucky experiment. You will find decision criteria, example prompts, checklists, and a troubleshooting section you can return to when a render comes out wrong.
What Actually Makes an AI Video Go Viral
Technical quality is now table stakes. Viewers scroll past footage that is merely impressive, because impressive footage is everywhere. What stops a thumb is a combination of recognizable format, immediate tension, and a payoff that arrives faster than expected.
Four factors do most of the work:
- A hook in the first 1.5 seconds. Motion, a surprising visual, a question, or a face entering frame. Static establishing shots are the fastest way to lose an audience.
- Novelty inside a familiar frame. A known format (before-and-after, day-in-the-life, ranking, transformation) with one element that is clearly new.
- Emotional or informational payoff. The viewer must feel they got something: a laugh, a fact, a technique, or an aesthetic experience.
- Loopability. If the last frame connects to the first, the replay rate climbs, and replay rate is one of the strongest distribution signals on short-form platforms.
AI generation gives you an advantage on the third and fourth factors, because you can produce stylized, impossible, or expensive-looking visuals without logistics. It gives you no advantage at all on the first. The hook is a writing and editing problem, not a rendering problem.
The Shift From Shooting to Directing
The mental model that produces the best results is not "I am generating clips." It is "I am directing a production where the camera and the cast are synthetic." That reframing matters because it changes what you prepare before you touch a generator.
A director works from a script, a shot list, and a consistent visual language. When you adopt the same preparation, three things improve immediately: your generations become more predictable, your editing becomes faster because you are not hunting for usable material, and your output stays coherent across an entire series rather than looking like unrelated experiments.
Practically, this means spending thirty to forty percent of your time on pre-production. Write the hook, draft the beats, define the look, and choose the models before generating anything. Creators who skip this step usually end up with twenty disconnected clips and no video.
Choosing the Right Generation Model for Each Shot
No single model wins across every shot type. The most reliable approach is to assign models by job, the way a production assigns a camera package to a scene.
Match the model to the shot's dominant requirement
- Realistic human motion and physical interaction: choose a model known for temporal stability and natural body mechanics. Test hands, walking, and object contact before committing to a sequence.
- Stylized animation, anime, or illustration: choose a model with strong stylization or a dedicated animation-oriented pipeline. Realistic models often produce uncanny results on illustrated subjects.
- Precise camera control: choose a model that accepts explicit camera language (dolly in, crane up, orbit, handheld). Some models interpret camera terms literally; others ignore them.
- Character or product consistency: choose an image-to-video workflow driven by a reference still rather than pure text-to-video.
- Dialogue and lip sync: choose a model with native audio or pair a video model with a dedicated lip-sync tool.
- Speed versus fidelity: fast drafts for exploration, higher-fidelity settings only for shots that survive the edit.
Work in draft mode, then commit
Generate low-cost drafts of every shot first, assemble a rough cut, and only then re-render the shots that made the cut at maximum quality. This one habit saves more time than any prompt trick. Rough cuts reveal problems that are invisible when you review clips individually: mismatched lighting, inconsistent pacing, repeated compositions, and shots that are beautiful but useless to the story.
Plan for post-processing
Assume every generation needs help. Typical finishing steps include upscaling to delivery resolution, frame interpolation for smoother motion, artifact cleanup on faces and hands, and color matching across clips from different models. Build these steps into your schedule rather than treating them as emergencies.
Writing Prompts That Give You Cinematic Control
A prompt is a shot description. The most effective ones follow a stable order: subject, action, environment, lighting, camera, mood, and technical format. Keeping the order consistent makes it easy to change one variable at a time, which is the only reliable way to learn what a model responds to.
A reusable prompt template
[Shot size and angle] of [subject with two or three specific visual details], [action in present tense], in [environment with texture and depth cues], lit by [lighting source and quality], shot on [lens or film reference], camera [movement], [mood or color grade], [aspect ratio and frame rate].
Example: "Medium close-up of a street food vendor in a neon-lit alley, steam rising from the grill, wiping the counter with a cloth, shallow depth of field, lit by magenta signage and warm practical bulbs, handheld camera pushing in slowly, moody cinematic grade, 9:16, 24fps."
Notice what is included: specific details rather than adjectives, one action, one camera move, and a defined light source. Vague prompts produce vague footage.
Rules that hold across models
- One action per clip. Two actions produce a compromised blend of both.
- One camera move per clip. Competing moves create jitter and morphing.
- Describe light, do not just name a mood. "Golden hour backlight" is actionable; "beautiful" is not.
- Keep prompts under roughly eighty words. Overloaded prompts dilute the important tokens.
- Change one variable at a time when iterating. If you change subject, lighting, and camera together, you learn nothing.
- Keep a prompt library. Save every prompt that produced a usable shot, along with the model and settings, so a successful look can be reproduced later.
Reference images beat adjectives
When character appearance, wardrobe, or product details matter, an image reference is more precise than any paragraph. Generate a clean reference still first, then use it as the starting frame or style anchor for subsequent shots. This is also the foundation of visual consistency, covered next.
Building a Shot List and Keeping Visual Consistency
Inconsistency is the most common failure in AI video series. A character's jacket changes color, a location shifts from day to night between cuts, or a face subtly transforms across three clips. The fix is procedural, not technical.
Build a shot list as a table
Include: shot number, duration, framing, camera move, subject, prompt, model, seed or reference image, and output filename. This sounds bureaucratic until you are editing a sixty-second video assembled from forty generations, at which point it is the only thing keeping the project coherent.
Lock character and location references
Create one canonical image per character and per location. Reuse them as start frames, and keep wardrobe, hair, and environment descriptors byte-identical across prompts. Any small variation in wording can shift the result.
Manage lighting continuity
Decide the light direction and time of day for the whole sequence before generating. If the key light comes from the left in the wide shot, it should come from the left in the close-up. This single rule does more for perceived production value than higher resolution.
Use seeds deliberately
When a model supports seeds, record the one that produced a good shot. Reusing a seed with a modified prompt often preserves style and composition while changing content, which is exactly what is needed for a series with a consistent look.
Editing, Sound, and the First Three Seconds
AI footage almost never works at its full generated length. Motion drifts, details warp, and attention fades. The edit is where generated material becomes a video.
Cut on motion and trim aggressively
Keep the strongest 1 to 2 seconds of each generation. Cut on movement so transitions feel intentional rather than accidental. If a clip needs more than three seconds, generate a second angle and cut between them rather than holding on one shot.
Add sound before you judge the picture
Sound design sells realism more than rendering quality does. Layering a room tone, foley for visible actions, a music bed, and a voiceover transforms footage that looks synthetic into something that feels filmed. Do a pass with your eyes closed: if the audio alone does not carry the story, the visuals are doing too much work.
Grade across models
Clips from different generators rarely match in contrast, saturation, or grain. Apply a unifying grade: lift blacks slightly, match white balance, add a subtle layer of grain, and apply a light vignette. This single step hides a surprising amount of model-to-model variation.
Protect the first three seconds
Front-load motion, text, or a striking visual. Remove logos, slow fades, and long intros. Then check the loop: the final frame should flow back into the opening frame for another pass.
Packaging for Each Platform
A finished video is not a published video. Each platform rewards a different package.
- Vertical short-form: 9:16, burned-in captions, hook in the first second, loop-friendly ending, and a title that adds information rather than repeating the audio.
- Long-form horizontal: 16:9, a clear opening statement of value, and chapter markers so viewers can navigate.
- Square or landscape feeds: 1:1 or 16:9 crops with the subject centered and safe zones respected for interface overlays.
- Multiple placements: export a caption-free master plus a captioned version, so a single edit serves several destinations.
Keep titles specific and searchable. "We rebuilt a 1990s kitchen using AI video" outperforms "AI video test" because it gives the algorithm and the viewer a reason to click.
A Pre-Publish Quality Checklist
Run every video through the same list before publishing:
- Hands, faces, and teeth checked at full size, not in the timeline thumbnail.
- On-screen text and signage rendered correctly, with no warped letters.
- No flicker, morphing, or frame-level pops at cut points.
- Audio levels consistent, dialogue intelligible, music not masking speech.
- Captions accurate, including proper nouns and numbers.
- Aspect ratio and safe zones verified for each destination.
- First frame and final frame reviewed for loop potential.
- Synthetic-media disclosure applied where the platform or jurisdiction requires it.
- File named clearly and archived with its prompt and model settings.
That last point matters more than it appears. Projects get revisited, and a shot that took an hour to produce should be reproducible in minutes.
Common Mistakes That Kill AI Video Reach
Most underperforming AI videos fail for one of a handful of predictable reasons.
- Generating before scripting. The result is a pile of attractive clips with no narrative spine.
- Holding shots too long. Generated motion tires quickly; cut before the viewer notices.
- Ignoring sound. Silent AI footage reads as a demo, not a story.
- Overpacking the frame. Too many subjects or actions cause distortion and confuse the eye.
- Extreme close-ups on faces. Detail errors are most visible there. Use medium shots and let editing imply intimacy.
- Skipping continuity references. Each new clip reinvents the character, and the series loses identity.
- Chasing trends without a format. A trend is a vehicle; a format is the engine you reuse every week.
- Publishing without checking delivery specs. Cropped captions and clipped safe zones quietly reduce reach.
Scaling Into a Repeatable Content System
Once a single video works, the goal is repetition without degradation. Batch your production: write several hooks in one session, generate all reference images in another, run drafts in a third, and edit in a fourth. Batch work is faster because context switching, not rendering, is usually the real cost.
Maintain three assets that compound over time: a prompt library organized by shot type, a reference library of characters and locations, and a template project file with your grade, caption style, and audio chain already configured. Then run a simple weekly test matrix: vary one element at a time, such as hook type or opening frame, and compare retention graphs rather than guessing. Keep what wins, retire what does not, and let the system carry the creative risk.
FAQ
How long should an AI-generated short video be?
Most vertical shorts perform best between fifteen and forty seconds. The constraint is attention, not capability. If your idea needs ninety seconds, build it as a sequence of short, self-contained beats with a clear payoff at the end.
Do I need multiple generation tools?
Not necessarily, but most creators eventually use two or three: one for realistic motion, one for stylized work, and a utility tool for upscaling or lip sync. Choose by shot requirement rather than by brand loyalty, and keep your prompt library portable across tools.
How do I stop characters from changing between clips?
Create a single canonical reference image, reuse it as the starting frame for every shot with that character, keep wardrobe and environment descriptions identical, and avoid changing the model mid-sequence. If a shot still drifts, regenerate from the reference rather than trying to fix it in editing.
Why does my AI footage look uncanny?
Usually because of extreme close-ups, fast motion, or too many simultaneous actions. Move the camera further back, slow the action, reduce the number of moving elements, and add grain and sound design in post. These four changes resolve most uncanny results.
Is AI video acceptable on major platforms?
Yes, provided you follow each platform's rules for synthetic or altered media and clearly disclose AI-generated content where required. Accuracy matters too: do not present generated footage as documentary evidence of real events.
How do I learn which prompts work?
Keep a log. Record the prompt, model, seed, and a one-line assessment for every generation. After a few dozen entries, patterns appear: which phrasing controls camera movement, which descriptors affect lighting, and which words the model ignores entirely.
Bringing It Together
The creators who consistently produce strong AI video are not the ones with access to the most models. They are the ones who prepare like directors, prompt like cinematographers, edit like storytellers, and review like quality control engineers. Generation is one step in a chain, and the chain is what the audience actually experiences.
Start with one format you can repeat, one reference style you can maintain, and one weekly publishing slot you can defend. Improve a single variable each cycle. Within a few months, you will have something more valuable than any individual model release: a system that turns an idea into a finished, publishable video on demand.
