
Why prompt-by-prompt generation stalls at scale
Anyone who has spent a weekend generating AI video clips knows the pattern. The first three clips look astonishing. By the twentieth, the project has quietly collapsed. Characters drift between frames. Wardrobes change color. A room that felt cramped in one shot becomes cavernous in the next. The footage is beautiful and completely unusable as a sequence.
The problem is almost never the model. It is the absence of a directing layer: a structured process that decides what needs to be seen, in what order, and under what visual contract before a single frame is generated. Generative tools answer the question what does this prompt look like? They do not answer what does this story need next?
That gap is why experienced teams have moved toward pipeline thinking. Instead of treating video generation as a slot machine that occasionally pays out, they treat it as a production line with defined stages, handoffs, and quality gates. The creative decisions happen up front, in text and reference images, where they are cheap to change. The expensive, slow part — rendering — happens last, and only for decisions that have already survived review.
This guide walks through that pipeline in practical terms: how to break a script into shots, how to keep characters and locations stable, how to choose the right kind of model for each shot, and how to assemble everything into something that actually plays like a film rather than a highlight reel.
The five stages of a director-driven AI video workflow
A repeatable AI video workflow has five stages. Skipping any one of them pushes the cost of a mistake downstream, where it multiplies.
1. Script analysis and scene breakdown
Start with the text. Read the script and mark three things: every location, every speaking character, and every beat that changes the emotional temperature of the scene. Those beats become your scene boundaries. A scene is not defined by a page break; it is defined by a shift in intent.
Once you have scenes, write a one-line objective for each: what must the audience understand or feel by the end of it? If you cannot write that line, the scene is not ready to be visualized.
2. Shot list construction
Translate each scene into a sequence of shots. A shot is a single continuous camera event. Write it as a row: shot number, description, shot size, camera movement, duration, dialogue or action, and any continuity notes. This document becomes the spine of the entire project. Everything downstream references it.
3. Look development
Before mass generation, produce a small set of keyframes that establish the visual language: color, lighting, lens character, aspect ratio, texture, and the design of your main characters and locations. Approve these stills first. It is far cheaper to reject a still than a four-second clip.
4. Generation and iteration
Generate in small batches, review against the shot list, and only re-render what fails. The discipline here is refusing to accept a clip that is almost right. Almost-right clips are what create jarring edits later.
5. Assembly and finishing
Bring the selects into an editor, cut for rhythm, add sound, color, and titles. The edit is where AI footage stops looking like AI footage, because pacing and sound do more for perceived realism than pixel quality.
Writing a script the pipeline can actually read
Generative pipelines are literal readers. Vague writing produces vague shots, and abstract interior states produce nothing at all. Rewrite for the visible.
Describe behavior, not emotion. Instead of she feels betrayed, write she sets down the cup, looks at him for two seconds, and leaves without speaking. The second version gives you blocking, timing, and a close-up opportunity.
Name every prop that matters. If a letter appears in act one and returns in act three, give it a name in the script and a matching reference image in your asset library. Unnamed props get re-invented by the model every time they appear.
Keep locations finite. Ten distinct locations across a three-minute piece is a consistency nightmare. Six is manageable. Consolidate aggressively, or shoot coverage from angles that hide the parts of the set you have not designed.
Write dialogue that fits the format. Most AI-generated speech works best in short, declarative lines. Long monologues invite mismatched lip sync and awkward pacing.
Separate script from direction. Camera angles, lens choices, and movement belong in the shot list, not in the script. Keeping them apart lets you revise the story without rebuilding the shot plan.
Building a shot list: coverage, rhythm, and shot grammar
A shot list is where amateur AI video and professional-looking AI video diverge. The temptation is to write one shot per beat. The result is a slideshow. Real coverage gives you options.
The working rule is simple: for any moment that matters, capture three angles — a wide that establishes space, a medium that carries performance, and a close-up or insert that carries detail. You will use only one in the final cut, but having three lets you control rhythm.
| Shot type | Typical duration | Primary job | Practical note |
|---|---|---|---|
| Establishing wide | 3–5s | Place and scale | Generate once, reuse with different crops |
| Medium | 2–4s | Performance and dialogue | Keep eyeline consistent across takes |
| Close-up | 1.5–3s | Emotion, decision | Most sensitive to face drift; approve keyframe first |
| Insert | 1–2s | Detail, prop, texture | Cheapest to generate, highest editing value |
| Transition/pass-by | 1–2s | Time and space bridges | Whip pans and foreground wipes hide seams |
Cut duration by intent, not habit. Fast cutting reads as urgency; held shots read as weight. If every shot is two seconds long, the audience stops feeling anything, because there is no contrast.
Finally, plan your transitions in advance. A shot that ends on forward motion is far easier to cut against than one that ends on a static pause. When you know you need to bridge two locations, write a pass-by shot deliberately rather than hoping the edit will rescue you.
Keeping characters, props, and locations consistent
Consistency is the single hardest problem in AI video, and it is solved with documentation rather than luck.
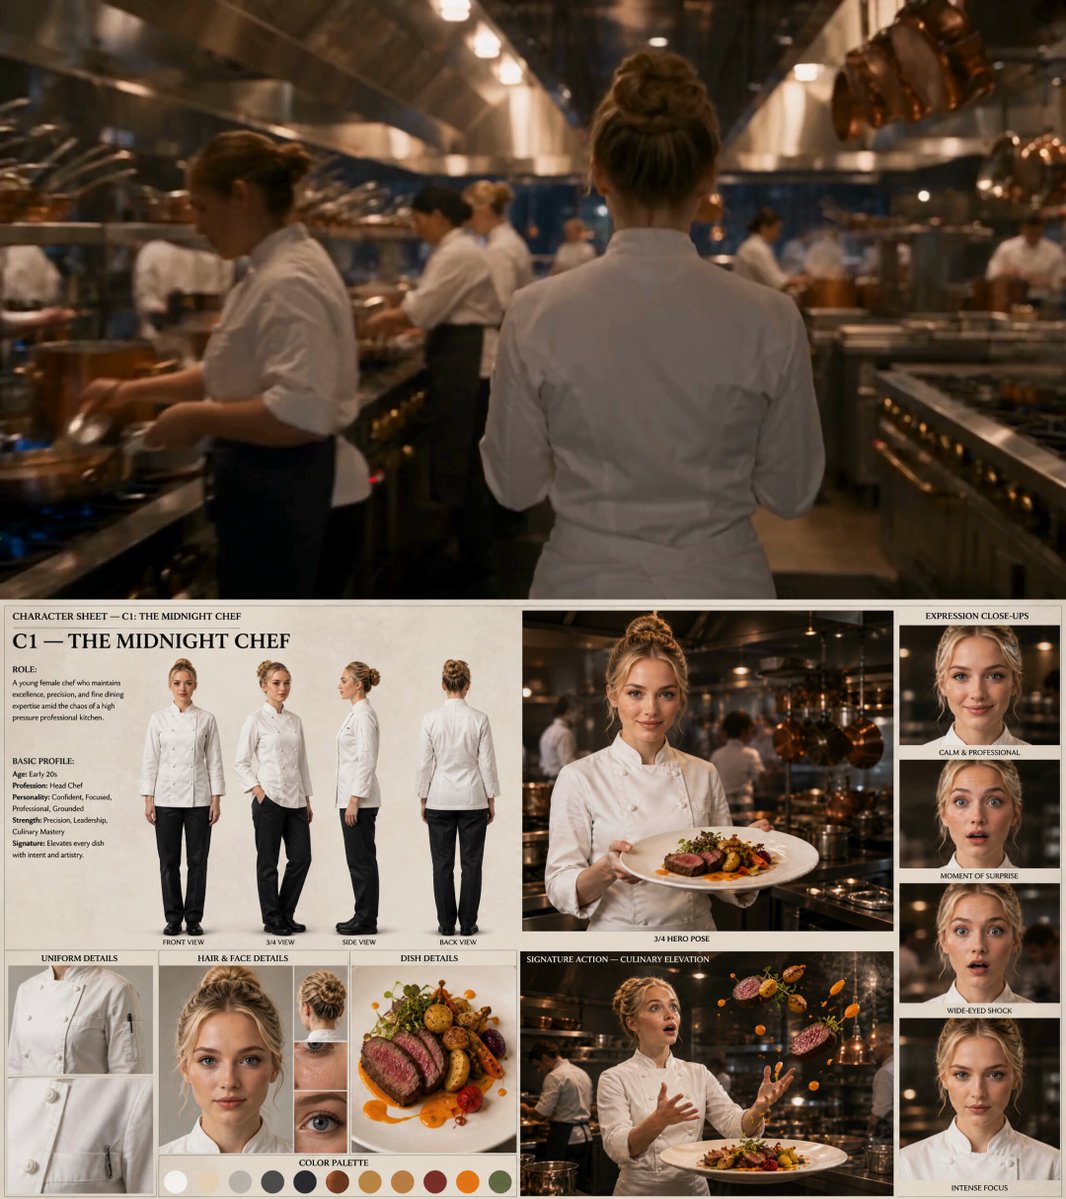
Build a character sheet. For each character, lock a reference portrait, a full-body reference, wardrobe description, hair, age range, and three or four fixed descriptor phrases. Copy those phrases verbatim into every prompt that includes the character. Synonyms are the enemy: if you describe a jacket as olive in one shot and military green in the next, expect two different jackets.
Anchor with image-to-video. Wherever possible, generate a still keyframe of the character in the correct pose and lighting, then animate from that image. Text-to-video invents a new person each time; image-to-video inherits your design.
Lock locations as plates. Generate one hero wide of each location and treat it as a master reference. All other angles of that location should be generated with the plate as a visual reference, so that window placement, wall color, and furniture stay put.
Track continuity in the shot list. Add two columns: wardrobe state and prop state. A shirt that gets stained in scene four must stay stained in scene five. Without a written record, you will not notice the inconsistency until the edit.
Reuse seeds and settings. When your tool exposes a seed or a style reference, record it next to the shot number. Reproducibility is worth more than any single lucky render.
Matching the model to the shot
Different shot types want different capabilities. Choosing one tool for everything is the fastest route to mediocre footage.
- Text-to-video is best for establishing shots, landscapes, atmosphere, and any moment where the specific identity of a person does not matter.
- Image-to-video is best for character work, product hero shots, and anything needing design fidelity.
- Video-to-video and style transfer are best for restyling existing footage or smoothing a clip that has the right motion but the wrong texture.
- Motion and performance transfer is best for dance, gesture, and physical action that must match a reference performance.
- Lip sync and dubbing tools are best for dialogue, narration, and localization passes.
- Upscaling and frame interpolation are finishing tools, not creative ones. Use them last, and use them sparingly, because they amplify artifacts as readily as they amplify detail.
Decision criteria when evaluating any tool: how long a clip can it hold without morphing, how well does it respect a reference image, how much control do you get over camera movement, how predictable is output across repeated runs, and how fast is the feedback loop? That last one matters more than raw quality. A slightly weaker tool that returns results in thirty seconds will improve your film more than a superior tool that takes ten minutes, because iteration is where quality comes from.
Sound design, pacing, and the finishing pass
Audiences forgive soft imagery. They do not forgive bad sound. Build the audio bed in layers: dialogue first, then ambience, then effects, then music. Each layer should be able to stand alone.
For AI-generated visuals, ambience is your secret weapon. Room tone, distant traffic, cloth movement, and breath all signal that a scene is real, and they mask the small motion artifacts that generative clips tend to produce.
Pacing comes from the edit, not the render. Cut to a rough assembly with temp music before you polish anything. If the piece does not work with placeholder audio and ungraded footage, better resolution will not save it.
Save the final pass for three things: color consistency across shots, shot-to-shot transition smoothing, and titles. Grading every clip toward a common look does more for cohesion than re-rendering individual shots ever will.
Common mistakes that derail AI video projects
- Generating before planning. Rendering clips before the shot list exists guarantees a folder of unusable footage.
- Rewriting prompts instead of fixing references. If a character drifts, the fix is a better reference image, not a longer prompt.
- Ignoring duration limits. A model that reliably holds four seconds should never be asked for twelve.
- Mixing styles accidentally. Two different lighting philosophies in the same scene read as an error, not a choice.
- Over-relying on upscaling. Upscalers cannot invent detail that was never rendered; they can only sharpen what is there.
- No continuity log. Most consistency failures are documentation failures.
- Cutting every shot to the same length. Uniform rhythm flattens emotion.
- Skipping the review gate. Approving keyframes before animating them is the cheapest quality control you will ever run.
A worked example: a 60-second product film end to end
Suppose you are making a one-minute film about a portable speaker.
Day one — text. Write a six-beat script: a quiet apartment, the speaker on a shelf, a hand reaching for it, a street at dusk, a rooftop, a group of friends silhouetted against the skyline. Each beat becomes a scene with a stated objective.
Day two — shot list. Expand into roughly eighteen shots, using coverage rules. Two establishing wides, six mediums, four close-ups, four inserts (grille texture, buttons, a finger pressing play, condensation on a glass), and two pass-by transitions. Total runtime lands around sixty seconds with room to trim.
Day three — look development. Produce six approved keyframes: product hero on shelf, hand reaching, street plate, rooftop plate, character portrait, group silhouette. Lock color temperature, contrast, and lens character here.
Day four — generation. Animate from the approved keyframes. Expect a third of the clips to fail and need re-running with adjusted motion prompts. Keep the winners, log seeds, and never regenerate a passing clip.
Day five — assembly. Cut to temp music. You will discover that the rooftop scene needs one more shot and the street scene one fewer. That is normal; the shot list exists to make those changes obvious rather than painful.
Day six — finishing. Lay in ambience (apartment hum, city traffic, wind), add the music bed, grade toward one look, and export. The extra shot you need is generated now, with the locked visual language, so it cuts in seamlessly.
The lesson is that the creative risk was taken on day one, the visual risk on day three, and the technical risk on day four. By the time you are editing, almost nothing can go catastrophically wrong.
Frequently asked questions
How long should each generated clip be? As short as the edit allows. Short clips are easier to keep consistent and easier to replace. Reserve long takes for moments where the camera move itself is the point.
Do I need an editor if I am using AI video tools? Yes, or at least editing skills. Sequences are built in the timeline, not in the generator. Any editor that supports multi-track audio and basic grading will do.
What is the fastest way to fix inconsistent characters? Switch from text-to-video to image-to-video, and lock a single reference portrait for every shot the character appears in. Prompt tuning is a distant second.
Should I generate in portrait or landscape? Decide before keyframes, not after. Reframing a finished sequence crops composition and usually breaks the intent of your wides.
How many shots do I need per minute? Roughly fifteen to twenty-five for a narrative piece, and thirty or more for a high-energy promo. The number matters less than the variety of shot sizes.
Can I mix output from several different models in one film? Yes, and most good projects do. The trick is unifying them in the grade and the sound mix, and keeping a character or location within a single model family wherever possible.
What is the biggest time-saver? Approving keyframes before animating them. A minute spent reviewing a still saves an hour of re-rendering clips.
How do I handle dialogue scenes? Keep them short, shoot them in mediums and close-ups, and treat lip sync as a separate finishing step rather than something to solve during generation.
Start small: one scene, one character, one location, full pipeline from script to finished cut. The habits you build on that scene will scale to a short film far more reliably than any single tool ever will.
