
Text-to-video stopped being a demo problem
A few years ago, the interesting question about AI video was whether a model could produce a coherent clip at all. That question is settled. Today, almost every major model family can turn a paragraph of text into moving footage that holds up on a phone screen. The interesting question has moved elsewhere: can you produce twelve clips that look like they belong to the same film?
That shift matters because it changes what "good" means. A generator is no longer the product. The workflow around the generator is the product. The creators shipping consistent, watchable AI video are not the ones with the best model access — they are the ones with the tightest process for planning shots, locking style, choosing the right tool per shot, and cleaning up in the edit.
This guide lays out that process end to end. It is tool-neutral by design, because the tool roster changes every few months while the underlying workflow stays stable. Whether you are making short-form social content, product explainers, narrative shorts, or internal training video, the same five layers apply: pre-production, generation, consistency control, post-production, and delivery.
Match the model to the shot, not the other way around
Most beginners pick one generator and try to force every shot through it. That is the single most expensive habit in AI video. Different model families are genuinely good at different things, and mixing them inside one project is normal practice at the professional level.
Fast draft models versus cinematic models
Draft-tier models prioritize speed and prompt adherence. They are excellent for storyboarding, testing a camera move, or checking whether a concept reads at all. You do not need a beautiful render to learn that your idea does not work.
Cinematic-tier models prioritize motion realism, lighting, and detail retention. They are slower and less predictable, which makes them a poor fit for exploration and a great fit for the four or five shots that actually carry your piece.
A useful rule: spend your first pass on the cheapest model that can answer your question, and your final pass on the model that produces the best hero frame.
When image-to-video beats text-to-video
If a shot depends on a specific character, product, or location, generate or source a still image first and animate from it. Image-to-video gives you:
- Compositional control. The framing is decided in the still, not gambled on in the prompt.
- Identity stability. A face that exists in an image tends to survive animation far better than a face described in words.
- Faster iteration. Fixing a still takes seconds; re-rolling a video with a slightly different prompt descriptor takes minutes.
Text-to-video remains the right choice for establishing shots, abstract transitions, weather, crowds, textures, and anything where you do not need a repeatable subject.
Motion control and camera language
Modern tools increasingly let you specify camera behavior directly — dolly in, orbit, handheld sway, rack focus, slow push. These controls are worth learning, because camera language is what makes a series of unrelated clips feel intentional. If you cannot control the camera, control it in the edit by varying clip length and cut rhythm instead.
Pre-production: turn the script into a shot list
AI video rewards planning more than any other medium, because every generation is a small lottery. A shot list reduces the number of variables you are gambling on at once.
Shot-level prompt anatomy
Write each prompt as a structured description rather than a run-on sentence. A reliable order:
- Subject — who or what, with two or three distinguishing details.
- Action — one clear verb phrase, present tense, one beat only.
- Setting — location plus one atmospheric detail (mist, dust, neon reflections).
- Lens and framing — close-up, 35mm look, wide establishing, low angle.
- Lighting — soft window light, hard rim light, overcast, practical lamps.
- Camera motion — static, slow push in, lateral tracking.
- Duration and pacing — implied by what you ask the model to fit into the clip.
- Negative constraints — no text overlays, no extra limbs, no flicker, no morphing.
The most common prompting mistake is stacking three actions into one clip. Models handle one continuous beat well and sequential beats badly. If your shot contains a turn, a step, and a gesture, split it into two clips and cut between them.
Reference images and style locks
Build a small reference kit before you generate anything at volume:
- A character sheet with the same person in three angles and two expressions.
- One or two environment plates for each location.
- A palette anchor — a still that establishes your color temperature and contrast.
- A texture reference for grain, film stock, or render style if you want a specific look.
Reuse these references across every prompt in a given scene. Consistency comes from repeated inputs far more than from clever wording.
Consistency: the real technical challenge
Ask anyone who has produced a multi-shot AI piece what actually cost them time. The answer is almost never generation. It is continuity.
Character continuity
Three tactics, in order of reliability:
- Reuse a locked reference image for every shot the character appears in, and vary only the camera and action.
- Keep wardrobe and hair descriptions identical, verbatim, across prompts. Paraphrasing invites drift.
- Generate the character in isolation first, then composite them into wider shots in the edit if the model refuses to keep them small in frame.
Environment and lighting continuity
Choose one time of day and one dominant light source per scene and never change them mid-scene. If a scene spans a time jump, make the jump obvious — a hard cut with a color shift reads as intentional, while a subtle drift reads as an error.
Style bibles are not bureaucracy
A style bible is a one-page document containing your palette, lens choices, grain settings, transition vocabulary, and music direction. It exists so that a collaborator — or you, three weeks later — can match the look without guessing. Even solo creators benefit, because it reduces the number of decisions you re-litigate per shot.
The end-to-end pipeline, step by step
Here is a workflow that scales from a single short to a recurring series.
Script and beat sheet. Write the script in beats, not shots, first. Then break each beat into one to three shots. A 60-second piece usually lands between 12 and 20 shots; fewer if you hold on longer takes, more if you are cutting fast for social.
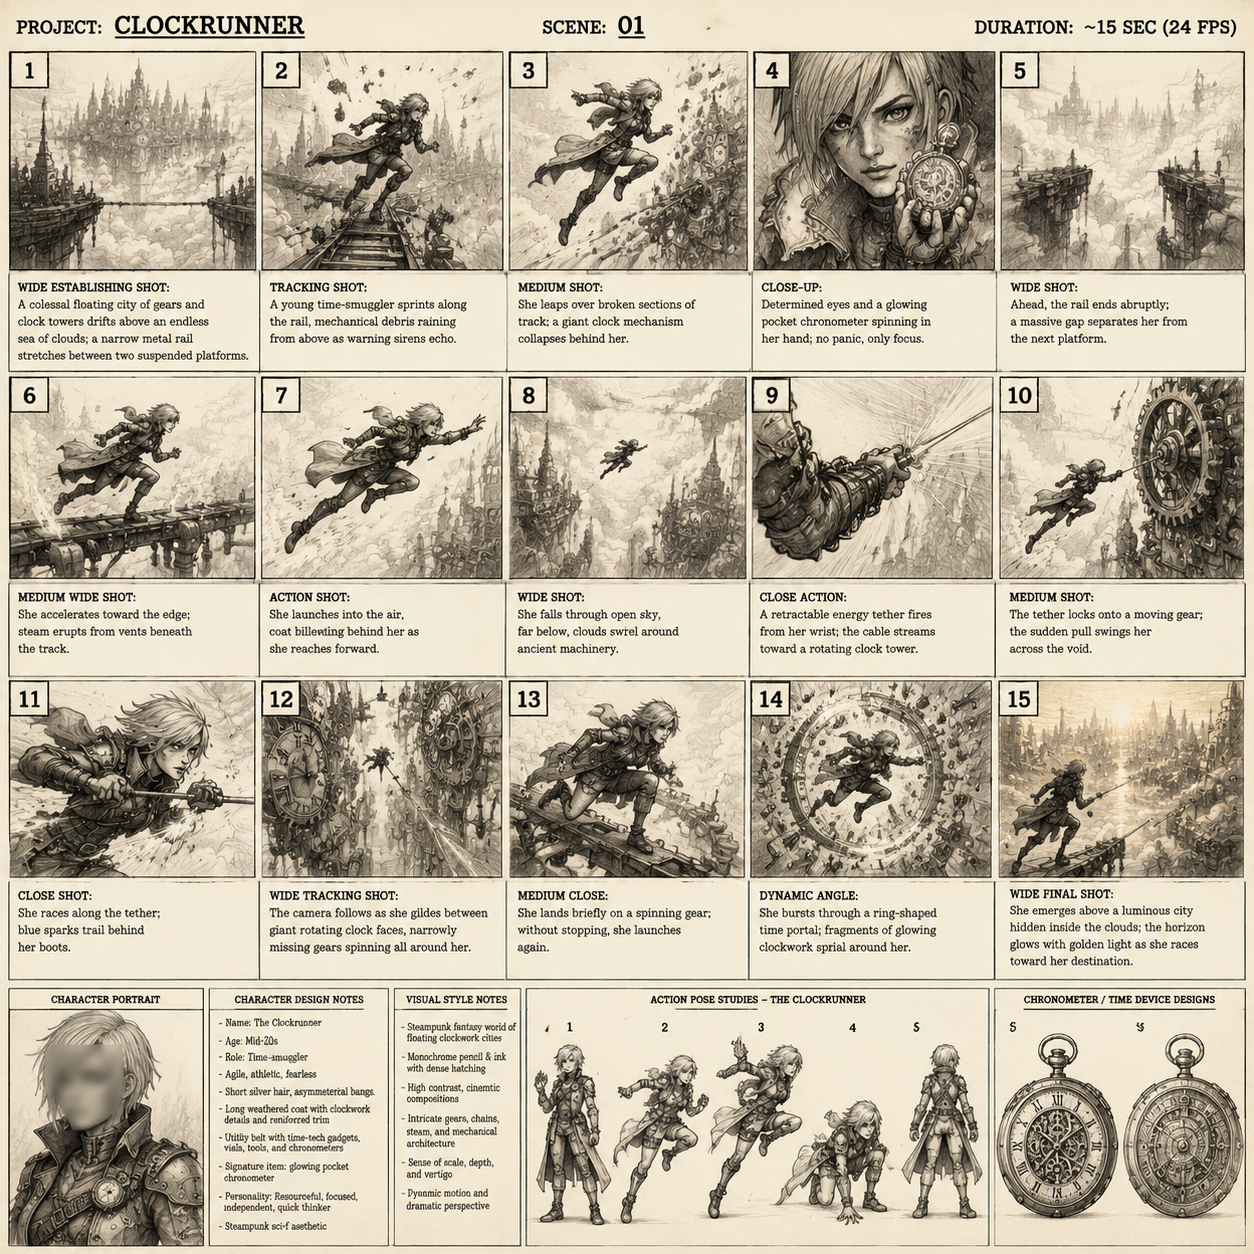
Storyboard stills. Generate still images for every shot before animating anything. This is cheap, fast, and exposes problems in composition and continuity early. Approve the board as a whole, not shot by shot — pacing only becomes visible when you see the sequence.
Draft generation. Animate the board at draft quality. Generate two or three variants per shot and pick the best; do not chase perfection here.
Hero generation. Re-generate only the shots that carry the piece at your highest quality setting, using the approved draft as a first frame where the tool supports it.
Upscale and interpolate. Many tools output at lower resolution or lower frame rate than you want for delivery. Upscale, then interpolate to your target frame rate, and check for warping around fast motion.
Edit. Cut to music or to a narration scratch track. Trim the first and last few frames of every clip — AI generations frequently start and end with instability that is invisible until you are cutting on it.
Sound design. Add ambience, foley, and music. Sound is the fastest way to make AI footage feel finished, and the most commonly skipped step.
Color and finishing. Apply a single grade across all clips to unify them. A slight grain overlay covers a surprising amount of cross-model inconsistency.
Sound, pacing, and the invisible edit
AI video tends to fail in the audio dimension before it fails visually. Silent clips with no ambience read as tests, not films.
A minimal sound pass includes:
- Room tone or ambience under every scene, even quiet ones.
- Foley for any visible action — footsteps, cloth, glass, doors.
- Music chosen to match your cut rhythm, and cut to its beat where possible.
- Narration or dialogue, recorded separately and never generated inside the video model unless the tool is specifically built for it.
Pacing advice: vary clip duration deliberately. Three-second, three-second, three-second becomes hypnotic in the wrong way. Alternate a long establishing hold with two or three quick cuts to create momentum.
Quality control: failure modes and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
| Face morphs mid-clip | No identity anchor | Regenerate from a locked reference image |
| Limbs multiply or merge | Too many subjects or actions in one prompt | Simplify to one subject, one action |
| Flicker or texture crawl | Model instability at low resolution | Upscale, apply grain, or shorten the clip |
| Camera drifts unintentionally | Motion not specified | Add explicit camera instruction or set motion to static |
| Scene tone shifts between shots | Inconsistent lighting language | Standardize the lighting phrase across the scene |
| Output ignores the prompt | Prompt too long or contradictory | Cut to the essentials, remove competing details |
| Text in frame is garbled | Model cannot render typography | Generate clean plates and add text in the edit |
Run this checklist on every clip before it enters the timeline. Catching a morph at the clip stage costs one regeneration; catching it after the edit costs a rebuild.
Decision criteria: how to choose in the moment
When you are staring at four tools and a deadline, decide with these four questions:
Does this shot need identity? If yes, use a tool with strong reference-image or character-locking support. If no, optimize for speed.
Is this shot structural or decorative? Structural shots — the ones the story depends on — deserve the extra render time. Decorative shots can come from a fast model and still look good.
How much will I re-cut it? Shots likely to change length should be generated slightly longer than needed, with a stable middle section you can trim into.
What is my delivery resolution? Generate at or above your delivery size where possible. Upscaling helps, but starting higher always beats rescuing later.
A practical default: a fast model for exploration, one high-fidelity model for hero shots, and a dedicated upscaler for everything.
Building a repeatable system
Once the pipeline works, the goal is repetition without burnout. Three habits make that possible.
Template your prompts. Save prompt skeletons with bracketed slots for subject, action, and camera. Consistency improves immediately, and onboarding a collaborator takes minutes.
Maintain an asset library. Organize reference images, approved stills, sound beds, and music cues by project and by scene. Most of the friction in a second episode is hunting for files from the first.
Version your outputs. Name files with scene, shot, and take number. When a client asks for "the earlier version of shot 4," you will have it.
For teams, add a single review gate before hero generation. One person approving the storyboard prevents the far more expensive scenario of five people disagreeing about finished footage.
FAQ
Do I need multiple AI video tools?
Not strictly, but most working creators use at least two: one fast model for drafts and one high-fidelity model for final shots. The combination usually produces better results per hour than any single tool.
How long should a generated clip be?
Shorter than you think. Three to six seconds is the sweet spot for most models; longer clips accumulate drift. Build longer scenes from multiple clips rather than one long generation.
Why does my character look different in every shot?
Because text descriptions are a weak identity signal. Lock a reference image, keep wardrobe and hair wording identical across prompts, and avoid changing the lighting phrase mid-scene.
Can I generate dialogue inside the video model?
Usually it is better not to. Record or synthesize narration separately, then sync it in the edit. You get cleaner audio, easier revisions, and no lip-sync drift to fight.
Is upscaling worth it?
Yes, if you are delivering to a large screen or cropping into a shot. For vertical social video viewed on a phone, a modest upscale plus grain is often enough.
How do I make AI footage feel less artificial?
Add sound, unify color across clips, vary clip length, and cut on motion. Most "AI look" complaints are actually editing and audio complaints.
What is the biggest beginner mistake?
Generating final-quality clips before the storyboard is approved. It multiplies cost and locks you into shots you have not yet decided you need.
Start with one scene, not one tool
If you take one thing from this guide, take the order of operations. Script, then board, then draft, then hero, then edit, then sound. Tools slot into that order; they do not replace it. Pick a single short scene, run it through the full pipeline once, and time each stage. The stage that takes longest is the one worth optimizing first — and it is rarely the generation step.
Keep your prompts structured, keep your references locked, and keep your grading unified. Do those three things and the model you choose becomes far less important than the workflow wrapped around it.
