
Why generative video finally fits inside a real edit
A few years ago, a generative video clip was a party trick: a few seconds of a face melting into a landscape, a camera that drifted through impossible geometry, limbs that changed length between frames. It was impressive and almost unusable. You could not cut it against live footage, you could not repeat the same character in two shots, and you certainly could not hand it to a client with a straight face.
That has changed. Modern generative video systems are trained on longer sequences, conditioned on motion data, and wrapped in control layers that let you describe camera behavior instead of hoping for it. The result is footage with temporal coherence, plausible physics, and lighting that responds to the geometry of a scene. More importantly, it is footage you can iterate on deliberately: generate a low-resolution version, judge the composition, fix the staging, then commit to a high-quality render.
This guide is written for directors, editors, animators, and solo creators who want a repeatable pipeline rather than a pile of lucky clips. It walks through how to evaluate models, how to design shots before you touch a prompt, how to keep characters consistent, and how to finish AI-assisted video so it holds up on a large screen.
Start with the shot, not with the model
Most disappointing AI video comes from the same mistake: opening a tool first and asking it for something interesting. Professionals invert that order. They decide what the shot has to accomplish in the edit, then choose the cheapest method that can produce it.
Before generating anything, write a one-line intention for each shot. "Establish loneliness in a wide, cold space." "Show the character's decision in a tight close-up." "Bridge two scenes with movement in the same direction." That sentence becomes your filter. If a generated clip does not serve the sentence, it is not a take — it is a test.
Then answer four practical questions:
- Duration and cut point. Does the clip need to hold for four seconds with a moving subject, or will it sit under dialogue as a half-second insert? Short inserts are dramatically easier and cheaper to produce well.
- Continuity risk. Does this shot need to match a face, a costume, or a location that appears elsewhere? If yes, plan for reference conditioning from the start.
- Motion complexity. Walking, running, and hand interaction with objects are the hardest motions. Static or slow-camera shots are the most reliable.
- Delivery format. Vertical social cuts tolerate softer detail and faster motion. A cinema-style wide shot does not. Your aspect ratio and viewing distance change what "good enough" means.
You can prototype all of this with still images before spending any generation time on video. A lookbook of five to ten reference frames settles arguments about lighting, palette, and lens choice far faster than debating prompt wording.
The four axes that separate usable models from impressive ones
Model choices change quickly, but the criteria for judging them are stable. Evaluate every tool on these four axes, and score each shot brief against them.
Motion realism and physical plausibility
Watch how weight behaves. Does a character's mass transfer correctly when they stop? Do fabrics settle, or do they snap back like rubber? Do vehicles follow a believable arc? A model that produces beautiful stills but rubbery motion is a still-image tool with a video export button. Test with three shots: a person sitting down, a liquid pouring, and a slow dolly past a foreground object. Those three reveal most physical weaknesses.
Semantic obedience
This is how closely the output matches what you actually asked for, not just how pretty it is. A model can be gorgeous and disobedient: you request a low-angle tracking shot and receive a static medium shot with lovely lighting. Obedience matters most when you are generating a series of shots that must intercut. Test by writing prompts with three specific constraints — subject, camera move, lighting direction — and count how many survive.
Aesthetic consistency and texture
Photoreal output lives or dies on texture. Skin, concrete, foliage, and glass each have characteristic noise and micro-detail. Some models produce a waxy, over-smoothed look that reads as artificial the moment it is projected large. Others add grain and halation that make a shot feel like it was captured on a real sensor. Decide which look your project needs: clean digital realism, filmic softness, or a stylized painterly finish.
Iteration efficiency
This is the axis creators underestimate. If a model takes twenty minutes per attempt and gives you almost no control between attempts, its effective quality is low regardless of its best output, because you cannot explore. Fast, controllable models win in practice. You will do more takes, discover better staging, and end up with a stronger shot than someone who generated four expensive clips and picked the least broken one.
A cinematography workflow you can repeat
Here is a sequence that keeps creative decisions in your hands and treats generation as a rendering step.
1. Script and shot list. Break the scene into individual shots with durations. Keep a column for "must match" assets: character, wardrobe, location, prop.
2. Reference frames. Build stills for the key beats. You can generate these or shoot them on a phone. Their purpose is to lock composition, lens feel, and light direction.
3. Previz pass. Animate the stills at low resolution with minimal motion — a slow push, a small parallax. Judge pacing and framing before detail.
4. Staging pass. Add subject motion, camera movement, and interaction. Still work at reduced quality. This is where you decide whether the shot works at all.
5. Hero render. Only now generate at full quality, using the winning settings from the staging pass.
6. Continuity check. Cut the hero shots together in your editor in order, without music, and watch for identity drift, inconsistent light direction, and mismatched motion speed.
7. Polish. Upscale, adjust frame cadence, match grain, grade, and hand off to sound.
The core principle is progressive commitment. Never spend full quality on an unproven shot, and never polish a shot whose staging is wrong.
Camera language that generative systems actually understand
AI video responds best to camera instructions phrased like a camera report. Vague adjectives such as "cinematic" or "epic" carry almost no information. Concrete terms do.
A strong prompt covers five things: subject and action, framing, lens, camera movement, and light. For example: "Middle-aged cyclist in a rain jacket pedaling slowly toward camera, medium shot, 35mm lens, shallow but not extreme depth of field, camera tracks backward at walking pace, overcast daylight with soft top light and wet reflections on asphalt."
Useful vocabulary to build your own shorthand:
- Framing: extreme wide, wide, medium wide, medium, medium close-up, close-up, insert.
- Lens feel: 24mm for spatial distortion and scale, 35mm for natural reportage, 50mm for neutral portraits, 85mm for compression and intimacy.
- Movement: static lock-off, slow push in, pull out, lateral tracking, crane up, handheld drift, orbit.
- Light: hard key from screen left, soft window light, practical street lamps, backlit rim, top-down overcast.
- Atmosphere: haze, rain, dust motes, steam, smoke density.
Two habits improve results immediately. First, describe movement in relation to the subject, not in the abstract: "camera moves left as the subject walks right" tells the model more than "dynamic camera." Second, keep one shot per generation. Asking a single clip to cover three story beats invites mush.
Keeping characters and locations consistent across shots
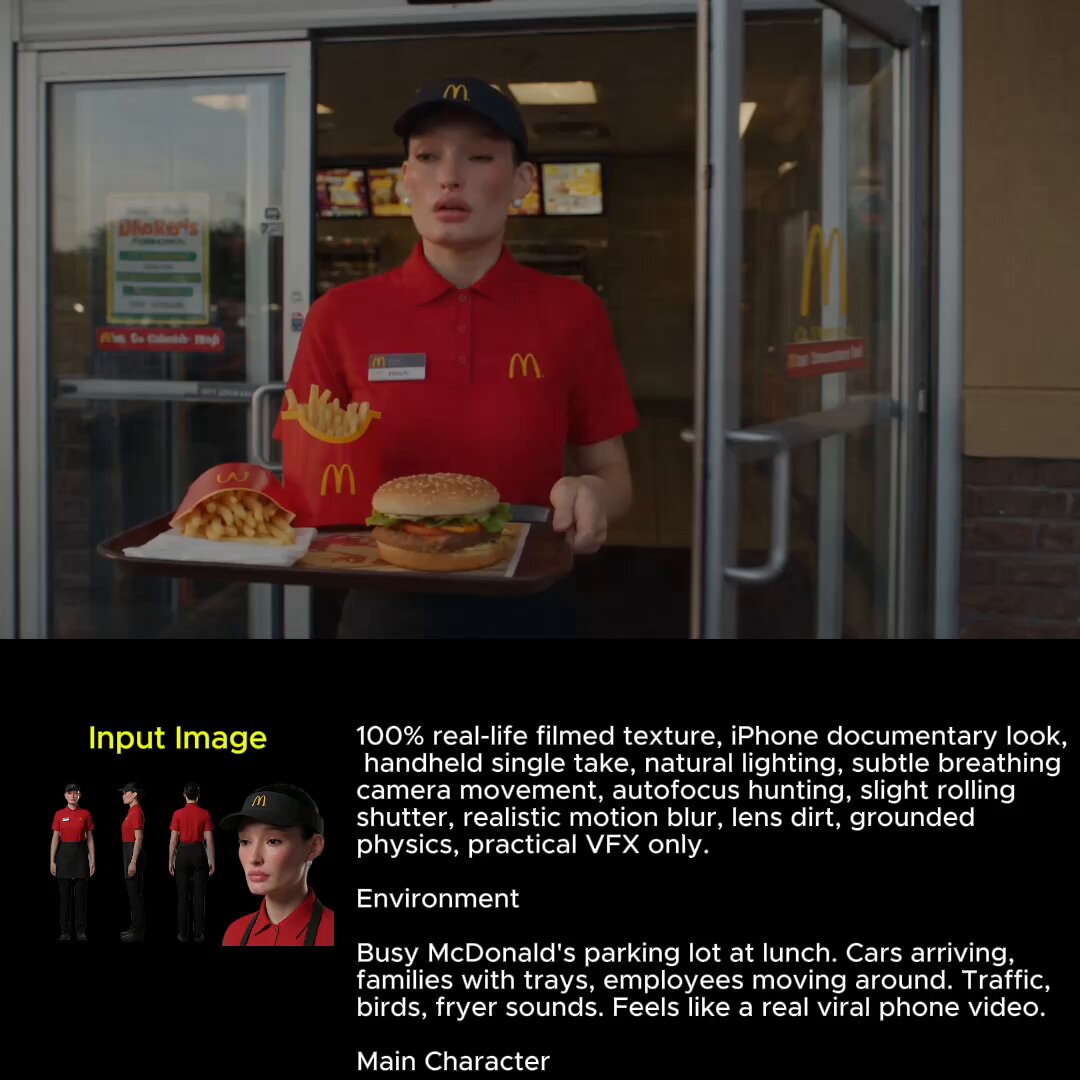
Consistency is the hardest problem in AI-assisted filmmaking, and the solution is preparation rather than luck. Build a character sheet: front, three-quarter, profile, full body, and a neutral expression, all in consistent lighting. Build the same for locations, ideally from two opposing angles so you know where the light comes from.
Then apply these techniques:
- Reference conditioning. Feed the model one or two reference images alongside the prompt. Multi-image conditioning, where the system blends identity from one frame and composition from another, is the most reliable current approach for faces.
- Seed and setting reuse. Lock a seed when you find a take you like, then change only one variable at a time — motion, camera, or lighting.
- Wardrobe and prop anchors. Distinctive but simple elements (a red scarf, a scuffed green toolbox) help the viewer track continuity and help you spot drift.
- Light direction discipline. Identity drift often appears when the light flips from left to right between shots. Note the key light direction in your shot list and repeat it in every prompt for that scene.
- Cut around the problem. If a model cannot hold a face in a wide shot, do not fight it. Show the wide from behind, or cut to a close-up earlier.
Expect imperfect results and design your edit so that continuity errors land on cuts where the audience is already reorienting.
Three animation pipelines and when to use each
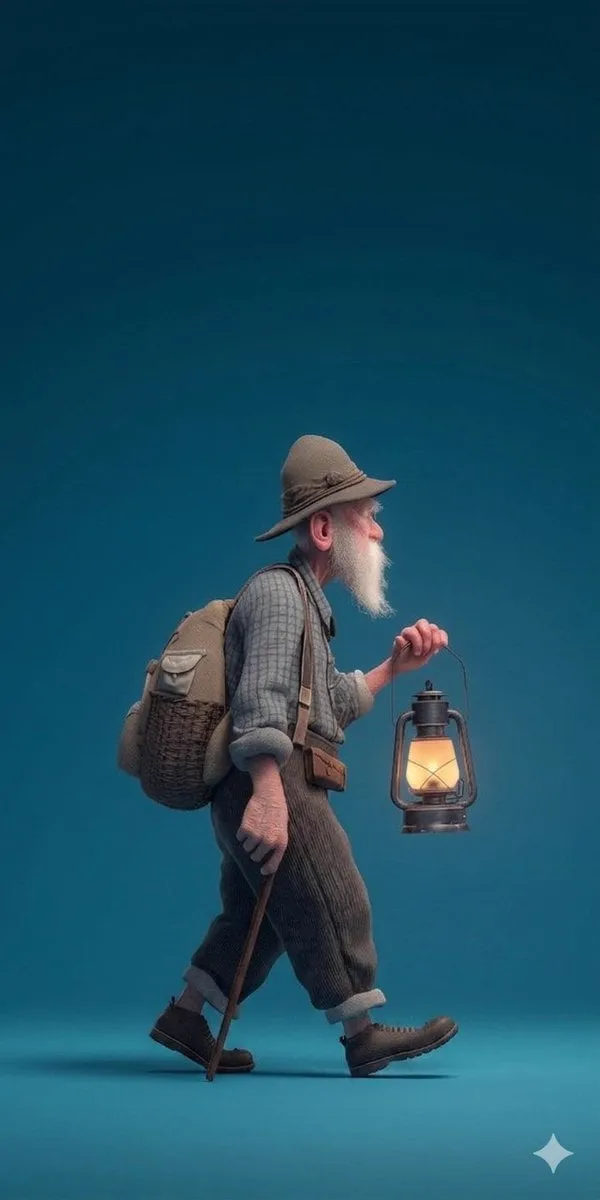
Stylized 2D-feel animation. Flat colors, limited frame rate, graphic shapes. Generative tools handle this well because motion expectations are lower. Best for explainers, social series, and branded shorts where personality matters more than realism.
Hybrid live-action plus generated elements. Shoot or generate a plate, then add generated creatures, weather, crowds, or set extensions. This is often the highest-value use of AI video, because the audience anchors on the real footage while the generated layer adds scale.
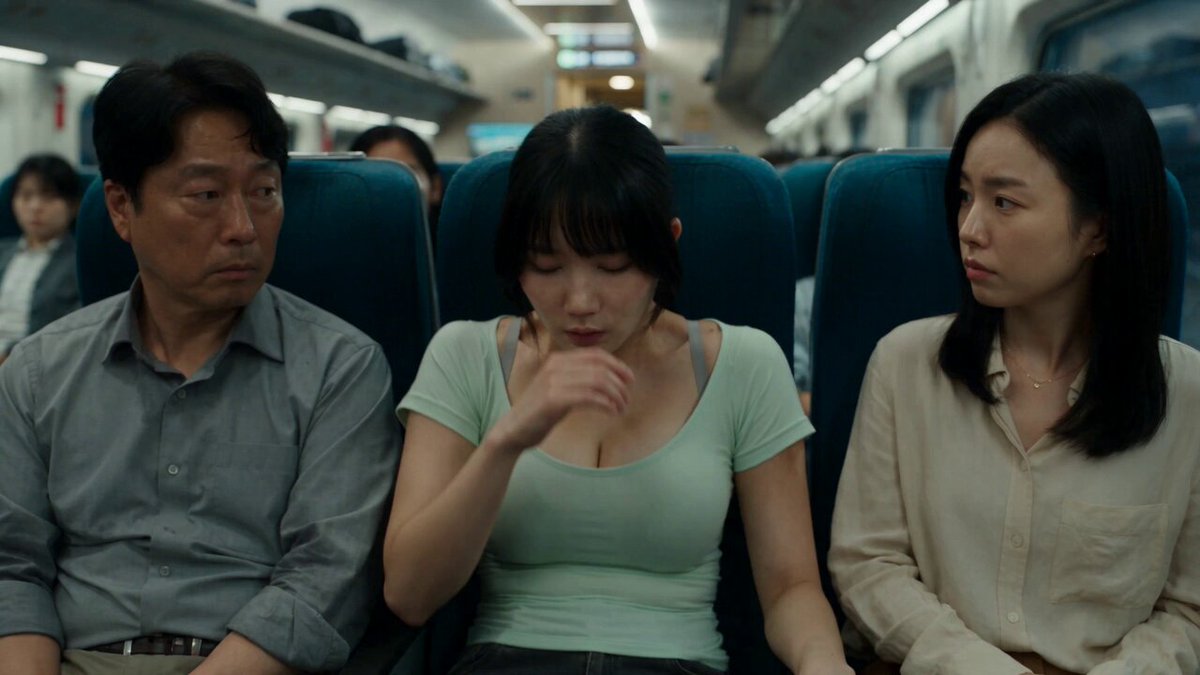
Photoreal full generation. Entire scenes built from prompts and references. Feasible for short pieces, dream sequences, and stylized realism, but demanding. Budget extra time for continuity passes and expect to discard a meaningful share of takes. Treat each shot as a miniature production with its own brief.
A practical rule: the more a shot depends on identifiable human faces and complex hand interaction, the more you should consider hybrid approaches or shooting plates.
Sound, cadence, and finishing
Raw generated footage usually looks like video and feels like animation. Two fixes close most of the gap.
Frame cadence. Many models output smooth high frame rates. Cinematic motion often benefits from a 24-frame-per-second feel, sometimes with slight motion blur. Frame interpolation and retiming tools let you convert a clean 30 or 60 fps render into a filmic cadence, or slow a shot for emphasis.
Texture matching. Add consistent grain across all shots, including any live-action inserts. Generative clips can look sterile next to camera footage; a shared grain and halation pass unifies them.
Color grading. Grade after you assemble. Matching black levels and skin tones across shots hides small model inconsistencies remarkably well.
On the audio side, prioritize room tone, footsteps, cloth movement, and ambience. AI video frequently has no believable diegetic sound, and silence reads as fake faster than imperfect imagery. Music carries emotion, but environmental sound carries realism.
Mistakes that quietly ruin AI-assisted scenes
- Changing too many variables at once. You will not know which change helped.
- Ignoring the first and last frame. Viewers notice the start and end of a clip. Trim into motion rather than letting a shot begin from stillness.
- Overusing camera movement. Constant drifting reads as a technical demo. Let some shots lock off.
- Uniform lighting across a scene. Variation in light creates depth; identical lighting flattens a sequence.
- Trusting the model with story. Models render. They do not stage emotional beats for you.
- Skipping the edit. Many "bad" AI shots work perfectly as two-second inserts inside a well-paced cut.
- Neglecting aspect-ratio framing. Compositions built for widescreen often fail when cropped vertical, so generate for the delivery format.
- No versioning. Without consistent file naming and notes, you will regenerate the same shot twice and lose the better take.
Scaling the workflow for small teams
A three-person team can run a credible AI-assisted production if roles are clear. One person owns look and continuity (references, light direction, wardrobe). One owns generation and iteration (prompting, seeds, takes). One owns assembly and finishing (edit, cadence, grain, grade). Rotate review so that no one signs off on their own work.
Add lightweight quality gates: a previz gate before staging, a staging gate before hero renders, and a continuity gate before finishing. Keep an asset register listing every reference image, seed, and prompt version that produced an approved shot. When a client asks for a change six weeks later, that register saves an entire day.
Finally, batch similar shots. Generate all the close-ups of one character in a single session with identical lighting language. Consistency is easier to maintain within a session than across sessions.
Frequently asked questions
How long should a generated shot be? Most usable shots run two to six seconds. Longer shots are possible but need stronger motion planning and more retakes. If a beat needs ten seconds, consider two shots cut together.
Can I mix models in one project? Yes, and you usually should. Match the model to the shot type — one for photoreal close-ups, another for stylized motion — then unify them in post with grain, cadence, and grading.
Do I need to shoot reference plates? Not always, but plates of your actual location and actors remove an enormous amount of guesswork and improve identity consistency.
What about dialogue and lip sync? Treat it as a separate step. Generate the performance with clear head movement and minimal occlusion, then apply lip-sync tools and check consonants frame by frame.
How do I handle client revisions? Archive prompts, references, and seeds per shot. Revisions then become small parameter changes rather than full regeneration.
Is AI video ready for broadcast work? For inserts, environments, titles, and stylized sequences, yes. For sustained photoreal human performance it still requires careful shot selection and a strong edit.
The takeaway
The teams producing convincing AI-assisted video are not the ones with access to the most models. They are the ones with the tightest process: a shot list, a reference library, progressive quality passes, continuity discipline, and a finishing chain that makes every clip feel like it came from the same camera. Choose tools by motion realism, obedience, texture, and iteration speed — then spend your creativity on staging and editing, where the audience actually lives.
