
Why AI Video Production Became a Pipeline Problem
Two years ago, making a video with generative AI meant typing a sentence and hoping the result looked like something. Today the interesting question is not whether a model can produce a moving image, but how a small team can reliably produce thirty finished shots that share a look, a cast, and a rhythm.
That shift is the whole story. Generative video has moved from demo to discipline. The bottleneck is no longer raw generation capability; it is orchestration — choosing the right model for each shot, keeping characters and lighting consistent between cuts, planning compute so renders finish overnight instead of over three days, and assembling everything with sound that does not feel bolted on.
This guide lays out a neutral, tool-agnostic workflow you can run with whatever model library you have access to. It covers the four production layers, how to pick models by job rather than by reputation, the consistency techniques that separate watchable output from unusable output, what GPU compute actually changes in your day, how a lightweight agent layer can handle repetitive decisions, and a full walkthrough from brief to export.
The Four Layers of a Modern AI Video Workflow
Almost every successful AI video pipeline decomposes into four layers. Teams that skip one of them usually end up redoing work at the end, when fixes are most expensive.
Layer 1: The script and beat layer
This is where you decide what the video is about and how long each beat lasts. A shot list with timecodes is worth more than any prompt library. If a beat runs six seconds, you need a model and a shot design that can hold attention for six seconds — not a ten-second clip you will trim in the edit and lose the punchline of.
Layer 2: The visual layer
This covers keyframes, character sheets, environments, and style references. In most pipelines the work here is image generation, not video generation. Getting a still frame that is exactly right makes the motion step almost trivial; getting a mediocre still and asking a video model to fix it is the most common source of wasted render time.
Layer 3: The motion layer
This is the actual image-to-video or text-to-video step: camera movement, performance, physics, transitions. Motion models are opinionated. Some are excellent at subtle facial performance and terrible at large camera moves. Some handle crowds and wide establishing shots beautifully but drift on close-ups.
Layer 4: The assembly layer
Sound design, music, voice, subtitles, color matching, and pacing. This layer is where perceived quality is won. A slightly soft shot with great sound reads as intentional; a sharp shot with mismatched ambience reads as amateur.
Choosing Models by Job, Not by Hype
A large model library is only an advantage if you know what each model is for. The fastest way to build that knowledge is to classify your shots and then test models against the classes.
Build a shot taxonomy first
Write down the six to ten shot types your project actually needs. A typical commercial or short film uses: establishing wide, medium dialogue, close-up reaction, product insert, transitional movement, and abstract/texture. Once that list exists, run a one-day test: generate three variations of each shot type in three candidate models and score them on prompt adherence, motion realism, and consistency with your reference look.
Match duration, resolution, and latency to the shot
Short social cuts rarely need more than 1080p and a few seconds per shot, and they benefit enormously from fast iteration. Cinematic sequences need higher resolution, longer holds, and more generous render windows. Do not use one setting for everything. A tiered setup — fast and cheap for exploration, slow and heavy for the hero shots — is what keeps a schedule intact.
Think in cost per finished minute, not cost per clip
Generators fail. A useful planning number is the ratio of generated seconds to usable seconds. If it takes four attempts to land a usable six-second shot, your real cost is twenty-four seconds of generation for six seconds of screen time. Track that ratio for each model you use. Some models look cheaper per render and end up more expensive per finished minute.
Consistency: The Hardest Part of AI Video
Viewers forgive imperfect physics. They do not forgive a character whose jacket changes color between two shots in the same scene. Consistency is the single biggest reason AI video projects fail review.
Lock identity with reference images
Before generating any motion, produce a character sheet: front, three-quarter, and profile views, plus two or three expressions, all generated from the same reference and approved by a human. Then feed those approved images into the motion step as conditioning input rather than relying on text descriptions of the character. Text descriptions drift; images anchor.
Use seeds, then stop chasing them
Seeds are useful for reproducibility, not for magic. Locking a seed helps when you want to vary one prompt element and hold everything else steady. It does not guarantee identity across different prompts, and treating it as a consistency solution leads to long, fruitless search sessions. Treat the seed as a version-control tool, not a character-lock tool.
Fusion techniques for multi-reference shots
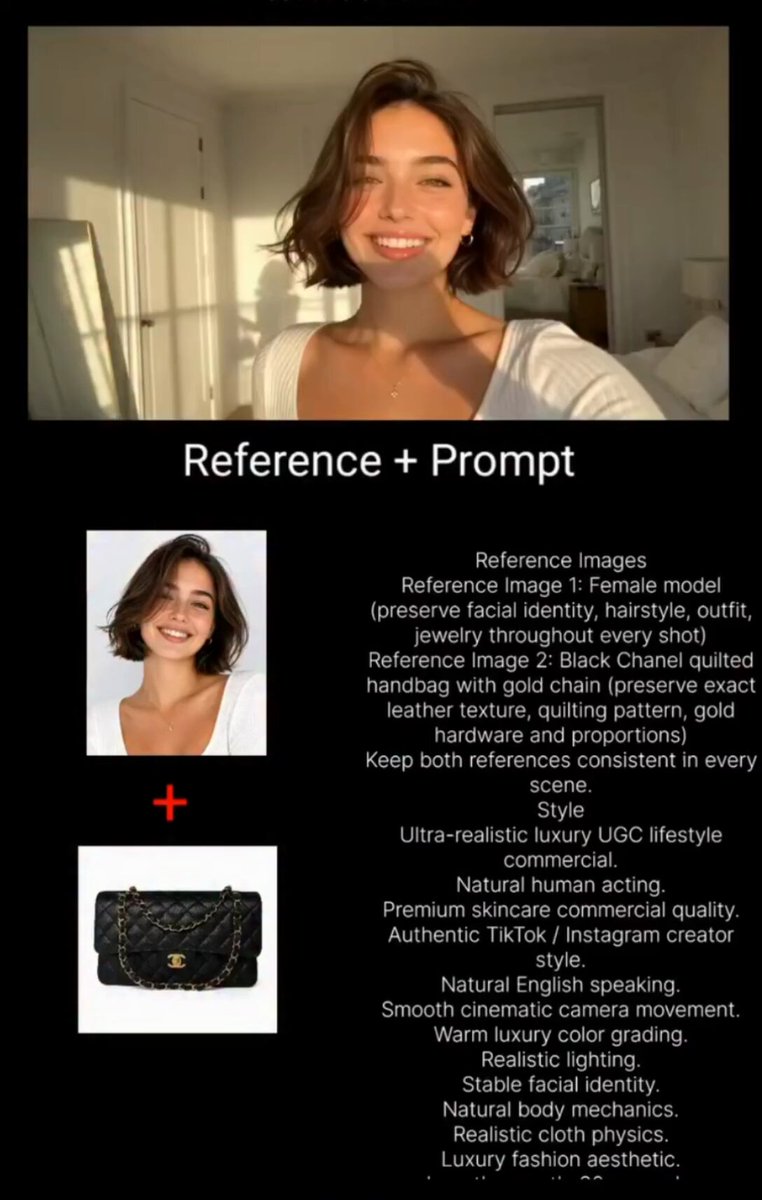
When a shot requires two characters, a specific location, and a particular lighting mood, single-reference conditioning usually breaks. Multi-image fusion — where several reference images are blended to constrain the generation — is the practical answer. Test how your chosen models weight competing references: many privilege the first image, so order your inputs deliberately and verify with a low-resolution draft before committing to a full render.
Keep a look bible
The look bible is one page: color palette, lighting direction, lens character, grain level, aspect ratio, and a handful of approved stills. Every generation gets compared against it. This single document prevents the slow style drift that turns a twenty-shot sequence into a visual collage.
Compute Realities: Where GPUs Actually Matter
You do not need to own a data center to make AI video, but understanding compute changes your scheduling and your model choices.
Training versus inference
Training diffusion and video models requires enormous parallel processing and memory bandwidth; that is why only a handful of organizations train frontier video models. You almost certainly operate in inference territory, where the relevant questions are different: how much VRAM does a model need at your resolution, how long does a batch take, and how much concurrency can you afford.
Local versus hosted inference
Local generation is attractive for privacy, cost predictability at high volume, and offline iteration — but it constrains you to models that fit your hardware and to resolutions that do not blow out memory. Hosted generation gives you access to larger models and faster iteration without capital outlay, at the price of variable latency and network dependency. Many teams run a hybrid: local for drafts and look development, hosted for final high-resolution renders of approved shots.
Batch and queue like a studio
Treat renders as a queue with priorities. Hero shots go first, filler shots are batched overnight, and nothing goes to full resolution until a low-resolution draft has passed review. Schedulers that pause on failure and resume without restarting the whole job save more time than any single model upgrade.
Agentic Direction: Automating the Boring Decisions
An agent layer in a video pipeline is not a replacement for a director. It is a scheduler with taste, handling the repetitive decisions that eat creative hours.
What agents should own
Good candidates: expanding a one-line beat into a structured shot description, generating prompt variants from an approved template, checking outputs against the look bible, flagging shots that fail a similarity threshold, re-running failed generations with adjusted parameters, and assembling first-pass edits to a beat map. These tasks are rule-heavy, repeatable, and easy to audit.
Keep humans at the checkpoints that matter
Approve the character sheet, approve the look bible, approve each hero shot, approve the final sound mix. Everything else can be automated. The rule of thumb: automate anything you would happily let an assistant do twice, and keep the decisions you would want to defend in a client review.
Put guardrails on the agent
An agent that can generate without limits will burn your budget in an afternoon. Set per-shot attempt caps, define a stopping condition (a similarity score, or simply a hard attempt count), and require explicit human sign-off before a job escalates to full resolution. Log every action. When a sequence looks wrong, the log tells you which parameter changed.
A Concrete Production Walkthrough
Here is a full path through a sixty-second piece with eight shots, using the layers above.
Step 1: Brief and beat map
Write the objective, audience, and one-sentence takeaway. Then break the minute into eight beats with timings. Two seconds for the hook, six to eight seconds per body beat, three seconds for the closing call to action.
Step 2: Shot list and layer assignment
For each beat, define shot type, camera movement, subject, and which layer carries the emotional weight. Mark which shots are hero shots — usually two or three — and which are connective tissue.
Step 3: Look development
Generate six to ten stills that establish the palette and lighting. Pick three and write the look bible. This is the step teams skip and regret.
Step 4: Character and location sheets
Approve identities and environments as stills before any motion generation happens. Save every approved reference with a clear filename and version number.
Step 5: Low-resolution motion drafts
Generate short, low-resolution motion passes for every shot. Score them against the look bible. Reject fast. The goal here is to eliminate bad ideas before they get expensive.
Step 6: Hero renders
Take approved drafts to full resolution with final parameters. Render hero shots first, and let connective shots batch overnight.
Step 7: Sound and voice
Record or generate voice, then cut to the voice rather than cutting picture and fitting voice later. Add ambience per shot, then a music bed, then mix. Sound is often the difference between a sequence that reads as a sequence and one that reads as unrelated clips.
Step 8: Assembly and color
Match exposure and color across shots so cuts do not jump. Add transitions sparingly — hard cuts with matched motion are usually stronger than any cross-dissolve.
Quality Control Checklist and Common Mistakes
Run this before you export anything.
- Identity: does every character look like the same person in every shot?
- Continuity: do wardrobe, props, and location details hold across cuts?
- Motion: are hands, faces, and fast movement free of obvious warping?
- Physics: do objects obey gravity and contact realistically?
- Text: if on-screen text or signage appears, is it legible and correct?
- Pacing: does each shot earn its duration?
- Sound: does ambience match the visual space, and are levels consistent?
- Framing: do you have safe margins for captions and platform crops?
The recurring mistakes are predictable. Generating motion before locking stills. Using one model for every shot type. Skipping low-resolution drafts. Forgetting that a shot will be cropped for vertical platforms. Rendering the whole timeline at maximum resolution when only three shots need it. And treating sound as an afterthought, which is the fastest way to make technically impressive footage feel unfinished.
Distribution: Aspect Ratios, Subtitles, and Delivery Specs
Plan delivery at the brief stage, not at the end. A sixteen-by-nine master usually needs a one-by-one and a nine-by-sixteen version, which means your framing must survive a center crop or you must generate alternate compositions for key shots.
Subtitles should be burned in for social and delivered as a sidecar file for platforms that support them. Keep captions inside safe margins, use a font with clear weight at small sizes, and avoid covering faces. If your video will play without sound in a feed, design the first two seconds to work silently — visually distinctive, text-forward, no dialogue-dependent setup.
Export specs worth standardizing: high-bitrate master at production resolution, a compressed delivery version for each target platform, and a short version for cut-downs. Store the project file with all reference images and prompts so a future revision is a rerender, not a rebuild.
FAQ
How many models do I really need?
Three to five, chosen by shot type, outperform a sprawling library you have not tested. Coverage matters less than knowing which model handles your close-ups, which handles motion, and which handles stylized texture.
Do I need a powerful GPU to start?
No. Start with hosted generation to learn the workflow, then move high-volume or privacy-sensitive work local if the economics justify it. Learn the pipeline before you optimize the hardware.
How do I keep characters consistent across many shots?
Approved reference images plus a written look bible plus multi-reference conditioning for complex shots. Text-only character descriptions will drift within a handful of generations.
Is an agent layer worth the setup effort?
If you produce more than a couple of videos a month, yes. Prompt templating, output checking, and retry logic are mechanical tasks that compound savings quickly. Below that volume, a good checklist is enough.
How long should a shot be?
As short as the beat allows. Three to six seconds covers most narrative material; longer holds demand either strong performance or deliberate atmosphere. When in doubt, cut earlier.
What is the most common reason AI video looks amateurish?
Inconsistent identity and unmotivated sound. Fixing those two issues improves perceived quality more than any resolution increase.
Where to Start This Week
Pick one thirty-second idea, build a six-shot beat map, and run the full pipeline end to end — stills, sheets, drafts, hero renders, sound, export. The point is not the video. The point is discovering where your own workflow breaks: which model needs a better reference, which step needs a human checkpoint, which render queue needs prioritizing.
Once you have one finished piece, the second one takes half the time, because the look bible, the character sheets, and the prompt templates already exist. That compounding asset library, not any single model release, is what turns AI video from an experiment into a production capability.
