
Why Shorts and Reels Reward a Workflow, Not a Single Tool
Vertical short-form video is a delivery format with brutal constraints. The frame is 9:16, the first second is often watched on mute, and a meaningful share of viewers decide whether to keep watching before the first cut even lands. That means the thing you are optimizing is not "video quality" in the abstract — it is retention density: how much signal you compress into every 1.5 seconds.
Most creators approach AI video backwards. They start by asking which generator is best, then try to force an idea through it. The result is a folder of beautiful clips that do not add up to a watchable video: the character changes faces between shots, the lighting shifts three times in ten seconds, the music fights the voiceover, and the hook arrives at second four instead of second zero.
A better mental model is to treat generation models as interchangeable camera units. A camera does not decide what the story is; it executes a shot list. When you build a repeatable pipeline — concept compression, shot planning, model matching, consistency locking, sound design, assembly, QC — swapping a generator in or out becomes a minor decision instead of a rewrite.
This guide lays out that pipeline in practical terms. It assumes you already have access to one or more text-to-video and image-to-video tools and want to produce Shorts, Reels, and similar vertical formats on a schedule without burning entire days per clip.
The Five-Stage AI Video Pipeline at a Glance
Before the detail, here is the spine of the workflow. Each stage has a clear output, and no stage should be skipped because "the AI will handle it."
| Stage | What you produce | Typical time |
|---|---|---|
| 1. Concept compression | A one-sentence promise plus a shot list | 10–20 min |
| 2. Model matching | A per-shot tool assignment | 5 min |
| 3. Generation | 2–4 candidate clips per shot | 20–60 min |
| 4. Sound and pacing | Voiceover, music bed, SFX, captions | 20–40 min |
| 5. Assembly and QC | Final vertical master plus platform variants | 20–30 min |
The important property of this pipeline is that it front-loads decisions. Ninety percent of the frustration people associate with AI video comes from discovering a structural problem — wrong aspect rationale, inconsistent subject, unusable motion — after twenty generations have already been spent.
If you only adopt one habit from this article, adopt this: never generate a shot you have not written down first. A shot list turns generation from an act of exploration into an act of production, and production is what scales.
Stage 1 — Compress the Idea Before You Generate Anything
Short-form does not reward explanation. It rewards a single promise delivered fast and then paid off. So the first stage is not writing; it is deleting.
Take your idea and force it into one sentence of the form: "If you watch this, you will [specific payoff] in [timeframe]." If you cannot fill in the brackets, the idea is not ready for generation. "Cool AI visuals of a city" fails this test. "Watch a rain-soaked Tokyo alley transform from sketch to photoreal in fifteen seconds" passes.
Hook formulas that survive a mute-first feed
Because many viewers start muted, the hook has to work visually. Three reliable structures:
- Transformation hook: Show the end state in frame one, then rewind to the process. Works extremely well with image-to-video because your first frame is a deliberate still.
- Anomaly hook: Something is subtly wrong. A person walking normally while the background flows backward. The brain stays to resolve the mismatch.
- Promise hook: A bold text overlay plus a single strong visual. Keep the overlay to five words or fewer.
Avoid "Hey guys, welcome back" openers and any setup that requires context. In a 30-second vertical edit, you have roughly eight shots. Every one of them must earn its place.
Write a shot list, not a script
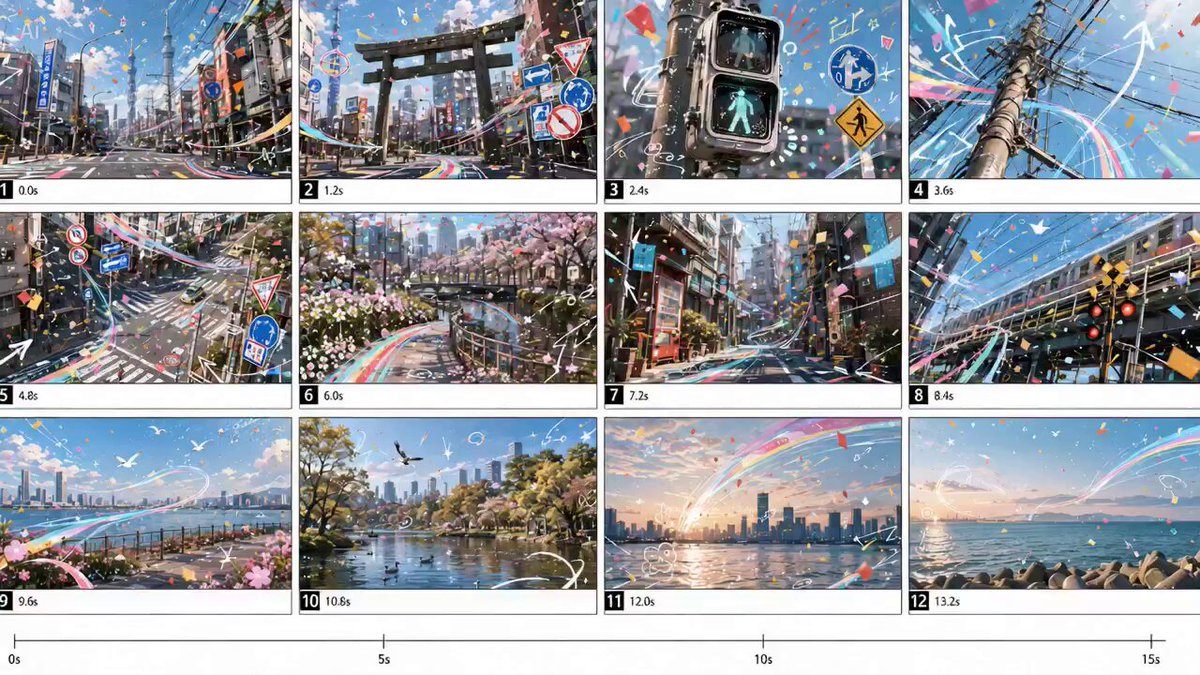
Replace the script with a table: shot number, duration, subject, action, camera, and the tool you plan to use. Eight rows for a 30-second video, twelve to sixteen for a 60-second one. Assign durations in whole seconds and force the total to match your target runtime exactly.
This single artifact is what makes the rest of the pipeline deterministic. It also makes revision possible: when shot 5 fails, you regenerate shot 5, not the whole video.
Stage 2 — Match the Model to the Shot
Different generators have genuinely different personalities. Some are cinematographers — slow, deliberate, physically plausible camera moves. Others are stylists — fast, expressive, forgiving of impossible geometry. Others are best at interpreting a still image and adding motion without redesigning the subject.
The practical mistake is using one model for everything because it is familiar. The production habit is to assign per shot, based on what each shot needs to do.
Text-to-video versus image-to-video
Use text-to-video for establishing shots, abstract transitions, and anything where you do not have a reference yet. Use image-to-video whenever a shot must match something you already approved: a product, a character, a location, a color palette. Image-to-video is the single most effective consistency tool available, because it constrains the model's starting state instead of hoping it converges to the right one.
A useful rule: if the shot contains a face, a logo, or a hero object, it should almost always be image-to-video, seeded from a frame you generated or photographed deliberately.
Motion budget and duration discipline
Most vertical AI shots should be 2–4 seconds. Long generative clips drift, warp, and accumulate artifacts. Short clips hide imperfections and cut faster, which raises perceived energy.
Also budget motion explicitly. Write the camera move into the prompt in plain terms — "slow dolly in," "static locked-off frame," "handheld follow" — and keep one primary motion per shot. Two competing motions (camera push plus subject spin plus background parallax) is the most common cause of mushy, unusable output.
Finally, generate in the native aspect ratio the model handles best, then crop deliberately in post rather than asking for a stretched 9:16 render. Cropping a wider frame into vertical gives you the freedom to reposition the subject and add headroom for captions.
Stage 3 — Engineering Consistency Across Clips
Consistency is not a prompt trick. It is an asset-management discipline. If you can hold subject, lens language, and color constant across clips, viewers will read your video as professionally produced even when individual shots are imperfect.
The anchor-frame method
Generate one reference frame per scene — a clean, well-lit image of the subject or location. Approve it. Then derive every clip in that scene from that anchor, either by animating it directly or by using it as a visual reference alongside your prompt. When a clip drifts too far, your anchor tells you immediately what "correct" looks like, and regeneration becomes a targeted fix.
Keep anchor frames in a dedicated folder with naming like scene02_anchor_v3.png. Version them. Do not overwrite. The fastest way to ruin a session is to lose the one image that was working.
Lock lens language and color early
Write down three constants for the whole video and repeat them in every prompt: lens and framing, light direction, and color treatment. For example: "35mm, shallow depth of field, soft window light from camera left, cool teal shadows, warm skin tones." Repeating these constants does more for perceived cohesion than any single high-end model upgrade.
In post, apply one shared color grade and one grain or texture layer across every clip. This is the oldest trick in editing and it still works: a uniform grade makes mismatched sources feel like one film.
Stage 4 — Sound, Pacing, and the Mute-First Feed
Video generation gets the attention, but audio decides retention. A weak audio mix will sink a visually excellent edit, and a strong one can carry merely adequate visuals.
Voiceover, timing, and lip-sync realism
If the video has narration, cut the audio first and place visuals against it. Do not animate a mouth to match audio you have not finalized. Where lip-sync is required, keep the speaking shot short — two to three seconds — and cut away before sync errors become visible. Where lip-sync is not required, prefer voiceover over a visible speaker; it removes an entire class of failure.
Write narration for the ear: short clauses, active verbs, no subordinate stacking. Read it aloud with a timer. If it runs long, cut words rather than speeding up delivery.
Music, ducking, and the three-second rule
Choose music that establishes its energy within three seconds; slow-building ambient tracks lose the mute-first audience. Then duck the music under the voice by 6–10 dB rather than lowering the whole bed. Add two or three sound effects — a whoosh on a transition, a click on a text reveal, a low impact on the hook — placed deliberately, not continuously.
Captions are not optional. Burn them in, keep them inside the central safe zone so platform UI does not cover them, and use no more than two lines at a time. Match caption style to the video's grade so text feels designed rather than appended.
Stage 5 — Assembly, QC, and Export
Assembly is where you enforce rhythm. Place clips on the timeline in shot-list order, then watch once at full speed without stopping. Do not fix anything during this pass. You are looking for structural problems: a hook that lands late, a shot that overstays, a section without any change in visual intensity.
The artifact checklist
Before you call a shot done, check it against a short list: warping faces, melting hands, text that mutates between frames, background geometry that breathes or shimmers, and shadows that point in two directions. If two or more appear, regenerate rather than repair — AI artifacts rarely survive a color grade.
Export settings and platform variants
Export a vertical master at the highest resolution your editing setup handles comfortably, then create platform variants from it. Keep a version with captions and one without, so you can reuse the footage in different placements. Check the first frame as a static thumbnail — many viewers effectively see it as a cover image before playback begins.
A Worked Example: 45-Second Vertical Product Story
Suppose you are making a 45-second vertical video for a compact camera gimbal.
Shots 1–2 (0:00–0:05) are the transformation hook: a chaotic handheld clip that stabilizes into a locked, cinematic frame. Both shots are image-to-video, derived from two anchor stills of the same street corner. Shot 3 (0:05–0:10) is a close-up of the gimbal's joint rotating — image-to-video from a product photo, static camera, one motion only.
Shots 4–7 (0:10–0:30) demonstrate three use cases: running, cycling, and a low-angle walking shot. Text-to-video is fine here because no faces or logos are visible; the anchor stills only need to share lens language and grade. Shot 8 (0:30–0:38) returns to the product for the payoff claim. Shots 9–10 (0:38–0:45) are the call to action over a slow push-in on the hero frame.
Total generation budget: roughly 20 candidate clips for 10 used shots, which is a realistic two-to-one hit rate once anchors and prompt constants are in place. Voiceover was recorded and locked before any clip was generated, so pacing was never a guess. Music ducking was set once, and three SFX were placed at the two transitions and the hook.
The point of the example is not the product. It is that every creative decision was made in a document before it was made in a generator.
Common Mistakes That Kill Retention
- Starting with the tool, not the promise. The hook is a writing problem, not a model problem.
- One motion too many. Two simultaneous camera or subject moves produce mush.
- No anchor frames. Without a reference, consistency becomes luck across a session.
- Ignoring the audio timeline. Visual edits made before the voiceover is locked almost always get recut.
- Overlong shots. If nothing changes for four seconds in a vertical video, you have lost momentum.
- Captions outside the safe zone. Platform interfaces eat the bottom and right edges.
- Grading each clip separately. One shared grade across all clips is what sells cohesion.
- Skipping the full-speed watch-through. Stopping to fix each clip as you assemble hides pacing problems until export.
Budgeting Time, Compute, and Revision Passes
Treat generation allowance the way a film production treats film stock: as a finite resource that rewards planning. A reliable pattern is three passes. Pass one is exploratory — low resolution, short duration, finding out what the model does with your prompt. Pass two is the production pass at final quality, using anchors. Pass three is the repair pass, regenerating only failed shots.
Time-wise, expect the first video in a new format to take three to four times longer than the tenth. The investment is in the artifacts — anchor frames, prompt constants, caption templates, export presets — which are reusable. Once those exist, a 45-second vertical video is often a two-hour job rather than a two-day one.
Frequently Asked Questions
How many shots should a 30-second vertical video have?
Eight is a comfortable target, averaging just under four seconds each. Shorter shots feel more energetic but demand more generation work; longer shots are easier to produce but harder to keep interesting.
Is text-to-video or image-to-video better overall?
Image-to-video wins on consistency and control, which matters more in short-form. Text-to-video is faster for exploration and for shots without recurring subjects.
Do I need a different tool for every shot type?
No, but assign deliberately. Use one model for establishing shots, one for character or product shots, and a stylized model for transitions. The assignment matters more than the brands.
How do I stop characters from changing between shots?
Anchor frames plus repeated prompt constants. Derive every clip from an approved reference and repeat lens, light, and color language verbatim in each prompt.
What aspect ratio should I generate in?
Generate in the ratio the model handles best — often 16:9 or 1:1 — then crop to 9:16 in post. This gives you repositioning freedom and headroom for captions.
Why does my video look generically "AI"?
Usually flat lighting plus uniform sharpness plus no grain. Add a light direction, a shallow depth-of-field feel, a shared grade, and slight texture. Specificity is what reads as intentional.
How long should the hook be?
One shot, two seconds at most, and it should be visually legible with the sound off.
Can I reuse clips across platforms?
Yes, and you should. Export a captioned vertical master plus a clean version, then adapt captions and length per platform rather than regenerating footage.
Pre-Publish Checklist
Before you upload, confirm: the hook lands within two seconds, every shot has a single primary motion, all clips share one grade and one grain layer, the voiceover is locked and the music is ducked, captions sit inside the safe zone, the full-speed watch-through produced no urge to skip, and the first frame works as a static cover image.
If all eight are true, you have a video that a generation model helped you make — not a video a generation model made for you. That distinction is what separates a channel that scales from a folder of pretty clips.
