
Generative video stopped being a novelty the moment teams realized they could storyboard on Monday and screen a rough cut on Friday. The bottleneck is no longer whether a model can produce motion. It is choosing the right model for each shot, prompting it precisely, and stitching the results into something that feels intentional rather than assembled.
Why a Multi-Model Workflow Beats Loyalty to One Tool
Every video model has a personality. One renders skin and fabric with startling realism but drifts off-brief whenever you ask for a camera move. Another nails stylized motion and choreography but softens faces at distance. A third handles product close-ups beautifully and falls apart on crowds. None of them is universally best, and the gap between them is widest exactly where budgets are tightest: hero shots that carry the story.
A single-tool habit forces your idea to bend toward whatever that tool does well. You end up writing around its weaknesses. A multi-model workflow flips the relationship. You define the shot, then ask which engine gives the best first attempt, which one gives the most controllable iteration, and which one gives the cleanest final frame at delivery resolution.
There is a second, less obvious benefit: redundancy. Models change, rate limits shift, and a style that looked fresh six months ago starts to feel like a template. When your pipeline assumes two or three viable engines per shot type, a disruption becomes an inconvenience instead of a shutdown.
The practical takeaway is not to collect tools. It is to define a small set of jobs, assign a primary and a backup engine to each, and document the prompt patterns that work. That document becomes the most valuable asset on your team, more than any individual render.
Mapping Your Project to the Right Model Category
Before prompting anything, sort your shot list into jobs. Shots that look similar on the page often need completely different model categories.
The five jobs that cover most projects
Concept and mood exploration. Fast, cheap, low-resolution generation used purely to test whether an idea reads on screen. Quantity matters more than polish here.
Image-to-video animation. You already have a still frame — a photograph, a product render, a hand-drawn keyframe — and you need believable motion inside it. This is the workhorse category for controlled composition.
Motion and pose transfer. You supply a reference performance or a movement pattern and want it applied to a new subject or style. Useful for dance, sport, and any shot where gesture matters more than environment.
Style and look transfer. You want the texture, palette, or rendering language of one reference applied to new content. Often better handled as a pass over finished footage than as the first generation step.
Restoration, upscaling, and frame interpolation. The cleanup category. Slow motion, resolution lift, and artifact reduction that turn an acceptable generation into a deliverable.
Matching jobs to engines
Once the jobs are labeled, evaluate engines per job rather than per brand. Run the same three test shots through each candidate and score them on four criteria: fidelity to the brief, motion coherence, consistency across a second generation of the same prompt, and how much correction the output needs afterward. The last criterion is the one teams forget, and it usually decides the winner.
Writing Briefs That Models Can Actually Follow
Most disappointing output comes from an ambiguous brief, not a weak model. A model cannot guess your intent; it can only weight the words you give it.
The shot brief template
Write each shot as five lines, in this order:
- Subject — who or what, including age, wardrobe, and any distinguishing detail.
- Action — one primary verb, plus a secondary micro-action for liveliness.
- Environment — location, time of day, weather, and background activity.
- Camera — framing, angle, movement, and lens character.
- Look — lighting, palette, film or sensor character, and overall mood.
Keep the total under about ninety words for the first attempt. Long prompts dilute attention; add detail only after you see what the model misread.
Reference images do more than adjectives
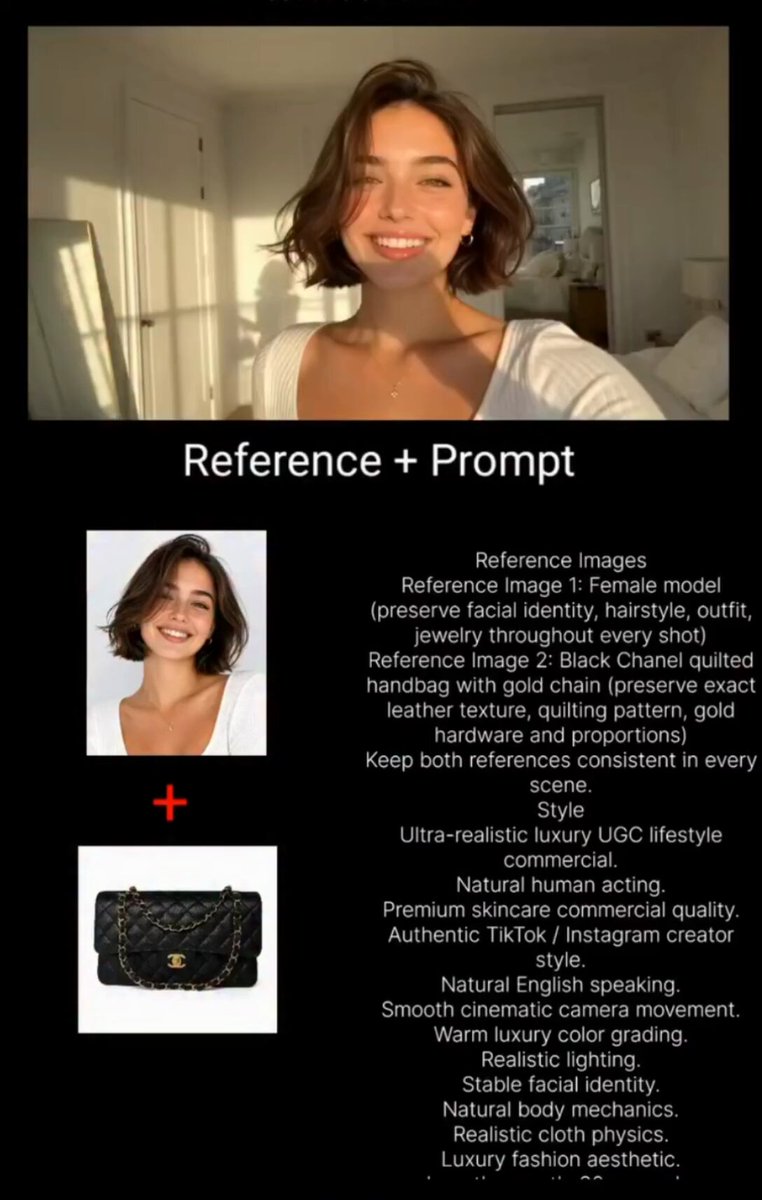
A single well-chosen reference frame often communicates more than three sentences of description. Supply references for composition and lighting separately from references for subject identity. Mixing them in one image teaches the model to copy the whole frame, including the parts you wanted to change.
Negative prompts as guardrails
Maintain a reusable negative list per project: extra fingers, warped text, duplicate limbs, drifting background architecture, sudden lighting shifts, watermarks, and unwanted on-screen captions. Trim it when the model starts obeying the negative too literally, which tends to flatten the image.
Character Consistency Across Shots
Consistency is where generative pipelines earn or lose trust. A viewer forgives a slightly soft frame; they do not forgive a face that changes between cuts.
Anchor frames beat descriptions
Pick one frame per character as the canonical anchor: neutral expression, even lighting, clear view of the face, and the actual wardrobe. Generate every subsequent shot using that anchor as a reference. When a scene requires a different outfit or lighting state, produce a new anchor for that state rather than describing the change in text.
Multi-image references for three-quarter and profile views
Feeding two or three angles of the same person dramatically improves stability when the character turns or walks. If the model supports multi-image conditioning, use it. If it does not, generate the turn as two shorter shots and cut between them rather than asking for one continuous rotation.
Lock what does not change
Wardrobe, key light direction, lens choice, and color temperature should stay constant within a scene. Write them once in a scene header and copy that header into every shot prompt. Most apparent inconsistency is actually the model obeying a different set of adjectives.
Knowing when to train or fine-tune
If a character appears in more than a dozen shots, a dedicated fine-tune or a reusable character asset is usually cheaper in time than repeated reference-conditioning. Below that threshold, anchors plus disciplined prompts are faster.
Speaking Cinematography: Lenses, Motion, and Aesthetics
Models respond surprisingly well to real camera vocabulary, and badly to vague intensity words.
Camera language that works
- "slow dolly in, 35mm, shallow depth of field"
- "handheld medium shot, slight sway"
- "static wide, deep focus, symmetrical composition"
- "crane up revealing the street below"
- "macro detail, focus rack from fabric to face"
Each phrase implies both a movement and a visual character. That is exactly the kind of compression a model can act on.
The motion-strength problem
When a shot looks unnatural, the instinct is to add more movement description. Usually the opposite helps. Reduce motion intensity, shorten the duration to three or four seconds, and let editing create the sense of speed. Generative models degrade fastest when asked to sustain complex motion for a long take.
Aesthetic control without clichés
Describe light rather than mood labels. "Low sun raking across the room, warm highlights, cool shadows" gives the model something concrete. "Cinematic" gives it an average of everything, which is why so many generations look interchangeable.
A Practical Production Pipeline, Step by Step
This is the sequence that keeps quality high without burning days on exploration.
Step 1: Script and shot list
Cut the script into shots of three to six seconds. Anything longer should be split or planned as a camera move within a single generated clip. Note for each shot whether it is a hero shot, a connective shot, or a texture insert. Hero shots get the most attempts and the highest settings.
Step 2: Look development
Generate twenty to forty still frames before touching video. Stills are fast, and they force you to settle palette, lighting, and composition while changes are cheap. Approve a look board, then treat it as the contract for everything that follows.
Step 3: Blocking with draft generations
Produce every shot at low resolution and short duration. The goal is rhythm and coverage, not detail. If the cut does not work at draft quality, it will not work at delivery quality either.
Step 4: Hero shots at full settings
Only once the edit locks, regenerate the hero shots with the best engine for each job, more attempts, and longer prompts refined from what the drafts revealed. Expect to keep roughly one in four attempts; plan accordingly.
Step 5: Assembly and repair passes
Bring everything into the edit, cut to the beat, and mark the shots that fail on close inspection. Repair passes — inpainting a hand, stabilizing a background, replacing a single frame — are far cheaper than regenerating whole clips.
Quality Control: Common Artifacts and Fixes
A short diagnostic list saves hours of guessing.
| Symptom | Likely cause | First fix |
|---|---|---|
| Faces change between shots | Weak identity anchoring | Add a canonical anchor frame per character |
| Limbs warp mid-motion | Too much motion in one take | Shorten clip, reduce motion strength, cut sooner |
| Background architecture drifts | Overloaded prompt | Simplify environment description, add negative terms |
| Motion looks floaty | Missing physical reference | Use motion transfer or add contact points and weight cues |
| Text and logos melt | Model limitation | Generate clean plates, add graphics in the edit |
| Colors shift across a scene | Inconsistent prompt headers | Freeze lighting and palette language per scene |
Mistakes that quietly cost days
Skipping look development and jumping straight to video. Rewriting prompts from scratch instead of iterating one variable at a time. Judging a shot from one attempt. Chasing a perfect generation when a two-second repair pass would solve it. And leaving sound design until the end, when it is the fastest way to make an average shot feel intentional.
Editing, Sound, and the Finish Line
Generative output is raw material. The edit is where it becomes a film.
Cut on motion. If a clip drifts in its final second, trim before the drift rather than trying to fix it. Use J-cuts and L-cuts to smooth transitions between shots generated by different engines, since audio continuity masks visual discontinuity better than any transition effect.
Sound carries more weight than most creators expect. Ambient beds, Foley for footsteps and fabric, and a consistent room tone make separately generated shots feel like one location. Music should be chosen before the final color pass, because pacing decisions follow rhythm.
Finish with a light grade. Apply one unified look across all shots — slight contrast curve, matched white balance, subtle grain — so that differences between engines read as film grain rather than inconsistency. Add titles and any graphic elements as an overlay pass so you never depend on a model to render text.
Deliver at the highest practical resolution, then create platform-specific crops. Vertical, square, and widescreen versions should be framed deliberately in the edit, not cropped blindly, because generative compositions often place the subject off-center.
Budget, Time, and Scaling Decisions
Plan production in passes rather than in total attempts. A reasonable split is 60 percent of your generation volume on drafts, 30 percent on hero shots, and 10 percent on repair work. If drafts are eating more than that, your prompts are not specific enough yet.
Track time per finished second of footage. A healthy benchmark for a small team is two to four hours of work per finished second on a polished piece, including prompting, review, and editing. When a single shot exceeds that, switch engines or simplify the shot rather than grinding.
Scale by templating. Once a project type works — product spot, explainer, social teaser — turn its shot briefs, negative lists, and look board into a reusable kit. The second project of the same type should take a fraction of the first.
Finally, keep a decision log. Note which engine won each shot job and why. Two weeks later that log is the difference between a fast production and relearning the same lessons.
FAQ
How many video models do I actually need?
Two or three well-understood engines cover most work: one strong at photoreal human motion, one strong at controlled image-to-video, and one strong at stylized or effects-driven shots. Add a restoration or upscaling tool and you have a complete kit.
Should I generate long clips and cut them down?
Rarely. Short generations with deliberate trimming produce better motion and give you more editing options. Think in shots, not scenes.
How do I keep characters consistent on a tight schedule?
Lock a single anchor frame per character and per wardrobe state, reuse a scene header for lighting and lens language, and avoid re-describing the character in every prompt. Consistency comes from repetition of a fixed brief, not from richer description.
What is the biggest beginner mistake?
Treating generation as the whole job. Generation is roughly a third of the work; look development, editing, and sound design determine whether the result feels professional.
Can I mix engines within a single scene?
Yes, and you should when it improves a specific shot. Match color temperature, grain, and lens character in the grade, and use audio continuity across the cut. Viewers notice inconsistent light far more than they notice a different rendering engine.
How do I evaluate a new model quickly?
Run the same three shots — a dialogue close-up, a moving subject, and a wide environment — through it, generate each twice, and compare consistency between attempts. If the second attempt drifts noticeably from the first, the model will be hard to use in production regardless of how good a single frame looks.
