
Why Short Video Still Rewards Craft Over Novelty
Generative video tools have collapsed the distance between an idea and a watchable clip. A single sentence can now produce a camera move that once required a dolly, a gimbal, and a very patient assistant. That convenience hides a hard truth: audiences do not reward the tool, they reward the result. A technically impressive AI clip that opens with three seconds of nothing still loses to a phone-shot clip that grabs attention instantly.
The practical implication is that AI has not replaced short-video craft. It has raised the cost of skipping it. When generation is fast and cheap, the bottleneck moves downstream: to scripting, shot planning, consistency management, and editing judgment. Creators who treat AI as a camera — something you point deliberately at a planned shot — consistently outperform creators who treat it as a slot machine.
This guide lays out a repeatable production system for AI-assisted short video. It covers hook design, shot planning, character and style consistency, model selection, first-frame/last-frame control, pacing, quality gates, common failure modes, and a lightweight publishing loop. Everything here applies whether your output is vertical social clips, product demos, explainers, or narrative shorts.
The Three-Second Contract: Designing Hooks That Survive Muting
Every short video makes an implicit contract in its opening moments: stay with me and you will get something worth the next thirty seconds. If the first three seconds are generic, the contract is void and the viewer scrolls. This rule has not changed — what has changed is that AI makes it easy to produce an enormous number of mediocre openings, so the bar for a good one feels higher.
Hook patterns that work across niches
Strong hooks usually fall into a handful of recognizable shapes. You can reuse these shapes endlessly as long as the content underneath them is specific.
- The interrupted action. Start mid-motion: a hand pulling something back, a door already opening, a kettle mid-pour. Motion implies a story already in progress.
- The contradiction. State something that sounds wrong and immediately justify it. "The cheapest setup produced the best footage — here is why."
- The visible result first. Show the finished cake, the finished render, the finished room. Reverse-engineer the process afterwards.
- The question with a stake. Not "have you tried this?" but "why does this fail every time you try it in low light?"
- The count or constraint. "Three rules, thirty seconds." Constraints set expectations and give viewers a reason to stay to the end.
What all of these share is specificity. "Amazing AI video" is not a hook. "This prompt made the character stop blinking" is.
Testing hooks without reshooting
One advantage of AI-heavy production is that hooks are now cheap to iterate. If your opening shot is generated rather than filmed, you can produce four or five alternative first clips from the same script and test them against each other. A practical routine:
- Write the hook in text first, three variants minimum.
- Generate a four-second clip for each variant using the same character reference.
- Assemble four versions of the video that are identical after second four.
- Publish or preview all variants and compare retention at the three-second mark.
Keep the winning hook shape in a swipe file. Over a few months you will build a personal library of openings that work for your audience, which is far more valuable than any generic template.
Pre-Production: Building a Shot Plan Before You Generate
The most common cause of wasted generation time is starting with a vibe instead of a plan. A shot plan does not need to be elaborate — six to ten lines is enough — but it must exist before you open a generation tool.
The six-shot skeleton for a thirty-second clip
A reliable default structure for a short piece:
| Shot | Function | Typical length |
|---|---|---|
| 1 | Hook — mid-motion or visible result | 2–4s |
| 2 | Context — who, where, what problem | 3–5s |
| 3 | Escalation — the attempt or the twist | 4–6s |
| 4 | Detail — close-up proving the point | 2–3s |
| 5 | Payoff — the result in motion | 4–6s |
| 6 | Close — reaction, CTA, or loop point | 2–4s |
Not every video needs all six, and a narrative short may run twelve shots across sixty seconds. The value of the skeleton is that it forces you to decide what each clip is for. A clip with no function should be cut, no matter how beautiful it looks.
What to lock before generating anything
Before the first generation, decide and write down:
- Aspect ratio and resolution. Vertical 9:16 for feed-based platforms, 16:9 for embedded or landscape contexts. Mixed output creates framing headaches later.
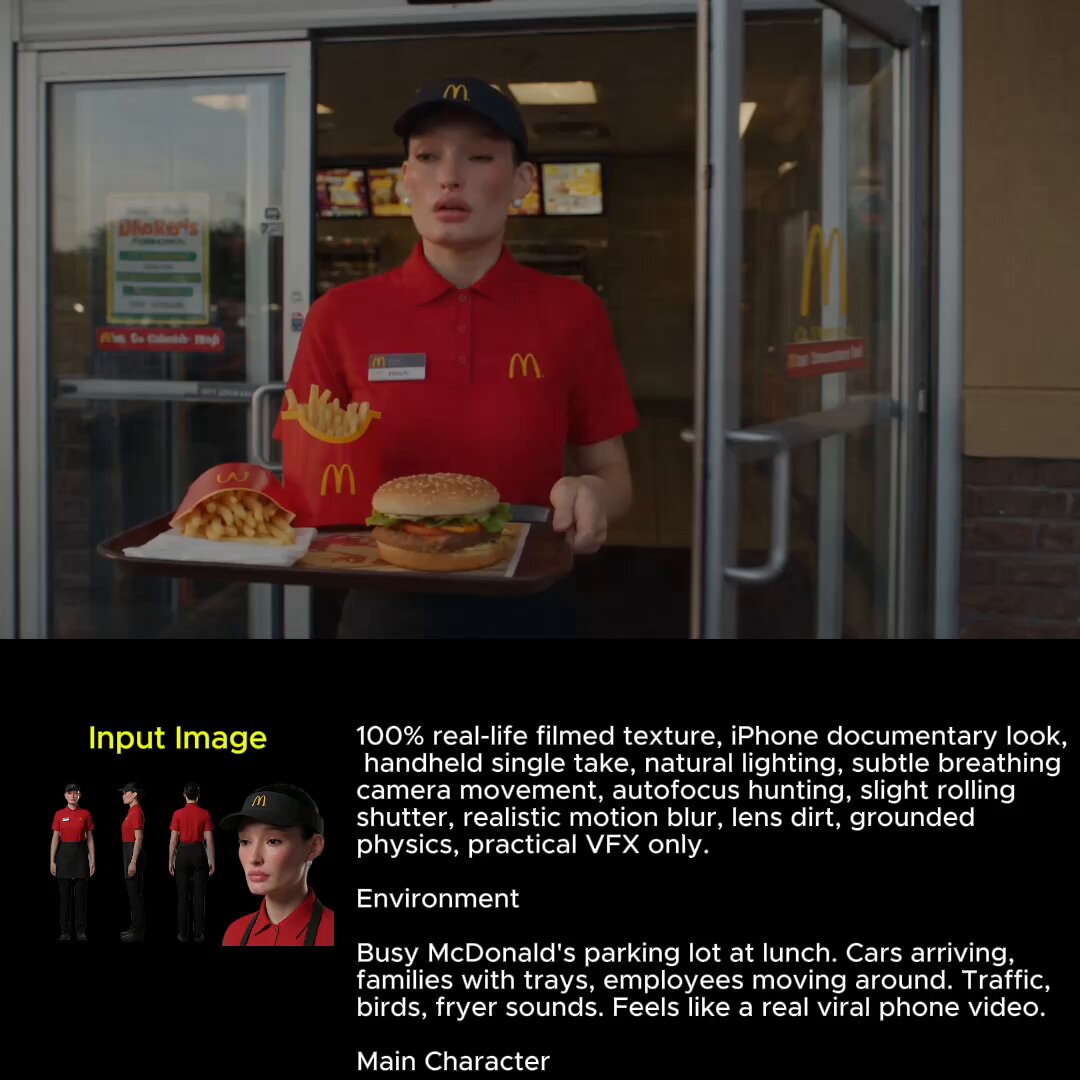
- Character sheet. Name, age range, wardrobe, hair, distinguishing features, and two or three reference images.
- Location and time of day. Once you commit to "overcast morning," keep it consistent or deliberately transition.
- Color and lighting direction. Warm window light from the left is a constraint; without it, clips will drift.
- Camera logic. Handheld realism, locked-off tripod, slow dolly — pick a limited vocabulary.
This is the document you will copy prompt fragments from. Treat it as the contract your generations must honour.
Character and Style Consistency Across Clips
The single most visible weakness of AI-generated short video is drift: the same character gradually changes face, jacket, hair length, or age between shots. Viewers may not articulate why a video feels off, but they feel it immediately.
Reference sheets and multi-image conditioning
Modern models accept multiple reference images alongside text prompts, which is the primary lever for consistency. A practical reference set for a recurring character includes:
- A neutral, front-facing portrait in flat light.
- A three-quarter view with the same wardrobe.
- A full-body shot that establishes proportions.
- An optional environmental shot that fixes costume details in context.
When you generate, attach the same references every time, and describe position and action rather than appearance. Let the references carry identity; let the prompt carry performance. Re-describing the wardrobe in text on one shot and omitting it on the next is one of the most common sources of drift.
Style bibles and prompt fragments
Keep a short text file of approved fragments you paste into every prompt. Something like:
- Lighting: overcast daylight, soft shadows, slight haze
- Grade: desaturated cool midtones, warm skin highlights, mild film grain
- Camera: 35mm equivalent, shallow depth of field, slow handheld drift
- Motion: naturalistic, no exaggerated speed ramps
Two benefits follow. First, consistency improves because the same language hits the model every time. Second, when a shot looks wrong, you can isolate which fragment caused it instead of guessing.
If a shot still drifts, do not generate five more versions and hope. Regenerate with fewer variables: one subject, one action, one camera instruction.
Choosing the Right Model for Each Shot
AI video models are not interchangeable. They differ in motion realism, physical plausibility, prompt adherence, stylization, and how well they handle faces and hands. Choosing deliberately per shot is faster than finding one model and forcing it to do everything.
Matching model to motion type
- Human performance and dialogue-adjacent shots. Favour models with strong facial animation and stable identity. Keep clips short; long takes give drift time to accumulate.
- Camera-driven cinematic shots. Favour models with reliable camera-motion understanding and coherent parallax. Describe the move explicitly — "slow push in, slight leftward drift" beats "dynamic."
- Product and object shots. Favour models that handle reflective and transparent surfaces and small text. Often a still image with a simulated camera move outperforms full generation.
- Abstract and stylized sequences. Favour models tuned for animation or illustration aesthetics. Push the style vocabulary hard, since realism constraints no longer apply.
A simple routing rule: use your strongest model for the hook and the payoff, and cheaper, faster settings for transitional shots. Viewers scrutinize the first and last seconds; middle clips mostly need to be coherent.
When to generate versus when to shoot
Not every shot should be synthetic. Hands interacting with physical objects, real products with logos, on-screen text, and anything requiring precise lip sync are often faster and better filmed on a phone. A hybrid approach — real footage for tactile close-ups, generated footage for environments and impossible camera moves — usually produces the most convincing result and the fewest retakes.
First-Frame and Last-Frame Control for Seamless Cuts
One of the most practical recent advances is conditioning a generation on a starting image, an ending image, or both. This turns generation from a lottery into a bridge-building exercise.
Use first-frame control when:
- You need a shot to begin exactly where the previous clip ended, creating a match cut.
- You want a still photograph to animate forward into motion.
- You need a consistent opening composition across an A/B test.
Use last-frame control when:
- The clip must land on a specific composition — a product centred, a face turned to camera.
- You are chaining multiple generations into a single continuous move.
- You want the final frame to become the thumbnail or the loop point.
Use both when you are building a transition: extract the final frame of clip A, use it as the opening frame of clip B, and describe only the new action. This is the closest thing to a reliable seamless cut that generative video offers today. Keep a folder of exported frames for exactly this purpose.
Pacing, Sound, and the Edit That Makes AI Footage Believable
AI footage often fails in the edit rather than in generation. Two problems dominate: clips that run too long, and sound that does not match the physical space of the image.
Cutting on motion, not on beats
A generated clip usually contains a moment of clean motion — a turn, a step, a hand movement. Cutting on that motion hides the transition and makes the sequence feel intentional. Cutting on a music beat instead can land mid-motion and read as an error.
Practical rules:
- Trim each clip to its strongest 1.5–3 seconds. If a moment of action exists, cut just before it completes and let the next shot finish it.
- Vary shot length deliberately: short, short, long. Uniform lengths create a metronomic, robotic feel.
- Add a 2–4 frame overlap or a subtle whip or swell between clips when a hard cut feels jumpy.
- Resist slow motion unless it serves a beat. Speed ramps amplify AI artifacts.
Sound design and voice
Sound does more for perceived realism than resolution. Layered ambience under every clip — room tone, wind, distant traffic, cloth movement — reduces the uncanny stillness of generated footage. Add specific foley for visible actions: a click, a pour, a footstep. If the shot includes a face, avoid silence; even subtle breath sounds help.
For voiceover, write for speech, not for reading. Short sentences, active verbs, one idea per line. Generate or record the voice first and cut picture to it, rather than the reverse. Captions should be burned in or auto-generated with a readable weight, positioned above the platform's interface overlay zone.
A Repeatable End-to-End Workflow
Once the elements above are in place, production becomes a loop rather than a project.
Stage 1 — Idea triage (15 minutes). Write the hook, the payoff, and one sentence of context. If you cannot state the payoff in a sentence, the idea is not ready.
Stage 2 — Shot plan (20 minutes). Fill the six-shot skeleton. Note which shots are generated and which are filmed. Assign a model class to each generated shot.
Stage 3 — Reference prep (10 minutes). Export or select character references, lock the style fragments, decide the aspect ratio.
Stage 4 — Generation (variable). Generate in order of narrative importance: hook first, payoff second, everything else last. Review each clip immediately and reject fast.
Stage 5 — Assembly (30–60 minutes). Rough cut with no music. Fix continuity and pacing before adding sound. Then add ambience, music, and voice. Then captions.
Stage 6 — Quality gate. Run the checklist below. Only then export.
The quality gate checklist
- Does the first frame contain motion, a face, or a clear result?
- Is the character recognizably the same person from shot one to shot six?
- Does every clip have a function? Cut anything decorative.
- Is any clip longer than four seconds without a reason?
- Are hands, teeth, and text free of obvious artifacts?
- Does the audio change at every cut, or is it flat and continuous?
- Does the last second create a loop, a question, or a clear next action?
- Does it work muted?
A video that passes all eight is usually publishable even if it is not perfect.
Common Mistakes and How to Avoid Them
Generating before planning. The fastest route to wasted time is opening a tool before writing the shot list. Write first, generate second.
Overloading the prompt. Long prompts with five competing ideas produce muddy results. One subject, one action, one camera instruction per generation.
Ignoring physics. If a prompt asks for something physically impossible, the model will produce something uncanny. Ask for plausible motion and let editing create the impossible.
Chasing resolution instead of story. Upscaling a boring clip produces a sharper boring clip. Fix the hook before fixing the pixels.
Uniform pacing. Every clip at exactly three seconds signals template filler. Vary rhythm.
Neglecting the last two seconds. Endings drive rewatches and shares. Design them, do not default to a fade.
Treating generation as the whole job. Generation is roughly a third of the work. Planning and editing carry the rest.
Publishing, Testing, and Iteration
Short video rewards volume with feedback, not volume alone. A simple iteration loop: publish three to five variations weekly that share a format but differ in hook or length; track three-second retention, average watch time, and completion rate; keep the winning structural choices and retire the losing ones.
Keep a running production log with the prompt fragments, model choices, and settings used for each published video. Within a month you will have a personal playbook grounded in your own results instead of borrowed advice. When a format plateaus, change one variable at a time — hook type, length, voice, or visual style — so you can attribute the change.
Finally, batch. Group scripting, generation, and editing into separate sessions. Context switching between creative writing and technical troubleshooting is the quiet productivity killer in AI-assisted production.
FAQ
How long should an AI-generated short video be? For feed-based platforms, 20–45 seconds is a practical default. Shorter works when the payoff is visual; longer works when the video teaches something in steps.
Do I need multiple AI video tools? Most creators benefit from two: one strong model for hero shots and one faster option for drafts and transitions. More than three usually adds friction without improving output.
Why does my character change between shots? Usually because identity is being described in text instead of carried by the same reference images. Attach identical references every time and describe only action and camera.
Can I mix filmed and generated footage? Yes, and it is often the best approach. Use real footage for hands, text, and product detail; use generation for environments, scale, and impossible camera moves.
How do I stop clips from looking artificial? Shorten them, add layered ambience, avoid slow motion, cut on motion, and add a subtle grade and grain pass so all clips share one visual texture.
What should I write in the prompt when I am unsure? Write less. State the subject, the action, and the camera. If the result is wrong, change one element at a time until it is right.
