
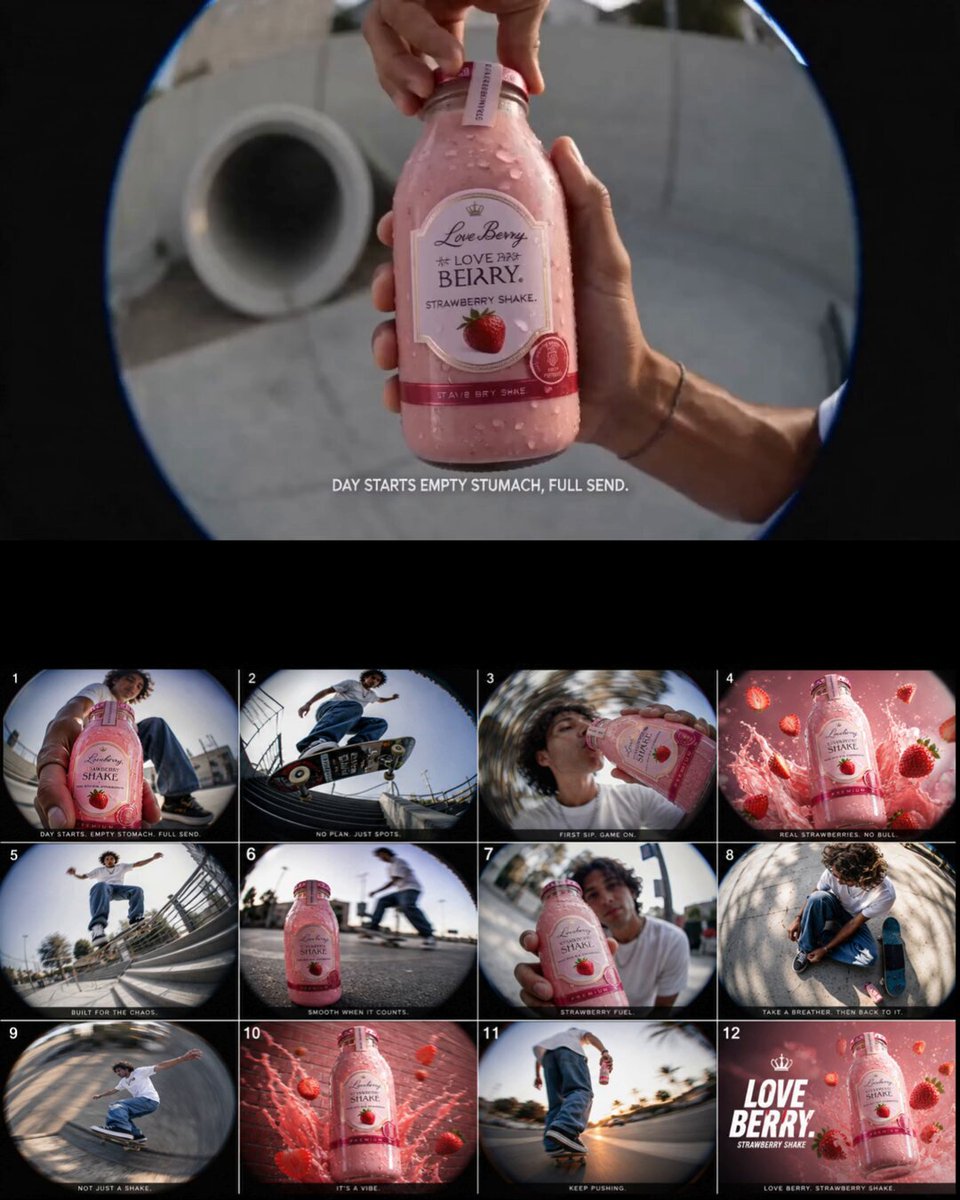
Why cinematic AI video is a workflow problem, not a model problem
A new text-to-video model seems to appear every few weeks, each with a launch reel full of impossible camera moves and flawless skin texture. Those clips are real, but they are also single shots. A finished piece — a brand film, a music video, a documentary insert, a game trailer — needs thirty to sixty shots that feel like they belong to the same world. The gap between one impressive clip and one coherent sequence is where nearly every AI video project succeeds or fails.
Three shifts have made this obvious. First, raw generation quality is no longer the differentiator: several systems now produce convincing faces, fabric, water, and crowd motion. Second, consistency across shots is still genuinely hard, because most models have no memory of your previous shot. Third, finishing decisions — pacing, sound, color, grain, frame rate — still determine whether an audience reads a sequence as cinema or as a slideshow of AI clips.
A repeatable pipeline therefore needs six things before you generate anything: a shot list broken into six-to-eight-second beats, a reference library of characters and locations, a model matrix that maps shot types to tools, prompt templates that stay stable across a scene, review gates where you reject weak takes early, and an assembly plan so each clip is generated already knowing how it will be cut.
Choosing the right model for each shot
There is no single best model. There are models that are strong at realism, models that excel at stylized motion, and models that give you precise control over framing and subject identity. The practical skill is matching the shot to the strength.
Realism, physics, and skin
When a shot depends on believable material behavior — cloth folding, hair moving, water splashing, hands interacting with objects — prioritize models with strong physical priors and high native resolution. Kling, Runway's newer generations, Sora, and Veo-class systems are common choices here. Generate short (four to six seconds), keep motion moderate, and resist the urge to ask for complex multi-action blocking in a single clip.
Motion, expression, and stylization
For character performance, anime-influenced looks, or fast, punchy movement, Pika, Luma Ray, PixVerse, and Hailuo MiniMax tend to reward stylized prompts. These models often handle exaggerated motion better than photoreal systems, which can smear under rapid action. If your project has a strong graphic identity, test two or three of them against the same prompt and compare only the motion arc, not the still frame.
Control, references, and fidelity to a plan
When the shot must match a storyboard, a product photo, or an existing actor's performance, control matters more than beauty. Vidu, Hunyuan Video, and the Wan family are frequently used for reference-driven generation, while image-to-video workflows built on a strong image model give you the tightest grip on composition. Generate your keyframe as a still first — in a capable image generator — then animate it. This single habit prevents most framing surprises.
A simple scoring rubric
| Shot type | What matters most | Traits to look for |
|---|---|---|
| Product hero | Edge fidelity, label legibility | Image-to-video, high resolution, low motion |
| Dialogue close-up | Lip sync, micro-expression | Performance transfer, native audio |
| Action beat | Motion coherence | Stylized model, short duration, high motion strength |
| Establishing wide | Depth, atmosphere | Text-to-video, long lens look, slow push-in |
| Insert / texture | Detail, stability | Image-to-video from a plate, minimal camera move |
Score each candidate model from one to five on realism, motion, control, speed, and cost per finished second — not cost per generation, because a cheap model that needs nine attempts is expensive.
Building a shot list that survives generation
Most failed AI videos were planned as paragraphs, not as shots. Convert your script into beats of six to eight seconds, and give each beat exactly one action and one camera idea. If a beat needs two actions, it is two shots.
Use a spreadsheet with these columns: shot number, duration, action, subject, environment, camera move, lens feel, lighting, audio, model, status. The discipline of filling every column forces decisions that would otherwise surface as twenty wasted generations.
Two planning habits pay for themselves. First, plan the cut before you generate: knowing that shot twelve cuts on motion from shot eleven lets you over-generate the tail of the earlier clip and hide the seam. Second, generate a little longer than you need — ten seconds to use six — so you have handles for trimming and for matching action across a cut.
Also decide your aspect ratio and frame rate up front. Mixing a vertical clip into a widescreen timeline means either cropping away composition or upscaling with softness. Choose 24 fps for a filmic cadence, 30 fps for online delivery, and higher only if you have a specific reason and enough light in the generated footage to support it.
Prompting camera language and motion
A prompt is a shot brief, not a mood board. The most reliable structure is: subject and wardrobe, action, environment, time of day and light quality, lens and framing, camera move, pacing, and style reference. Keep the order stable across a scene so the only variables are the ones you intend to change.
Weak prompt: "cinematic shot of a woman walking in a city, beautiful, 4k, masterpiece."
Stronger prompt: "Medium close-up, 50mm, of a woman in a charcoal wool coat walking left to right through a rain-slicked alley, sodium streetlights behind her, shallow depth of field, slow tracking camera matching her pace, subtle handheld drift, cool shadows with warm highlights, film grain, no text overlays."
The second version tells the model the framing, the subject, the motion direction, the lighting logic, and the camera behavior. If your tool supports negative prompts, use them for artifacts rather than for aesthetics: extra fingers, warped faces, flickering, sudden zoom, text, logos.
When a shot needs to land precisely, use first-frame and last-frame conditioning. Animating between two approved stills constrains the model far more than any adjective can, and it makes matching an edit point almost trivial. Motion strength is the other lever: lower it for dialogue and product shots, raise it for transitions and action inserts.
Keeping characters, wardrobe, and locations consistent
Consistency is a library problem. Build a look bible before generating a single clip: front, three-quarter, and profile portraits of each character; a wardrobe sheet with fabric and color names; two or three wide reference frames for each location; and a color script describing how light changes across the story.
Then standardize how you describe those elements. If a character is "a man in his forties with a close-cropped grey beard and a navy field jacket," that exact phrase should appear in every prompt featuring him. Slight rewording produces a different person, because the model has no memory of your intent.
Techniques that improve continuity: lock your seed where the tool allows it; reuse the same reference image across a scene; train or import a character adapter if your toolchain supports it; keep camera distance and lens length similar between shots of the same scene; and prefer cutting on action or on a matching shape rather than on a hard visual jump.
Locations benefit from the same treatment. Generate one establishing wide for a place, then use it as an image reference for every closer shot inside it. When a background drifts between shots, no amount of color grading will disguise it.
Audio, voice, and pacing
Sound design does more for perceived production value than resolution does. An audience forgives soft pixels; it does not forgive hollow rooms, mismatched ambience, or a music bed that fights the edit.
Decide early whether dialogue drives the visuals or the reverse. Dialogue-first projects should lock voice performance and timing before generating, so mouth shapes can be matched and cuts can land on breaths. Visual-first projects can record narration afterward to the finished cut, which is usually faster and far less frustrating.
Layer your audio in three passes. Start with a continuous ambience bed per location so scenes feel spatially real. Add foley for the actions the audience is watching — footsteps, fabric, a mug on a table — because visible motion with no sound reads as unfinished. Finally, add music and mix the levels so dialogue sits above the bed with a few decibels of headroom.
If you use synthesized voices, keep a written consent record for any cloned voice, and vary cadence deliberately: AI narration often defaults to an even, unhurried rhythm that flattens tension. Shorten pauses before reveals and let sentences run longer in reflective moments.
Post-production: assembly, cleanup, and finishing
Treat generated clips as camera rushes. Import everything into an editor, cut for story first, then fix problems. Common cleanup passes: stabilize drift, deflicker brightness pulses, remove warped frames in the middle of a clip, and replace a broken hand or background with a short clean plate.
Upscale only after the cut is locked, and upscale selectively. Interpolation to a higher frame rate can smooth motion, but it can also introduce a soap-opera look and ghosting artifacts around fast limbs, so test on one shot before applying it across a timeline.
Finishing is where AI footage becomes film. Apply a consistent color treatment so different models' color science stops fighting; add a subtle grain layer and a small amount of halation on highlights; keep a single aspect ratio and letterbox consistently; and check that black levels match from shot to shot. A one-second sound or visual overlap on each cut will also hide more model inconsistency than any prompt trick.
A 60-second end-to-end workflow
- Write a one-page treatment with a beginning, a turn, and an end.
- Break it into ten to fourteen beats of six to eight seconds and fill the shot-list spreadsheet.
- Generate reference stills for every character and location; approve them before animating.
- Score three candidate models on your hardest shot, not your easiest.
- Generate ten-second takes at your locked aspect ratio and frame rate.
- Review in batches with a yes/no rule; do not "fix in post" a take you already dislike.
- Assemble a rough cut with temp music as soon as you have six usable shots.
- Record or generate voice and ambience against the locked picture.
- Cleanup, upscale, grade, grain, and export at delivery specs.
The most common scheduling mistake is generating everything before editing anything. Cutting early tells you which shots you actually need, and it frequently kills three shots you were about to spend an afternoon on.
Common mistakes and how to fix them
- Too many ideas in one prompt. Split the beat. One action, one camera move, one lighting idea.
- Ignoring the cut. Generate handles, plan overlap transitions, and design cuts rather than hoping clips will join.
- Chasing a single model. Match the model to the shot, then unify the look in grading.
- No color script. Decide the palette per scene on paper; otherwise each clip arrives with its own mood.
- Neglecting audio. Budget a third of your time for sound, and build ambience before music.
- Skipping review gates. Approve stills, then motion tests, then full takes. Errors get cheaper the earlier you catch them.
- Final-length generation. Never generate a sixty-second clip. Generate six seconds and cut.
FAQ
How many AI video models do I actually need?
Two or three well-understood tools beat a dozen half-learned ones. Pick one for realism, one for stylized motion, and one for image-to-video control, then learn their failure modes.
Why do my characters change between shots?
Because the model has no memory. Fix it with a locked reference image, a consistent written description, similar lens length, and character adapters where available.
Is image-to-video better than text-to-video?
For anything that must match a storyboard, a product, or a specific face, yes. Text-to-video is best for establishing shots and exploratory work.
How long should each generated clip be?
Generate eight to ten seconds to use five to seven. Longer clips tend to drift in anatomy and lighting, and you rarely need the extra length.
What frame rate should I deliver?
24 fps for a filmic feel, 30 fps for general online delivery, 60 fps only for slow-motion source or gaming contexts. Consistency matters more than the number.
How do I make AI footage look less artificial?
Grain, halation, matched black levels, a single color treatment, real ambience, and cuts on motion. The tell is usually sound and grading, not resolution.
Should I use synthesized voice?
For narration and temp tracks, often yes. For on-camera dialogue, match lip sync carefully, keep a consent record for any clone, and vary cadence to avoid monotone delivery.
What is the biggest time sink?
Regenerating shots that should have been re-planned. Ten minutes with a shot list saves an hour of prompting, and a strong reference still saves more than that.
