
Why Character Consistency Is the Real Bottleneck in AI Video
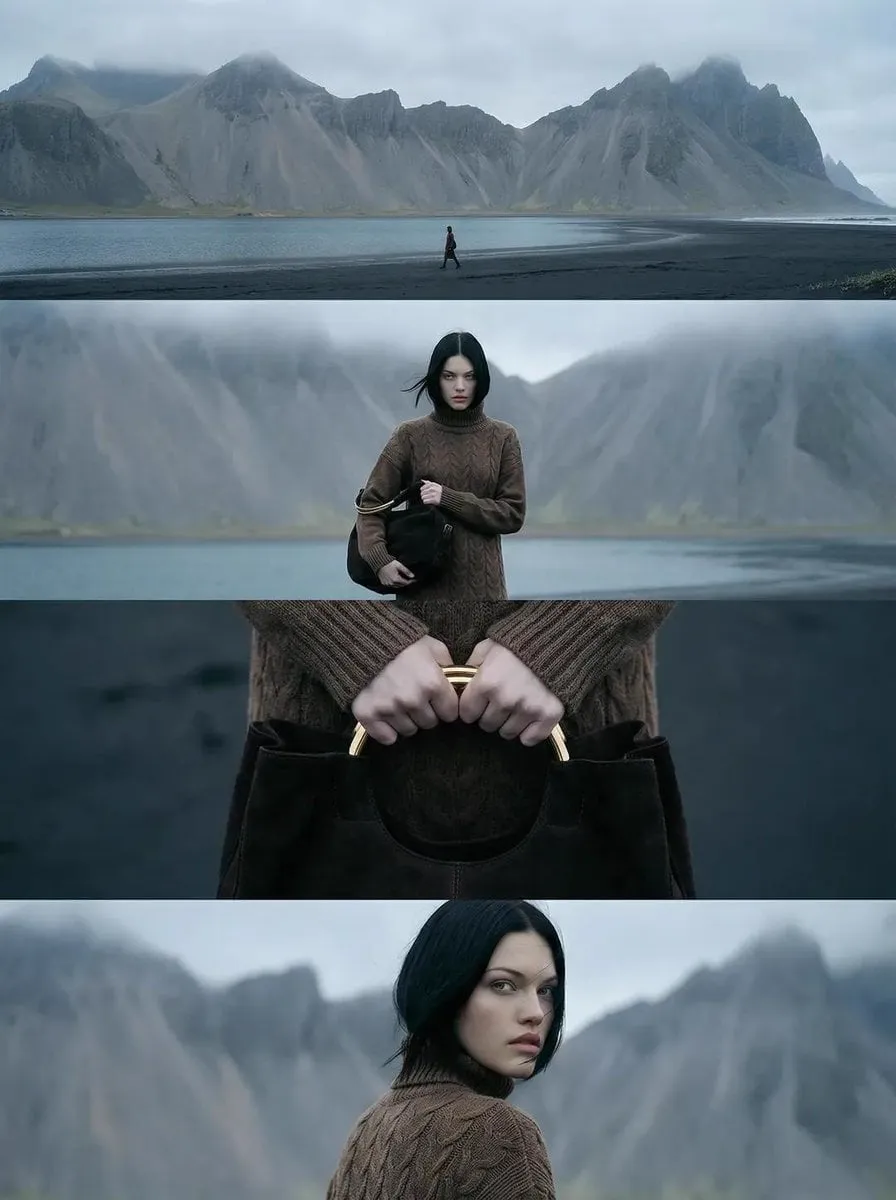
A single AI-generated shot can look astonishing. A face with believable skin texture, hair that catches light, a jacket that folds naturally as the subject turns. Then you generate the second shot, and the same character returns with a slightly narrower jaw, different eyebrows, a jacket that has quietly become a different shade of olive. By shot four, you are no longer making a film. You are making a slideshow of strangers who happen to share a name.
This is the central frustration of narrative AI video. Text-to-video models have become extraordinarily good at producing isolated moments. They remain unreliable at producing the same person across those moments. Continuity is not a rendering problem; it is an identity problem. And identity, in a diffusion or transformer-based pipeline, is not stored anywhere by default. Every generation starts from noise and re-invents the subject from whatever hints you provide.
The practical consequences are concrete. Re-shoots cost time, and re-shoots in AI video mean regenerating entire sequences, not just one take. Character recognition breaks for audiences within seconds. If your viewer cannot tell whether two shots show the same protagonist, the emotional arc collapses, no matter how beautiful the individual frames are.
The good news is that consistency is now a solvable engineering problem rather than a lucky accident. The reliable approaches share a common principle: stop relying on a single reference and a hopeful prompt, and instead supply the model with multiple, structured views of the same person, then lock that identity across keyframes. This guide walks through that workflow end to end.
What Actually Causes Character Drift
Before fixing drift, it helps to understand where it comes from. Most of it traces back to two structural issues.
Generative models are stochastic by design
Diffusion and transformer video models sample from a probability distribution. Two runs of the identical prompt and seed can produce subtly different faces because the sampling path is sensitive to noise scheduling, latent resolution, motion conditioning, and any temporal module that interpolates between frames. Add a new camera angle, a new lighting setup, or a new action, and the model has more room to improvise. Improvisation is exactly what you do not want for a recurring character.
Motion conditioning compounds this. A model that must keep a face coherent while the head turns 90 degrees has to invent the side profile. If it has no strong prior for what that person's profile looks like, it will invent a plausible one, which is usually a different one.
Single-image references carry too little information
A common early approach is to feed one portrait as a reference and describe the rest in text. This works for a single shot. It fails the moment the scene demands a change in pose, angle, expression, or wardrobe, because one image encodes exactly one configuration of the face. The model can transfer overall likeness, but it has no information about the jawline from below, the ear shape, the hairline at the back of the head, or how the subject looks mid-laugh.
Prompt-only descriptions have a parallel weakness. Adjectives like "sharp cheekbones" or "warm brown eyes" are interpreted differently at every sampling step. They are directional hints, not specifications. The result is a character who is recognizably of a type but not recognizably the same individual.
A third, quieter cause is inconsistency in your own inputs: switching aspect ratio between shots, changing the negative prompt, or letting a style modifier drift. Small input changes produce visible identity changes.
Build a Character Bible Before You Generate Anything
The single highest-leverage habit in consistent AI video is boring: decide who the character is before you render them. Professional animation studios call this a model sheet or character bible. You can replicate the useful parts of that practice in an afternoon.
The reference sheet: six to ten images, deliberately varied
Aim for a set that covers the identity from multiple angles rather than multiple near-duplicates of the same flattering headshot. A practical minimum:
- Front-facing, neutral expression, even lighting. This is your anchor image.
- Three-quarter left and three-quarter right. These teach the model how the face volume changes as it rotates.
- Straight profile. Critical for turnarounds and for any shot involving a look-away.
- Low angle and high angle. These reveal jaw and brow structure.
- Two or three expressions — smiling, serious, speaking. Expression changes muscle geometry; the model needs examples.
- One or two full-body or mid-body shots for proportions, posture, and wardrobe silhouette.
Keep lighting and background as consistent as you can across the set. If every reference has wildly different color temperature, the fusion step will average those differences into the character's skin tone.
The text anchor: a short, frozen description block
Write one paragraph describing the character and then reuse it verbatim, character for character, in every prompt. Do not paraphrase it between shots. Include: approximate age range, face shape, eye color and shape, hair color, length and texture, skin tone, distinguishing marks, and default wardrobe. Keep it under about 80 words so it does not drown out your scene description.
Store this block in a text file alongside your reference images. The moment you start rewriting it from memory, drift begins.
How Multi-Image Fusion Locks an Identity
Multi-image fusion is the technique that changed the practical ceiling of AI character work. Instead of conditioning a generation on one reference, you condition it on a blended representation built from several.
What blending actually does
When multiple reference images are encoded, each becomes a vector in the model's conditioning space. Fusion combines them — through weighted averaging, attention-based aggregation, or an adapter layer trained to extract identity — into a single composite embedding. That embedding encodes the invariant features across all your references and suppresses the parts that vary, like lighting or expression.
The effect is that the model is no longer guessing what the person looks like from the side. It has seen the side. Identity becomes a constraint rather than a suggestion, and it survives changes in pose, framing, and scene.
Reference selection and weighting matter more than quantity
More references are not automatically better. Ten near-identical portraits will over-constrain the front view and leave the profile undefined. A balanced, varied set of six usually beats an unbalanced set of fifteen.
Weighting is the second lever. Most fusion implementations let you emphasize the anchor image. A reasonable default is to give the clean front-facing shot the highest weight, the three-quarter and profile views moderate weight, and expression shots lower weight, since expressions distort geometry. If a character's side profile keeps coming out wrong, raise the profile image's weight rather than adding more front shots.
If your tool exposes a dedicated identity or reference adapter, prefer it over prompt-based approaches. Adapters trained specifically for identity preservation hold up far better under aggressive camera movement.
A Step-by-Step Workflow for a Three-Scene Sequence
Here is the process in the order that produces the fewest wasted generations.
Step 1: Prepare and normalize assets
Crop your references to consistent framing, normalize exposure and white balance, and remove distracting backgrounds where possible. Downscale to whatever resolution your tool prefers. Clean inputs produce a cleaner fused identity.
Step 2: Lock the identity on a test frame
Before generating any moving footage, render a single still of the character in neutral lighting using the fused reference set. Compare it against your reference sheet. Check eye spacing, nose length relative to the lip line, ear placement, and hairline. If the still is off, fix the reference set now. Everything downstream inherits this error.
Step 3: Generate a keyframe per shot
For each scene, render a still at the exact framing and angle you want the shot to start from, then optionally an ending still. This gives you keyframe control: the video model interpolates between frames you already approved instead of inventing a performance. It is the single most effective anti-drift technique available, because the beginning and end of every shot are guaranteed to show the correct person.
Step 4: Animate with restrained motion
Feed the keyframes into your image-to-video step with a motion prompt that describes action, not appearance. Do not re-describe the character in the motion prompt unless the tool requires it; redundant descriptions compete with your fused identity and can reintroduce drift. Keep camera moves modest in the first pass. Large arcs and whip pans are where temporal stabilization usually breaks down.
Step 5: Stabilize and review shot by shot
Watch each clip in isolation, then watch the sequence back to back. Pause on the first frame of each shot and the last frame of the previous shot. That transition is where continuity errors are most visible.
Step 6: Repair surgically
When one shot drifts, do not regenerate the whole sequence. Regenerate the single shot with a tighter reference weight, more keyframes, or a shorter duration. Segmenting your project into short, independently fixable clips is what keeps the workflow affordable in time.
Choosing the Right Tool for the Job
You do not need one tool that does everything. A realistic stack often has three roles: a still-image generator for character sheets and keyframes, an image-to-video model for motion, and an upscaler or frame interpolator for finishing.
When evaluating any tool for character work, ask these questions:
- Does it accept multiple reference images? If it only accepts one, it cannot do robust fusion.
- Can you weight or prioritize a reference? Weighting is what lets you correct profiles and angles.
- Does it support start and end keyframes? This is non-negotiable for narrative work.
- How long are the clips? Shorter clips drift less and are cheaper to redo.
- Is the styling consistent? Some models have a strong house look that will fight your intended aesthetic.
- What is the export path? Resolution, frame rate, and codec matter if you plan to edit in a real timeline.
Test candidates on the same two-shot sequence before committing. A model that looks great in a demo reel with one character in one pose tells you very little.
Common Mistakes and How to Fix Them
Using one reference for everything. The most common failure. Add angle coverage before you add prompt detail.
Letting the prompt describe appearance differently each time. Freeze your character block and paste it unchanged.
Changing aspect ratio mid-project. Reframing alters how the model composes the face. Pick a ratio and stay with it, or crop in post.
Overloading the motion prompt. Long prompts with wardrobe, lighting, lens, and mood all mixed together dilute the conditioning. Split responsibilities: identity from references, framing from keyframes, action from motion text.
Ignoring the wardrobe layer. Costume changes are a legitimate narrative tool, but they must be planned. If a jacket changes color between two shots in the same scene, audiences read it as an error.
Chasing perfection on every frame. Generated hair will shimmer. Decide which imperfections are acceptable at your final viewing size and stop there.
Not versioning. Save each reference set and prompt block with a version number. When a change makes things worse, you need a path back.
Handling Wardrobe Changes, Aging, and Doubles
Consistency does not mean the character never changes. It means change is intentional and legible.
For wardrobe, build a second fusion set that swaps only the clothing references while keeping the same face references. This keeps identity stable while the costume varies.
For time jumps or aging, generate an aged keyframe still first, verify it reads as the same person, then use that still as an additional reference for the later scenes.
For stunt or background doubles, use the opposite approach: keep the wardrobe identical and degrade the identity slightly by lowering the face reference weight. The audience should not be able to study the face.
Continuity QC and Versioning Discipline
Run a fixed checklist on every shot: face shape, eye color, hair length and parting, skin tone, wardrobe items and colors, props, and background continuity. Note the frame time of any discrepancy so you can trim or re-render precisely.
Keep a simple project log. For each shot record the reference set version, the character block version, the keyframe files, and the motion prompt. This turns a creative process into something reproducible, which is what allows a solo creator to produce a coherent multi-scene piece without losing their mind.
FAQ
How many reference images do I actually need? Six to ten, chosen for variety of angle and lighting consistency, is the practical sweet spot for most fusion systems. More helps only if the coverage is genuinely new.
Why does my character look right in stills but wrong in motion? Stills are single-frame problems; video adds temporal conditioning, which is where identity reconstruction is weakest. Use start and end keyframes and keep clips short.
Can I get consistency from text prompts alone? Only weakly. Text can hold a character type, not a specific face. References do the heavy lifting.
What should I do when only one shot drifts? Regenerate that shot alone with higher reference weight and additional keyframes. Do not rebuild the sequence.
Does a fixed seed guarantee the same character? No. A seed reproduces a sampling path, not an identity. Changing the pose or prompt moves you to a different region of the model's output space.
Is this workflow fast enough for short-form content? Yes, once the character bible exists. The setup costs an hour; after that, keyframe-first generation is typically faster than regenerating drifting clips over and over.
Should I edit inside the AI tool or in a separate editor? Generate in the AI tool, assemble in a dedicated editor. Cut points, sound, and color need real timeline control, and you will want the freedom to swap a single clip without touching the rest.
Consistency across scenes is not a magic setting. It is the product of structured references, disciplined prompts, keyframe control, and methodical review. Get those four things right, and your characters will finally start behaving like people who exist in the same story.
