
Why free AI video generators became production-ready
A few years ago, generating video with AI meant watching a subject melt into a puddle of pixels halfway through a three-second clip. Today, a free tier on a competent text-to-video or image-to-video tool can produce a shot that survives a real edit: stable subject, readable camera move, believable lighting, and enough temporal coherence that viewers do not immediately clock it as synthetic.
Three changes made that possible. First, temporal consistency improved dramatically, so frames stop drifting apart across the length of a clip. Second, prompt adherence got sharper, meaning the model actually respects "slow dolly in" instead of turning it into a random zoom. Third, iteration became cheap. When a mediocre result costs nothing but a minute of waiting, you can explore ten visual directions instead of committing to the first one.
That last point is the real shift. Free access is not just about saving money; it changes creative behavior. You storyboard differently when you can test a risky idea. You experiment with camera language you would never pay to attempt. You build a personal library of prompts that work for your niche.
Of course, free access has edges. Typical limitations include shorter clip lengths, capped resolution, watermarks on some tiers, slower queues at peak times, and a limited number of generations per day or month. Understanding those edges is what separates a frustrating afternoon from a repeatable production workflow.
What "free" actually means for AI video tools
The word free covers a wide spectrum, and the differences matter more than the price tag. Before you build a workflow around any tool, check five things:
- Export quality. Is the free export 720p, 1080p, or lower? Does it upscale acceptably if you finish in an editor?
- Watermark policy. Some tools watermark every free export; others watermark only certain models.
- Clip length limit. Many free tiers cap clips at three to five seconds, which changes how you plan shots.
- Commercial usage terms. This is the one people skip. If you are producing for a client, for ads, or for monetized channels, verify that the terms allow commercial use before you generate anything.
- Daily allowance. Whether it is measured in generations, seconds of video, or processing time, know your ceiling so you can budget it the way you budget time.
A useful habit: keep a small notes file listing which tools you have access to, their clip length, their aspect ratio support, and their best use case. That one page becomes your routing table, and routing is where most of the quality gains hide.
The end-to-end workflow at a glance
Here is the full pipeline, from blank page to published video. Each stage has a distinct job, and mixing them up is the most common source of wasted effort.
- Brief. One paragraph: audience, tone, platform, target length.
- Shot list. Every shot written as a single action with a stated camera move.
- Model routing. Decide which shots go to text-to-video, which go to image-to-video, and which get animated from a still.
- Prompt drafting. Turn each shot into a structured prompt using a consistent skeleton.
- Generation. Produce two to four variants per shot, not one.
- Selection. Judge on motion quality first, composition second.
- Assembly. Cut, sound design, grade, caption, export.
The loop matters more than the list. Every time a prompt produces a strong result, save it. Every time a prompt fails, note why. Within a month you have a private playbook that outperforms generic advice, because it is tuned to your subject matter and your tools.
Stage 1: Write a shot-first brief
Most disappointing AI video projects fail before generation starts. The brief was vague, so the shot list was vague, so the prompts were vague, so the output was mush.
Start with one sentence
Write a single sentence that states subject, action, and mood: "A chef plates a dessert in a warm evening kitchen, shot like a food documentary." That sentence contains everything the model needs to anchor tone. If you cannot write it, you do not yet know what you are making.
Build the shot list before touching a tool
A shot list should be a simple table with one row per shot and columns for duration, subject, action, camera, and intended model. Four to six seconds per shot is a realistic default for free tiers.
Two rules keep the list honest. First, one action per shot. "He walks in, opens the laptop, and reacts" is three shots pretending to be one. Second, one camera move per shot. Combining a push-in with a pan usually produces an unreadable smear.
Lock aspect ratio and platform early
Vertical for short-form, 16:9 for YouTube and presentations, square for certain social placements. Changing aspect ratio late forces regeneration, because cropping a vertical clip into widescreen loses the composition the model built.
Stage 2: Route each shot to the right model
No single model is best at everything. Photoreal humans, stylized animation, product macro shots, drone-style landscapes, and abstract motion all have different strengths. Treating models as interchangeable is why so many creators conclude that AI video "looks the same everywhere."
Text-to-video versus image-to-video
Text-to-video is best when you need discovery: you are not sure what the shot should look like, so you let the model propose. Image-to-video is best when composition matters: you create or select a still, then animate it with a specific motion instruction.
For brand work and character-driven stories, image-to-video wins almost every time. You control framing, wardrobe, and lighting in the still, and the model only has to handle motion. That single decision reduces the number of variables by half.
Looking beyond the obvious models
It is worth testing models outside the ones you see most often in demos. Some excel at anime and illustration, some at photoreal portraits, some at stylized landscapes, and some at strong, cinematic camera movement. Different model families also carry different cultural defaults in color, lighting, and composition, which is genuinely useful when you are producing content for a specific regional audience.
A routing table you can actually use
- Talking head or presenter shot: image-to-video from a portrait still.
- Product detail: text-to-video for motion tests, image-to-video for the hero shot.
- Landscape establishing shot: either, but lean on a model with strong camera control.
- Stylized animation: models tuned for illustration, not photorealism.
- Abstract background loop: text-to-video, short duration, low complexity.
Write one line per shot in your shot list assigning the model. This prevents the classic mistake of trying to brute-force a photoreal human out of a model that excels at painterly skies.
Stage 3: Prompt for motion, not just subject
Beginners describe a picture. Professionals describe what happens next.
A reusable prompt skeleton
Use a consistent order so you can debug by elimination:
- Subject — who or what, with two or three concrete details.
- Action — one verb-led motion, present tense.
- Environment — location, time of day, weather, atmosphere.
- Camera — shot size plus one move (e.g., "medium shot, slow push in").
- Lighting — soft window light, harsh noon sun, neon practicals.
- Style — film reference, lens, grade, texture.
Keeping the same order means that when a clip fails, you can change one line and re-run rather than rewriting everything and losing the thread of what worked.
Prompt around the common failure modes
- Morphing faces: reduce head movement, keep the face large in frame, shorten the clip.
- Limbs blending into objects: simplify the environment and reduce contacts like hands-on-surfaces.
- Warped text and signage: remove text from prompts entirely, add it in post.
- Unstable backgrounds: state a fixed background explicitly, or use image-to-video with a still background.
- Chaotic crowds: describe two or three background figures with vague detail instead of a crowd.
Also keep a short list of negative instructions for your own reference, such as avoiding extra limbs, text overlays, or flickering exposure. Consistency in what you forbid is as valuable as consistency in what you request.
Stage 4: Keep characters and scenes consistent
Continuity is the hardest problem in AI video, and it is where cheap workflows separate from professional-looking ones.
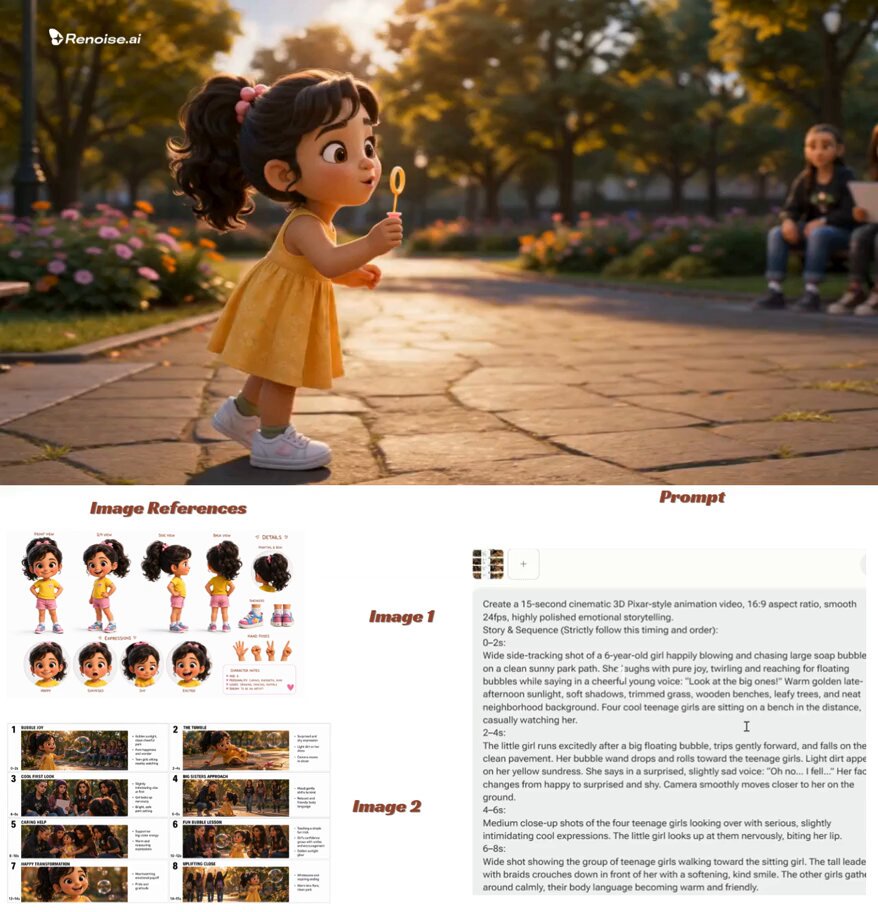
Use reference stills as anchors. Create or select a portrait of your character, then animate that same still for every shot. Wardrobe changes only when the story requires it.
Reuse what the tool lets you reuse. If a tool supports seed values, fixed references, or a character feature, use it religiously and record the settings alongside your prompts.
Build a visual bible. Two or three lines describing palette, lens family, and lighting approach. If a shot does not match the bible, regenerate it now rather than trying to fix it in the edit.
Control the environment as strictly as the character. A café that looks different in every shot reads as sloppy even if the actor is perfect. Lock location details: table material, window direction, time of day.
Match the first and last frame when possible. Some workflows let you specify a start and end frame. This is the closest thing to a directed cut you can get from a generative model, and it dramatically improves how shots assemble.
Stage 5: Generate, select, and edit
Generate two to four variants per shot. Judging a single take is a coin flip; judging four takes is a decision.
Select in two passes. First pass: watch at normal speed and reject anything with broken motion, warped anatomy, or distracting flicker. Second pass: watch the survivors in sequence and reject anything that clashes with the shots around it. A technically clean clip that breaks the rhythm of the sequence is still the wrong clip.
Then move into an editor and treat the footage the way you would treat camera rushes:
- Cut on motion so transitions feel intentional.
- Add sound design. Ambient beds and small foley cues do more for perceived realism than any visual tweak.
- Grade for consistency. Slight color matching across shots hides model differences.
- Add captions and titles in post, never in the prompt.
- Export at the highest resolution your source footage supports.
A thirty-second piece built from six four-second shots, cut tightly with sound, will outperform a sixty-second piece with twice the shots and no sound work.
Stage 6: Manage your free allowance without stalling
Free tiers impose limits, and the way you handle them determines whether you publish or stall.
Draft at the lowest useful quality. Test composition and motion, then re-render only the winners.
Batch similar prompts. Running several variations of the same idea in one session keeps context in your head and reduces redundant work.
Keep a prompt library. A working prompt is an asset. Store prompts with the model name, settings, and a note about what the output looked like.
Stop blind re-rolling. If a prompt failed twice, the problem is the prompt, not luck. Change one variable deliberately.
Plan around queues. Long processing times are ideal for editing other shots, writing copy, or preparing thumbnails.
Common mistakes that waste time
- Writing a short film in one prompt. Models respond to one action, not a script.
- Chasing perfection on the first shot. Establish the full sequence first, then polish.
- Ignoring sound until the end. Audio changes which visual flaws are noticeable.
- Mixing too many visual styles. Three different looks in thirty seconds reads as an accident.
- Over-prompting. Twenty adjectives compete with each other; six specific ones cooperate.
- Skipping aspect ratio decisions. Regenerating an entire project for framing is avoidable pain.
- Ignoring licensing terms. Check commercial usage before you build a deliverable on top of a free tier.
FAQ
Are free AI video generators good enough for client work?
For short-form social, product cutaways, and mood pieces, yes, provided you confirm commercial usage terms and finish with proper sound and grading. For dialogue-heavy narrative work, treat them as a previsualization tool rather than the final render.
How long should a generated clip be?
Four to six seconds is the sweet spot. Longer clips drift and lose subject fidelity, and shorter clips force a frantic edit rhythm.
Should I use text-to-video or image-to-video?
Use text-to-video to explore and image-to-video to execute. Once you know the look, lock a still and animate it.
How many variants should I generate per shot?
Two to four. Fewer than that and you are gambling; more than that and you are hoarding options you will never use.
How do I keep the same character across shots?
Anchor on one reference image, keep wardrobe and lighting constant, reuse whatever seeds or character settings the tool offers, and match first and last frames where possible.
Do I need a powerful computer?
Usually not, since most generation happens in the browser. You will want a modest machine for editing, plus fast internet for uploads and downloads.
What about lip sync and dialogue?
Generate the visual performance, then handle voice separately with a voice tool and align in the editor. Trying to get both from one prompt rarely ends well.
A weekly routine that actually scales
Separate creation from judgment. On a planning day, write briefs and shot lists for two or three pieces. On a generation day, batch every prompt and let the renders run while you do other work. On a review day, select takes, note which prompts worked, and update your library. On an edit day, assemble, add sound, grade, and export.
Batching does two things. It keeps you inside one mode of thinking, which improves the quality of both prompts and edits. It also turns occasional experimentation into a pipeline: by the end of a month you have a prompt library, a routing table, and a visual bible specific to your niche.
The tools will keep changing. The workflow will not. A clear brief, a shot list, the right model per shot, motion-first prompts, locked continuity, disciplined selection, and real post-production are what turn a free generator into something that produces work you would actually publish.
