
Why Image-to-Video Became the Default AI Video Workflow
Text-to-video prompts are seductive: type a sentence, get a clip. In real production, though, most teams end up routing their shots through image-to-video instead. The reason is control. A generated still is cheap to review, easy to reject, and simple to fix — you can regenerate a frame twenty times before you commit to motion. Once you animate, every flaw in the composition gets amplified by movement, and fixing it means running another full motion pass.
The image-to-video path splits one hard problem into two easier ones. First you answer the question: what does this shot look like? Then you answer: how does it move? Separating those decisions lets a director, an art director, and an editor each do their job without stepping on each other. It also makes iteration cheap at the stage where iteration matters most.
There is a practical side too. Brands already own enormous libraries of stills: product photography, archival frames, illustrated assets, packaging renders. Image-to-video turns that library into footage without a shoot. For e-commerce, that means animated hero shots built from existing catalogue images. For publishers, it means bringing archive photography to life for social cutdowns. For game and app marketing, it means turning key art into a ten-second teaser in an afternoon rather than a week.
The workflow is not complicated, but it is full of small decisions that compound. Get the source frame right, describe motion in the right vocabulary, pick a model that matches the physics of the shot, and finish the clip properly. Miss any of those and you get the classic result: a mushy, warping, slightly haunted loop that nobody wants to publish.
This guide walks through the entire pipeline — image preparation, model choice, prompt construction, batch production, finishing, and quality control — with the specific failure modes you should expect and the fixes that actually work.
How Image-to-Video Actually Works
From still frame to motion
An image-to-video model does not understand your picture the way you do. It receives a grid of pixels, encodes it into a compressed latent representation, and then generates a sequence of latents that are conditioned on that first frame. During generation, the model keeps re-anchoring itself to the source image so the clip does not drift away from the original composition.
That re-anchoring is the whole game. Too little anchoring and the subject morphs into something else by second three. Too much anchoring and nothing moves at all — you get a static image with a bit of shimmer. Every model sits somewhere on that spectrum, which is why you cannot use identical settings across different tools.
What the model needs to know
Three inputs drive the output: the source image, a motion prompt, and the length or frame count. The image supplies identity, style, and composition. The prompt supplies trajectory. The length determines how far the model has to extrapolate beyond what it can hold steady.
Short clips — two to five seconds — are dramatically more reliable than long ones. Most professional workflows therefore build sequences out of short, well-controlled shots rather than attempting a single twenty-second animation. This mirrors live-action editing logic: you rarely need one long take, you need coverage.
The motion budget
Every model has a finite amount of believable motion per shot. A slow push-in on a face can hold for six seconds. A full-body run across a frame at speed will fall apart in two. Think of it as a motion budget: the more dramatic the movement, the shorter the window in which it stays coherent. Plan the duration around the motion, not the other way around.
Frame consistency and the melting problem
When a subject has complex geometry — hands, hair, jewellery, thin straps, foliage — the model has to invent detail that is not visible from the starting angle. That invention is where melting happens. The fixes are unglamorous but reliable: keep the camera movement modest, avoid subjects that rotate past 45 degrees, and choose source images where the ambiguous detail is either sharp and clearly lit or genuinely out of frame.
Choosing the Right Model for the Job
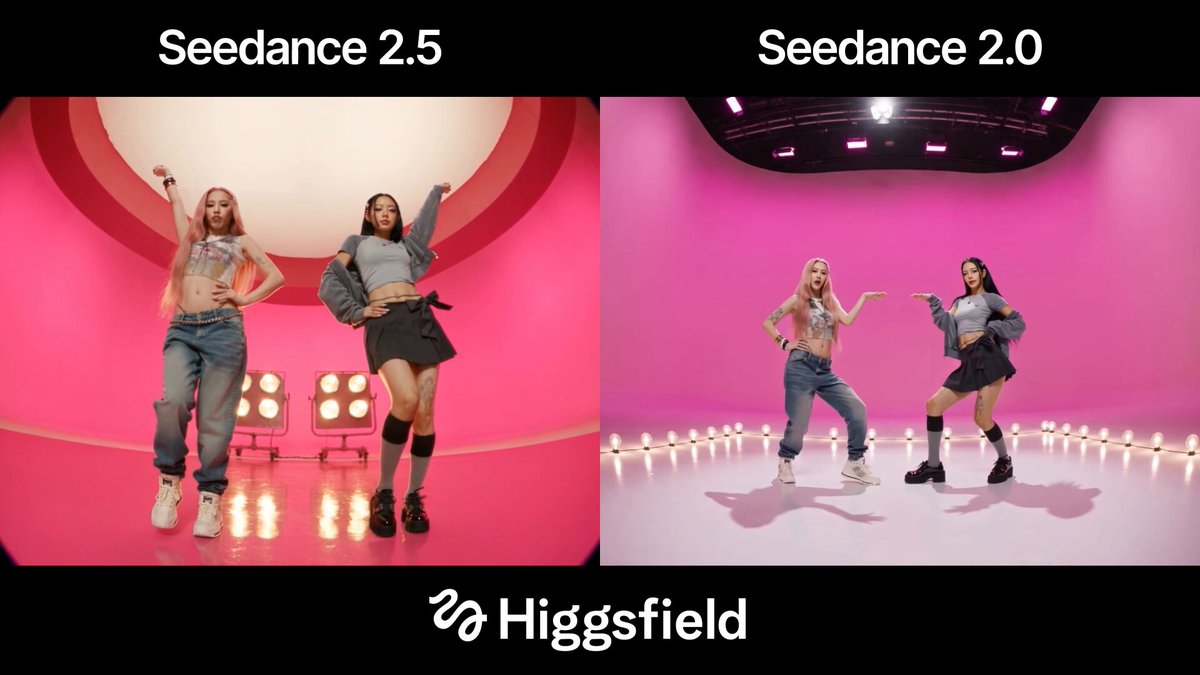
Model families differ far more in personality than in raw quality. Instead of chasing a leaderboard, match the model to the shot.
Photoreal humans and product shots
The highest-fidelity photoreal models excel when the subject is centred, well lit, and static in pose, with the camera doing the work. They are the right choice for beauty shots, food, cosmetics, and hero product rotations. They are the wrong choice for chaotic crowd scenes, where they tend to smooth everything into a plastic sheen.
Cinematic camera moves and stylised looks
Some models are built around camera language: dolly in, crane up, orbit, whip pan. They are noticeably better at producing shots that read as intentional cinematography rather than accidental drift. If your deliverable is a trailer, a title sequence, or a mood piece, start here and let the camera carry the emotion.
Local adaptation and text in frame
Models trained with strong multilingual and regional data handle signage, packaging text, and culturally specific environments more gracefully. If the shot includes a readable logo, a storefront, or a label, test two or three candidates before committing — text legibility under motion is the single fastest way to expose a weak model.
Animation, illustration, and 2D-to-motion
For illustrated or anime-style source frames, general photoreal models fight the artwork. Purpose-built animation pipelines preserve line art, maintain flat colour fields, and understand squash-and-stretch. Use these when your source is drawn, and keep photoreal models for photographic sources.
Physics-heavy content
Water, smoke, cloth, hair, and anything that needs to obey gravity are the hardest test. Some models specialise in physical realism and handle splashes and fabric much better than their peers. If your shot is fundamentally about a physical event, prioritise that specialisation over resolution.
Open and self-hosted options
Open-weight video models matter for teams with strict data policies, unusual fine-tuning needs, or high volume where per-clip cost dominates. The trade-off is operational: you own the GPU bill, the queue, and the quality tuning. A reasonable pattern is to prototype on a hosted tool, then move the highest-volume, most repetitive shot type in-house once the recipe is proven.
Preparing Source Images: The Step Most People Skip
Roughly eighty percent of disappointing outputs trace back to the input frame, not the model.
Resolution and aspect ratio
Feed the model a frame that matches your delivery aspect ratio. Cropping after generation wastes the parts of the frame the model spent effort animating, and letterboxing forces it to hallucinate edges. Generate or upscale the still to a resolution the model handles natively — usually 720p to 1080p on the long edge — and avoid upscaling a tiny source before animating. Detail that does not exist cannot be animated convincingly.
Lighting and contrast
Models interpret contrast as depth. A flat, evenly lit frame gives them almost no spatial information, so motion turns mushy. A frame with clear directional light, a defined shadow, and a separated background gives the model strong cues about what is in front of what. If your source is flat, a quick contrast and shadow pass in an image editor will improve the video more than any prompt tweak.
Background separation
Subjects that blend into their background are the leading cause of edge crawl — that fizzing outline that appears around a person when the model cannot tell where they end. Nudge the background darker or blur it slightly. This is a two-minute fix that saves an entire generation round.
Composing for motion
Leave room in the frame in the direction the camera will travel. A push-in needs headroom above the subject. A lateral track needs space on the leading edge. If the composition is already tight to the frame edge, the model will either refuse to move or smear the boundary.
Consistent series
When you are animating a set of related frames — a product line, a cast of characters — normalise the stills first: same lighting direction, same colour temperature, same crop logic. Consistency at the still stage is what makes the final edit feel like one shoot instead of a collage.
Writing Motion Prompts That Actually Work
Describe the camera, not just the subject
The most useful prompts read like a camera note: slow dolly in, slight handheld drift, gentle orbit to the right, static camera with subject motion only. Camera language gives the model a coherent global transformation to apply. Subject-only prompts force it to invent the movement from scratch, which is where jitter and identity drift come from.
Physical verbs beat adjectives
Beautiful and cinematic are nearly meaningless to these models. Steam rises, fabric ripples, hair sways, liquid pours, dust drifts, leaves fall. Concrete verbs describe actual pixel displacement, and the model responds much more predictably to them.
One motion per shot
Stacking three movements in one prompt is the fastest route to mush. Slow push in while the subject turns and the background pans is three shots pretending to be one. Split it, generate three clips, and cut them together. Editors have been doing this for a century for a reason.
Restraint and negative guidance
If your tool supports negative prompts, use them sparingly and specifically: no morphing, no warping limbs, no extra fingers, no flicker in text. Long negative lists often backfire by pulling the model toward the very concepts you named. Three or four targeted exclusions outperform twenty.
Speed words matter
Slow, gentle, subtle, gradual are not decoration. They measurably reduce the per-frame displacement the model attempts, and lower displacement means higher consistency. When a shot fails, try the same prompt with slower language before you change anything else.
A Repeatable Production Workflow
Step 1: Brief and shot list
Write the shot list before generating anything. For each shot, specify the source frame, the intended duration, the camera move, and the delivery format. Four fields per row is enough. This forces you to notice that you have nine push-ins in a row and no variety.
Step 2: Still generation or curation
Produce or select the stills. If you are generating them, review at thumbnail size first — composition problems are obvious when small and invisible when large. Approve frames in batches, and keep the rejected ones; a frame that failed as a still sometimes works for a different shot in the sequence.
Step 3: Motion passes
Generate two or three motion variants per approved still with different prompt phrasings and durations. Do not evaluate them in isolation. Scrub through them at speed and watch for identity drift between first and last frame. A clip that looks great paused but drifts by the end is unusable in a cut.
Step 4: Finish each clip
Raw output almost always needs three passes: temporal smoothing or frame interpolation to lift the frame rate, an upscale to delivery resolution, and a light grade so the clips match. Interpolation is the highest-leverage step — it turns a 24 fps-feeling clip into something that sits naturally in a 30 or 60 fps timeline.
Step 5: Assemble and version
Cut the clips to a scratch track first, before polishing. You will discover that half your shots are the wrong length, and it is far cheaper to regenerate a two-second clip than to re-edit around a six-second one. Export a low-resolution review cut, get notes, then finish.
Batch Production and Format Adaptation
Once a shot recipe works, treat it as a template: same source framing, same prompt pattern, same duration, same finish chain. Templates are what turn image-to-video from a novelty into a production line.
Format adaptation is where that pays off. One approved vertical master can yield a square version, a 16:9 version, and a six-second bumper by re-running the same recipe with different crops and durations. Rather than regenerating everything from text prompts, keep the approved still as the anchor and let the model re-animate to the new frame. Consistency across formats is a brand requirement, and anchoring to a fixed still is the simplest way to guarantee it.
For high-volume campaigns, queue work in batches of a single shot type. Switching model, aspect ratio, and prompt style every few minutes is the main source of avoidable errors in AI video pipelines.
Common Mistakes and How to Fix Them
Everything warps after two seconds. Your motion is too ambitious for the duration. Cut the clip shorter or reduce the camera move.
The subject changes identity. Anchoring is too weak or the source frame has ambiguous detail. Sharpen the face and hands in the source, and slow the prompt down.
Nothing moves. Your prompt is describing a mood rather than a displacement. Add one explicit camera verb.
Edges crawl and shimmer. Background separation is insufficient. Darken or blur the background slightly before animating.
Text turns to gibberish. Text under motion is brutally hard. Either keep the camera essentially static, or composite the text in post over a clean plate — the second option is almost always better.
Colour shifts between clips. Different models and settings apply different grades. Build a normalisation step into the pipeline and apply it to every clip before assembly.
Good clips, bad sequence. You optimised shots instead of the edit. Cut to a scratch track earlier and let the edit drive regeneration.
Quality Control Checklist
Before a clip is approved, check: does the first frame match the source image exactly; does the subject still look like itself in the last frame; is there any visible flicker in flat areas; do hands, hair, and thin edges stay coherent; does the camera move read as intentional; does the clip cut cleanly against its neighbours; is the resolution and frame rate at delivery spec; and does it survive being watched at half speed?
That last check catches more problems than any other. Slow playback exposes drift, popping, and edge artefacts that look fine in real time.
FAQ
How long should an AI-generated clip be?
Two to five seconds is the reliable zone for most models. Longer clips are possible but should be reserved for slow, simple camera moves on structurally simple subjects.
Can I use image-to-video for talking-head content?
Yes, but lip sync requires a dedicated pipeline. Generate the motion, then apply a lip-sync pass to the finished clip rather than trying to prompt speech into the video model.
Do I need a different prompt for every model?
Yes. Prompt vocabulary is model-specific. Keep a short notes file per model listing the phrasings that worked and the ones that caused drift.
Is upscaling before or after animation better?
After, in most cases. Animate at the model's native resolution, then upscale the sequence. Upscaling stills first inflates generation time without adding information the model can actually use.
How many variants should I generate per shot?
Two or three. Fewer and you accept the first mediocrity; more and you spend your review time on near-identical clips instead of on the edit.
What is the single biggest quality lever?
Source image quality and lighting contrast. Better inputs beat better prompts almost every time.
Can I match a specific visual style across a series?
Yes, by fixing the still-generation recipe first. Styles drift when the stills drift; the video model faithfully amplifies whatever inconsistency you feed it.
Where to Start This Week
Pick one shot type you produce repeatedly — a product hero, a character intro, a title card — and build a single repeatable recipe around it: one source framing rule, one camera move, one duration, one finish chain. Run it ten times. The failures will tell you exactly which variable matters most in your pipeline, and the successes become a template you can hand to anyone on the team.
Image-to-video is not a magic button. It is a controllable, iterable production technique that rewards preparation over prompting, and consistency over novelty. Teams that treat it that way end up with a library of reusable shot recipes; teams that treat it as a slot machine end up with a folder of clips nobody can cut together.
