
Why image-to-video sits at the center of modern AI pipelines
Text-to-video gets the headlines, but image-to-video does the work. When you start from a still frame, you already control composition, wardrobe, palette, product placement, and likeness. The model only has to answer one question: how does this frame move forward in time? That narrower problem produces far more predictable results than asking a model to invent a whole scene from a sentence.
The practical consequence is a review-friendly pipeline. Teams storyboard as stills, get client approval on cheap artifacts, and only then spend heavy generation time on the shots that survived feedback. Revision loops shrink from hours to minutes because the argument is about a locked frame, not a stochastic result nobody can reproduce.
There is also a cost-structure argument. Still-image generation is fast and inexpensive relative to video, so exploratory work should happen there. A director can test twenty framings of a hero shot as images in the time it takes to render two mediocre clips. Image-to-video turns image generation into pre-production, and pre-production is where good video is actually won.
Finally, consistency. Franchises, product lines, and recurring characters live or die on visual continuity. Anchoring each shot to a reference still gives you a repeatable unit of control that pure prompt-based generation rarely matches.
How image-to-video models actually work
It helps to know what the model is doing, because every failure mode maps to a mechanical cause.
Latent diffusion and the temporal consistency problem
Most current systems compress video into a latent space, denoise it, and decode it back to pixels. A still image is encoded into that same latent space and used as the conditioning signal for the first frame — or, in some architectures, injected at every step so the clip never drifts far from its source.
Temporal consistency is the hard part. Each frame is generated in the context of neighboring frames, so small errors compound. That is why a face can look perfect at frame one and slightly melted at frame ninety. Models that enforce stronger cross-frame attention drift less, but they also move less. This is the central trade-off you will manage constantly: fidelity versus motion amplitude.
What models learn about motion
Models learn motion priors from video data: how hair falls, how water ripples, how crowds shift, how cameras pan. They also learn physics approximately, which means they can produce a convincing splash and an impossible bounce in the same clip.
Practically, this means motion prompts work best when they describe familiar, well-represented phenomena. A slow dolly-in on a face, steam rising from a cup, fabric moving in wind — these are densely represented in training data and render reliably. Abstract instructions like make it feel energetic are not motion at all, and the model will guess.
Choosing the right model for the shot
Model choice is a shot-level decision, not a project-level one. Different engines excel at different content, and mixing them inside one edit is normal practice.
Photoreal people and faces
For talking heads, beauty, and lifestyle, prioritize models with strong identity retention and micro-expression handling. Look for smooth eyelid motion and stable teeth — two details that instantly read as fake when they fail. Runway and Kling both handle human motion well in different ways: one tends toward cinematic smoothness, the other toward more energetic movement. Test both on a single portrait before committing a whole sequence.
Stylized and illustrated sources
Animation, 3D renders, and illustration benefit from models that respect flat color regions and hard edges. Luma and Pika-style engines often do better here than photoreal-focused ones, because they are less eager to add skin texture and lighting gradients to something that should stay graphic. If your source is a cel-shaded character, test whether the model preserves line weight across the clip.
Products, architecture, and landscape
These shots need geometric stability. Nothing breaks immersion faster than a building whose windows rearrange themselves. Favor models with strong camera control — explicit dolly, orbit, or crane parameters — and keep motion minimal. A two-second parallax push on a product shot is often more convincing than a five-second flourish. Veo and Sora-class models are strong on physical plausibility, while dedicated image-to-video engines often give you finer manual control over camera paths.
Build a personal matrix: three test images, three models, one page of notes. Reuse it on every project.
Preparing source images that models can actually animate
Garbage in, wobble out. Most disappointing clips trace back to the source frame, not the prompt.
Resolution, aspect ratio, and framing
Generate or upscale your still to at least 1080p on the short edge, preferably higher. Match the aspect ratio to your delivery format exactly — 16:9 for landscape, 9:16 for vertical, 1:1 for square placements. Cropping after generation almost always destroys the composition you carefully built.
Leave breathing room around the subject. If a character fills the frame edge to edge, there is nowhere for motion to go, and the model will either freeze or distort the edges. A modest margin of background gives the camera and the subject room to move.
Lighting, depth, and separation
Models infer depth from cues. Strong subject-background separation, consistent light direction, and visible shadows all help the model understand where things are in space. Flat, frontal, shadowless lighting makes 3D structure ambiguous, and the result is a clip that looks like a photograph being stretched.
Add a touch of atmospheric depth when you can — haze, blur falloff, foreground elements. Even a blurred leaf in the corner gives the model a parallax anchor.
Repairing images before you animate
Fix hands, text, and symmetry problems in the still first. Video models amplify flaws in motion. Text on packaging, in particular, will scramble. Either remove it in the source or plan to composite a clean plate over it in the edit. Text is the single most reliable thing to get wrong.
Prompting for motion, not description
The most common prompting mistake is describing what is in the frame. The model can see the frame. What it does not know is what should happen next.
The four-part motion prompt
A reliable structure covers four things in order:
- Subject motion — who or what moves, and how. The woman turns her head slowly to the left, hair shifting with the movement.
- Camera behavior — static, slow push in, gentle handheld drift, locked-off wide. Be explicit. If you say nothing, you get a default drift that rarely matches your intent.
- Environmental motion — wind, rain, traffic, crowd, fabric, smoke. This is what makes a shot feel alive rather than animated.
- Pacing and duration feel — a slow, continuous take with no cuts; a single unbroken movement over five seconds.
Keep it under roughly sixty words. Long prompts dilute the signal, and the model weights early tokens more heavily anyway.
Negative prompts and known failure modes
Negative prompts are your correction layer. Common entries: morphing faces, extra fingers, warping background, flickering, text artifacts, sudden cuts, oversaturated colors, jittery camera. Do not build a giant list — target the two or three problems you actually observed in previous generations.
If motion is too small, increase subject or camera motion rather than adding adjectives. If the whole frame warps, reduce motion amplitude and add a stability-oriented negative term. If the clip drifts in color, the source image likely has inconsistent white balance.
The end-to-end production workflow
Here is a pipeline that holds up under deadline pressure.
Step 1: Build a shot list with fixed durations
Write the sequence before generating anything. For each shot, record a purpose, a duration, a camera move, and a source-image description. This prevents the classic trap of generating beautiful clips that cannot be cut together because they all last four seconds and all push in.
Step 2: Generate cheap variations, then commit
For each approved still, produce three to five short, low-resolution variations with different motion prompts. Watch them side by side at full speed, then at 25 percent speed. Motion problems are visible in slow motion long before they are visible in real time.
Pick one winner per shot. Do not fall in love with a clip that does not serve the edit.
Step 3: Finalize, upscale, and stabilize
Re-render the selected variation at final resolution with the winning prompt. Then run it through three post steps: upscaling for detail, frame interpolation if you need 60fps smoothness, and stabilization if there is residual jitter. Do not interpolate footage that has morphing artifacts — interpolation makes them worse, not better.
Step 4: Edit, sound, and deliver
Cut to the beat. AI clips rarely have internal rhythm, so the edit supplies it. Add sound design early: room tone, footsteps, cloth movement, ambient beds. Sound is what convinces an audience that a synthetic shot is real. Color grade last, and grade every clip in the same pass so model-to-model differences disappear.
Keeping characters and scenes consistent
Consistency is a systems problem, not a prompt problem.
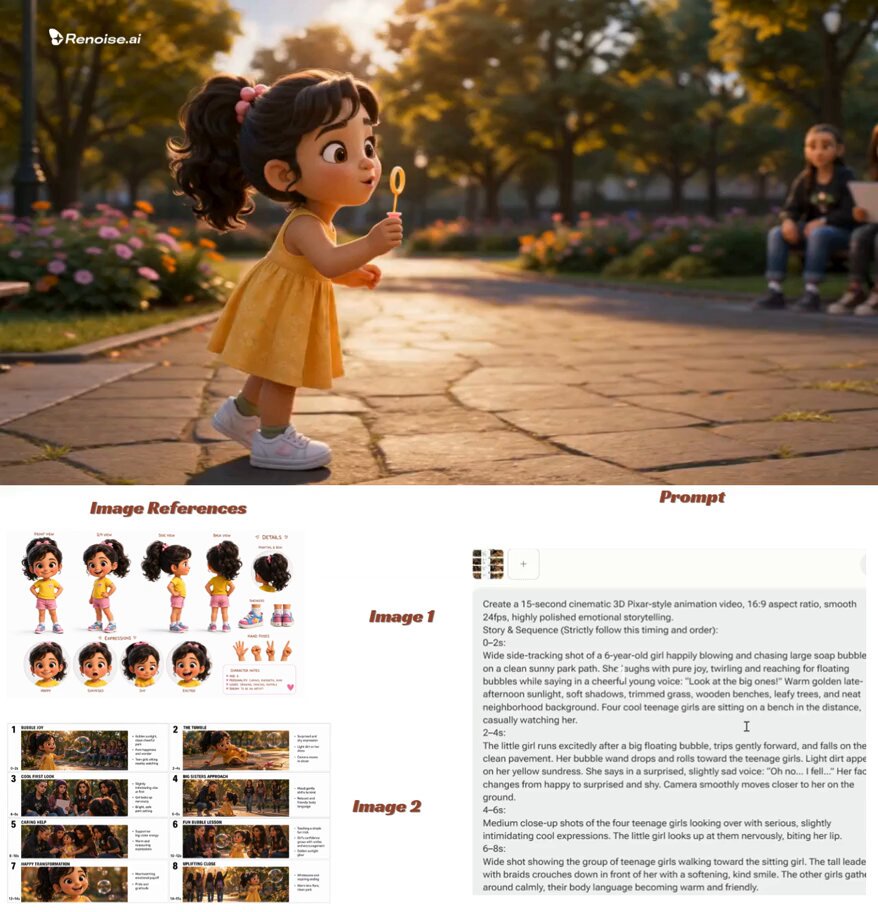
Create a reference sheet per character: front, three-quarter, and profile views under identical lighting. When generating new source images, feed the reference sheet as a visual input rather than relying on descriptive text. Specificity beats adjectives — silver hoop earrings and a scar above the left eyebrow survive re-generation; a friendly face does not.
For environments, lock a palette and a light direction and reuse them across every frame in the sequence. If a scene has warm afternoon light, every still in that scene should share the same color temperature. Keep a written style block and paste it into every prompt so you are not re-deciding.
Multi-image fusion — feeding several reference stills into a single generation — is the most practical way to keep a character recognizable across angles. It also helps with products: supply a front, side, and detail shot, and the model has enough information to maintain geometry.
Finally, accept small drift. Perfect continuity is not the goal; perceptual continuity is. Audiences forgive a slightly different jawline if the wardrobe, lighting, and energy match.
Common mistakes and how to fix them
Over-prompting. Twelve lines of description produce mush. Cut to the four-part motion structure and delete anything the model can already see.
Animating a flat, front-lit portrait. Add separation light or a background gradient to the source image first, then animate.
Ignoring the first and last frames. Clips start and end at whatever the model decides. If you need a specific end state, generate a target image and use first-frame/last-frame conditioning when available.
Rendering everything at maximum quality immediately. You will burn your budget on shots that get cut. Render low, decide, then render high.
Mixing frame rates in one timeline. Standardize on one frame rate before the edit. Mixed sources cause stutter that looks like a generation flaw but is actually an assembly error.
Skipping the slow-motion review. Almost every defect — warping hands, breathing backgrounds, flickering textures — is obvious at quarter speed and invisible at full speed. Make slow-motion review a mandatory gate.
Trusting one model for everything. Different shots want different engines. Build a small library and match the tool to the content type.
Quality control checklist before delivery
Run every clip through the same gate:
- Does the composition match the approved still?
- Are hands, teeth, and eyes stable across the whole clip?
- Is there any text that scrambled or morphed?
- Does the camera move match the shot list intent?
- Is the motion amplitude appropriate for the cut length?
- Does the clip hold at quarter speed?
- Does the color match the surrounding shots?
- Is there a usable first frame and last frame for editing flexibility?
- Does it still work with sound removed?
Any clip that fails two or more items should be re-rendered, not patched in post. Fixing a morphing shot in an edit suite costs more than regenerating it.
Frequently asked questions
How long should an image-to-video clip be?
Two to five seconds is the sweet spot. Longer clips accumulate drift, and short clips cut together more flexibly. If a shot needs eight seconds, generate two clips and join them on a motion-matched cut.
Why does my clip barely move?
Usually the prompt describes the scene instead of the motion, the source image is too tightly framed, or the model is tuned for stability. Specify subject and camera movement explicitly, add background breathing room, and test a model known for stronger motion handling.
Do I need to upscale the source image?
Yes, to at least 1080p on the short edge, and higher if you plan to crop or reframe. Upscaling the source before generation produces sharper output than upscaling the finished video.
What causes faces to morph?
Low resolution on the face, extreme head angles, fast rotation, or a source image with soft focus. Generate the still with a clean, well-lit, front-facing face and keep head rotation gentle.
Can I use the same image for multiple shots?
Yes, and you should. Reusing an approved still with different motion prompts is the cheapest way to build a coherent sequence with varied camera work.
How do I handle text on packaging or signage?
Treat it as a compositing problem. Remove or replace the text in the source image, or plan to overlay a clean graphic in the edit. Expecting a video model to render legible text reliably is a losing bet.
What is the fastest way to learn a new model?
Run the same three test images through it — one portrait, one product shot, one wide landscape — with identical prompts. Ten minutes of comparison teaches you more than an hour of reading documentation.
Bringing it together
The teams that get the most from image-to-video treat it as cinematography with extra steps, not as a slot machine. They lock frames before they animate, they write motion prompts instead of descriptions, they review at quarter speed, and they keep a small stable of models matched to specific content types. None of that requires exotic tooling. It requires treating the still image as the real creative decision — and letting the model do the one thing it is genuinely good at: carrying that decision forward in time.
