
Getting an AI model to animate a still image is easy. Getting it to animate the same person across twelve shots, three outfits, and two lighting setups is where most projects fall apart. Faces widen slightly. Jawlines soften. A scar migrates from the left cheek to the right. Eye color shifts between a close-up and a wide shot. The viewer may not be able to name the problem, but they feel it instantly: the character stops being a character and becomes a series of unrelated people who happen to look similar.
Multi-image fusion is the technique that fixes most of this. Instead of handing a model one photo and hoping the identity holds, you supply a small, deliberately chosen set of references and let the model build a stronger internal representation of who the subject is. This guide walks through that process end to end: how fusion works, how to prepare references, how to prompt, how to pick a model for the shot you are actually making, and how to catch drift before it costs you a full render.
Why Identity Drift Happens in Generated Video
Video models are not designed to remember who someone is. They are designed to predict the next plausible frame. Every time the camera moves, the subject turns, or the light changes, the model re-decides what the face should look like based on the current frame plus the text prompt. Multiply that re-decision across a hundred frames and small errors compound into a visibly different person.
Three forces drive the drift. First, angle change destroys the pixel evidence of identity — a profile view contains far less identity information than a frontal portrait, so the model has to guess. Second, text prompts describe categories, not individuals: "a woman in her thirties with dark hair" fits millions of people. Third, compression, resizing, and denoising smooth away distinguishing marks such as freckles, moles, and asymmetries, which are exactly the details that make a face recognizable.
This is why character consistency is not a single toggle you enable. It is an information problem. The model needs enough stable evidence about the subject to keep re-deriving the same face from every new angle. Fusion is one way of supplying that evidence.
Multi-Image Fusion, Explained Without the Hype
Multi-image fusion — sometimes called multi-reference conditioning — is the practice of supplying several images of the same subject to a generation model at once. The model encodes each image into a representation of identity, attends across them, and conditions the output on that combined signal instead of on a single photo.
The practical consequence is that no single frame carries the full burden of defining the character. A three-quarter shot contributes jawline information. A profile contributes nose geometry and ear position. A full-body frame contributes proportion and posture. When the animation reaches a difficult angle, the fused representation has something to fall back on, so the model invents less.
What the model actually learns from a second image
A single reference gives the model a surface: colors, texture, one specific lighting condition. A second and third image give it structure: which features remain constant when the camera or the light changes. That distinction matters more than most people expect, because a model that has seen only one photo will happily reproduce the lighting of that photo rather than the face underneath it. Two images shot under different lighting teach the model to separate the person from the illumination.
Identity, style, and composition are three different signals
Conflating these is the most common reason fusion disappoints. Identity is the face and body. Style is the rendering — photographic, illustrated, 3D shaded, grainy film. Composition is framing and pose. If your reference set mixes all three, the model averages them, and you get a character whose face sits halfway between two people and whose lighting matches neither. Keep identity references clean and consistent, and describe style separately in the prompt.
Building a Reference Sheet That Survives Animation
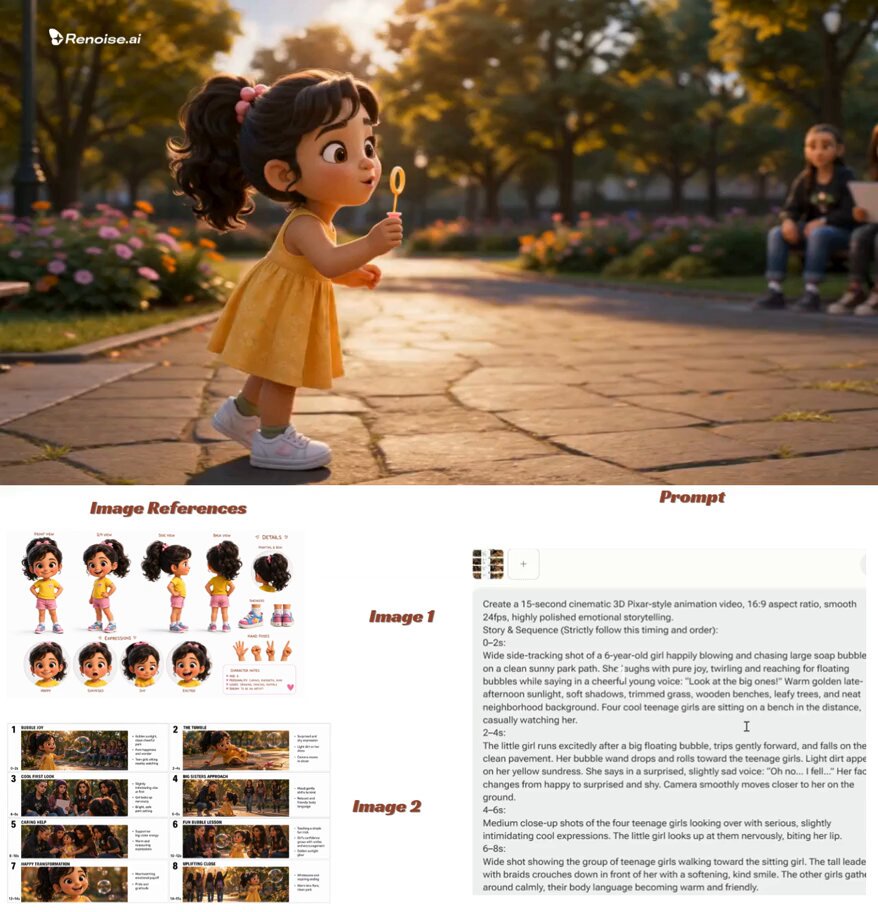
The cheapest insurance against drift is preparation. Before generating a single second of video, assemble a reference sheet — a small, curated set of images that describe your character completely enough that a stranger could pick them out of a crowd.
The five-angle minimum
A workable minimum set looks like this:
- Frontal, neutral expression, even lighting
- Left three-quarter view
- Right three-quarter view
- Full profile
- One full-body or waist-up frame for proportion and posture
If the character appears in action, add one dynamic pose reference. If they wear something distinctive, add a frame where the garment is fully visible. Resist the urge to include ten images; three to six well-chosen references usually outperform a large, noisy set, because every extra image introduces competing information.
Wardrobe and props as identity anchors
For short clips, viewers track continuity through salient details far more than through bone structure. A red scarf, a specific pair of glasses, a moleskin jacket, a chipped tooth — these read as identity markers because they are unambiguous and easy to compare frame to frame. Keep at least one signature accessory constant across every shot, and reintroduce it early in each scene so the viewer re-anchors immediately.
Keep reference backgrounds boring on purpose
Backgrounds leak. A reference photo shot in a busy kitchen can push kitchen-like textures into a scene that should be set in a forest. Shoot or select references against plain, mid-tone backgrounds, and let the video prompt define the environment. This single habit removes a surprising share of unwanted artifacts.
The End-to-End Workflow: From Photos to a Finished Sequence
Step 1 — Write a character bible before you generate anything
Before touching a model, write down the details that must not change: hair color and length, eye color, age range, body type, signature clothing, distinguishing marks, and posture habits. Ten lines is enough. This document becomes your prompt boilerplate and your quality-control checklist. It also prevents the most expensive mistake in AI video production, which is discovering in post that you never decided what the character looks like.
Step 2 — Generate and select anchor stills
Produce a batch of stills that match the character bible, then select for consistency rather than for beauty. The most attractive frame is often the worst anchor, because dramatic lighting and unusual angles carry information the model will struggle to generalize. Choose the clearest, least stylized images. Crop tight enough that the face occupies a substantial portion of the frame, but not so tight that hair and shoulders disappear.
Step 3 — Fuse, then check at thumbnail size
Run your references through fusion conditioning and generate a few test stills from new angles — not the angles in your references. Squint at them. Scale them down to thumbnail size. Identity problems that are invisible at full resolution are obvious at 120 pixels wide, because downscaling strips away detail and leaves only structure. If the face survives the thumbnail test against your other shots, it will survive animation.
Step 4 — Animate in short beats, not long takes
Generate three-to-five second clips rather than twenty-second takes. Short beats keep the model anchored near its conditioning frames, limit how far drift can accumulate, and are far easier to regenerate when one beat fails. Overlap each clip by a second or so with the next one so you have handles for cutting.
Step 5 — Assemble, then match color and grain last
Edit the sequence together before you touch the grade. Watch it once at normal speed with the sound off. Identity errors that seemed severe in a still often vanish in motion, and vice versa — a face that looks correct in every frame can still read as inconsistent because the lighting jumps between cuts. Fix the cut, not the face, when that happens. Apply color matching and grain at the very end, uniformly across the whole sequence, so the footage feels shot at once.
Prompt Patterns That Protect a Face
Subject-first phrasing
Lead every prompt with who is on screen before describing what happens: "the same woman, dark bob, red scarf, subtle freckles" then "walks toward the window and turns to the left." Leading with action makes some models treat the subject as a fresh description rather than a continuation.
Motion verbs that do not rebuild the face
Prefer small, physical verbs — turns, steps, tilts, breathes, glances. Large expressive actions such as laughing, shouting, or screaming force the model to deform facial geometry heavily, and those deformations are rarely reversible across a cut. If a shot genuinely requires a big expression, generate it as its own beat and keep it short.
Keep camera language simple
One camera instruction per clip is plenty. Blending "slow dolly in, then pan right, then tilt up" asks the model to solve three problems at once, and the face is usually what gets sacrificed. Shoot clean single movements and assemble the complexity in the edit.
What to put in negative prompts
Negative prompts are most useful for categorical drift rather than aesthetic polish. Terms that suppress "different person," "face morphing," "changing hairstyle," and "identity swap" do more for consistency than stacking a dozen quality adjectives. Keep the list short and stable across the whole project so you are not introducing new variables between shots.
Choosing a Model for the Shot You Are Actually Making
Model choice matters less than reference quality, but it is not irrelevant. Rather than chasing leaderboards, categorize models by what they are good at.
Match model to motion type
- Talking-head models are strongest on faces and lip sync, but they often fix the camera and limit body movement.
- General image-to-video models handle camera moves and environments better, with weaker facial micro-detail.
- Character-reference models accept multiple identity images and preserve a face across varied angles, at the cost of some motion freedom.
- Stylized or animation models preserve design-line consistency beautifully and photographic identity poorly.
A quick decision framework
Ask four questions before choosing. Does the shot require a recognizable human face? Does it involve a large camera move? Does the character need to appear across multiple scenes? Is the target style photoreal or illustrated? A single-scene, wide, illustrated shot with no close-ups needs almost no identity machinery. A close-up dialogue sequence across five locations needs the strongest reference-driven model you can access plus a disciplined reference sheet.
Quality Control: Catching Drift Before It Costs You a Render
Build a repeatable check that runs before you spend time on a full sequence.
- Generate a single test still from an angle absent from your references.
- Generate a one-second motion test of that still.
- Compare both against your character bible, at thumbnail size.
- Check the signature accessory and one distinguishing mark.
- Only then batch-generate the full sequence.
If the test fails, change one variable at a time: add a reference image, simplify the prompt, reduce motion, or switch models. Changing three things at once teaches you nothing about which one mattered.
Common Mistakes and Their Fixes
Using one reference and hoping. The most frequent cause of drift. Fix: add a three-quarter and a profile view before changing anything else.
Mixing lighting conditions without realizing it. References shot indoors and outdoors teach the model that the character's skin tone changes. Fix: normalize references in a simple editor before fusion.
Over-prompting. Long prompts filled with contradictory descriptors make the model average competing ideas, which reads as a new face. Fix: cut the prompt to identity, action, and one camera note.
Reusing an old reference sheet after a wardrobe change. Now the model has two versions of the character. Fix: rebuild the sheet whenever the character's appearance changes permanently.
Fixing drift in post. Retouching faces shot by shot is slow and rarely convincing. Fix: regenerate the offending beat with stronger conditioning.
Ignoring aspect ratio. Cropping a vertical reference for a horizontal shot removes the shoulders and hair that carried proportion information. Fix: shoot references at the target aspect ratio.
When Consistency Matters Less Than Motion
Not every project needs a stable identity. Product shots, establishing landscapes, abstract transitions, and one-off social clips can prioritize motion quality and ignore fusion entirely. The decision is economic: how much time does consistency work cost, and how much does the audience notice the alternative?
As a rough rule, invest in fusion when a character appears in more than two shots, when close-ups are involved, or when the same character will return in future episodes. Skip it when the subject is anonymous, distant, or on screen for under two seconds. Being strategic here is what separates a finished project from an endless polish loop.
FAQ
How many reference images do I actually need?
Three to five well-chosen images covering distinct angles. More than six tends to add noise unless every image is tightly controlled for lighting and wardrobe.
Can I use images from different sources, like a phone selfie and a studio photo?
You can, but first normalize them: match exposure, white balance, and crop so the face occupies a similar share of the frame. Mismatched references are a leading cause of mid-video face shifts.
Does fusion replace training a custom model on my character?
No. Fusion is fast, flexible, and needs no training time. A trained character model can be more stable for very long projects, but it locks you into one look and requires more setup. Many workflows start with fusion and only consider training when a project exceeds dozens of shots.
Why does the face look fine in stills but wrong in motion?
Still tests evaluate structure; motion exposes temporal instability. Generate short motion tests, not just stills, and check whether the face shape at frame one matches the face shape at frame sixty.
Should I upscale before or after fusion?
After. Upscaling early freezes imperfections in place and makes later correction harder. Generate at a workable resolution, confirm identity, then upscale the approved take.
How do I keep lighting consistent across scenes?
Describe lighting in the prompt with one stable phrase per scene and keep it consistent within that scene. Then unify the sequence with a single color pass at the end rather than grading shot by shot.
What if the character needs to age or change costume mid-story?
Treat each major appearance change as a new reference sheet, built from the original identity references plus the new wardrobe or age details. This keeps the underlying face anchored while allowing the deliberate change.
A Closing Checklist
Before you render a full sequence, confirm that you have a written character bible, three to five normalized reference images covering distinct angles, at least one consistent signature accessory, prompts that lead with identity, motion limited to small physical actions, one camera instruction per clip, and a one-second motion test that passed at thumbnail size. Do those things and multi-image fusion stops being a trick you hope works and becomes a repeatable part of production — the invisible step that lets an audience follow a character instead of a sequence of similar strangers.
