
Why identity drift is the defining problem in AI video
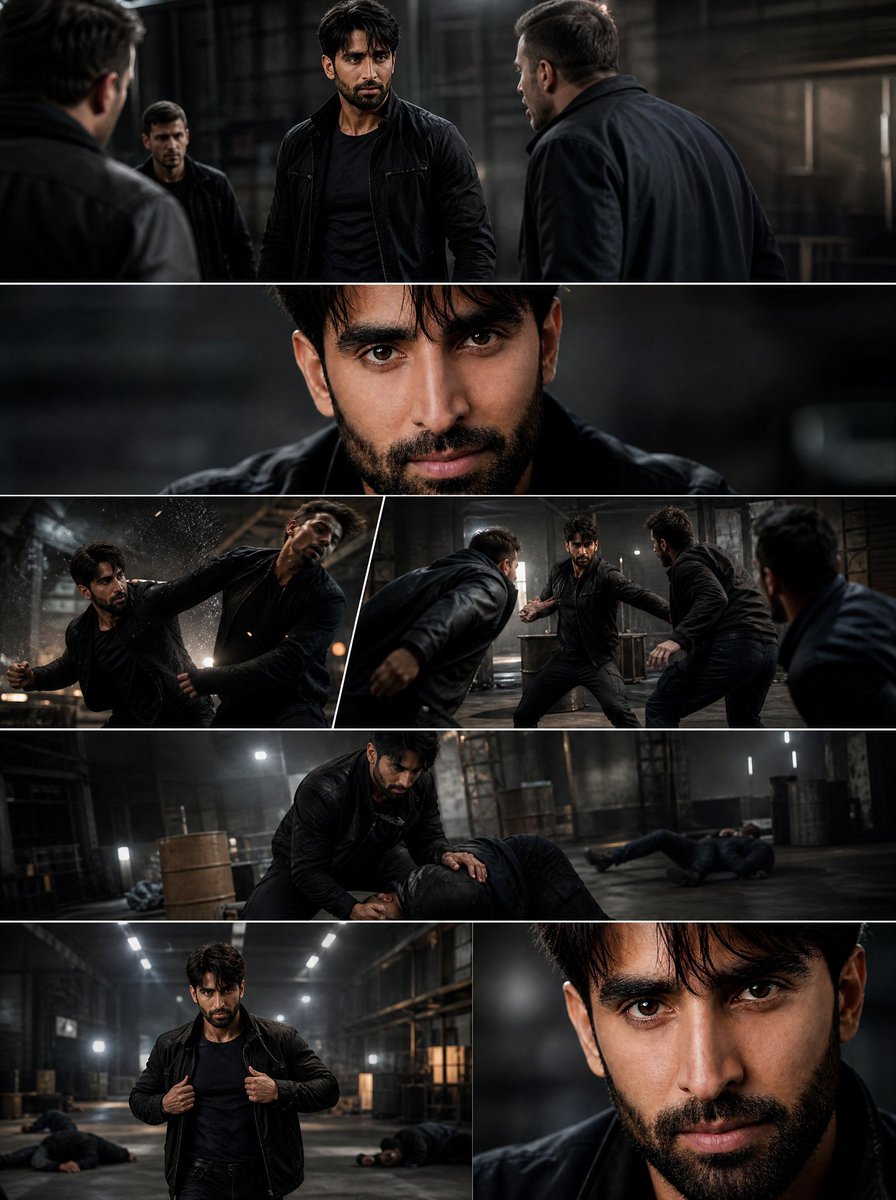
Anyone who has generated more than a handful of AI video clips has met the same wall. The first shot looks fantastic: the face is right, the lighting works, the wardrobe matches the brief. The second shot introduces a stranger with a similar haircut. By the fourth shot, the protagonist has quietly become someone else, and no amount of re-rolling brings the original back.
This is identity drift, and it is not a bug in any single model. It is the natural consequence of how generative video systems work. Each clip is sampled from a probability distribution conditioned on a text prompt, a seed, and whatever reference material you supplied. Change the camera angle, the lens description, the time of day, or the length of the clip, and you change the conditioning. The model then re-imagines the subject from scratch, filling gaps in the prompt with whatever its training data considers plausible.
The practical symptoms are easy to recognise:
- Face morphing between cuts. Jawline, nose width, and eye spacing shift subtly, then dramatically.
- Age and build drift. A character grows younger, taller, or heavier across a sequence.
- Wardrobe mutation. A navy jacket becomes charcoal, then grey, then a different cut entirely.
- Colour and grade jumps. Skin tones shift warmer or cooler depending on the scene's lighting prompt.
- Props that come and go. A scar, glasses, or a ring appears in one shot and vanishes in the next.
For a single social clip, drift is a minor annoyance. For a serialised story, a product demo with a presenter, a training video, or a multi-scene ad, it is fatal. Audiences forgive imperfect physics. They do not forgive a character who changes faces mid-story.
The good news is that drift is largely solvable with workflow discipline rather than luck. The core technique is to stop treating each clip as an isolated generation and start treating the character as a reusable asset that gets fed into every shot.
How multi-image reference fusion works
Older image-to-video pipelines conditioned on a single still frame. That works reasonably well when the output stays close to the reference: same angle, same framing, same lighting. As soon as the shot changes, the single reference stops being informative. A front-facing portrait tells the model almost nothing about what the character looks like in profile, at dusk, or from behind.
Multi-image reference workflows change the input side of the equation. Instead of one image, you supply a small set of images covering different angles, expressions, and lighting conditions. The model encodes each reference into a shared feature space, blends the identity information into an embedding, and injects that embedding into the generation process through cross-attention or an adapter layer. The result is a much more complete internal representation of the subject.
Latent identity versus per-frame appearance
The key mental model is the difference between identity and appearance. Identity is the stable structure: bone structure, eye shape, hairline, skin tone range, body proportions. Appearance is everything layered on top: pose, wardrobe, expression, lighting, lens distortion, film grain, motion blur.
A good multi-image workflow separates the two. Identity features come from the reference pack. Appearance comes from the prompt and the shot design. When those two signals stay cleanly separated, the character survives scene changes. When they blur together, drift returns.
What a strong reference set actually contains
Quality beats quantity here, but coverage beats everything. A workable pack usually includes:
- A neutral front view with even, shadowless lighting and a relaxed expression.
- Two three-quarter views (left and right) to teach the model how the face turns.
- A profile shot, which is where most single-reference pipelines collapse.
- A full-body frame so proportions and build are captured, not just the head.
- Two expression variants — one smiling, one serious — so the model does not lock the character into a permanent neutral stare.
- One alternate lighting condition, ideally warmer or lower key, so the identity embedding is not tied to a single colour temperature.
- A wardrobe reference if the costume is part of the character's signature look.
Eight to twelve well-chosen images is a good target. Forty near-duplicate frames add processing weight without adding information, and they can actively bias the embedding toward one angle.
Where the pipeline usually breaks
The failure points are predictable. Blurry or heavily filtered references teach the model the wrong features. Mixed resolutions confuse the encoder. References generated from different seeds with wildly different faces give the model contradictory identity signals — the embedding becomes an average of several people, and the output looks like none of them.
The fix is boring but effective: generate all references in one session with a locked prompt and seed, curate ruthlessly, and never mix two visually distinct faces in the same pack.
Step-by-step: building a reusable character reference pack
Treat this like asset production, not like prompting. The goal is a folder you can reuse for months.
Step 1 — Write the character bible first. Sixty to eighty words describing only permanent traits: approximate age range, ethnicity or ancestry where relevant, face shape, hair colour and length, eye colour, build, distinguishing marks, and default wardrobe. Leave out mood, lighting, and scene details. Those belong to individual shots.
Step 2 — Generate a character sheet. Use an image model with a locked seed and a prompt built directly from the bible. Ask for a neutral pose on a plain background. Generate a batch and pick the one version you like best.
Step 3 — Expand the sheet into angle coverage. Using the chosen frame as a starting reference, generate the three-quarter views, profile, and full-body shots. Keep the wardrobe and background consistent so only the angle changes.
Step 4 — Curate hard. Reject anything with asymmetric eyes, warped ears, strange hands, or inconsistent jaw structure. A single bad reference can drag the whole embedding off target.
Step 5 — Normalise the files. Same resolution, same aspect ratio, sRGB colour, tight but consistent cropping, no watermark or text overlays. Compression artefacts are a silent killer of identity quality.
Step 6 — Name and version the pack. Something like elena-refpack-v3-2024 invites confusion; use a scheme such as elena_refpack_v3. Keep a short changelog noting which images you swapped and why.
Step 7 — Stress-test before you commit. Generate five deliberately different shots: a close-up at night, a wide shot at golden hour, a profile walking shot, a low-angle action beat, and a soft indoor scene. If the face holds across all five, the pack is ready. If it does not, identify the shot that broke and add a reference that covers that angle or lighting condition.
The whole process takes an hour or two for the first character. Later characters go faster because you are reusing the template.
Writing prompts that hold a face steady
A reference pack does most of the heavy lifting, but prompts still decide how cleanly the identity survives. Consistency comes from structure and repetition, not from eloquence.
Use a fixed prompt skeleton and never reorder it:
[shot type] of [character token], [action], wearing [wardrobe],
[environment], [lighting], [camera and lens], [style suffix]
A concrete example:
Medium close-up of ELENA, walking through a rain-slicked alley,
wearing a charcoal wool coat and black turtleneck, neon signage
glancing off wet pavement, low-key cyan and magenta practicals,
35mm lens, shallow depth of field, cinematic realism
The character token is a placeholder you keep identical in every prompt. Do not paraphrase it. "ELENA" and "Elena, the woman from earlier" are different conditioning signals, and the model will treat them as such.
The style suffix matters more than most people expect. If shot one ends with "cinematic realism" and shot seven ends with "moody film noir," you have changed two variables at once. Keep the suffix frozen for the whole project and change only one element per shot: the action, the environment, or the camera. One variable at a time keeps cause and effect readable.
Avoid descriptors that models interpret inconsistently. Phrases like "chiselled jawline," "striking beauty," or "average build" are vague enough that every generation resolves them differently. Physical specifics — "square jaw," "dark brown eyes," "170 cm, slim athletic build" — reproduce far more reliably. If a trait keeps drifting, move it out of the prompt and into the reference pack instead.
Shot planning and continuity across scenes
The single biggest continuity win has nothing to do with the model. It comes from planning coverage before generating anything.
Write a shot list with one line per clip: shot number, framing, action, environment, lighting, and estimated duration. Then group shots by environment. Generating all the alley shots back to back means the lighting and background stay coherent, and you can reuse a working prompt with only small edits.
Continuity anchors
Pick three or four visual anchors and repeat them deliberately: a signature garment, a prop, a colour motif, and a location detail. Audiences track these unconsciously and read them as continuity. A character who always wears the same battered leather jacket reads as consistent even if the face shifts by ten percent in one shot.
Transitions that hide transitions
Cut points are where drift becomes visible. A few tactics reduce the risk:
- Cut on motion. A turn, a step, or a door closing covers small mismatches.
- Use inserts. A close-up of hands, a phone screen, or a cup of coffee buys you several seconds and lets the audience reset.
- Go to the back of the head. A shot from behind, or a silhouette, is far more forgiving than a full frontal close-up.
- Match the light, not the angle. If two shots share the same colour temperature and contrast, the eye links them even when the framing changes completely.
- Keep a wide establishing shot between two tight ones. It resets spatial context and masks small identity shifts.
When to abandon a shot
If a clip needs four or five regenerations and still looks wrong, the problem is usually upstream. Either the reference pack lacks that angle, or the prompt contains a contradictory descriptor. Chasing it with more re-rolls wastes time. Go back one step and fix the input.
Choosing tools: the decision criteria that matter
Feature lists are noisy. What actually determines whether a tool fits your workflow is a short list of practical questions:
- How many reference images can it accept? One or two is limiting. Four to twelve gives real identity control.
- Does it support both references and start/end frames? Frame conditioning is invaluable for controlled transitions.
- What is the maximum clip length? Short clips mean more cuts, and more cuts mean more chances for drift.
- How well does it handle motion? Identity stability is worthless if the character's arms melt.
- Can you lock a seed and reuse it? Reproducibility is the backbone of iteration.
- How fast is the feedback loop? A tool that returns a draft in under a minute encourages experimentation; one that takes twenty minutes discourages it.
- Does it export clean frames? You will want a still from clip three to use as a reference for clip eight.
- What does the cost model look like at volume? Price per generation rises quickly when a 60-second piece needs eighty attempts.
- How does it handle style consistency across a sequence? Some engines drift in colour grade even when the face holds.
- Are the licensing terms clear? This matters the moment a project becomes commercial.
Test any candidate with the same stress test you used for your reference pack: five diverse shots of one character. That tells you more than any demo reel.
A full workflow walkthrough: one character, sixty seconds
Here is how the pieces fit together for a realistic short project.
Pre-production. Write a one-page story. Break it into eight to twelve shots. Build the character bible and generate the reference pack. Choose a locked style suffix.
Shot generation. Start with the hardest shot — usually a tight close-up with strong lighting — because it exposes identity weaknesses fastest. Once it works, move outward to medium and wide shots. Reuse the previous shot's last frame as a start frame for the next clip whenever the camera continues a movement.
Review pass one. Watch the sequence with sound off at half speed. Mark every frame where the face, wardrobe, or colour grade shifts. Do not fix anything yet.
Repair pass. For each flagged shot, decide whether the cause is a reference gap, a prompt contradiction, or a lighting mismatch. Fix the input, regenerate, and re-check.
Assembly. Cut on motion, insert the coverage shots, and apply a single grade across the whole sequence. A consistent grade hides more identity sins than almost any other trick.
Final check. Watch it once at full speed on a phone screen. That is how most viewers will see it, and small drift that is glaring on a monitor often disappears at that size.
Troubleshooting: symptom, cause, fix
Face changes between cuts. Cause: references too narrow in angle coverage. Fix: add profile and three-quarter views.
Skin tone shifts warm to cool. Cause: lighting prompt changed between shots. Fix: lock colour temperature wording and apply a global grade.
Character looks younger in some shots. Cause: soft lighting plus a beauty-adjacent style suffix. Fix: remove smoothing terms and add a reference with hard, textured lighting.
Wardrobe colour drifts. Cause: vague colour words like "dark jacket." Fix: use specific terms such as "charcoal grey wool coat" and repeat them verbatim.
Eyes look glassy or wrong. Cause: references at low resolution or with heavy eye makeup. Fix: replace with clean, sharp, naturally lit images.
Model ignores the character entirely. Cause: character token buried in a long prompt. Fix: move the token to the front of the sentence and shorten the surrounding text.
Motion looks fine but identity is lost in fast action. Cause: motion blur output exceeds reference strength. Fix: shorten the clip, reduce action complexity, or split the beat into two shots.
Quality control and versioning
At scale, consistency is a production discipline. Build a contact sheet of one frame per shot and eyeball it as a grid — drift that is invisible clip by clip becomes obvious in a grid. Keep a version log for each character pack noting which images changed and which shots improved. Store prompts alongside outputs so you can reproduce a good result months later. And whenever a shot is unusually good, export a still and add it to the reference pack. Your own best outputs make the strongest references.
FAQ
How many reference images do I actually need?
Eight to twelve covering front, both three-quarters, profile, full body, and at least one alternate lighting condition. More only helps if the extra images add genuinely new information.
Can I fix drift after generation instead of before?
Sometimes. Post-processing passes can restore a face, but they add artefacts and cost, and they work best as a safety net rather than the primary strategy. Fix it at the input stage first.
Should I train a custom model instead of using references?
Training gives the strongest identity lock when a character appears in dozens of shots across many projects. For a single short piece, a well-built reference pack is faster and usually sufficient.
Why does the character look right in stills but wrong in motion?
Motion adds temporal sampling variance. Reduce clip length, simplify the action, and avoid extreme angles during fast movement.
Do references conflict with strong style prompts?
They can. Reference strength and style strength compete. If the identity weakens, lower the style intensity rather than rewriting the character description.
How do I keep two characters apart in the same shot?
Give each a distinct silhouette and colour palette, keep them separated in frame, and generate them individually first so you know each identity is stable before combining them.
What is the fastest way to improve an inconsistent sequence?
Apply a single colour grade across every clip, cut on motion, and insert a wide establishing shot between tight shots. Those three fixes resolve a surprising share of visible drift.
Is any of this stable enough for client work?
Yes, with safeguards: lock the reference pack before production, budget time for a repair pass, and keep the character's face out of frame during the hardest action beats.
Key takeaways
- Multi-image references beat single-image conditioning because they teach the model what a character looks like from more than one viewpoint.
- Identity and appearance must stay separate: references carry the face, prompts carry the scene.
- Eight to twelve curated references covering angles, expressions, and lighting outperform hundreds of duplicates.
- Lock the prompt skeleton, change one variable per shot, and never paraphrase your character token.
- Plan coverage and cut on motion; transitions are where drift becomes visible.
- Stress-test a new character with five deliberately different shots before building a scene list around them.
- When a shot fails repeatedly, the problem is upstream — fix the input rather than re-rolling the output.
Character consistency in AI video is less about finding a magic model and more about treating your protagonist as a production asset. Build the pack once, guard it carefully, and every scene that follows inherits the same face.
