
Why character consistency is the hardest problem in AI video
Anyone who has generated more than a handful of AI video clips has run into the same wall. Shot one gives you a protagonist with a warm, rounded face and a leather jacket. Shot two gives you a similar-looking person with a slightly different jaw, a different nose bridge, and a jacket that has somehow become a windbreaker. By shot five, you are looking at a stranger wearing the same clothes.
This is not a prompting failure. It is a structural problem. Most generative video models are conditioned on text, and text is a terrible container for identity. Words like "short dark hair" and "olive skin" describe a category, not a person. Every time the model samples from that category, it lands somewhere slightly different. The result is a cast of near-twins instead of one believable character.
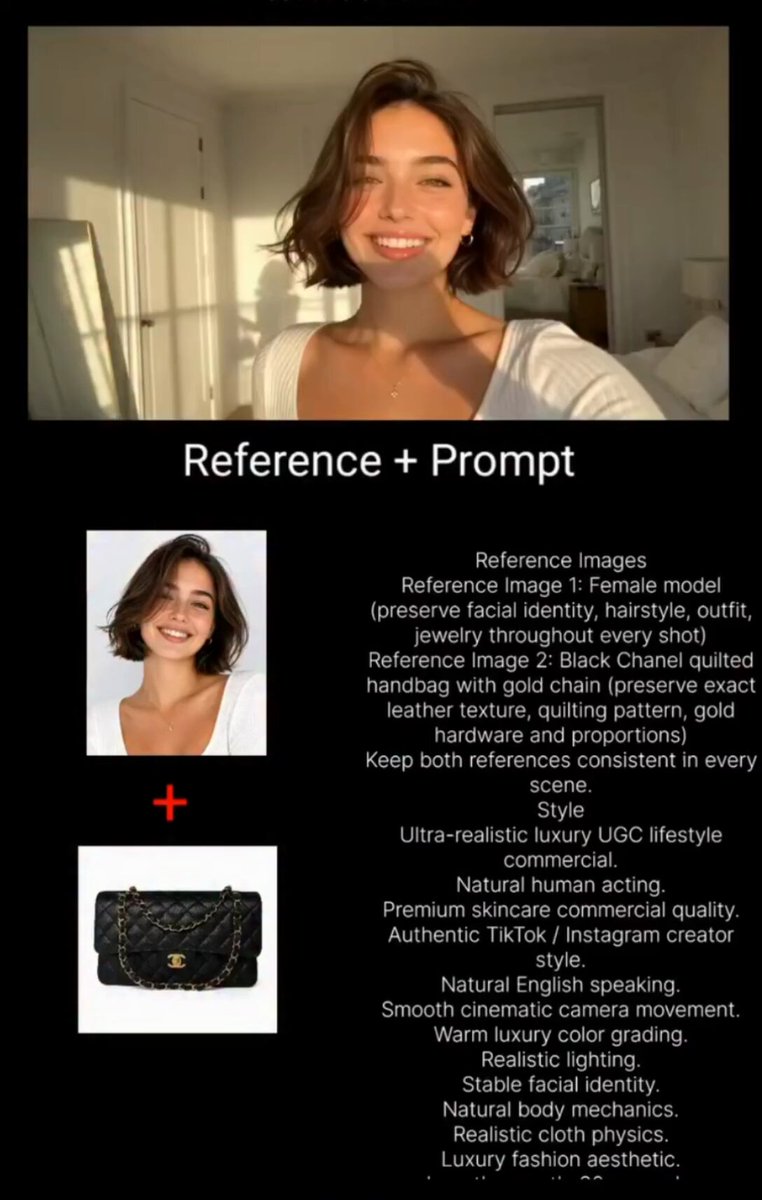
Multi-image fusion is the technique that closes most of that gap. Instead of describing your character in words, you supply several reference images and let the pipeline fuse their identity signals into a single conditioning vector. The model then carries that vector through every frame and every shot, so the face, hair, skin tone, and clothing silhouette remain recognizably the same person.
This guide is a practical walkthrough. It covers how multi-image fusion works, how to build a reference set that actually helps, how to write prompts that support instead of fight the fusion, and how to run quality control so a long sequence does not drift. It is written for people producing narrative shorts, episodic series, branded content, and character-led social video where the same face has to survive dozens of cuts.
How multi-image fusion actually works
Identity embeddings versus per-frame conditioning
There are two broad families of approach, and knowing which one you are using changes how you prepare your inputs.
The first is embedding-based. The system analyzes your reference images, extracts a compact numeric representation of the subject's identity, and injects that representation into the generation process. Because the embedding is derived from several images, it averages out incidental details like a particular lighting setup or a head tilt, keeping only the features that repeat across all references. This is usually the most stable option for long sequences.
The second is per-frame conditioning. Each frame or clip is generated with the reference images attached as conditioning inputs, often through an attention mechanism that cross-references the reference at every sampling step. This gives strong shot-level fidelity but can introduce small instabilities between clips if the reference weighting changes.
In practice, most modern workflows blend both: an identity embedding for global stability plus per-shot reference conditioning for detail fidelity.
What the model can and cannot lock
Multi-image fusion is extremely good at locking facial geometry, hair pattern, skin tone, and general body proportions. It is moderately good at wardrobe, especially distinctive garments with unusual silhouettes or patterns. It is unreliable at fine accessories — jewelry, small logos, thin eyeglass frames — and at anything the reference images do not clearly show.
That last point matters more than people expect. If every reference image shows your character from the front, the model has no information about what the back of their head looks like. It will guess, and it will guess differently in different shots. Fusion is only as strong as the coverage of the reference set.
Why multiple images beat one
A single reference image is one data point. The model cannot tell which features are identity and which are noise — the color cast from the room, the shadow under the chin, the lens distortion at the edges. Give it eight images and the statistics change. Features that appear in all eight are almost certainly the person. Features that appear in one are almost certainly the environment.
This is why a well-curated set of six to twelve references usually outperforms a single beautifully retouched portrait, even if that portrait looks better on its own.
Building a reference set that works
The shot list your character sheet needs
Treat reference gathering like a casting photo shoot. Aim for these angles and conditions:
- Front, neutral expression, evenly lit. The anchor image.
- Three-quarter left and right. Reveals cheekbone and jaw structure.
- Full profile left and right. Critical for shots where the character turns.
- Slight low angle and slight high angle. Teaches the model how the face compresses and stretches.
- Two or three genuine expressions — a smile, a serious look, a mid-speech frame with the mouth open.
- One full-body or three-quarter-body shot for proportions and default posture.
- One shot in motion, ideally mid-stride, to hint at how the silhouette behaves.
If your character wears distinctive clothing, include at least two wardrobe references — one full front, one showing the garment from the side or back.
Resolution, lighting, and consistency of the set
Keep every reference at the same aspect ratio and roughly the same resolution. Mixed aspect ratios force the pipeline to crop or letterbox, which can bias the fused identity toward whatever survives the crop.
Lighting is the subtle one. A reference set shot under five completely different lighting conditions will produce a fused identity that is slightly muddy, because the model has to average across the extremes. The sweet spot is moderate variety: mostly soft, even, front-facing light, with a couple of references under harder or warmer light so the model learns your character's skin response rather than a single color cast.
Avoid references with:
- Heavy beauty filters or skin smoothing that erases texture
- Strong colored gels washing the face
- Sunglasses, masks, or hair covering the eyes in most images
- Motion blur, compression artifacts, or extreme JPEG noise
- Very different ages if the character is meant to be a single age
Cleaning and preparing images
Run a quick pre-pass before feeding anything into a pipeline. Crop to the character, keeping a small margin around the head and shoulders. Normalize exposure so no reference is dramatically darker or brighter than the others. Upscale anything below roughly 1024 pixels on the short side, because fusion quality falls off quickly with tiny inputs.
If you are working with a real actor's footage, get a clean plate first — pull frames where the face is well lit and unobstructed, then remove background clutter so the model does not associate the character with a specific room.
A step-by-step fusion workflow
Step 1: Lock the character bible
Before generating anything, write a one-page character bible: age, build, hair, eyes, skin, signature wardrobe, posture, and two or three personality traits that should show up in body language. This is not decoration. It becomes the spine of every prompt you write, and it prevents you from accidentally drifting the character's presentation over a long project.
Step 2: Generate a canonical anchor frame
Produce a single high-quality still of your character in a neutral pose against a plain background, using your reference set. Iterate until it is exactly right. This frame becomes your master reference. Everything downstream is compared against it.
Step 3: Fuse and test across three shots
Now create three short test clips in genuinely different conditions — a close-up, a medium shot with movement, and a wide shot with the character small in frame. This is the cheapest way to find out whether your fusion setup holds. If identity survives all three, you have a workable configuration. If it breaks in the wide shot, you need more full-body references.
Step 4: Establish shot-level prompts
Write prompts that describe action, camera, and environment, and stay deliberately vague about the face. Repeating detailed facial descriptions alongside strong reference conditioning can create conflict — the text pulls one way, the references pull another. Let the references own identity; let the text own everything else.
Step 5: Generate the full sequence
Work shot by shot in narrative order if possible, so you can catch drift early. Keep the anchor frame attached as an additional reference for every shot, even ones where you think you do not need it.
Step 6: Repair and conform
No pipeline is perfect. Plan a repair pass where you regenerate individual problem shots, then a conform pass where you color-match and stabilize the sequence in an editor.
Prompting and control techniques that protect identity
Keep identity out of the text
A prompt like "a 30-year-old woman with a narrow face, high cheekbones, green eyes, and dark wavy hair, walking through a market" is fighting itself. The references say one thing; the text says a slightly different thing. Better: "she walks through a crowded market at golden hour, medium tracking shot, shallow depth of field, natural motion."
Use seeds and reference weights deliberately
Most diffusion-based video tools accept a seed. Fixing the seed for a shot reduces random variation, which is useful for multi-take comparisons but can also lock in an artifact. A practical habit: fix the seed while you troubleshoot, then vary it once you are happy, keeping the fused identity as the constant.
Reference weight, where exposed, controls how strongly the model clings to your references. Higher weights increase fidelity but can make motion stiff, because the model is being pulled toward static reference frames. Start moderately high, then reduce in small increments if motion looks rigid.
Negative prompts and identity drift
Negative prompts help more than people expect. Terms that suppress generic descriptions — "different person, inconsistent face, changing eye color, morphing features, plastic skin" — push the sampler away from drifting. Avoid stacking dozens of negatives; five to ten relevant terms work better than a wall of text.
Motion prompts that fight fusion
Certain requested motions are inherently hard on identity. Extreme head turns, fast whip pans, and heavy handheld camera shake all reduce the number of frames where the face is legible, which weakens whatever identity anchoring you have. If a shot must include a big turn, break it into two shots and cut between them.
Tools and pipeline choices
Subject-reference image-to-video
Many image-to-video models now accept one or more subject references alongside the driving image. This is the simplest entry point: you supply a character reference plus a first frame, and the model animates while holding identity. It works well for dialogue shots and close-ups, and it is easy to run at volume.
Node-based pipelines
For anything long or complex, node-based environments such as ComfyUI-style graphs give you direct control over reference weighting, identity embedding injection, and per-node conditioning. The cost is setup time. The benefit is reproducibility: once a graph works, it works identically for shot forty as it did for shot one, which is exactly what series production needs.
Character LoRA training
Training a small adapter on your reference set is the heavyweight option. It takes more preparation — typically twenty to fifty curated images, careful captioning, and a training run — but it produces the strongest identity lock available and composes cleanly with different styles and environments. If you are producing an ongoing series with one recurring lead, this is usually worth the upfront effort.
Post-production repair
Even with fusion, expect some shots to be slightly off. Face-swap or face-restoration passes in post can pull a drifted shot back toward the anchor. Use them sparingly: aggressive face replacement flattens performance and creates an uncanny stillness. A light restoration pass on three shots out of thirty is a rescue; on thirty out of thirty it is a warning that your reference set or workflow needs fixing.
Audio, lipsync, and pacing
Once identity is stable, layer dialogue. Test lipsync on a two-second clip before committing to a full scene, and keep mouth-heavy close-ups short. Long talking-head shots are where small identity and lipsync imperfections become most visible.
Continuity beyond the face
Identity is only half of visual continuity. Audiences forgive a slightly soft jawline far more readily than a jacket that changes color between cuts.
Wardrobe. Keep a written and visual wardrobe sheet. If your character wears the same outfit across a scene, include that outfit in several references and mention it explicitly in prompts, because clothing is more susceptible to text conditioning than faces are.
Props. Hero props — a specific bag, a weapon, a coffee cup — need their own reference images. Generate a clean prop still and attach it when the prop is prominent.
Environment. A recurring location should have its own small reference set: establishing wide, mid, and detail shots. Reusing environment references reduces the chance that the background shifts style between cuts, which is often what makes a sequence feel inconsistent even when the character is fine.
Color and grade. Decide a color script early. If shot three is cool blue and shot four is warm orange for no story reason, the sequence reads as broken. Grade the whole sequence at the end rather than grading each shot in isolation.
Camera language. Repeated focal lengths and consistent framing rules make a sequence feel intentional. A character held in medium close-up across a scene will feel more coherent than one whose framing changes drastically every three seconds.
Common mistakes and how to fix them
Too few references, or all from one angle. The most common cause of identity drift. Fix by adding profile and three-quarter angles.
Over-described prompts. Text fighting references. Fix by stripping facial detail from prompts and describing only action, camera, and light.
Mixed-quality reference images. One low-resolution image in a set of eight drags the fused identity toward softness. Fix by culling aggressively; six clean references beat twelve uneven ones.
Inconsistent aspect ratios. Fix by cropping every reference to a single standard ratio before fusion.
Chasing perfection on one hard shot. Some shots resist every technique. Fix by changing the shot — a wider frame, a behind-the-shoulder angle, a cutaway — instead of burning hours on a configuration that will not hold.
Ignoring the full-body references until wide shots fail. Fix by planning for wide shots from the start and capturing body references even if your first scene is all close-ups.
Reusing a good seed across unrelated shots. Fix by treating seeds as per-shot variables, not global settings.
Quality control checklist for long sequences
Run this pass after every batch of five to ten shots:
- Compare the latest shot against the anchor frame side by side at 100% zoom.
- Check hairline, ear shape, eye spacing, and jaw angle — the four features that drift first.
- Check wardrobe color and silhouette consistency against the wardrobe sheet.
- Watch the sequence at normal speed, then at half speed, looking for flicker or identity pulsing at cut points.
- Verify lighting direction matches the scene's established logic.
- Flag any shot that fails two or more checks for regeneration rather than repair.
Keep a simple log: shot number, reference set version, seed, and pass or fail. When something breaks six shots into a sequence, the log tells you quickly whether the cause was a reference change, a prompt change, or random variation.
FAQ
How many reference images do I need? Six to twelve well-chosen images is the practical sweet spot for most tools. Below four, drift becomes likely. Above roughly twenty, you mostly add noise unless you are training a dedicated adapter.
Can I use one image and get good results? Sometimes, if the image is clean, front-facing, evenly lit, and high resolution, and if the shots are all similar in framing. For anything with movement or camera variety, multiple references are more reliable.
Does multi-image fusion work for non-human characters? Yes, and it often works better, because stylized characters have more distinctive silhouettes and fewer ambiguous features for the model to average away.
Why does my character look right in close-ups and wrong in wide shots? Your reference set probably lacks body references. Add full-body and three-quarter-body images, and check that the character occupies a reasonable portion of the frame in the wide shots.
Should I train a custom model or rely on references? Use references for one-off projects and tests. Train a small adapter when you have a recurring character across many scenes, because training front-loads the work and pays it back in consistency and generation speed.
What is the fastest way to fix a single drifted shot? First try regenerating it with a different seed at the same settings. If that fails, add one more reference captured from the angle the shot requires. Only move to post-production face work after both attempts fail.
How do I keep style consistent across a sequence, not just identity? Lock your style descriptors in a saved preset, keep the same model and settings across the project, and grade the finished sequence in one pass.
Getting started this week
Pick one character you intend to use repeatedly and build a proper reference set around them: a neutral front image, two three-quarter angles, two profiles, a couple of expressions, and one body shot. Generate a canonical anchor frame, then run the three-shot test — close-up, medium with movement, wide. Compare results at 100% zoom against the anchor.
Most people find that the test already exposes which references are doing the work and which are dead weight. Cull, re-test, and only then move on to your full sequence. The upfront afternoon you spend curating references will save you far more time than endless prompt tweaking ever will, because multi-image fusion gives the model something text simply cannot: a concrete, consistent, statistically reinforced answer to the question of who your character is.
