
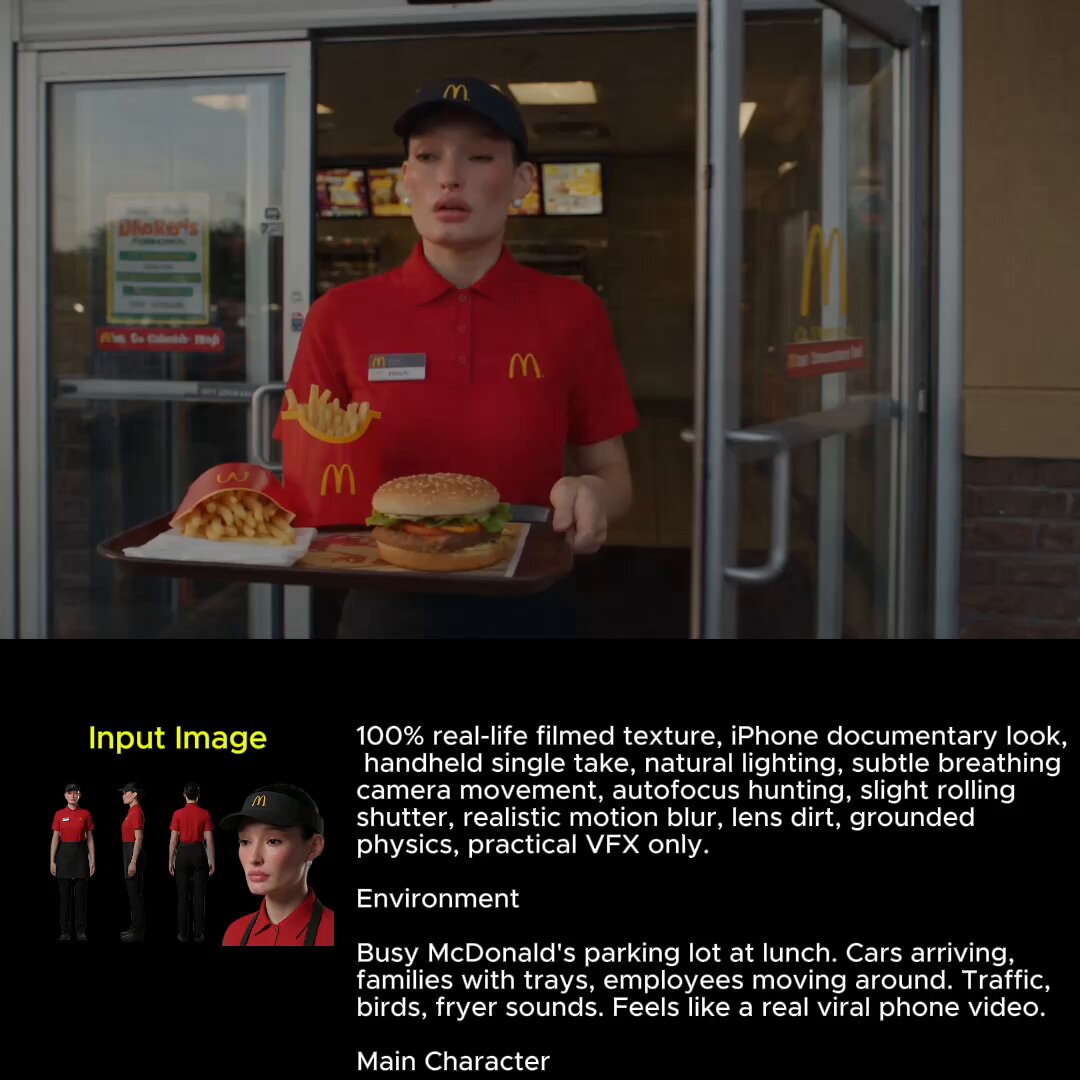
A single still image pushed into a video model gives you a clip. Three, five, or nine coherent stills pushed into the same model give you a scene — and a chain of scenes gives you a film. That is the whole promise of multi-image referencing: conditioning a video generator on several reference frames at once so faces, wardrobe, props, locations, and color palettes survive across shots that were never actually filmed together.
The gap between a lucky clip and a usable sequence is almost never raw model quality. It is continuity. Viewers forgive soft motion, odd hands, or a slightly stylized look. They do not forgive a protagonist whose jawline changes between cuts, or a red coat that turns maroon, then teal, then disappears. Multi-image conditioning exists to close that gap, and learning to use it well is the difference between experimenting with AI video and directing it.
This guide walks through the mechanics, the model-selection decisions, a complete production workflow, prompting patterns, and a troubleshooting list you can return to whenever a sequence starts drifting.
What multi-image referencing actually changes
Traditional image-to-video takes one frame as the anchor and animates forward. The model has exactly one visual truth to protect, so it protects it heavily for the first second or two and then gradually invents. That is why so many single-image clips look convincing at the start and abstract by the end.
Multi-image conditioning changes the contract. Instead of one anchor, you supply a small constellation of anchors: a front-facing portrait, a three-quarter view, a full-body shot in costume, a wide of the location, maybe a prop detail. The model now has to satisfy several visual constraints simultaneously at every timestep. The result is not just a better first frame — it is a persistent identity that survives camera moves, lighting changes, and scene transitions.
There are three practical benefits worth naming clearly:
- Identity lock. Facial structure, hair, and skin tone stay stable even when the subject turns or moves away from the camera.
- Continuity across cuts. Shot two and shot seven can share the same character because both were conditioned on the same reference set, not because you got lucky twice.
- Directable style. A reference frame can carry a grade, texture, or lens character, effectively acting as a look-development document the model respects.
How multi-image conditioning works under the hood
You do not need to read research papers to use this well, but a rough mental model prevents a lot of wasted compute.
Reference slots and attention
Most modern video models accept a limited number of reference images — commonly two to four, sometimes more in specialized pipelines. Each image is encoded into a latent representation and injected into the generation process through cross-attention layers. Practically, this means references compete for the model's attention. If you supply five near-identical portraits, you have spent your reference budget on redundancy. If you supply one portrait, one full-body costume shot, and one environment wide, you have spent it on coverage.
What gets locked and what gets averaged
Models do not treat every detail equally. Identity features — face geometry, hairline, eye spacing — tend to be strongly preserved. Wardrobe and color are preserved but slightly softened. Fine textural detail like fabric weave or freckle placement is often averaged across references. If a detail matters to your story, it needs to appear in more than one reference image, and it helps if it appears at a consistent scale.
Temporal consistency is a separate problem
Multi-image conditioning improves identity, but temporal consistency — the smoothness of a subject across frames within a single shot — is a different axis. A shot can have a perfect face and still flicker like a bad projector. Flicker is usually caused by competing motion prompts, insufficient motion budget, or references that contradict each other in lighting direction.
Choosing the right model for each shot type
No single model wins every shot. The productive approach is to assign shots to models the way a producer assigns scenes to units.
Character-driven dialogue and close-ups
For shots where a face carries the emotion, prioritize models with strong identity preservation and gentle camera response. These handle slow push-ins, subtle head turns, and eye-line shifts well. Avoid models that aggressively reinterpret the reference — they tend to add flattering but wrong detail to faces.
Motion-heavy action beats
For running, fighting, driving, or dancing, prioritize models with high motion ceilings and strong physics priors. Expect to trade some facial fidelity for believable movement. A useful trick is to run the shot twice: once with the full reference set for identity, once with only the environment reference for motion, then choose the better take and use a still from it as the next reference.
Environment and establishing shots
Wides rarely need character references. Give the model a location reference plus a light direction note and let it breathe. Establishing shots are also the cheapest place to establish your grade, because there is no face to distract the viewer from the palette.
Insert and detail shots
Props, hands, weapons, cups, phones, tickets. These shots are continuity landmines. Condition them on a dedicated prop reference and keep the camera almost still. If a prop must move, keep the motion simple and short.
Building a reference set that survives motion
Your reference set is a document. Treat it like a costume bible, not a folder of pretty pictures.
Cover the angles you intend to shoot
If the script calls for a profile shot, include a profile reference. Models extrapolate poorly from a single front view. A minimum viable set for a recurring character looks like this:
- Neutral front portrait, even lighting, neutral expression.
- Three-quarter portrait with a slight expression.
- Full body in the primary costume.
- Full body in the secondary costume, if any.
- A wide shot of the character in the main location.
Match the lighting direction across references
Contradictory lighting is the most common cause of rubbery, unstable output. If your portrait is lit from the left and your full-body shot is lit from behind, the model has to reconcile two incompatible light rigs and will compromise visibly. Shoot or generate your reference set in one lighting setup, then let the video prompt change the light in-scene.
Keep the palette tight
Three or four dominant colors per character, repeated consistently. This makes drift obvious to the eye early, so you catch it before you have rendered twenty shots with the wrong jacket.
Common reference mistakes
- Same pose, five times. Coverage is worth more than volume.
- Heavy stylistic filters in references. The filter becomes part of the identity and bleeds into every shot.
- Low resolution or noisy references. Garbage in, mush out — upscale and denoise first.
- Multiple people in every reference. If the model is not told who matters, it may blend two faces.
- References that fight the prompt. Asking for a night scene while every reference is daylight forces the model to improvise.
A practical end-to-end workflow
Here is a workflow that scales from a thirty-second short to a five-minute narrative piece.
Step 1: Script to shot list
Write the script, then break it into numbered shots with a column each for characters present, location, time of day, camera movement, and duration. This table becomes your production database. Every later decision — references, model choice, prompt — attaches to a shot number.
Step 2: Generate and curate keyframes
Produce the still for each shot before animating anything. Iterate on the still until it is right. Keyframes are cheap relative to video, and a mediocre keyframe becomes an expensive, unusable clip. Approve stills in batches and keep a rejected folder so you can revisit ideas later.
Step 3: Assemble per-character reference sets
Group approved keyframes by character and location. Pick the three or four strongest as canonical references. Keep them in a dedicated folder with a naming convention that includes character, costume, and lighting: mara_coat_day_front, mara_coat_day_threequarter.
Step 4: The conditioning pass
For each shot, load the keyframe plus the relevant character references plus one location reference. Write a short prompt covering action, camera, and lighting only. Do not re-describe appearance — the references already carry it, and duplicating appearance in text often fights the images.
Step 5: Motion prompting and camera language
Keep motion instructions concrete and singular. "Slow dolly in, subject turns head to the right, hair moves slightly" works. "Dynamic cinematic movement with energy and emotion" does not. If a shot needs two motions, consider splitting it into two shots.
Step 6: Review, replace, re-condition
Watch every clip at full speed, then scrub frame by frame. Face drift usually appears at the transition points, not the middle. When a clip fails, replace the failing reference rather than adding more prompt text.
Step 7: Assembly and finishing
Cut in an editor. Stabilize, color match, add sound design. Audio does enormous work hiding micro-flicker — a footstep or room tone on a cut makes the eye far more forgiving.
Prompting patterns for multi-reference shots
Structure prompts in a fixed order so you can debug them: subject action, camera behavior, lighting, atmosphere, negative constraints.
- Action: "She sets the cup down and exhales."
- Camera: "Static medium shot, shallow depth of field."
- Lighting: "Warm practical lamp from camera left, cool window fill from behind."
- Atmosphere: "Dust in the air, quiet interior."
- Negatives: "No camera shake, no zoom, no added characters."
Two patterns are worth memorizing. First, the continuation pattern: end shot one on a clean frame, export it, and use it as the starting frame for shot two alongside the same character references. This chains continuity across a sequence. Second, the anchor-and-release pattern: use full references for the first half of a shot and rely on motion for the second half, so the model is not over-constrained when the character needs to move freely.
Troubleshooting common failures
Face drift mid-shot
Cause: references emphasize different angles or lighting. Fix: rebuild the reference set with consistent lighting, reduce the number of references, and shorten the shot.
Costume morphing
Cause: wardrobe detail is not represented at full body scale, or the motion prompt implies a change. Fix: add a full-body reference and remove any word in the prompt that could suggest transformation.
Flicker and boil
Cause: conflicting motion prompts, or aggressive style references. Fix: simplify to one motion verb, reduce motion strength, and drop the stylistic reference.
Style jumps between shots
Cause: different models per shot with no shared look reference. Fix: create a single graded still as a look reference and apply it to every shot, or commit to fewer models per sequence.
Waxy, over-smoothed faces
Cause: upscaling references too aggressively or stacking too many references of the same person. Fix: use a clean, non-upscaled portrait as one of the references and reduce redundancy.
A quality control checklist before export
Run this list against every finished sequence:
- Face identity holds at first frame, midpoint, and last frame of each shot.
- Wardrobe color matches across cuts under the same lighting condition.
- Props appear in the same hand, same orientation, same scale.
- Screen direction of movement is consistent across a conversation or chase.
- Eye lines match between reverse shots.
- Background elements do not teleport between cuts of the same location.
- Grain, contrast, and color temperature are consistent.
- Audio cues land on cuts, not near them.
If three or more items fail, do not patch — re-condition the offending shots from new keyframes.
Planning time, compute, and iteration
Assume a ratio of roughly five to eight generated clips for every one that survives. Budget accordingly, and budget most heavily on keyframes, because fixing a still is minutes of work and fixing a clip is an afternoon. Batch similar shots together when you have generation capacity available, since loading and conditioning a reference set once for several variations is more efficient than doing it shot by shot.
A realistic split for a three-minute narrative short is roughly 40 percent keyframe production, 35 percent video conditioning and review, and 25 percent editing and sound. Teams that invert this and spend everything on video generation usually end up with beautiful isolated clips and an unwatchable sequence.
FAQ
How many reference images do I actually need?
Three to five per recurring character is the sweet spot. Fewer and identity drifts; more and references start competing, which produces averaging artifacts.
Can I mix models across a single sequence?
Yes, and it is often the right call. Keep one shared look reference and one shared character reference set, and assign shots to models based on motion needs. Consistency comes from the references, not from the model.
Does multi-image conditioning replace a good prompt?
No. It replaces the parts of the prompt that describe appearance. You still need clear action, camera, and lighting language.
Why does my character look right but move strangely?
Identity and motion are separate conditioning paths. Improve motion by simplifying the motion instruction, reducing motion strength, and giving the model a clearer starting frame.
Should references be real photos or AI-generated stills?
Both work. Generated stills are often better because you control lighting and costume exactly, and they already match the look you want the video to inherit.
How do I handle crowds and background characters?
Do not condition them individually. Condition the environment, describe the crowd in words, and keep crowd members out of focus and in the background.
What is the single biggest mistake beginners make?
Treating the reference set as a mood board. It is a technical specification. Every image in it should answer a question the model will otherwise answer incorrectly.
Where to go from here
The shift from clip-making to sequence-making is mostly a discipline change. Build shot lists, build reference sets, keep lighting consistent, prompt only what the images cannot say, and review frame by frame. Multi-image referencing gives you the tools to hold a world together across dozens of shots — but the throughline is still yours to design. Start with one character, one location, and a three-shot sequence. Nail continuity there, then scale the same pipeline to a full film.
