
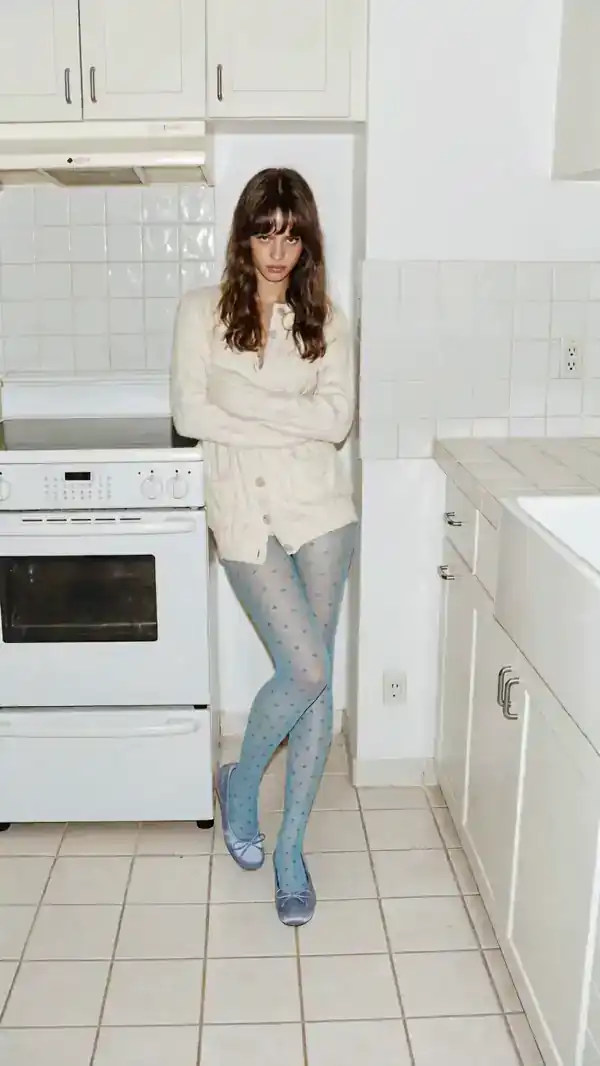
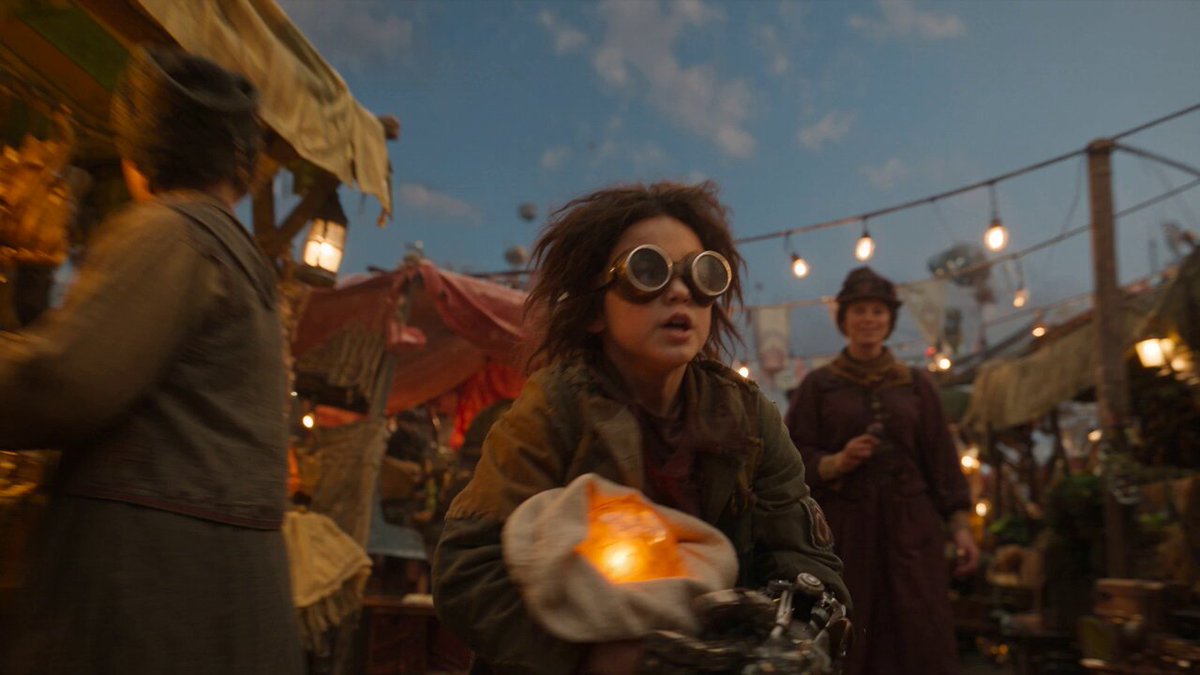
Why Photorealism Became the Real Benchmark
A few years ago, the novelty of AI video was enough. A slightly melted face, a hand with six fingers, or a background that pulsed like a lava lamp were acceptable trade-offs for the sheer magic of typing a sentence and getting motion back. That era is over. Audiences have seen enough synthetic footage to develop a fine-grained detector for fakeness, and clients have learned to reject anything that flickers, warps, or breathes unnaturally.
The result is that photorealism — not concept generation — has become the primary competitive battleground for video models. The interesting question is no longer "can a model generate a video?" but "can it generate a video that survives a full-screen viewing on a large display without the viewer noticing something is off?"
That shift changes how you should evaluate tools. A model that produces gorgeous still frames but drifts over four seconds is less useful than a model that produces slightly less striking frames with rock-solid temporal stability. A model with breathtaking physics but poor prompt adherence will cost you more time in re-rolls than it saves. This guide walks through the criteria that actually matter, how the major model families differ in practice, and a repeatable workflow for producing believable footage.
What "Photorealistic" Actually Means in Generated Video
Photorealism is not a single property. It is a stack of four layers, and a clip only fails if any one of them breaks.
Surface and material fidelity. Skin needs subsurface scattering, not a plastic sheen. Metal needs anisotropic highlights. Fabric needs visible weave at close range. When materials look wrong, viewers describe the result as "AI-looking" even if they cannot articulate why.
Lighting physics. Shadows must fall consistently with the light source. Practical lights inside the frame should cast light on nearby surfaces. Reflections need to move correctly as the camera moves. Broken lighting is the single most common giveaway in otherwise strong generations.
Motion plausibility. Weight, inertia, and contact matter more than raw smoothness. A hand that touches a table without deforming or occluding correctly will read as fake, no matter how clean the render.
Temporal stability. The frame-to-frame consistency of texture, identity, and geometry. High-frequency detail like hair, foliage, and gravel is where instability shows up first.
When you evaluate a model, score each layer separately. Most tools are strong in one or two and weak in the others, and knowing which is which lets you combine them intelligently instead of searching for a single perfect option.
Evaluation Criteria That Separate Usable Models from Demos
Temporal coherence and flicker
The hardest problem in the field. Watch for texture swimming, edge crawling, and slow identity drift over the length of a clip. Generate the same prompt several times and inspect the fifth second, not the first — most instability compounds.
Prompt adherence and camera control
A model that ignores half your prompt is a model you cannot direct. Test with compound prompts: subject, action, camera movement, lens, lighting, and environment. Note which elements consistently survive and which get dropped.
Motion physics and contact realism
Look for footfalls that plant, objects that rest on surfaces, and cloth that responds to movement. Physics failures are usually more damaging than aesthetic ones because they are immediately legible.
Identity and style consistency
For any multi-shot project, you need the same character, wardrobe, and grade across cuts. Reference-image support, character locking, and style transfer tools are what make episodic or campaign work viable.
Resolution, duration, and aspect flexibility
Native output resolution matters less than how gracefully the model handles upscaling and reframing. Vertical, square, and ultra-wide crops should all hold up without recomposing the scene.
Iteration speed and predictability
A model that takes ten times longer but gives you the shot on the first attempt is often faster overall. Track your hit rate, not just generation time.
The Model Landscape, Grouped by Strength
Rather than ranking models one through ten, it is more useful to group them by what they are genuinely best at. Strengths cluster by architecture lineage and training philosophy.
Western commercial platforms
Runway's Gen-3 and Gen-4 generations are known for cinematic camera control, strong stylistic range, and dependable motion for medium shots. They are a solid default for narrative and advertising work where direction matters as much as realism. Luma's Ray 2 line is particularly strong at large-scale coherence — wide landscapes, long camera moves, and shots where the environment itself must stay stable across many seconds. Sora-class models tend to excel at physical plausibility and complex scene composition, often producing the most convincing results in shots with multiple interacting subjects.
Asian lab models
Kling's series has become a reference point for human motion and facial expression, especially in close-ups where micro-expressions matter. PixVerse's later versions put unusual emphasis on cinematic controls and multi-reference workflows, which is valuable when you need to lock several elements — a product, a location, a face — into one shot. MiniMax's Hailuo line is frequently praised for physical realism and a natural, slightly charming quality in everyday scenes, which makes it a strong choice for lifestyle and documentary-style content.
Image-first pipelines feeding video
Flux-family models are image generators, not video engines, but they matter enormously in video work. The highest-quality AI video pipelines usually start with a carefully generated or photographed still used as the first frame, then let a video model animate it. This approach gives you precise control over composition and lighting before a single frame moves, and it dramatically improves consistency across shots.
Open-weight and self-hosted options
Open models have closed much of the gap on still images and are narrowing it on short clips. Their real advantage is control: no queue, no content filter surprises, and the ability to fine-tune on your own footage. Their disadvantage is operational overhead — you own the infrastructure, the failures, and the maintenance.
| Shot type | What matters most | Best-fit approach |
|---|---|---|
| Talking head close-up | Facial identity, micro-expression, lip sync | Model with strong face locking plus a reference still |
| Product beauty shot | Material fidelity, controlled lighting, slow moves | Image-first keyframe, then short animated takes |
| Wide establishing landscape | Large-scale coherence, stable horizon | Model tuned for long coherence and camera moves |
| Action with physical contact | Motion physics, contact realism | Model with strong physics; keep shots short |
| Multi-shot brand campaign | Cross-shot identity and grade consistency | Reference-driven workflow with a locked look bible |
| Fast social b-roll | Speed and volume | Fast, cheap model plus aggressive editing |
A Practical Photorealistic Workflow, Start to Finish
Step 1: Lock the look before you generate
Write a one-page look bible: lens family, color temperature, contrast curve, grain, and the reference films or photographs you are matching. Every subsequent decision should be justifiable against that page. Most disappointing AI video projects skip this step and try to discover the look through generation, which is slow and rarely converges.
Step 2: Build a reference kit
Collect or generate stills for each hero element: the character from three angles, the location in two lighting conditions, the product on two backgrounds. These stills become inputs to the video model and anchors for consistency. In practice, a strong reference kit eliminates more re-rolls than any prompt trick.
Step 3: Generate in short, controlled takes
Resist the urge to request a long clip. Generate three to five seconds at a time with a single clear action, then stitch. Short takes keep the model inside its coherence envelope and give you edit points. A ten-second shot assembled from three generations usually looks better than a single ten-second generation, because you can discard the weak segments.
Step 4: Extend, interpolate, and stabilize
Use frame interpolation sparingly — it smooths motion but can introduce a soap-opera quality and ghosting on fast movement. Stabilization should be applied with intent, since AI footage often has a subtle shake that reads as realistic and should sometimes be preserved.
Step 5: Finish in the edit
Color grade, grain overlay, lens vignette, subtle chromatic aberration, and a realistic audio bed do more for believability than any additional generation pass. Sound design in particular is underrated: an AI clip with proper foley reads as real footage far more readily.
Step 6: Upscale deliberately
Upscale only after you have locked the cut. Different upscalers handle synthetic texture differently, and some amplify the exact high-frequency artifacts you are trying to hide. Test on a short segment before committing the full timeline.
Prompting Techniques That Move the Needle
Photorealistic prompting is closer to cinematography than to copywriting. Describe the camera, the light, and the action — not the mood adjectives.
| Weak prompt | Strong prompt |
|---|---|
| "A realistic woman walking in a city, beautiful, cinematic" | "Medium close-up, 50mm lens, woman in a gray wool coat walks left to right past a wet storefront, overcast morning light, shallow depth of field, camera tracks alongside at walking pace" |
| "A product shot of a watch, luxury, 4k" | "Macro shot of a steel watch on black acrylic, single soft key from upper left, slow 15-degree orbit, reflections of the softbox visible on the bezel, no visible fingerprints" |
A few reliable principles:
- Name the lens and framing. Focal length and shot size communicate more about the final look than any style word.
- Specify light direction and quality. "Soft key from camera left, warm practical in background" beats "dramatic lighting."
- Describe motion with verbs, not adjectives. "Pours," "settles," "scrapes," and "turns" give the model physics cues.
- Keep one action per take. Two simultaneous actions in one short clip usually produce mush.
- Use negatives sparingly and concretely. "No text overlays, no lens flare" works better than a long list of aesthetic prohibitions.
Common Failure Modes and How to Fix Them
| Symptom | Likely cause | Fix |
|---|---|---|
| Faces morph over time | Weak identity conditioning | Use a reference image, shorten takes, regenerate rather than extend |
| Background texture swims | High-frequency detail with low temporal stability | Reduce detail density, add slight motion blur, or generate in a shallower depth of field |
| Hands look wrong | Physics and contact modeling limits | Frame hands out of shot, use a wider shot, or place hands on a surface |
| Lighting changes mid-clip | Underspecified light setup | State light direction and quality explicitly, avoid ambiguous "cinematic" descriptors |
| Motion feels floaty | Missing weight cues | Describe surface contact, add footfalls, reduce camera speed |
| Everything looks plastic | Shallow material description | Specify material behavior: wool, brushed steel, matte ceramic, unpolished wood |
Budget, Speed, and Scale: How to Decide
Not every shot deserves the same effort. Sort your shot list into three tiers.
Hero shots — the three to five seconds that sell the entire piece. Spend your best model, your best references, and as many takes as it needs. Consider generating the still, animating it, and finishing it in post.
Supporting shots — mid-tier coverage that carries the story. Use a fast, reliable model with a strong reference kit. Accept a slightly lower ceiling in exchange for predictable throughput.
Filler and b-roll — texture, atmosphere, transitions. Generate at volume with the cheapest reasonable option. These shots pass by quickly and rarely need to survive close scrutiny.
This tiering matters because the most common budget mistake in AI video production is treating every shot as a hero shot. That approach burns time on material nobody will look at while starving the shots that actually carry the message.
The second most common mistake is the opposite: refusing to invest in the hero shot, then trying to fix a weak generation in post with grading, sharpening, and speed ramps. Post can rescue a mediocre shot; it cannot rescue a broken one.
Quality Control Checklist Before Delivery
Run every clip through the same checklist before it enters the timeline:
- Watch at full screen, on the largest display available, at normal speed and in slow motion.
- Check hands, teeth, ears, jewelry, and any thin structures.
- Verify shadows and reflections stay consistent with the light source throughout.
- Confirm identity does not drift between the first and last frame.
- Look at the edges of the frame — artifacts often hide at the borders.
- Mute the audio and watch again; visual problems become more obvious without sound.
- Play the clip in context with neighboring shots to confirm grade and motion continuity.
- Confirm the clip survives the final delivery codec, which can introduce banding in smooth gradients like skies and walls.
Frequently Asked Questions
Which model produces the most photorealistic video?
There is no single winner, because photorealism is layered. Some models lead on faces and human motion, others on wide-scene coherence, and others on physical plausibility in complex interactions. The practical answer is to pick two or three models for different shot types and standardize your workflow around that small toolkit rather than chasing a single universal option.
How long should AI-generated clips be?
Shorter than you want. Three to five seconds per generation is the sweet spot for most workflows. Longer clips are possible, but instability compounds, and you lose the ability to discard only the weak portion of a shot.
Do I still need a real camera?
For hero product shots, hands interacting with objects, and anything requiring precise brand accuracy, shooting practically is often faster and cheaper. AI video is most valuable for environments, scale, impossible locations, and volume — the places where a real shoot would be slow, expensive, or physically impractical.
Why do my clips look fine on a phone but wrong on a monitor?
Because instability lives in high-frequency detail, and small screens hide it. Always review at the largest size available, and ideally at 100% zoom on a section of the frame with fine texture.
Can I use the same character across multiple shots?
Yes, with reference-image conditioning and a consistent look bible. Generate your character stills first, lock the wardrobe and lighting, and reuse those references for every shot. Expect to regenerate occasionally when the model drifts.
How much post-production is normal?
Assume that generation gets you roughly seventy percent of the way, and post handles the rest. Grading, grain, sound design, and editorial pacing are what push AI footage from "impressive demo" to "broadcast-ready."
Where to Go Next
The practical path forward is to stop evaluating models in the abstract and start evaluating them against your own shot list. Take five representative shots — a face, a product, a wide landscape, an action beat, and a multi-shot continuity test — and run them through two or three candidate models using the same references and prompts. Score each result on temporal stability, prompt adherence, physics, and consistency.
That small experiment will tell you more than any comparison chart, because it measures the only thing that ultimately matters: how reliably a given tool produces footage you can actually finish. Build your toolkit from the results, write down the settings and prompt patterns that worked, and treat that document as your production standard. Photorealism is no longer a lucky accident of a good generation — it is the output of a disciplined process, and the teams that treat it that way are the ones whose work stops looking generated at all.
