
Why the static image is no longer the finish line
A polished still frame used to be enough. A hero product shot, a portrait with perfect skin texture, a landscape with believable light — that was the deliverable. Today, the same client who approved that frame will ask a simple follow-up: can it move? Not in a cartoonish way, not with the waxy uncanny drift that defined early generative video, but with the same material realism the still image had.
That request is the whole problem in one sentence. Photorealism in a still image is a spatial problem: get the lighting, albedo, geometry, and grain right in a single frozen moment. Photorealism in video is a temporal problem on top of that. Every one of those properties has to stay coherent across dozens or hundreds of frames, through motion, occlusion, and changing camera angles. A single frame with a slightly off ear or a warped hand is a curiosity. Thirty frames of an off ear is a ruined shot.
This guide is written for people who already understand composition, lighting, and edit rhythm — directors, motion designers, product marketers, in-house creative teams — and who now need to fold synthetic footage into real production pipelines. It covers the technical foundations in plain language, how to choose between model classes, a repeatable end-to-end workflow, prompting patterns that actually move the needle on realism, quality-control checks, and the mistakes that quietly destroy otherwise good work.
What changes when the output is video
When you move from images to video, four constraints appear at once, and they interact.
Temporal consistency. The model must decide not just what the scene looks like, but how it evolves. Identity, lighting direction, fabric weave, hair strands, and background geometry all need continuity. Drift is the default failure mode.
Motion plausibility. A generated clip can be perfectly sharp and still feel wrong because the motion physics are off — a coat that does not react to wind, a foot that does not plant, a camera move that accelerates without reason.
Compute reality. Video generation costs orders of magnitude more than image generation, both in time and in money. Iteration speed becomes a creative constraint, not just an operational one. You cannot explore twenty variants casually.
Editorial integration. The clip has to cut against real footage, match a color space, survive compression, and hold up on a phone screen at arm's length. Perfect generation that cannot be graded or cut is not useful.
Understanding these four constraints changes how you plan. Instead of asking "what image do I want," you ask "what shot do I want, how long does it need to be, and what is the cheapest way to verify it works before committing?"
The technical foundations, without the math
You do not need to read architecture papers to work well with these systems, but you do need a mental model of what the model is actually doing, because it tells you where it will break.
Temporal consistency and how drift starts
Generative video models produce frames in relation to previous frames or in relation to a latent representation of the whole clip. Either way, small errors compound. If frame ten is slightly warmer in tone than frame nine, by frame eighty the shot can look like it was lit by a different sun. Drift shows up in three places first: skin tone, fine textures like knitwear and foliage, and background details like window frames or signage.
Practical consequence: shorter clips are more reliable than longer ones. Four to six seconds per generation, then extend or stitch, almost always beats a single twenty-second request. You also get earlier feedback and cheaper iteration.
Reference conditioning and multi-image fusion
Most modern pipelines let you condition generation on one or more inputs: a start frame, an end frame, a subject reference, a depth pass, a matte, or a motion reference. Multi-image fusion — feeding several stills of the same subject or scene from different angles — is one of the most effective realism levers available, because it constrains identity and geometry that a text prompt cannot describe precisely.
If you have a real product, photograph it from five angles under consistent light before you generate anything. If you have a real actor, capture stills with neutral expression, three-quarter turn, and profile. That folder of references is worth more than any prompt you will write.
Motion control: camera, subject, and timing
Professional work usually needs separated control over three things: camera movement, subject movement, and pacing. Some tools expose these as distinct parameters or as control inputs such as depth sequences, poses, or motion transfer from a driving clip. Others conflate them, which is why a prompt like "slow dolly in while she turns and smiles" sometimes produces a spinning room.
Rule of thumb: describe one motion per generation. If a shot needs a dolly and a turn, generate the dolly and let the turn be a separate beat, or accept a lower success rate and budget for retries.
Choosing the right model class for the shot
There is no single best model. There are model classes with different trade-offs, and the professional skill is matching class to shot.
Realism-first models
These prioritize material accuracy, skin rendering, and stable lighting. They are slower and more expensive per second, and they usually offer fewer wild stylistic options. Use them for hero shots: a close-up on a face, a product rotating in studio light, an architectural reveal where texture detail sells the budget. Expect to wait, and expect to pay more per attempt.
Iteration-speed models
Faster, cheaper, lower fidelity. Their value is not the final frame — it is the storyboard. Use them to test camera moves, timing, and blocking before committing a hero model to the shot. A director who previews a motion with a fast model and then re-renders the approved take in a realism model will spend less total time and money than one who renders every idea at maximum quality.
Specialized models
Some systems are tuned for narrow jobs: talking-head performance, product turntables, environmental fly-throughs, or style transfer over existing footage. When your shot falls squarely into one of these categories, a specialized model often beats a generalist on consistency, because the problem space is constrained. The trade-off is flexibility — you cannot easily improvise outside the trained domain.
Open-weight and self-hosted options
If you have GPU capacity and engineering support, open-weight models give you control over versioning, data handling, and fine-tuning on a proprietary product or face. The hidden cost is maintenance: checkpoints change, dependencies break, and quality improvements in hosted services do not automatically reach you. Choose this route when data governance or a very specific look justifies the overhead.
A production workflow from brief to final cut
This is the sequence that holds up on real deadlines. It assumes you have access to several model classes and a timeline editor.
Step 1: Lock the intent and write a shot list
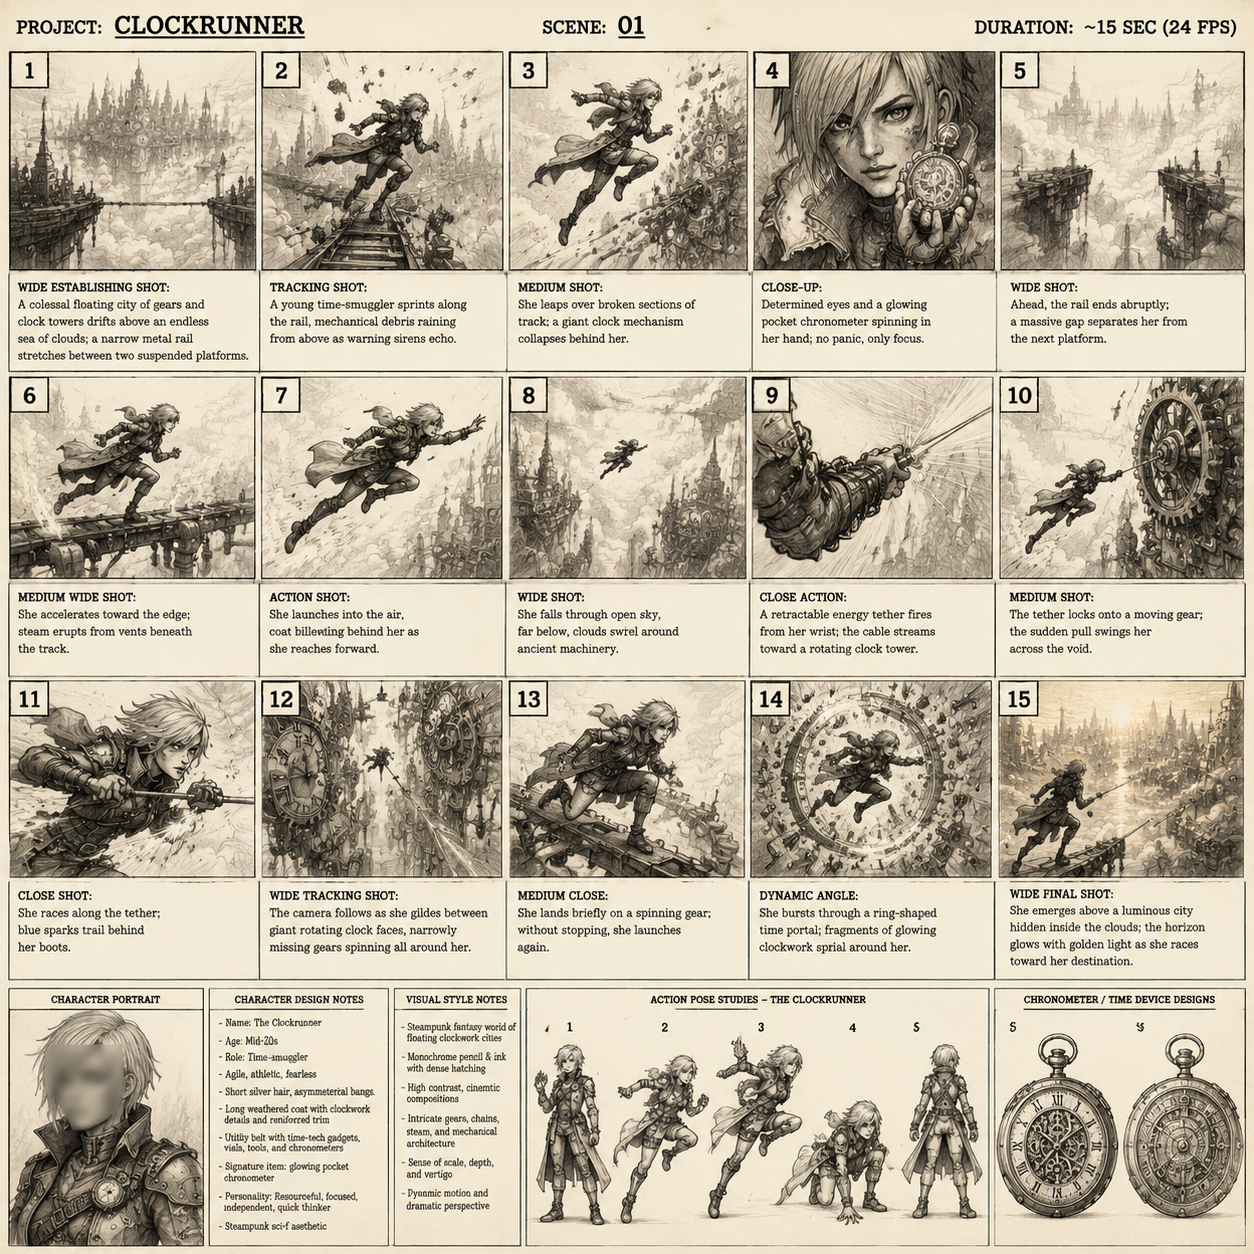
Before generating anything, write down what each shot must accomplish in the edit. "Establish location, four seconds, no dialogue" is a usable brief. "Cool cinematic vibes" is not. For each shot, note: duration, camera behavior, subject behavior, lighting conditions, and what it cuts to on either side. That last item matters more than people expect — a generated clip that has to cut on movement needs a different generation strategy than one that ends static.
Step 2: Build the reference package
Gather stills, footage, color references, and any technical passes you can produce. If you can output depth or pose data from a real clip, do it. Organize references per shot, not per project, because the needs differ. Name files so that a collaborator can regenerate the same shot without asking you questions.
Step 3: Generate short, verifiable clips
Start with three to five second tests at lower resolution if the tool supports it. Evaluate against a fixed checklist (see the QA section below) rather than vibes. Approve or reject fast. When something works, extend it rather than re-rolling from scratch — extending preserves the identity and lighting you already liked.
Step 4: Extend, stabilize, and upscale
Long shots are built, not generated. Extend approved segments, then fix the seams. Typical repairs: stabilize micro-jitter, match exposure frame to frame, retime speed slightly, and upscale to delivery resolution. Upscaling is not just resolution — a good upscaler reconstructs plausible grain and micro-texture, which is exactly what sells photorealism on a large screen.
Step 5: Grade, composite, and mix
Synthetic footage rarely arrives in your delivery color space. Grade it alongside real footage, not separately, so you can see mismatches immediately. Add contact shadows and light wrap where synthetic elements sit in real plates. Then treat sound as part of realism: room tone, footsteps, cloth movement, and a touch of camera audio noise do more for believability than another generation pass.
Prompting patterns that improve realism
Prompts are not spells; they are specifications. The most reliable pattern is a structured one.
Subject and material. Describe surfaces, not adjectives. "Brushed aluminum with fine vertical grain" beats "shiny metal." "Cotton jersey with visible loop texture" beats "nice fabric."
Light source and direction. Name the source and its position: "single soft key from camera left, warm practical lamp behind subject, no fill." Ambiguity here produces the flat, source-less lighting that instantly reads as synthetic.
Camera. Specify lens character and movement: "35mm, slight handheld float, no zoom." Mention what should not happen — "no camera rotation" — because negative constraints work reasonably well on motion.
Motion, one at a time. "Subject turns head slowly to the right" or "camera dollies forward at constant speed." Not both.
Format and finish. Reference the format you want: "shot on Super 16, visible grain, shallow depth of field, natural skin texture." Finish references help models avoid the overly smooth look that plagues synthetic faces.
Keep a personal library of prompts that worked, with the reference images that accompanied them. Over a few projects, that library becomes your real competitive advantage.
Quality control: the checklist that saves a project
Run every candidate clip through the same checks, in the same order. Consistency of evaluation catches problems that enthusiasm hides.
- Identity hold. Face, body proportions, and distinguishing features. Check at the start, middle, and end of the clip.
- Hands and feet. The classic failure zone. Look at finger count, knuckle bends, and foot contact with ground.
- Texture stability. Does fabric weave, hair, or foliage change character across the clip?
- Lighting continuity. Track a shadow across the clip. If the shadow direction shifts without a light source moving, reject.
- Background integrity. Text, signage, windows, and architecture. Blur them in post if needed, but know they are there.
- Motion physics. Weight, momentum, and reaction. Does the coat move when the body moves?
- Cut compatibility. Does the clip hold up when placed next to the shots it will actually sit between?
- Delivery survivability. Watch it on a phone, compressed, at half attention. Anything that only works on a large calibrated monitor is a risk.
Common mistakes that break photorealism
Over-smoothing. Chasing "clean" output removes the imperfections that signal reality. Keep grain, keep pores, keep slight lens falloff.
Asking for too much in one generation. Multiple characters, a complex camera move, dialogue, and a wardrobe change in one request guarantees mush. Decompose.
Ignoring the cut. A clip that looks great in isolation often fails in the timeline because its motion does not match the surrounding rhythm.
Skipping the reference step. Text descriptions cannot encode a specific face or product. References can.
No versioning. If you cannot return to the exact settings and inputs that produced an approved shot, you cannot make a small revision later. Log everything.
Treating generation as the whole job. Generation is maybe forty percent of the work. Stabilization, grading, compositing, and sound carry the rest.
Cost, time, and risk: decision criteria for teams
The right level of investment depends on how the clip will be used, and how visible its flaws will be.
Ask three questions about each shot. How large will it appear on screen? How long will it be on screen? Will the audience be primed to scrutinize it?
A two-second background plate in a social ad can survive a fast model with light cleanup. A five-second close-up of a founder's face in a broadcast spot needs the highest-fidelity option available, plus manual retouching. Meanwhile, an eight-second product turntable may be better solved with a specialized model than a generalist, because the dominant risk there is texture consistency, not human anatomy.
Build a simple tiering system: preview tier, standard tier, hero tier. Assign every shot to a tier before you generate, and stick to it unless the edit forces a change. This prevents the two most expensive habits in synthetic production — over-rendering shots nobody will look at, and under-rendering the one shot everyone will.
Building a repeatable pipeline
The teams that get consistent results treat synthetic video as a pipeline with named stages, not as a creative slot machine. That means: a shot list that maps to tiers, a shared reference library, standardized prompt templates, a fixed QA checklist, versioned outputs with readable naming, and a post-production step that always includes stabilization, grade matching, and sound design.
Document your own failure patterns too. If you notice that your model of choice consistently drifts on metal surfaces, write it down and compensate with shorter clips or additional reference passes. Over time, that internal documentation is more valuable than any individual generation.
Finally, keep a small real-footage safety net. Plates, textures, and cutaways shot on a phone can rescue a synthetic sequence when a deadline tightens. Photorealistic synthesis is strongest when it is used deliberately alongside captured material, not as a total replacement for it.
FAQ
How long can a single generated clip reliably be?
For professional use, four to eight seconds is the practical sweet spot for most models. Longer shots are best assembled from extended segments and then stabilized. If you need twenty continuous seconds, plan for stitching and expect a seam-fixing pass.
Do I need reference images, or is a good prompt enough?
A prompt is enough for generic scenes and abstract motion. The moment a specific person, product, or location matters, references become mandatory. Five well-lit stills from different angles will outperform any paragraph of description.
Why does my clip look sharp but still fake?
Usually lighting logic or motion physics. Synthetic frames often lack a definitive light source, and objects move without weight. Fixing direction of light, shadow behavior, and reaction to motion solves most of it. A subtle grain pass helps too.
Should I upscale AI video?
Yes, especially for large displays or broadcast delivery. Upscaling reconstructs micro-texture and grain that compression and generation smooth away. Just make sure it is done after you approve the motion, not before, so you do not waste the processing time.
How do I handle faces that drift over a clip?
Shorten the clip, add identity references, and prefer models with strong face consistency for close-ups. If drift persists, treat the face in post: a subtle composite of a real still over the synthetic face for a few frames can hold identity when needed.
Can synthetic footage cut against real footage without looking obvious?
Yes, if you match three things: grain structure, color response, and motion blur. Match those and most viewers will not distinguish. Skip them and the synthetic shots will stand out regardless of how detailed they are.
