
Why Text-to-Video and Image-to-Video Are Two Different Crafts
Text-to-video and image-to-video are often described as two settings of the same feature, but they solve fundamentally different problems. Text-to-video starts from nothing and asks the model to invent a world: subject, wardrobe, lighting, camera behavior, and pacing all come from your prompt. Image-to-video starts from a fixed frame and asks the model to animate what is already there, which means most of the creative decisions were made before generation began.
That difference has practical consequences. Text-to-video rewards descriptive writing and patience with iteration. Image-to-video rewards motion writing, restraint, and a strong understanding of what a single frame can and cannot support. If you mix the two mindsets — writing a novel in an image-to-video prompt, or feeding a text model a static reference it cannot interpret — you will spend hours fighting tools that are working correctly.
The most reliable approach is to treat them as two stages of one pipeline rather than competing options. Generate or source a keyframe first, then animate it. Use pure text-to-video for establishing shots, abstract transitions, and anything where no single frame needs to hold up under close inspection.
Choosing Your Starting Point: Text, Image, or Hybrid
Before opening any tool, decide what your shot actually needs. A short establishing shot of a city at dawn is a text-to-video job. A product close-up where the logo must remain legible is an image-to-video job. A dialogue scene with two characters in a fixed location is usually a hybrid: locked keyframes for each angle, animated individually, then cut together.
Three questions sort this quickly:
- Does the shot need visual accuracy? If a specific object, face, or brand element must look correct, start from an image. No text prompt reliably reproduces a real person or a specific product.
- Does the shot need motion complexity? If the camera must travel through a space, text-to-video models handle camera language more gracefully because they are designing the scene from scratch.
- Does the shot need to match neighbors? If yes, consistency matters more than any single frame's beauty, and locked keyframes give you a much tighter grip on continuity.
A useful rule of thumb: image-to-video for anything that will be on screen longer than three seconds, and text-to-video for anything that exists to bridge, transition, or set a mood.
The Cost of Getting This Wrong
Choosing text-to-video for a shot that needed a keyframe typically produces a usable first second followed by drift — faces shift, clothing mutates, backgrounds lose detail. Choosing image-to-video for a shot that needed free invention usually produces a beautiful but lifeless clip: a photograph that gently breathes instead of a scene that moves. Both mistakes are expensive because they are discovered late, after the generation and review cycle.
Building a Prompt Framework That Survives Model Swapping
Every video model interprets prompts differently, and version updates can change behavior overnight. The way to stay productive is to write prompts in a structured, portable format rather than in whatever phrasing a single tool happens to like.
A durable video prompt has five layers:
- Subject and action — who or what, doing exactly what, in one clause.
- Setting and time — location, weather, hour, atmosphere.
- Camera — shot size, angle, movement, lens feel.
- Light and color — key light direction, contrast, palette, grade.
- Motion and rhythm — speed, duration, what should change across the clip.
Keep each layer to a single phrase. "A baker pulls a tray from an oven, small kitchen before dawn, medium shot at chest height, slow push in, warm tungsten light from the left, steam catching the light, unhurried movement" gives any model enough to work with and gives you a consistent checklist when a clip fails.
Motion Prompts Are Not Longer Prompts
New users often assume more words mean more control. In practice, video models weight motion verbs and camera terms far more heavily than adjectives. Trimming decorative language and adding precise motion words — drift, settle, rotate, track, parallax — usually improves output more than any other single edit.
Image-to-Video: Controlling Motion Without Losing the Frame
The appeal of image-to-video is control. The risk is that the model drifts away from the frame you approved. Managing that balance is the core skill of this workflow.
Start with a keyframe that is technically clean: sharp, well-lit, with clear separation between subject and background. Soft or noisy references give the model ambiguous edges, and ambiguous edges move unpredictably. If your keyframe came from an image generator, upscale and lightly clean it before animating.
Then describe only the motion you want, not the scene. The model already sees the scene. Words like "slow push in," "hair moves gently in the wind," or "steam rises and disperses" are useful. Re-describing the subject's appearance or the room's lighting tends to confuse the model and can trigger unwanted changes.
Keep Motion Small
Most image-to-video artifacts come from asking for too much movement. Large gestures, full-body turns, and fast camera moves force the model to invent detail it cannot see. Small, believable motion — a head tilt, a hand adjusting a sleeve, fabric shifting — reads as more professional and survives compression better.
Anchor the First and Last Frame
Where the tool supports it, define both a start and end frame. Two anchors turn an open-ended animation into an interpolation problem, which dramatically reduces drift and gives you an editable handle at both ends of the clip.
Managing Shot Consistency Across a Sequence
Consistency is what separates a demo from a film. Audiences forgive imperfect textures but not changing faces, shifting costumes, or rooms that rearrange themselves between cuts.
Practical techniques that work across most tools:
- Lock a character reference sheet. Generate or photograph a front, three-quarter, and profile view. Reuse these as keyframes rather than regenerating a character from a text description each time.
- Fix your lighting language. Decide the key light direction and color temperature for a scene and copy that exact phrasing into every prompt.
- Control the lens vocabulary. If one shot is described as a 50mm look, keep a consistent set of focal-length phrases across the sequence.
- Work in short clips. Four to six second generations drift far less than ten second ones, and they cut together just as well.
- Keep a style block. A short, unchanged paragraph of palette, contrast, and texture language appended to every prompt in a project.
Editing Is Part of Consistency
No generation pipeline produces perfect continuity on its own. Color correction, frame-rate conforming, and a light film grain over the whole sequence hide small inconsistencies far better than any prompt trick. Plan for a grading pass from the beginning rather than treating it as a rescue operation.
A Practical Production Workflow, Step by Step
This is a workflow that scales from a single social clip to a short film without changing its core structure.
Step 1: Script into shots. Break the script into a numbered shot list with one sentence per shot describing action and intent. Do not write prompts yet — this is a directing pass, not a generating pass.
Step 2: Assign generation modes. Mark each shot as text-to-video, image-to-video, or hybrid. Note which shots need locked keyframes because of faces, products, or continuity.
Step 3: Produce keyframes. Generate or shoot every keyframe in the sequence before animating any of them. This reveals continuity problems while they are still cheap to fix.
Step 4: Animate in passes. Generate the three most important shots first and evaluate the style. Only after the look is settled should you produce the rest, reusing the same phrasing and references.
Step 5: Assemble a rough cut. Cut with temporary placeholders where a shot is missing. Rhythm problems are easier to spot in an edit than in a folder of clips.
Step 6: Reshoot selectively. Only regenerate shots that fail in context. A clip that looks weak in isolation often works fine at two seconds in a montage.
Step 7: Post-produce. Grade, stabilize, add sound design and music, and add transitions that mask the seams between generated clips.
Sound Is Not an Afterthought
Generated video usually arrives silent, and silent footage feels artificial regardless of quality. Ambient beds, foley, and music do more for perceived realism than another generation pass. Budget time for audio as a first-class stage rather than a final garnish.
Model Selection Criteria: Matching the Tool to the Shot
The AI video landscape is broad enough that the honest answer to "which model is best" is "for what shot?" Instead of chasing a single winner, evaluate candidates against the specific demands of your project.
Key criteria to compare:
| Criterion | Why it matters |
|---|---|
| Motion realism | Determines whether human movement reads as natural or uncanny |
| Image adherence | How closely image-to-video output holds the source frame |
| Duration per generation | Affects how many seams you need to hide in the edit |
| Aspect ratio support | Vertical delivery requires native vertical generation or careful reframing |
| Resolution and upscaling | Matters for large screens and for text overlays |
| Iteration speed | Fast drafts change how ambitious you can afford to be |
| Prompt sensitivity | Some models need dense prompts, others need terse ones |
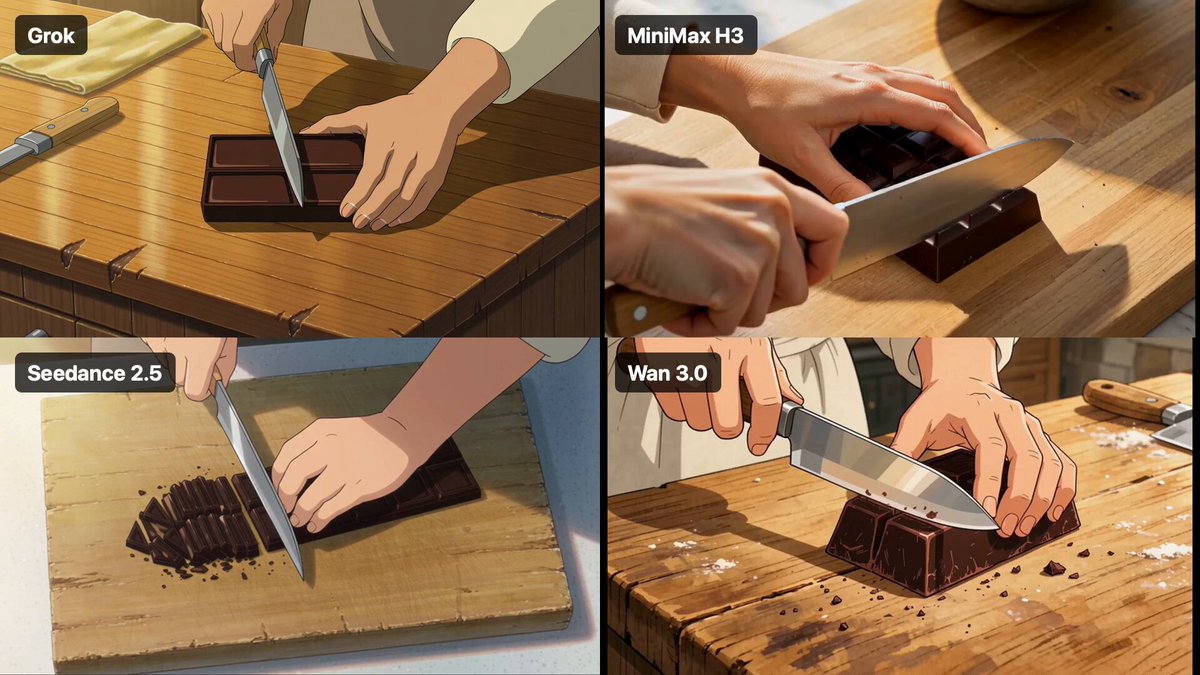
Different families of tools tend to specialize. Some excel at photoreal human motion and cinematic camera language, which suits narrative and advertising work. Others are tuned for stylized, animation-friendly output and handle exaggerated motion better than realism. A third group optimizes for speed and volume, which makes them ideal for social content where quantity and turnaround matter more than polish.
The practical strategy is to maintain two or three tools you know deeply rather than sampling dozens. Fluency with a model's quirks — where it drifts, what phrasing it respects — is worth more than access to another option you have not learned.
Common Mistakes and How to Avoid Them
Most disappointing AI video output traces back to a small set of repeatable errors.
Overloading prompts. Cramming three actions into one clip produces mush. One action per generation, edited together, always looks better.
Ignoring aspect ratio at the start. Generating widescreen and cropping to vertical destroys composition. Decide delivery format before you generate.
Treating the first output as final. Good clips come from the third or fourth attempt with a revised prompt, not the first.
Animating a weak keyframe. If the still image is not compelling, the video will not be either. Fix the frame first.
Skipping reference management. Without consistent character and location references, long sequences fall apart by the third shot.
Expecting long continuous takes. Current tools are strongest in short bursts. Build sequences from many short clips rather than one long one.
Neglecting licensing and disclosure. Check the terms for commercial use and follow any platform rules about labeling synthetic media. This protects you later.
Quality Control, Post-Production, and Delivery
A review checklist saves more time than any prompt improvement. Before a clip enters the edit, check for warping in hands and faces, flickering textures, inconsistent shadows, unstable backgrounds, and motion that does not match the intended pacing. Reject anything with a structural flaw; small artifacts can be graded around, but broken anatomy cannot.
Post-production is where generated footage starts to feel like real footage. Conform everything to a single frame rate, apply a consistent grade, add grain or a subtle halation, and stabilize handheld shots. Add a title and end card so the piece has a defined shape.
For delivery, export masters at your target resolution and keep the project files. Rerendering a shorter cut for a different platform is far cheaper than regenerating shots. Keep a log of the prompt and references used for every approved clip — when a client asks for a variation six weeks later, that log is the difference between an hour of work and a rebuild.
FAQ
Do I need both text-to-video and image-to-video?
Not necessarily, but almost every serious project ends up using both. Text-to-video is faster for exploration and establishing shots; image-to-video is more controllable for anything with continuity requirements.
How long should a single generated clip be?
Four to six seconds is the sweet spot for most tools. Longer generations drift more, and short clips give you more control in the edit.
Why do faces change between shots?
Because each generation invents detail independently. Use locked reference images, keep lighting language identical, and accept that a grading pass will still be needed.
Is generated video good enough for commercial work?
For many contexts, yes — especially backgrounds, product-adjacent inserts, social content, and stylized sequences. Check the terms of each tool for commercial rights, and be transparent with clients about how footage was produced.
What is the fastest way to improve output quality?
Shorten your prompts, reduce motion, and generate from a strong keyframe. Those three changes improve results more than switching tools.
How do I keep a whole sequence looking like one film?
Lock character and location references, reuse a fixed style block in every prompt, generate in short clips, and finish with a single consistent grade across the entire edit.
Should I learn many models or master one?
Master two or three. Deep familiarity with a model's drift patterns and prompt preferences consistently outperforms shallow access to a wider menu of options.
