
Why Text-to-Video Became a Practical Production Skill
A few years ago, "text to video" meant a five-second clip of a melting face and a caption explaining that the technology was promising. Today it means a storyboard you can generate before lunch, a set of shots that hold together across forty seconds, and a rough cut you can hand to a client the same afternoon.
The shift is not just about model quality. It is about workflow. The people getting reliable results are not typing longer prompts into a single box and hoping. They are running a pipeline: script breakdown, reference stills, short generations, careful review, then editing that treats generated footage like any other footage. That pipeline is the subject of this guide.
What follows is engine-agnostic. Whether you use Runway, Kling, Pika, Luma Dream Machine, Sora, Veo, or an open-source model running on your own hardware, the structure holds. Tools change quarterly; the pipeline changes slowly.
What Text-to-Video Actually Does (and What It Doesn't)
Understanding the limits of the technology saves more time than any prompt trick. A generative video model is not a director, an editor, or a continuity supervisor. It is a very fast, very literal renderer with no memory of your intentions.
The three layers of any generation
Every text-to-video output is the result of three interacting layers:
- The prompt layer. Your written description of subject, action, camera, lighting, and style. This is what you control most directly.
- The model layer. The trained network and its inherent biases toward certain looks, motions, and compositions. This is what you learn to work around.
- The conditioning layer. Any extra input you supply — a first frame, a last frame, a reference image, a motion path, a depth map. This is where professional results usually come from.
Beginners over-invest in the prompt layer and ignore conditioning. Professionals invert that ratio.
Where quality still breaks
Even strong models struggle with a predictable set of problems: hands interacting with small objects, text rendering inside the frame, characters who leave and re-enter, crowds, rapid camera moves combined with rapid subject motion, and long continuous takes. You can sometimes prompt your way around these issues, but the more reliable strategy is to design shots that avoid them. A cutaway to a close-up of a hand is easier to generate than a wide shot of that hand tying a knot.
Choosing the Right Engine for the Job
There is no best model, only a best model for a specific shot. Build a small mental map of your available engines and their personalities.
Realistic and cinematic work
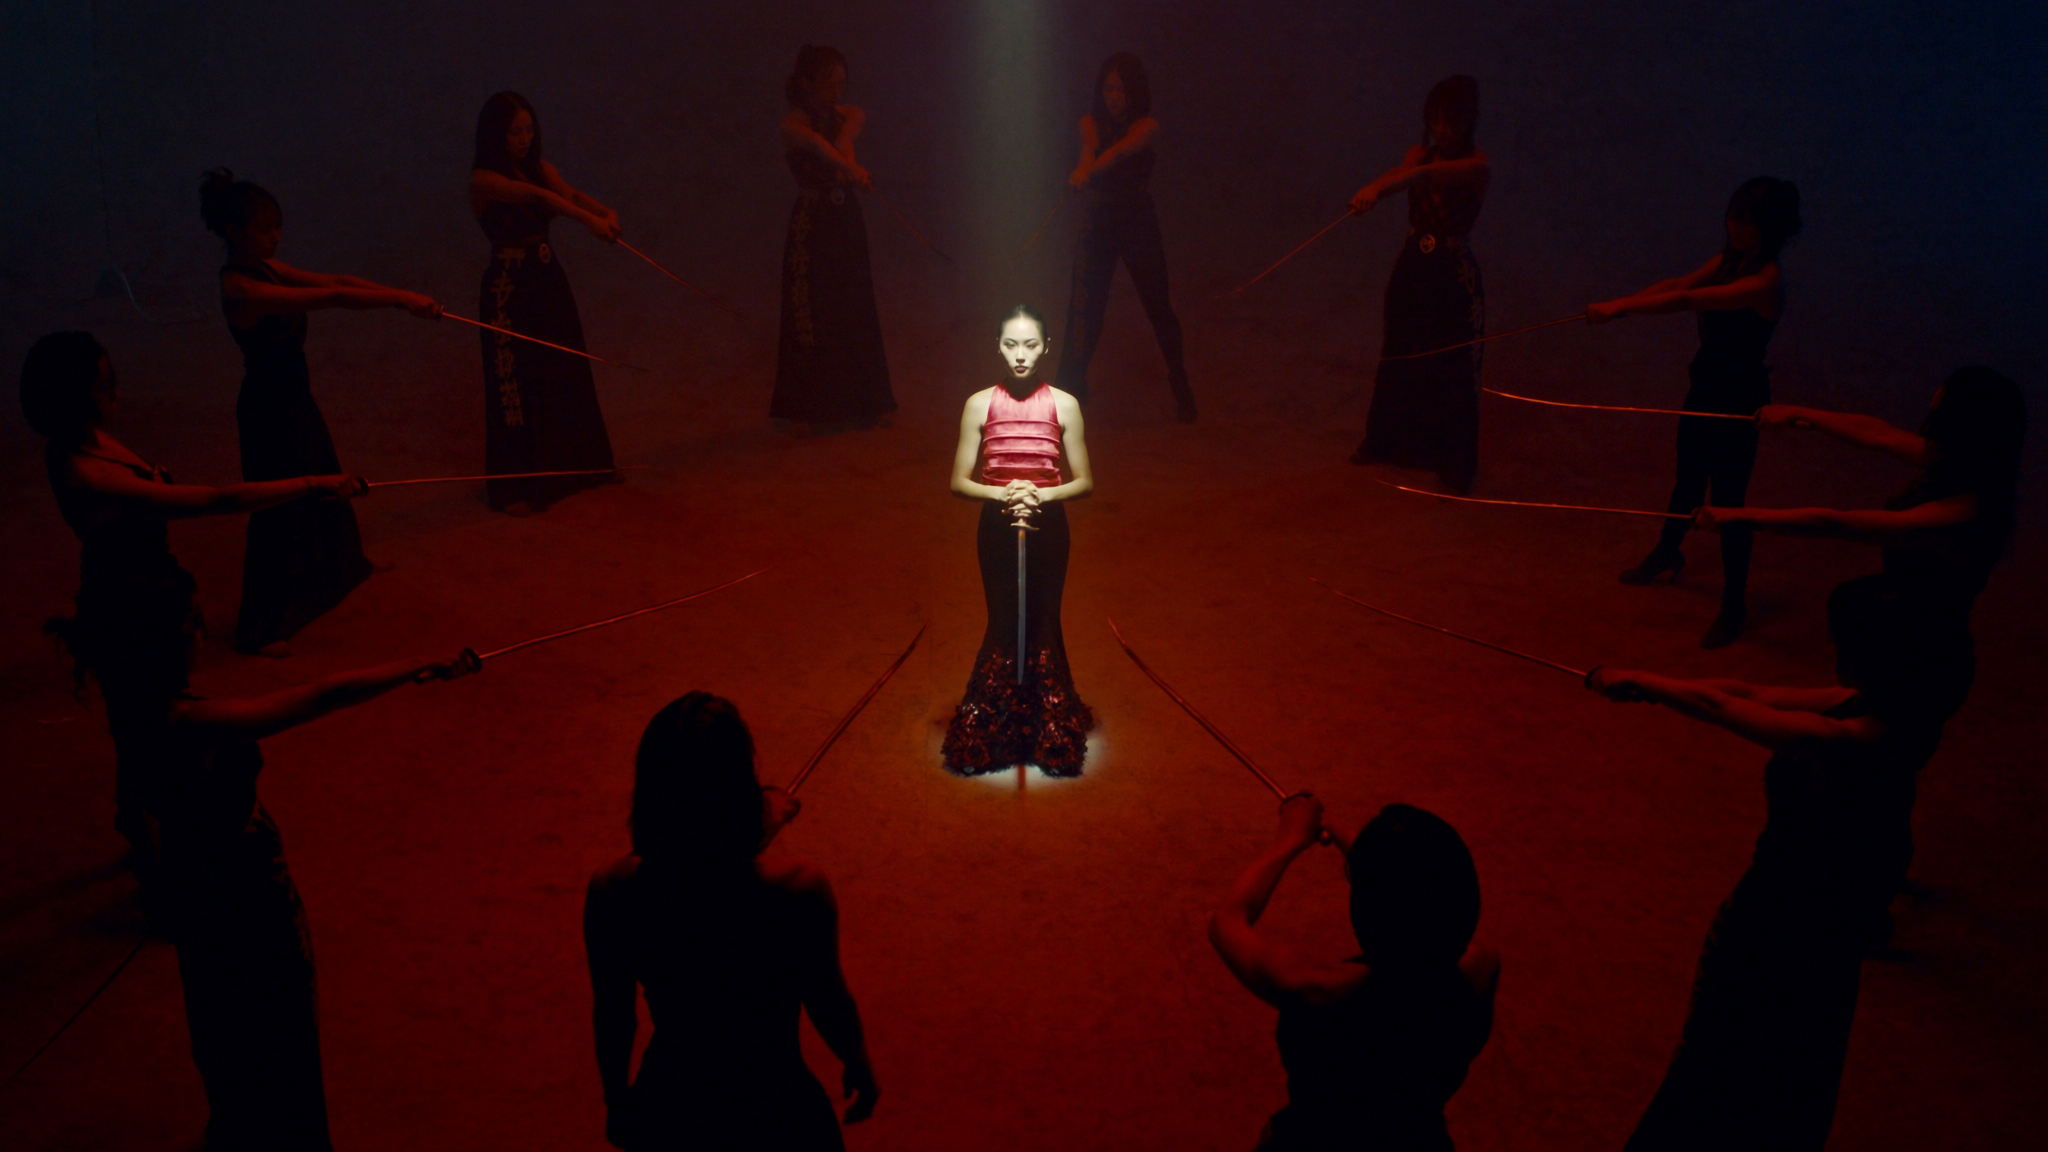
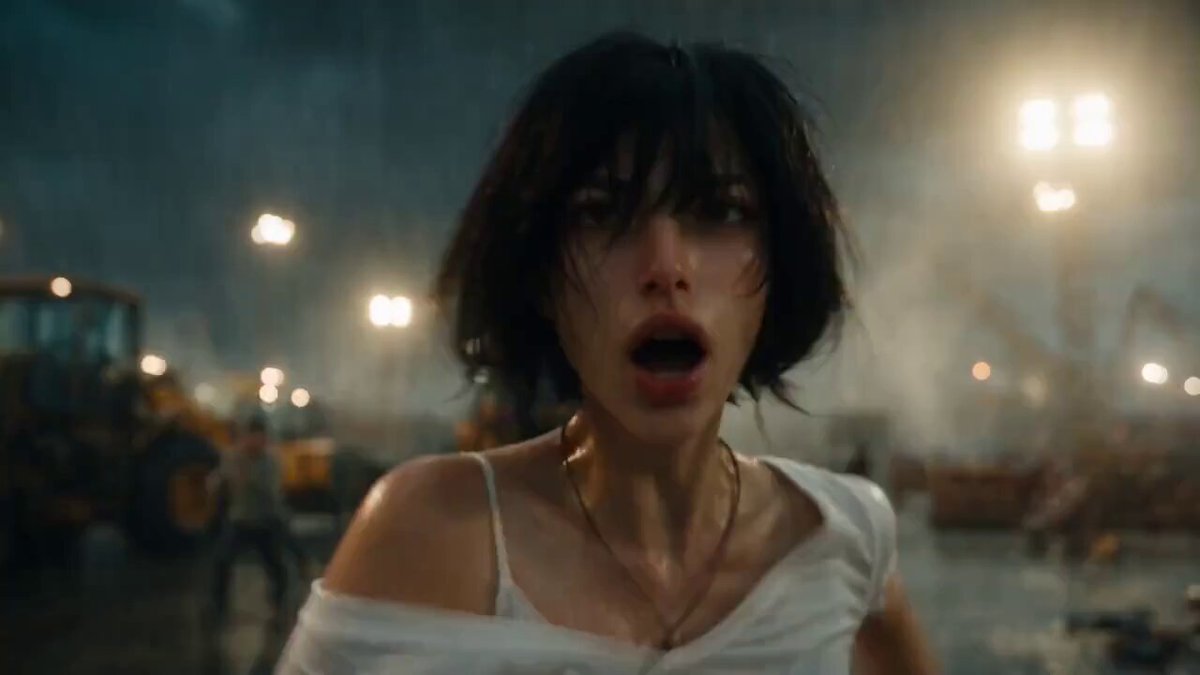
For natural skin tones, believable depth of field, and slow camera movement, the current generation of diffusion-based video models with strong temporal attention performs best. These engines reward detailed lighting language ("soft window light from camera left, cool ambient fill") and punish vague style words ("epic", "stunning").
Stylized, animated, and graphic work
Anime, 2D illustration, claymation, and motion-graphics looks often come out cleaner on models tuned toward stylization. The advantage is not just aesthetic: stylized output hides small anatomical errors that would be obvious in photoreal footage. If a shot keeps failing, changing the visual register can rescue it.
Image-first pipelines
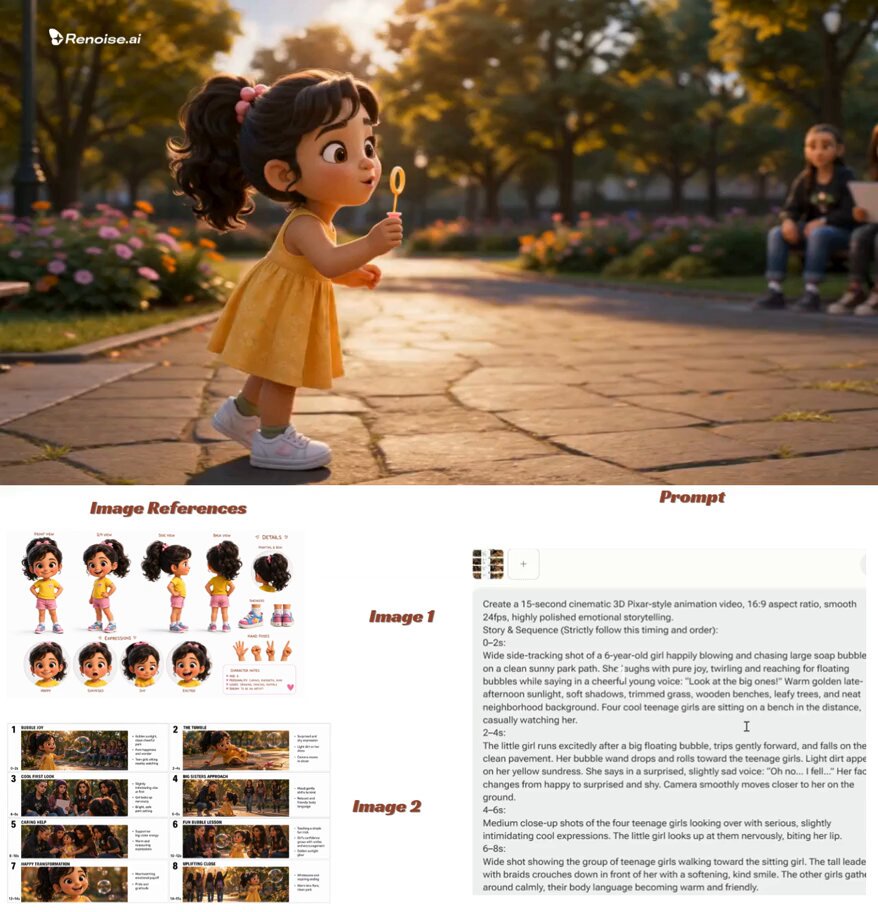
The most reliable path for most commercial work is image-to-video. Generate or photograph a still you are happy with, then animate it. You get exact control over composition, wardrobe, and lighting, and the model only has to solve motion. This single change converts a fifty-percent success rate into something closer to eighty or ninety percent for many shot types.
Practical selection criteria
When evaluating an engine for a project, score it on five axes:
- Motion coherence — does the subject stay intact over the full clip length?
- Prompt adherence — does it respect camera and lighting instructions?
- Duration and resolution — what is the longest usable take, and at what size?
- Conditioning support — first frame, last frame, reference images, motion brush?
- Iteration speed — how long until you see the next attempt?
Speed matters more than people expect. An engine that produces slightly worse output in twenty seconds often beats a better engine that takes six minutes, because you can explore ten variations instead of two.
Designing Prompts That Survive Generation
A prompt is not a description of a video. It is a compressed instruction set for a renderer that will happily invent anything you leave ambiguous.
The five-slot template
Write every prompt in five ordered slots. This prevents the most common failure mode, which is spending your entire prompt on the subject and forgetting the camera.
- Subject: who or what, with two or three defining visual details.
- Action: one clear verb phrase. One.
- Environment: location, time of day, weather, background activity.
- Camera: framing, angle, movement, lens feel.
- Light and grade: source, direction, contrast, color treatment.
A filled example: A woman in her sixties with short grey hair and a canvas apron, slowly pouring tea into a ceramic cup, in a small bakery kitchen at dawn, medium close-up at eye level with a slow push in, warm window light from the right with soft shadows and muted film grade.
Camera vocabulary that models understand
Vague camera language produces vague camera work. Use terms that appear constantly in real production and in training data: dolly in, dolly out, truck left, crane up, handheld follow, static tripod, over-the-shoulder, low angle, Dutch tilt, rack focus, shallow depth of field, wide establishing shot, macro detail.
Avoid combining more than one movement per shot unless you specifically want the model to blend them badly. "Slow push in while orbiting slightly" is usually a recipe for a warped face.
Writing negative constraints
Many engines accept a negative field. Even those that don't respond well to explicit negatives while ignoring them, so it is worth being specific in the positive prompt about what should stay constant: "her jacket remains dark green throughout," "background stays out of focus," "no other people enter the frame." Stating continuity as a positive instruction is more effective than listing what you don't want.
Building Visual Consistency Across Shots
Consistency is the single hardest problem in AI video, and the one most likely to sink a project. A character who changes face between shots destroys the illusion faster than any rendering artifact.
Character sheets and reference frames
Before generating any motion, build a small reference library. Generate or capture five to eight stills of each main character from different angles and in different lighting: front, three-quarter, profile, close-up, full body. Keep the same wardrobe. This library becomes your anchor for every subsequent shot.
Do the same for locations. Two or three wide references of each set make it far easier to place characters inside them convincingly.
Multi-reference and image-conditioning techniques
If your engine supports multiple reference images, use them with discipline. Feed a face reference plus a wardrobe reference plus a lighting reference, and describe how they combine. If your engine supports only a single first frame, build that frame in an image editor by compositing the elements yourself, then animate the composite. This is slower per shot and dramatically faster per finished project.
Some workflows add a last-frame reference as well, which lets you write the shot in reverse and gives you editorial control over where the action lands.
A continuity checklist
Run this list against every generated clip before you accept it:
- Does the face match the character sheet?
- Is the wardrobe identical, including color and any visible logo or pattern?
- Is the light direction consistent with the previous shot in the scene?
- Does the background geometry stay stable when the camera moves?
- Does the action complete, or does it cut off mid-motion?
- Does the clip's color temperature match its neighbors?
The last two items are the ones people forget, and they are the ones that make a sequence feel edited rather than assembled.
A Step-by-Step Workflow From Script to Final Cut
This is the pipeline I would hand to a small team starting a new project. It scales from a single creator to a five-person crew.
Step 1: Break the script into shots, not scenes
A scene is a unit of story. A shot is a unit of generation. Convert every scene into a numbered shot list with a duration estimate and one sentence of action. If a shot requires more than one action, split it. Generated clips rarely handle two beats cleanly.
Aim for an average of three to five seconds per shot. It feels short on paper and correct on screen.
Step 2: Generate stills first, and approve them
Produce a still for every shot in the list before generating a single second of video. Review the stills as a contact sheet. This is where you catch a costume mismatch, a wrong location, or a weak composition for a fraction of the cost of fixing it in motion.
Approval at the still stage is the highest-leverage review in the entire pipeline.
Step 3: Animate with image-to-video passes
Feed each approved still as the first frame with a short motion prompt describing only what should move. Camera language belongs here; subject description mostly does not, because the still already defines the subject.
Generate three to five variations per shot at the lowest acceptable resolution, pick the best, then re-render that variation at full quality. Treating low-resolution passes as a scouting step is the difference between a comfortable afternoon and a frantic one.
Step 4: Upscale, interpolate, and stabilize
Generated clips frequently look soft and slightly stuttery. A standard cleanup chain handles both:
- Frame interpolation to double or quadruple the frame rate for smoother motion.
- Upscaling to your delivery resolution, preferably with a model trained on video rather than stills.
- Stabilization for handheld-style shots that drift more than intended.
- Deflicker if exposure pulses between frames.
Do the cleanup after you have locked the edit structure. Cleaning up shots you delete is wasted time.
Step 5: Edit, then sound-design
Cut in your editor of choice with the generated clips on the timeline as though they came from a camera. Apply a consistent grade across the sequence, since different engines and even different seeds within one engine produce different color science. A single adjustment layer with matched contrast and saturation curves unifies them quickly.
Sound is where AI video stops looking like AI video. Add room tone under every scene, foley for visible actions, and music that changes with the edit rhythm. A clip that feels artificial on mute often feels convincing with a door click and a breath in it.
Step 6: Prepare deliverables per platform
Render a master at your highest quality, then derive versions. Vertical crops need recomposition, not just cropping — check that faces stay inside the safe area. Add burned-in captions for social versions and keep a clean master without them. Keep the master's audio stems separate in case a client wants music swapped later.
Post-Production Tools Worth Knowing
You do not need a large stack, but a few categories of tool pay for themselves immediately.
- Non-linear editors such as DaVinci Resolve, Premiere Pro, or Final Cut for assembly and grading. Resolve's free tier covers most of what this workflow needs.
- Interpolation and upscaling utilities for frame-rate and resolution work.
- Compositing tools for building reference frames and cleaning small artifacts. Even basic layer-based editing gets you most of the way.
- Audio tools for noise reduction, loudness normalization, and stem separation.
- Asset managers so that reference stills, prompts, and versions stay linked to the shot they belong to.
That last one is unglamorous and decisive. Once a project passes thirty shots, the ability to find "the approved version of shot 14" in five seconds determines whether you can revise anything at all.
Common Mistakes and How to Fix Them
Mistake: prompting a whole scene in one generation. Fix by cutting the scene into individual shots and generating them separately.
Mistake: ignoring aspect ratio until the end. Fix by choosing the delivery ratio before generating stills. Vertical-first projects should be boarded vertically.
Mistake: chasing a perfect single take. Fix by accepting two good shots instead of one impossible one, and covering the moment with a cut.
Mistake: letting the model decide motion. Fix by specifying camera movement explicitly and keeping subject movement simple.
Mistake: treating the first acceptable take as final. Fix by generating variations consistently. The fifth attempt is often visibly better than the first, and the cost of checking is small.
Mistake: no color pass at the end. Fix by grading the sequence as a whole. Consistency in color does more for perceived quality than consistency in resolution.
Mistake: text inside the frame. Fix by adding text in post. Models render lettering unreliably, and a misspelled sign pulls attention from everything else.
Time, Hardware, and Cost Decisions
Before committing to a pipeline, answer three questions honestly.
How many finished minutes do you need per week? A solo creator producing one polished minute per week is comfortably served by hosted engines and a laptop. A team producing ten minutes per week needs an asset manager, a review process, and probably a dedicated editor.
Is your footage sensitive? If it involves unreleased products, personal data, or client confidentiality, prefer engines that let you run locally or that contractually exclude training on your inputs. For everything else, hosted tools are usually faster and cheaper than maintaining a GPU.
Where is your bottleneck? Generation time, review time, and editing time are three different constraints with three different solutions. Track them for a week before buying anything. Most people discover their bottleneck is review, not rendering, and fix it with a checklist rather than hardware.
On local hardware, a modern consumer GPU with 12 to 16 GB of memory can run smaller video models comfortably, but expect to trade speed and quality for privacy and unlimited iteration. Many creators run a hybrid: hosted engines for hero shots, local models for exploration.
Frequently Asked Questions
How long should a generated clip be?
Three to five seconds is the sweet spot for most models. Quality tends to degrade as clips get longer, and short clips give you more editorial flexibility anyway.
Do I need to learn prompt engineering as a separate skill?
Not as a separate discipline, but you do need a consistent prompt template and a vocabulary of camera and lighting terms. Two hours spent learning real cinematography vocabulary improves output more than two weeks of prompt tweaking.
Why does my character's face change between shots?
Because the model has no persistent memory of your character. Fix it with reference frames, a first-frame conditioning pipeline, and a character sheet you check every clip against.
Is image-to-video always better than text-to-video?
For controlled, continuity-dependent work, almost always. Text-to-video remains useful for abstract backgrounds, texture plates, mood exploration, and any shot where exact composition does not matter.
How much editing does generated footage need?
More than people expect. Plan on interpolation, upscaling, a color pass, and sound design for anything client-facing. Skipping those steps is the fastest way to make finished work look like a demo.
Can I mix engines in one project?
Yes, and you probably should. Different engines handle different shot types better. Match them at the grade and the project will read as one piece.
What about audio generation?
Generate music and effects separately, then assemble in your editor. Trying to generate a finished mix in a single pass rarely gives you the control you need for a polished result.
How do I keep projects organized at scale?
Name every asset with a shot number prefix, keep prompts in a text file next to the renders, and store approved stills in a single folder per character and location. Simple conventions beat sophisticated systems that nobody follows.
