
Why prompt craft is the new cinematography skill
AI video tools have crossed the line from curious demo to usable production instrument. The bottleneck is no longer whether a model can render motion, light, and texture. The bottleneck is whether the person writing the prompt can describe a shot the way a director describes it to a crew. That translation skill — cinematic prompt engineering — is the difference between a clip that looks generated and a clip that looks directed.
The shift matters because directors now work on two layers at once. The first is the traditional layer: framing, blocking, pacing, tone, continuity. The second is the linguistic layer: the exact order, emphasis, and vocabulary fed into a generative model. A vague prompt such as "cinematic shot of a woman walking" hands control to the model. A directed prompt names the movement, the lens, the light source, the surface texture, and the emotional register, and the model follows.
Treat prompts as part of your shot list, not as a magic phrase. Every shot in a sequence deserves its own written description, with variables you can change one at a time. When something goes wrong, you should be able to point at a single word in the prompt and understand why the image changed. That is the discipline this guide builds: a repeatable, directable vocabulary for AI cinematography.
Decoding camera language into text
Camera language is the fastest way to make AI footage feel intentional. Models respond well to established film grammar because that grammar appears constantly in their training data. The trick is being specific without being contradictory.
Movement verbs that actually register
Movement is where most prompts fail. Writers stack three movements into one sentence and the model averages them into a drifting, weightless camera. Pick one primary movement per shot:
- Push in and pull out for emotional emphasis.
- Dolly for lateral spatial reveals that keep perspective stable.
- Truck and track when the camera moves parallel to a subject in motion.
- Crane up and crane down for scale and geography.
- Orbit or arc for product hero shots and character reveals.
- Handheld with micro-shake for documentary realism.
- Whip pan for transitions and comedic energy.
- Rack focus when you want attention to shift inside the frame rather than through the frame.
Speed and motivation matter as much as direction. "Slow push in, motivated by the character's realization" reads differently than "fast zoom." Add whether the move is stabilized, gimbal-smooth, or deliberately shaky. If you want a locked-off shot, say static camera, locked tripod — otherwise models tend to invent motion to fill the timeline.
Lens, format, and depth cues
Focal length is a creative decision, not a technical footnote. A 24mm wide exaggerates space and puts the environment in the story. An 85mm portrait lens compresses background and isolates faces. A macro lens turns texture into subject matter. Mention aperture behavior when depth matters: shallow depth of field, f/1.8, creamy background falloff versus deep focus, f/11, everything sharp.
Format language also steers the look. Anamorphic brings oval bokeh, horizontal flares, and a widescreen feel. 16mm grain signals intimacy and imperfection. Super 35 reads as modern narrative. IMAX-scale wide suggests grandeur. Add a color and texture reference — Kodak-inspired warm highlights, slight halation — but keep it to one or two references so the model does not negotiate between competing looks.
Lighting schemes and environmental atmosphere
Lighting is the strongest single lever you have. Describe the source, the direction, the quality, and the color temperature:
- Source: practical lamp, window, firelight, neon sign, overcast sky, bounced sunlight.
- Direction: backlit, side-lit, top-down, underlit, three-quarter key.
- Quality: hard shadows, soft wraparound light, diffused, specular highlights.
- Color: tungsten warmth, cool moonlight, sodium-vapor orange, teal shadows.
- Atmosphere: volumetric haze, drifting dust, rain streaks, steam, smoke density.
Combine them into a single coherent sentence: "Backlit by a single tungsten practical, soft haze, warm highlights bleeding into cool shadows, faces half in darkness." That sentence tells a colorist and a gaffer exactly what to do — and a video model reads it the same way.
Prompt architecture for precision control
Once vocabulary is solid, structure determines reliability. A prompt is not a sentence; it is a stack of decisions ordered by priority.
Hierarchical stacking
Write in layers, most important first, because early tokens carry more weight in most generation pipelines:
- Subject and wardrobe — who or what, with identifying detail.
- Action and emotion — what happens, and how it feels.
- Shot size and framing — wide, medium, close-up, over-the-shoulder.
- Camera movement — one primary move, one modifier.
- Lens and depth — focal length, aperture behavior.
- Lighting and atmosphere — source, quality, color.
- Style and grade — film stock, palette, contrast.
- Technical constraints — aspect ratio, frame rate feel, motion blur.
Keep each layer short. A 120-word prompt that reads like a paragraph of prose usually beats a 400-word prompt that repeats itself. Repetition does not add emphasis; it adds noise.
Negative prompting for artifact reduction
Negative prompts are your cleanup crew. Typical entries: no text overlays, no watermark, no logo, no extra fingers, no warped faces, no flickering, no jitter, no sudden cuts, no morphing limbs, no duplicated subjects, no cartoon rendering. Add context-specific negatives per shot — for a dialogue close-up, no distorted teeth, no melting eyes; for a city wide, no floating buildings, no inconsistent windows.
Keep the negative list focused. Twenty negatives dilute each other, and some models begin treating them as positive descriptions. Start with five, add one only when you see the same artifact twice.
Weighting and token emphasis
Many interfaces let you emphasize tokens, either with numeric weights or syntactic cues. Use weighting surgically. If the camera move is wrong, boost the movement phrase rather than re-describing the whole scene. If the wardrobe keeps drifting, weight the garment and its color instead of adding adjectives elsewhere. Changing one weighted token per iteration is how you learn what a model actually listens to.
Keeping characters and props consistent across shots
Continuity is where amateur AI sequences fall apart. Faces change between cuts, jackets change color, a prop vanishes. The fix is a character sheet approach borrowed from animation production.
Write a locked description block for each recurring element and reuse it verbatim in every prompt:
- Character block: age range, hair length and color, eye color, skin tone, distinguishing feature, wardrobe with fabric and color, accessories.
- Prop block: object shape, material, wear marks, color, size relative to the hand.
- Environment block: architecture style, wall color, floor material, light sources, weather.
Then use every consistency tool the platform offers: reference images, image-to-video from a locked keyframe, seed control, character reference features, and consistent aspect ratio. Where a model supports a first-frame reference, generate a hero keyframe of the character once and animate from it for every shot in the scene. That single habit eliminates most drift.
A shot-by-shot workflow for AI sequences
Directing a sequence is a pipeline problem. Here is a workflow that scales from a 15-second social cut to a multi-scene narrative.
Step 1 — Beat the script. Break the scene into shots on paper. One idea per shot. If a shot needs two ideas, split it.
Step 2 — Define the visual grammar. Choose three to five rules and obey them: color palette, lens family, movement style, grade. A lookbook of still references keeps everyone aligned.
Step 3 — Write shot templates. Create a reusable prompt skeleton with slots for subject, action, movement, lens, light, and style. Fill it per shot instead of writing from scratch.
Step 4 — Generate keyframes first. Still images are cheap and fast. Lock composition, wardrobe, and lighting as images before spending time on motion. Fix the frame before you fix the movement.
Step 5 — Animate selectively. Use image-to-video for controlled shots and text-to-video for inserts, landscapes, and transitions. Match duration to the edit, not to the model's maximum.
Step 6 — Assemble and grade. Cut the shots together, then unify color, grain, and contrast in post. A shared grade makes separately generated clips feel like one film.
Step 7 — Sound design. Ambience, footsteps, and room tone hide small motion imperfections better than any re-render will.
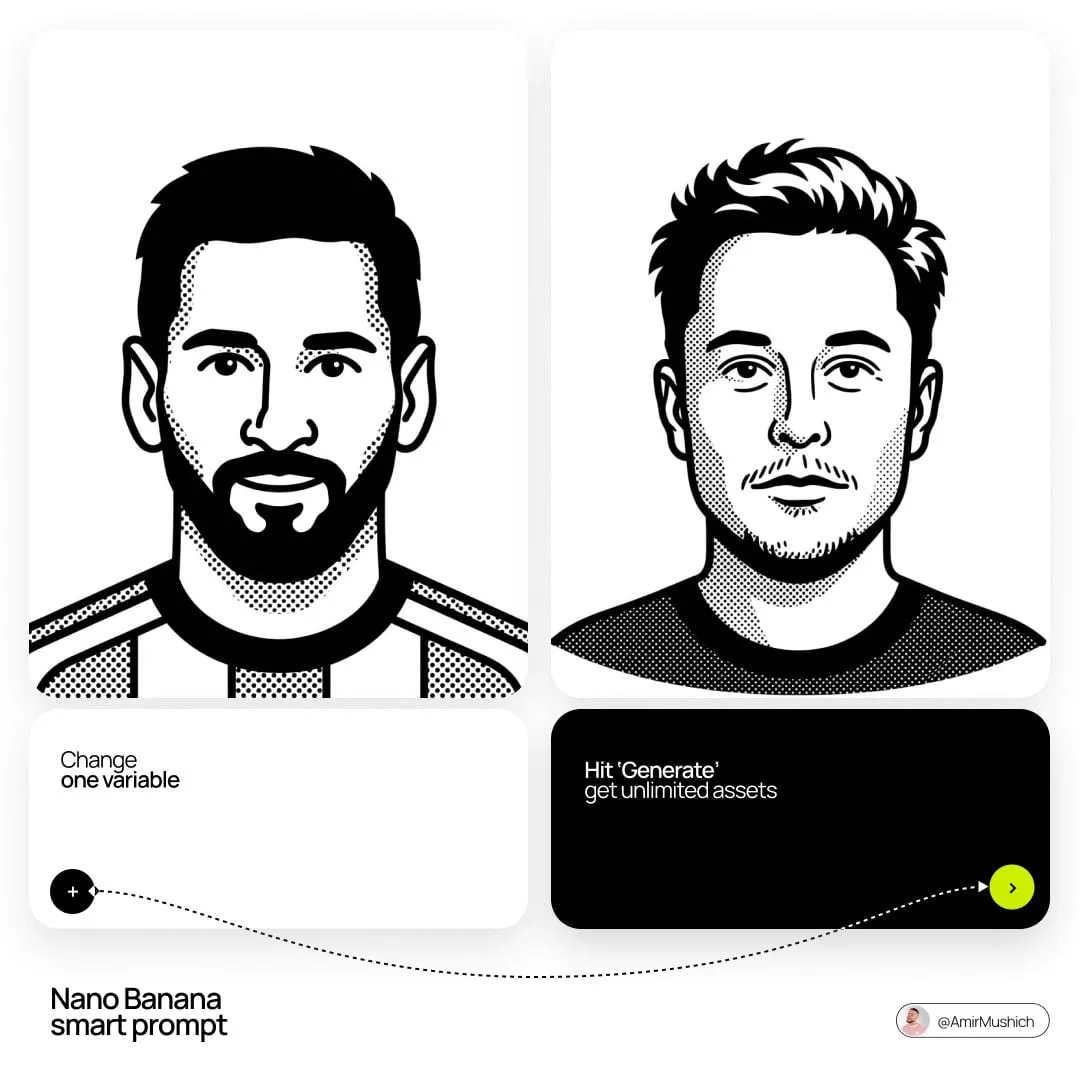
The iteration loop: change one variable at a time
Speed comes from disciplined iteration, not from generating hundreds of clips. Keep a prompt log with columns for shot number, prompt version, seed, model, and the single variable you changed. When a shot works, you can reproduce it. When it fails, you know what caused it.
Run A/B tests with two variables at most. If you change the lens and the lighting simultaneously, you learn nothing. Also learn when to stop: if a shot has survived five iterations without improving, the prompt is not the problem — the concept is. Redesign the shot instead of re-rolling.
Save winners as reusable recipes. A "night interior, tungsten practical, slow push in, 50mm" recipe can serve an entire series, and consistency across episodes is what makes AI-made content feel like a show rather than a demo reel.
Common mistakes and how to fix them
- Stacking movements. Three camera moves average into a floating camera. Fix: one primary move per shot.
- Adjective soup. "Epic, stunning, beautiful, hyper-realistic" adds no information. Fix: replace every adjective with a concrete noun or measurement.
- Ignoring shot size. Models default to medium shots. Fix: state framing explicitly in every prompt.
- Mixing incompatible looks. Neon noir plus sunlit pastoral confuses the grade. Fix: one lighting logic per scene.
- Re-describing the character each time. Drift creeps in. Fix: copy the locked character block verbatim.
- Overloading negatives. Too many prohibitions dilute each other. Fix: five focused negatives, add only after repeat offenses.
- Skipping keyframes. Motion hides bad composition. Fix: approve the still first.
- No grade pass. Ungraded clips look like a montage of unrelated sources. Fix: shared LUT, grain, and contrast.
Choosing tools and building a pipeline
Model choice should follow shot requirements, not hype. Evaluate candidates against concrete criteria:
- Motion coherence: how well limbs, fabric, and liquids hold together across a shot.
- Control depth: reference images, first and last frame control, camera-motion parameters, seed locking.
- Duration and pacing: whether it gives you the exact seconds your edit needs.
- Resolution and detail retention: what survives an upscale and a grade.
- Consistency features: character references, style locking, and reusable presets.
- Cost predictability: flat subscriptions are easier to budget than metered generation.
- Licensing and commercial use: confirm rights before client delivery.
- Audio and post-friendliness: clean exports, frame rates, and codecs that cut well.
Most professional pipelines mix two or three tools: one for hero character shots, one for environments and inserts, and a traditional editor and color suite for finishing. The prompt vocabulary you build transfers across all of them, which is why investing in language beats investing in a single platform.
FAQ
How long should a cinematic prompt be?
Most effective prompts land between 40 and 120 words. Long enough to specify subject, action, camera, lens, light, and style; short enough that no layer competes with another. If you cannot remove a word without losing information, the prompt is already lean.
Do I need to know real cinematography terms?
They help enormously because they are precise. "Dolly in" says more than "move closer." You do not need a film school background, but a basic vocabulary of shot sizes, movement types, and lighting directions will improve results immediately.
Why does my character change between shots?
Because each generation starts fresh unless you give it anchors. Use a locked character description block, reference images or keyframes, and consistent seeds. Avoid paraphrasing descriptions between shots — variation in wording creates variation in faces.
Should I use text-to-video or image-to-video?
Use image-to-video whenever composition and wardrobe must match an approved frame. Use text-to-video for environments, inserts, abstract transitions, and fast exploration. A hybrid approach is the most efficient production strategy.
How many variations should I generate per shot?
Generate three to five candidates with a controlled variable, pick the best, then refine that one. Endless re-rolling without changing the prompt produces the same failure in different costumes.
Is AI cinematography a replacement for a crew?
It is a new production layer. Directors still make every creative decision — framing, pacing, performance, tone — and post-production still decides whether the sequence works. The prompt is simply another instrument, and like any instrument it rewards practice.
Final take
AI cinematography rewards directors who think in specifics. Build a vocabulary of movement, lens, and light; structure prompts in layers; lock continuity with reusable description blocks; and iterate one variable at a time. Do that consistently and the model stops feeling like a slot machine and starts feeling like a crew that takes direction.
