
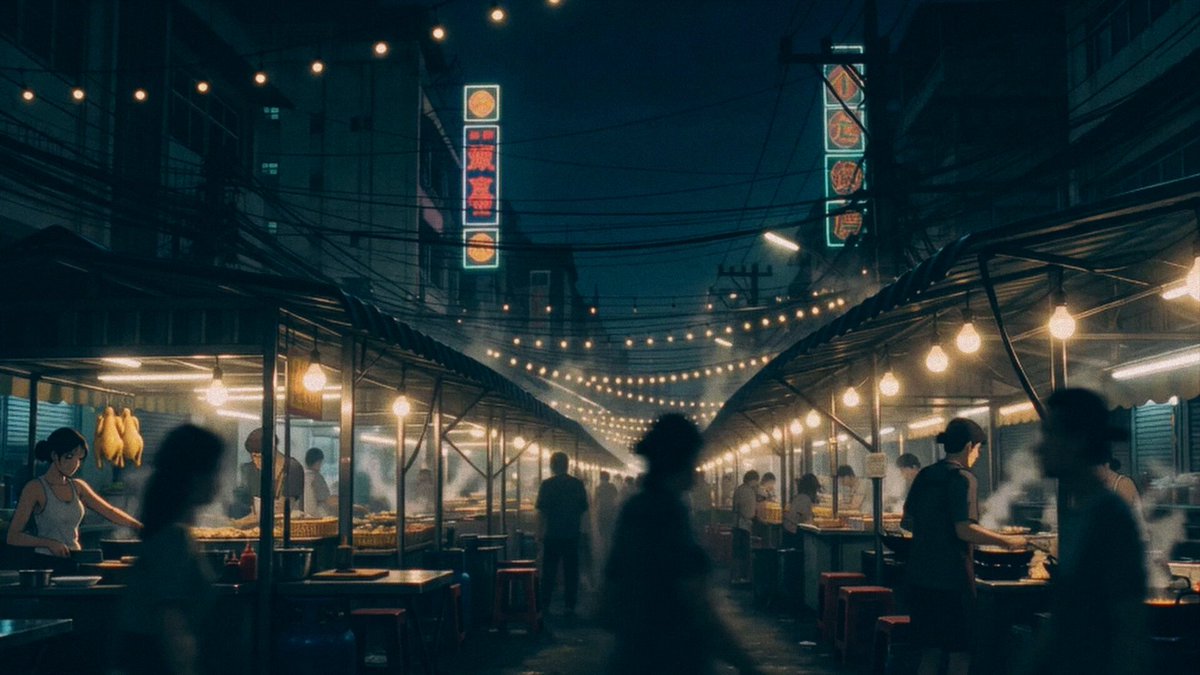
Why AI Cinematography Is a Directing Skill, Not a Prompt Trick
Generative video has made one thing dramatically cheaper: rendering a shot. It has not made the harder thing any cheaper at all — deciding which shot to render, why it exists in the sequence, and what the audience should feel when it lands. That gap is where most AI video projects fail. People spend an afternoon generating twenty clips that look technically impressive and cut together into something with no point of view.
A cinematographer's job has never been "operate the camera." It is to translate a story beat into visual decisions: where the frame sits, how much of the world it includes, how the camera moves, what the light is doing, and how long the audience is forced to sit with the result. When you work with generative video, every one of those decisions has to be expressed in language and reference images, because there is no crew standing next to you to interpret a nod toward the window.
The practical mental model that fixes most problems: treat the model as an extremely fast camera crew with no taste and no memory. It will execute a described shot competently. It will not know that the shot is wrong for the scene, that the lighting should have stayed consistent from the previous cut, or that the wardrobe changed between takes. You are the taste and the memory. Everything in this guide is about supplying those two things systematically instead of hoping the model guesses right.
The Four Decisions Behind Every Cinematic Shot
Before touching a prompt box, separate the choices you are making. Almost every usable AI shot is the product of four independent decisions, and confusing them is why prompts become bloated, contradictory walls of text.
Shot size and framing
Shot size is the single most communicative decision available to you. An extreme wide shot establishes geography and makes a character feel small against the world. A wide shot shows a body in a space. A medium shot is conversation language. A close-up is emotional pressure. An extreme close-up is obsession or detail.
The discipline that matters here is the one-idea-per-shot rule. If a shot is meant to show that a character is isolated, the frame should make that argument and stop. Adding a second idea — a phone buzzing, a dog running past, a flare in the corner — dilutes the first. In AI video this has a technical dimension too: the more elements you pack into a frame, the more likely the model will drift, morph, or lose one of them mid-clip.
Also decide aspect ratio and headroom early. Vertical framing for social feeds is not just a crop of horizontal footage; it changes what shot sizes are readable. A wide shot in a 9:16 frame is mostly environment, so close-ups and mediums carry far more of the storytelling load.
Lens language and depth of field
Lens choice is a mood tool, and generative models respond to it surprisingly well when you describe it in plain physical terms. A wide lens exaggerates distance, bends verticals, and makes spaces feel bigger and slightly unstable. A long lens compresses depth, stacks subjects against backgrounds, and flatters faces. Shallow depth of field isolates a subject from a busy background; deep focus puts everything in play and is essential for group scenes and environmental storytelling.
Useful phrasing: "24mm wide lens, slight barrel distortion," "85mm portrait lens, shallow depth of field, background softly blurred," "telephoto compression with the crowd stacked behind the subject." Vague words like "cinematic" or "professional lens" carry almost no information. Name the focal length, name the aperture behavior, name what is sharp and what is not.
Camera movement vocabulary
Movement is where AI shots most often betray themselves. Models handle slow, physically plausible moves extremely well and fast or compound moves poorly. Learn the basic vocabulary and use one move per shot:
- Static / locked off — the frame does not move. Underrated. Ideal for dialogue and for letting performance carry the beat.
- Pan and tilt — rotation from a fixed position. Great for reveals and for following across a landscape.
- Dolly or push-in — the camera physically advances. A slow push-in raises tension; a fast one is a punch.
- Pull-back or reveal — camera retreats, usually to reveal context after a close-up.
- Truck / lateral track — sideways movement, good for parallel action and for scanning a scene.
- Crane or boom — vertical travel, strong for openings and endings.
- Orbit / arc — circling a subject. Powerful but easy to make implausible; keep arcs small and slow.
- Handheld — micro-instability, documentary energy.
Always attach a rate: "very slow," "steady," "gradual." An unqualified "camera moves" instruction tends to produce a move that is too fast or drifts into something you never asked for.
Lighting and color temperature
The lighting decision is often the difference between "AI clip" and "footage." Describe light as something with a source and a direction, not a vibe. Motivated light — light that appears to come from a window, a lamp, a screen, a street sign — reads as real. Unmotivated even lighting reads as a render.
Build a small lighting vocabulary you can reuse across a project: hard midday sun with sharp shadows; soft overcast diffusion; golden-hour backlight with lens haze; practical neon at night with mixed color temperature; single-source key with deep falloff into darkness. Then decide your contrast ratio — how dark the shadows are relative to the highlights. High-contrast, low-key frames read as drama; low-contrast, bright frames read as comedy or documentary.
Turning Intent Into Prompt Language
Once the four decisions are separate, a shot description becomes a fill-in-the-blank sentence rather than improvisation. A dependable order is: subject and action, shot size, camera movement, lens and depth of field, lighting, palette and mood, then pacing or duration notes.
Here is the same shot written badly and well:
| Weak description | Directed description |
|---|---|
| "Cinematic shot of a woman in a city, cool lighting, 4k, masterpiece" | "A woman in a grey wool coat steps off a curb into traffic; medium shot; slow lateral truck to the right; 50mm lens, shallow depth of field, background traffic blurred; overcast morning light, soft shadows, muted blue-grey palette; calm, resigned mood; 4 seconds" |
The second version is longer but every clause constrains something real. The first version gives the model freedom it cannot use well.
A few habits that consistently improve output:
- Write in the present tense and describe what is visible. The model renders surfaces, not intentions. "She is afraid" produces a neutral face; "her jaw is tight, eyes fixed downward, hands still" produces a performance.
- Avoid contradiction. "Static camera slowly pushing in" guarantees a compromise you will not like.
- Keep the frame's contents countable. One subject, one background layer, one foreground element is a strong default.
- Say what should not appear when a model has a recurring habit — extra fingers, floating props, text overlays, sudden cuts to a new angle.
- Match duration to the beat. Ask for clips slightly longer than you need; trimming is easy, extending is not.
Camera Control in Practice: Blocking, Continuity, and Rhythm
Movement must be motivated. A push-in works because something is intensifying; an orbit works because something is being examined. If you cannot name the reason, a static frame is almost always stronger and cheaper to get right.
Continuity is where AI sequences live or die. Two rules do most of the work. The first is the 180-degree rule: keep the camera on one side of the line between two characters, or the audience will feel disoriented even if they cannot explain why. The second is eyeline match: if a character looks frame-right in one shot, the thing they are looking at should arrive from frame-left in the next. Generative tools will not enforce either, so you enforce it by specifying gaze direction and subject placement in every prompt.
Rhythm comes from shot length. A practical pattern for building a sequence is the shot ladder: wide to establish, medium to engage, close-up to intensify, then back out to release. Vary the lengths — a long wide followed by three short close-ups creates acceleration without any camera movement at all. Cutting on action (a door opening, a head turn, a step) hides the seams between separately generated clips better than any dissolve.
When two clips will be cut together, generate them as a matched pair: same palette, same light direction, same wardrobe language, same lens description, copied verbatim. Small wording changes between prompts produce visible discontinuities on screen.
Consistency: Keeping Characters, Wardrobe, and Sets Stable
Character drift is the most common complaint in AI video, and it is a workflow problem more than a model problem. Four techniques solve most of it.
Build a character sheet first. Generate a handful of still images of your character from several angles and expressions, pick the one that is most on-model, and treat that image as the anchor for every subsequent shot. Feed it as a reference rather than re-describing the character from scratch.
Freeze your wording. Write one canonical sentence describing the character's face, hair, build, and outfit, then paste it unchanged into every prompt. Paraphrasing between shots is a silent source of drift.
Use multiple reference images when the tool supports it. Supply a face reference, a wardrobe reference, and a location reference separately, and state which image controls which element. This is far more reliable than one cluttered composite.
Anchor the palette. Name three colors that define the scene and repeat them in every prompt for that scene. Color continuity does more for perceived consistency than perfect facial matching — audiences notice tonal shifts long before they notice a slightly different nose.
Sets need the same treatment. Generate a clean "plate" of your location with no characters in it, then reuse that plate as a reference for every shot in the scene. This also protects you during editing: if a shot goes wrong, you can regenerate it against a known-good background.
A Repeatable Production Workflow
Step 1 — Treatment and shot list
Write half a page of prose describing what happens and how it should feel. Then convert it into a numbered shot list with one line per shot: size, movement, subject, purpose. This document is your source of truth and the thing you will copy phrases from.
Step 2 — Stills before motion
Generate keyframes as images first. Stills are fast and cheap to iterate, and a good keyframe makes the animation step almost trivial. Approve the frame before you commit to motion; approving motion you dislike is expensive in time.
Step 3 — Animate with image-to-video
Use image-to-video rather than text-to-video for anything with a character or a specific composition. Describe only the movement and the change: what the camera does, what the subject does, what enters or leaves the frame. Redescribing the whole scene here usually destabilizes the frame you approved.
Step 4 — Edit, sound, and grade
Cut in a real editor. Add sound design early — footsteps, room tone, cloth movement — because audio does more to make AI footage feel shot than any visual trick. Grade all clips together with a single look so tonal differences collapse into one visual world. Match frame rates across clips before you begin.
Step 5 — Review twice, at two speeds
Watch the cut at normal speed for emotion, then at quarter speed for errors: warping faces, disappearing props, hands that change shape. Fix only what a normal-speed viewer would notice, then watch it again on a phone screen, which is where most of your audience will actually be.
Choosing Tools for Each Stage
The tool landscape is easier to navigate if you stop looking for one app that does everything and instead assemble a pipeline of specialists.
- Concept and stills: Midjourney, Flux, and Stable Diffusion variants handle keyframes and character sheets well, with LoRA training available when you need a single face repeated many times.
- Motion: image-to-video models from Runway, Kling, Luma, Pika, and the Veo- and Sora-class generators each have different strengths. Test the same keyframe across two or three and compare how they handle hands, faces, and slow camera moves.
- Fine control: ComfyUI with ControlNet-style conditioning lets you dictate pose, depth, and composition, which is the closest thing to a real camera rig in this space.
- Editing and finishing: DaVinci Resolve and Premiere Pro for cutting and grading; a dedicated upscaler such as Topaz Video AI when a clip needs to survive a large screen.
- Audio: a voice tool like ElevenLabs paired with a music generator and a library of real sound effects. Never rely on generated audio alone for footsteps and impacts.
Pick two motion models as your defaults and learn them deeply rather than sampling ten. Fluency with a tool's quirks beats novelty every time.
Common Mistakes That Break the Illusion
Overstuffed prompts. Every additional element is another thing that can drift. If a shot needs six ideas, it is probably three shots.
Compound camera moves. "Push in while orbiting and tilting up" produces mush. One move per shot.
Ignoring screen direction. Two shots that both look frame-right read as two people looking the same way. Specify gaze and placement.
Changing lighting between cuts. If a scene is overcast, keep saying overcast. A sudden shaft of golden light in the middle of a scene reads as a mistake, not a mood shift.
Shots that run too long. Generative clips get less stable the longer they run. Generate a few seconds longer than you need, then cut at the moment the frame is strongest.
Treating sound as an afterthought. Silent AI footage always looks like AI footage. Sound is the cheapest realism you can buy.
Skipping the plate. Regenerating a background from scratch every shot guarantees continuity errors you will spend hours repairing.
Quality Control Checklist Before You Export
- Faces stable across the full clip at quarter speed
- Hands and limbs anatomically plausible in every frame
- Wardrobe, hair, and props identical to the character sheet
- Light direction consistent with the previous and next shot
- Camera move executed at the requested speed and direction
- No unintended text, watermarks, or duplicated objects
- Resolution and frame rate matched across all clips
- Color graded as one sequence, not per clip
- Audio levels normalized with room tone under dialogue
- Viewed once on a phone, in silence, to confirm the visuals carry the story
FAQ
How long should an AI-generated shot be?
Treat three to five seconds as a comfortable default for anything with movement, and allow longer only for locked-off frames. If a beat needs eight seconds of screen time, consider two shots instead of one long clip — you gain control and lose almost nothing.
Should I write prompts in English even if my audience is elsewhere?
Most video models were trained predominantly on English captions and respond most predictably to English terminology, especially lens and lighting vocabulary. Write your shot list in your own language, then translate the technical prompt line literally. Keep the translation identical across a scene so consistency survives.
Why do my characters change face between shots?
Nearly always because you re-described them instead of reusing a reference image and identical wording. Lock one canonical description, attach a face reference, and stop improvising new adjectives.
Is text-to-video ever better than image-to-video?
Yes, for abstract transitions, landscapes, textures, and establishing shots where composition is not critical. For anything with a person, a product, or a specific framing you already approved, image-to-video wins.
How do I make AI footage feel less artificial?
Three fixes in order of impact: add real sound design, grade the whole sequence with one look, and cut faster so no single clip outlives its stability. Most "AI look" complaints are actually editing and audio complaints.
Do I need a storyboard?
A rough shot list is mandatory; drawings are optional. What matters is that every shot has a stated purpose, so you can delete anything that exists only because it looked nice in isolation.
What is the fastest way to improve?
Recreate a thirty-second scene from a film you admire, shot for shot. Matching someone else's decisions teaches you why each one exists far faster than generating freely. You will finish with a reusable shot list, a lighting vocabulary, and a clear sense of your tools' limits — which is exactly what cinematography is.
