
Why Cinematography Still Matters in the Age of Generative Video
Cinematography is the art and science of capturing moving images with intention. It decides where the audience looks, how they feel about what they see, and how long they are allowed to sit with a single moment before the story moves on. Generative video tools have not replaced any of that. They have simply moved part of the craft from the set to the timeline, the prompt, and the shot list.
The practical consequence is that AI-assisted filmmakers now need two overlapping skill sets. The first is the traditional one: light, lens, composition, movement, and pacing. The second is technical and editorial: how a diffusion-based video model interprets language, how it handles temporal consistency, and where it predictably fails. People who only learn the second set produce clips that look impressive for three seconds and then fall apart in an edit. People who learn both can produce sequences that hold together for minutes.
This guide walks through that overlap. It starts with the classical toolkit, explains how modern video models change the production pipeline, then moves into consistency, prompting, visual effects, direction, a full end-to-end workflow, and the mistakes that cost the most time.
The Classical Toolkit: Light, Frame, and Motion
Before touching any generation tool, it helps to be fluent in the three levers that define every shot. Almost every weakness in an AI-generated sequence traces back to one of them being vague.
Lighting and shadow as narrative tools
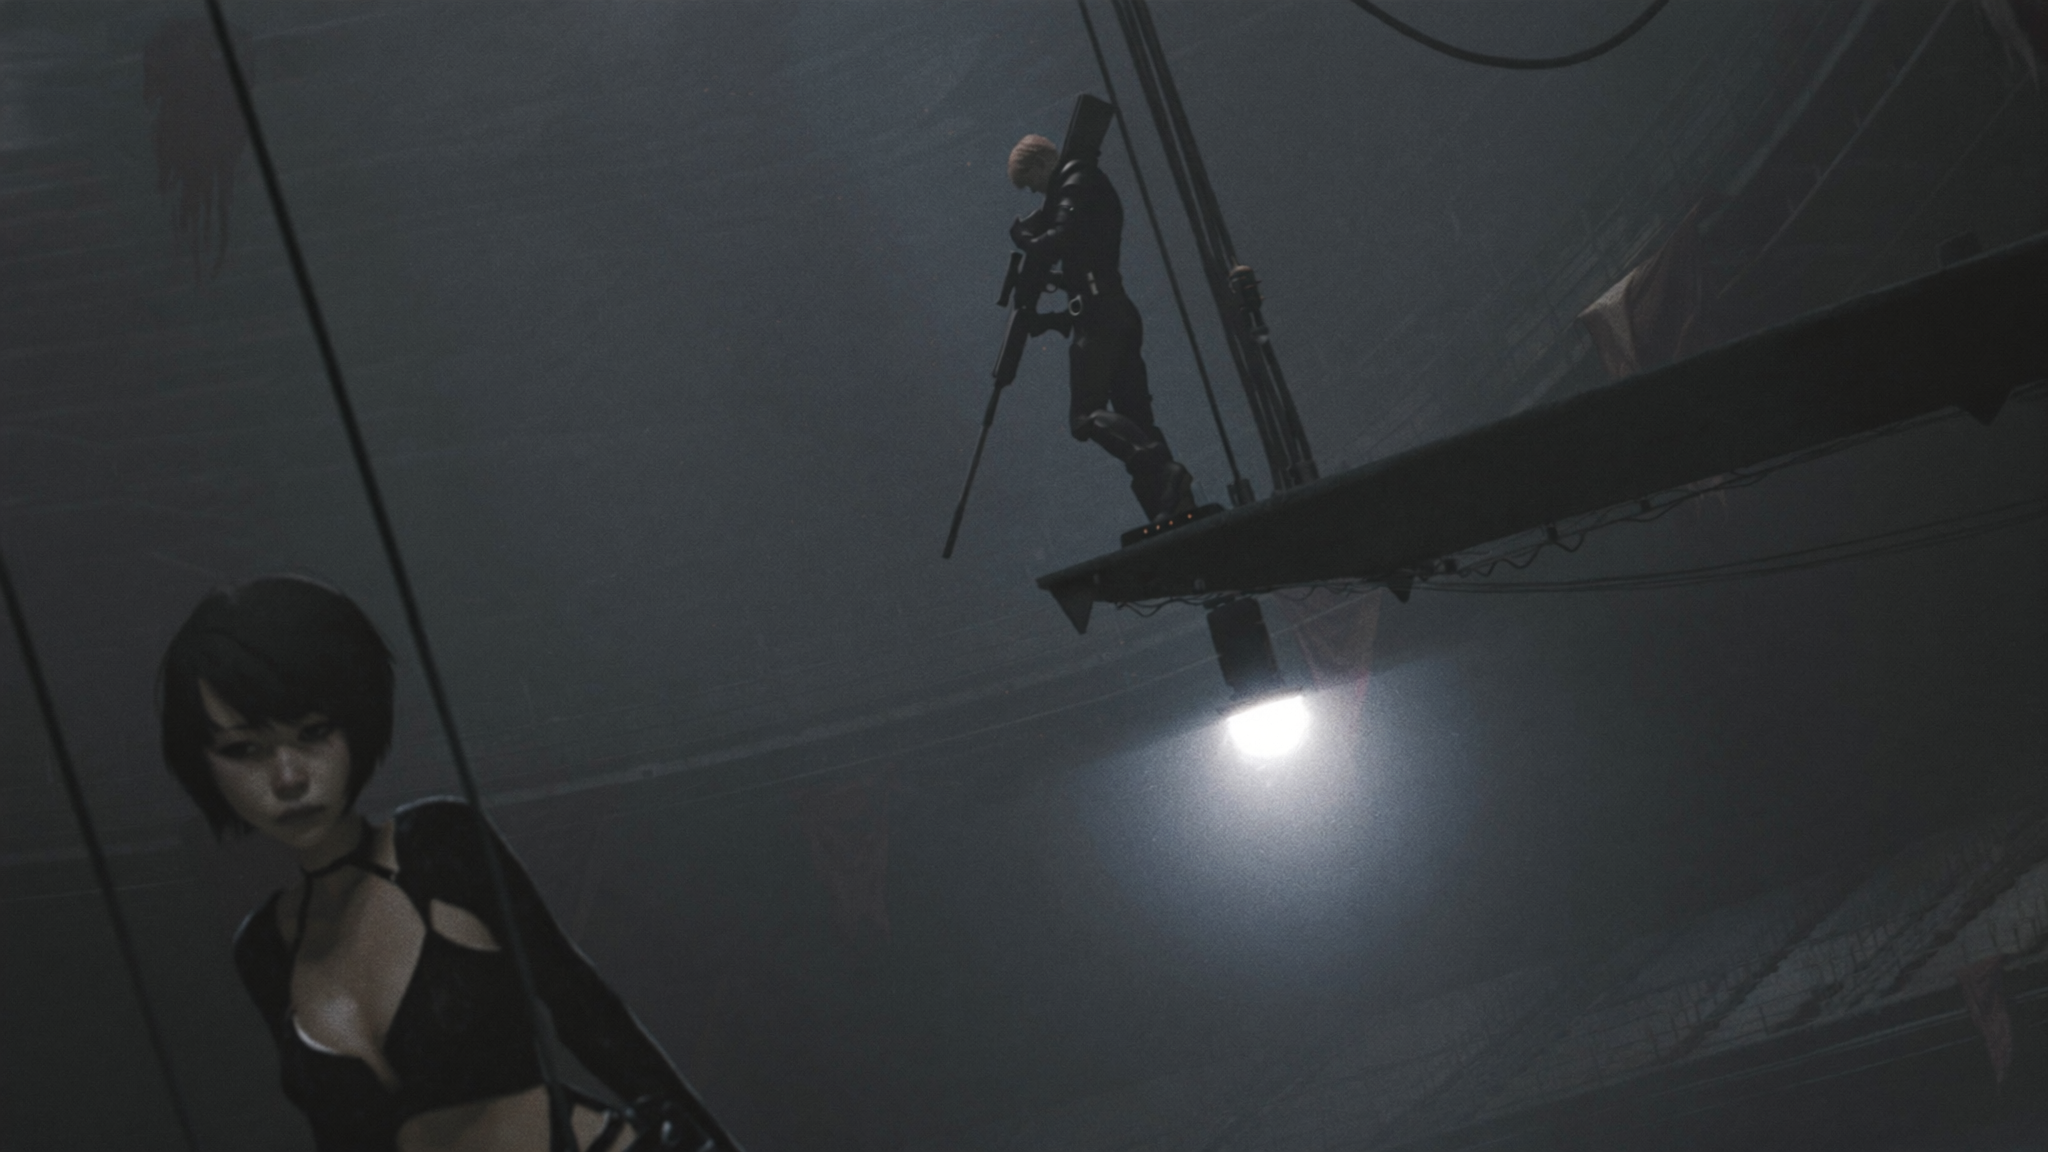
Lighting does three jobs at once: it reveals shape, it establishes mood, and it directs attention. A hard key from the side creates contrast and reads as tension. A large soft source above the subject flattens features and reads as calm or clinical. Practical sources inside the frame — a lamp, a screen, a fire — anchor the scene in a believable space and give the model something to reflect.
When you write a prompt, translate lighting into its physical components: source size, direction, color temperature, and ratio between key and fill. "Warm tungsten light from a window on the left, deep shadows on the right, slight haze in the air" gives a model far more to work with than "dramatic lighting." The same discipline applies when you shoot plates for compositing: match the direction, softness, and color of the light that already exists in the plate.
Composition and the art of breaking rules
Framing is a contract with the viewer. Placing a subject on a third line and leaving negative space in the direction of their gaze tells the audience where the story is heading. Centering a subject and locking the camera dead still does the opposite: it creates unease, formality, or confrontation.
The rules matter most when you break them deliberately. If you use a symmetrical, centered composition in a chaotic scene, the audience should feel the tension between the order of the frame and the disorder of the content. That is a choice. Random framing is not.
For AI work, composition has a second benefit: models respond strongly to layout language. Words like "wide establishing shot, subject small in frame on the lower right, empty road leading to horizon" produce more controllable results than abstract descriptions of mood.
Camera movement that serves the story
Movement should answer a question. A slow push in increases pressure or intimacy. A pull back reveals context and can undercut a moment. A lateral tracking shot follows action without interrupting it. A handheld feel adds immediacy but also chaos, so use it where the story is unstable.
In generated footage, movement is often the weakest link because the model has to invent consistent geometry as the camera moves. Short, motivated moves — a twelve-frame push, a gentle arc — usually survive generation better than long, complex choreography. When you need a long move, consider generating a wider, slower version and adding the final motion in post with a subtle scale and position animation.
How AI Video Models Change the Pipeline
Traditional production runs linearly: script, prep, shoot, post. AI-assisted production is iterative and non-linear. You write, generate, review, rewrite, regenerate, and assemble. Understanding the three main generation modes is what makes that loop efficient.
Text-to-video, image-to-video, and video-to-video
Text-to-video is the fastest way to explore ideas but the least controllable. It is excellent for mood boards, establishing shots, and discovering a visual direction you had not considered.
Image-to-video gives you a fixed starting frame, which dramatically improves both composition and consistency. Most professional AI sequences are built this way: a still image first, then animation. If you can draw, photograph, or render a strong keyframe, you have already solved half of the problem.
Video-to-video and motion-transfer workflows let you drive a generated look with real footage. This is how you get believable body language, hand gestures, and complex camera work without teaching a model from scratch. It is also the most reliable route to stylized transformations such as turning live-action plates into animation or painterly looks.
What models do well — and where they stumble
Current video models are strong at atmosphere: weather, light, texture, color, environment. They are increasingly good at short, self-contained actions. They still struggle with fine motor detail, precise text, complex object interactions, and cause-and-effect continuity across cuts — a character picking up a cup in one shot and holding it in the next.
The practical lesson is to design around those limits. Put the hard detail in a shot you can control with a still image. Keep interactions simple. If a character needs to handle an object, generate the moment of contact and cut before the details become ambiguous.
Building Consistency Across Characters, Locations, and Style
Consistency is the difference between a demo reel and a film. It comes from documentation, not luck.
Reference frames and character sheets
Create a character sheet before you generate anything long. Include a neutral portrait, a three-quarter view, a full-body frame, and two or three emotional variations. Save the exact prompt, seed, and reference image that produced each one. When you generate a new shot, attach the closest reference rather than describing the character from memory.
Do the same for locations. A handful of wide, medium, and detail frames of a room will keep light direction and set dressing stable across a sequence, which is exactly what audiences notice first when it drifts.
Style bibles and color scripts
A style bible is a short document that records your look: palette, contrast level, film grain characteristics, lens preferences, and any recurring motif. A color script goes further, mapping emotional temperature across the story — cool and desaturated in the opening, warmer and higher contrast as the stakes rise.
Both documents exist to make decisions faster. When a generated shot looks wrong, the style bible tells you why in one sentence instead of a twenty-minute debate.
Continuity in practice
Track four variables per shot: wardrobe, light direction, screen direction, and time of day. Most continuity breaks in AI sequences come from screen direction flipping — a character moving left to right in one shot and right to left in the next, which reads as a jump in space. Fix it by specifying direction explicitly in every prompt or by mirroring the clip in post.
Prompting Like a Cinematographer
Prompt writing is shot description. The more your prompt resembles a director's note, the more predictable your output.
Shot vocabulary that models understand
Use concrete terms: extreme wide, wide, medium, close-up, extreme close-up, over-the-shoulder, low angle, high angle, Dutch tilt. Add lens language where it helps — 24mm for environmental distortion, 50mm for neutral perspective, 85mm for compression and background separation. Add depth of field when it matters: shallow focus on the eyes, deep focus for an ensemble.
A reliable prompt structure is: subject and action, then environment, then lighting, then camera, then look. For example: "A lone cyclist pedals uphill through fog at dawn; pine forest and wet asphalt; soft backlit haze with a warm rim on the rider; low tracking shot from a car window, 35mm, shallow depth of field; muted teal and amber grade, light grain."
Describing light precisely
Replace adjectives with physics. Instead of "beautiful light," write "single hard source from camera left, 3200K, strong falloff, visible shadow edge on the wall." Instead of "moody," write "underexposed by two stops with a warm practical in the background." Models respond to measurable language because measurable language narrows the space of possible images.
Constraints and negative guidance
Constraints are as valuable as descriptions. State what you do not want: no text overlays, no lens flare, no extra limbs, no camera shake, no flicker. Keep the list short and specific; long lists of negatives dilute one another. If a model keeps adding a specific artifact, name it once per prompt rather than five times.
Visual Effects Without a Big Crew
Visual effects work in AI production is mostly compositing discipline. The generation is one step; matching the result into a shot is where quality lives.
Practical compositing steps
Start by stabilizing the plate. Remove camera shake if the generated element needs to track cleanly. Then set your element's position and scale, and match the perspective so the horizon lines agree. Next, match light: color temperature, direction, and contrast. Then add the artifacts that sell integration — motion blur on fast movement, grain matched to the plate, a slight defocus, and a subtle atmospheric haze pass between foreground and background.
Finally, grade the composite as one image. If the element still looks pasted on, the problem is almost always contrast or edge quality, not color.
Simulating explosions, weather, and crowds
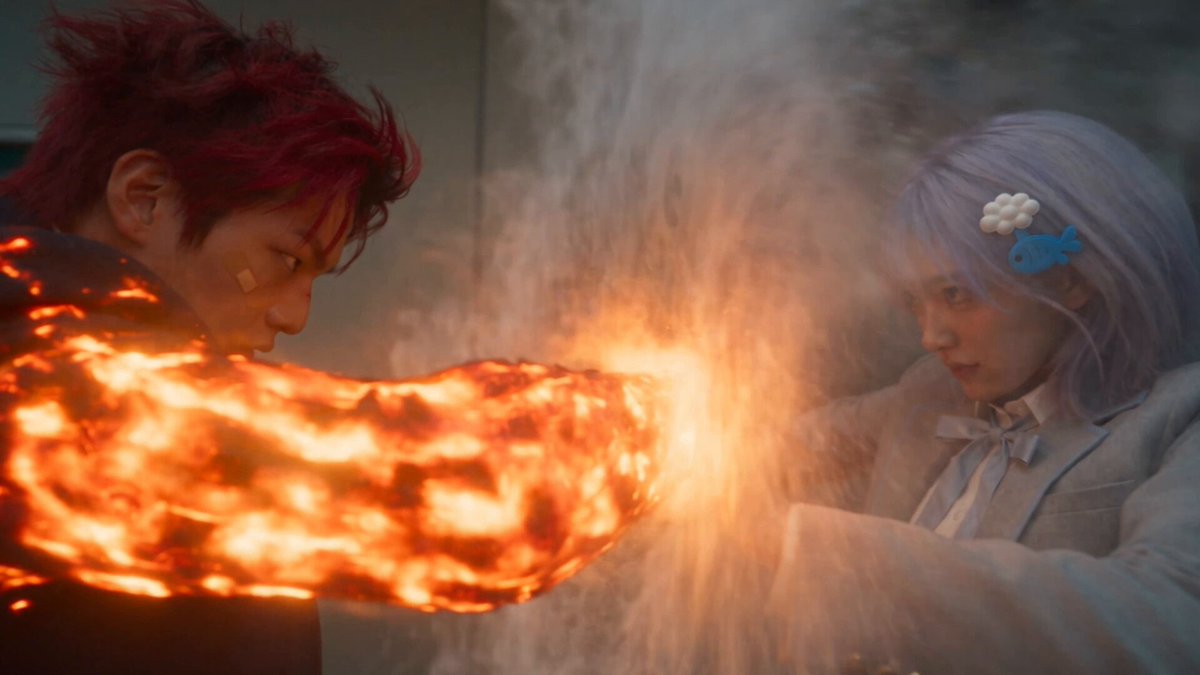
Large-scale practical effects are now largely a generation and compositing problem. Explosions work best when you generate the core in isolation against a simple background, then blend it with smoke plates and a fast light flicker that momentarily lifts the exposure of the surrounding scene. Weather is easier: rain, snow, fog, and dust are all additive layers with their own motion and depth.
Crowds remain one of the hardest cases because individual faces and gaits must stay coherent. A reliable approach is to generate a mid-distance crowd with motion blur and shallow focus, then place a few hero characters in the foreground where the audience will actually look.
Matching grain, blur, and lens character
Lens character is the fingerprint that makes a composite feel native. If your plate has halation around highlights, add it. If it has barrel distortion at the edges, apply the same distortion to the element. If the plate is clean digital, keep the element clean. Mismatched texture is the fastest way to break an otherwise perfect shot.
Directing with AI: Shot Lists, Storyboards, and Coverage
Direction is decision-making under constraint. AI does not remove the need for it; it makes it visible faster.
From script to shot list
Break the scene into beats, then into shots. For each shot, record: shot number, framing, subject and action, camera movement, lighting plan, and intended duration. A twenty-shot list for sixty seconds of screen time is a reasonable starting density for dialogue-driven scenes; action scenes often need more.
Storyboards and animatics
Storyboards do not need to be beautiful. Rough frames with correct composition are enough. Once the boards exist, generate a still for each and assemble them into an animatic with rough timing and temporary audio. This step catches problems — pacing, screen direction, unanswered questions — when they cost minutes rather than hours.
Editing, pacing, and coverage
Cut on movement, not on stillness; a cut lands more smoothly if the outgoing shot still has energy. Vary shot length deliberately: long takes build tension, short cuts build urgency. And shoot coverage even in AI: generate a wider and a tighter version of every important beat, plus a clean insert with no character, so you have options in the edit.
A Practical End-to-End Workflow
Pre-production
Write the scene. Build the shot list. Create character sheets and location references. Write the style bible and color script. Record the exact prompts and settings that produce each reference so the look is reproducible.
Generation
Generate stills first, approve the visual direction, then animate the approved stills. Work in short clips and check each one on a timeline rather than in isolation. Regenerate selectively: if one shot is wrong, fix that shot, not the whole sequence. Keep a log of what changed between iterations.
Assembly and finishing
Edit to a rough cut with temp sound. Lock picture before doing heavy effects work. Then composite, grade, and add sound design. Sound does more for perceived production value than almost any visual upgrade, so budget real time for it.
Common Mistakes and How to Fix Them
The most expensive errors are usually conceptual, not technical.
Overloading a single prompt. One prompt should describe one shot. If you are describing two actions, split it.
Ignoring screen direction. Track it per shot. Mirror in post when needed.
Chasing realism in every shot. Stylized footage hides detail failures; hyper-realism exposes them. Choose realism only where you can control the detail.
Skipping the animatic. Without it, pacing problems surface after you have already produced everything.
Treating generation as the finish line. Generation produces raw material. The edit, composite, grade, and mix produce the film.
Never reviewing on a timeline. A clip that looks great alone often fails in a cut, and a clip that looks weak alone can be perfect as a two-second insert.
Frequently Asked Questions
Do I need a film background to work with AI video tools? No, but you need the vocabulary. Learn lighting direction, framing, and camera movement terminology; that knowledge transfers directly into prompts and shot planning.
How long should a generated clip be? As short as the moment requires. Most usable clips run two to six seconds, and editors assemble sequences from many of them.
How do I keep a character's face consistent? Use a reference image per shot, keep the description identical across prompts, and limit the range of angles within a single scene.
Is it better to generate video directly or animate stills? Animate stills when composition and consistency matter. Generate directly when you are exploring a look or need a fast establishing shot.
What should I learn first? Editing. It teaches you what footage you actually need, which makes every earlier decision — script, shot list, prompt — sharper.
How do I handle audio? Build it separately. Record or generate dialogue, layer ambience and effects, then mix to picture. Clean sound design consistently reads as higher production value than additional visual polish.
The tools will keep changing. The underlying craft — deciding where the camera goes, what the light does, and how long the audience holds a moment — will not. Learn that, and every new model becomes a faster way to execute ideas you already understand.
