
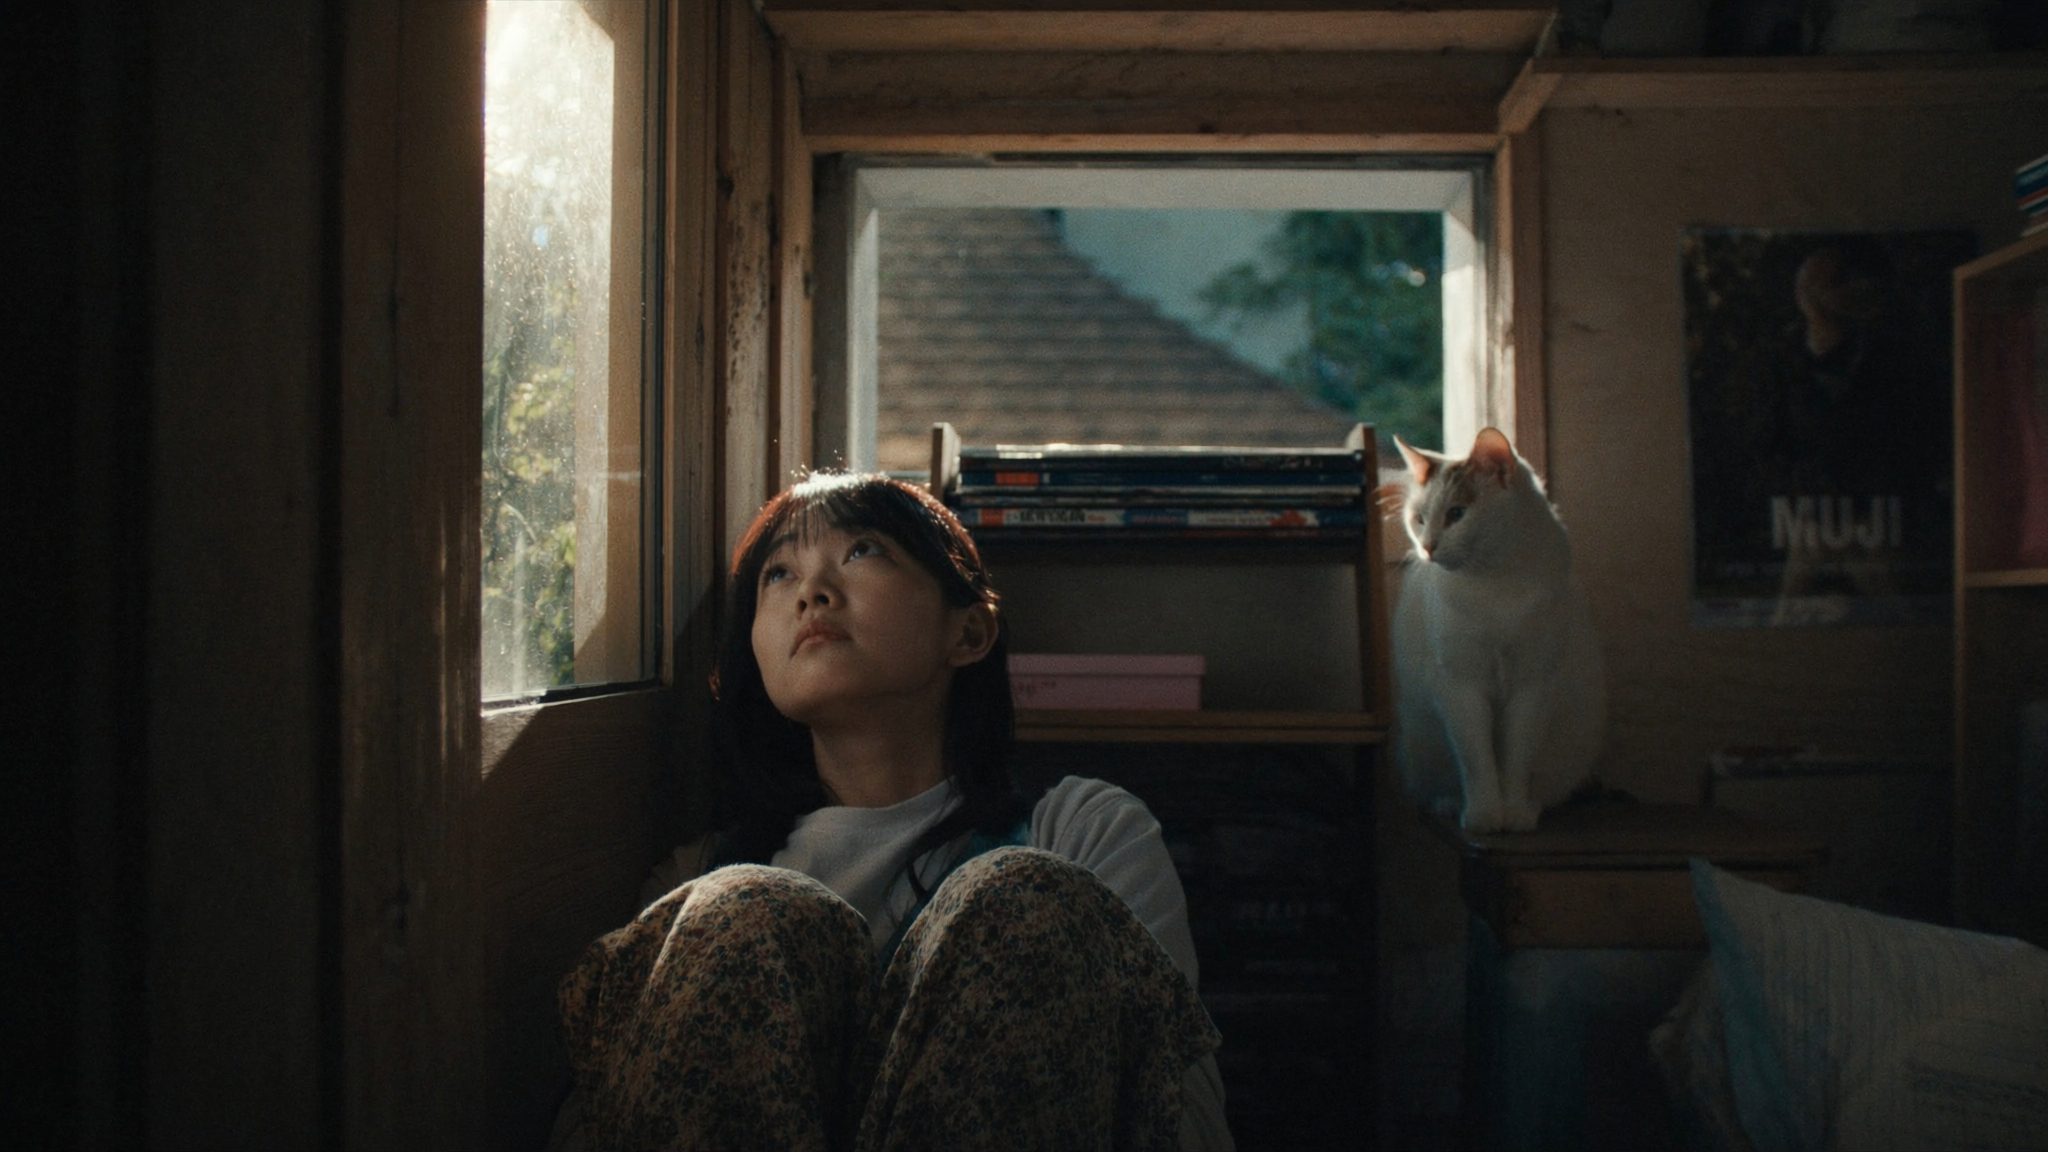
Most people treat an AI image generator like a slot machine: type a sentence, pull the lever, and hope a photograph falls out. That habit produces the same soft, glossy, faintly uncanny result again and again. The images that look genuinely captured — the ones viewers ask which camera shot — come from a short, repeatable pipeline instead: a structured prompt, a generator matched to the job, a control pass for composition, a consistency pass for repeated subjects, and a finishing pass that restores texture the model flattened. This guide walks through each stage, the decisions inside it, and the failure modes that quietly destroy realism.
Why Photorealism Is a Pipeline, Not a Prompt
Realism has four largely independent layers: content (what is in the frame), composition (where it sits), consistency (whether it matches the rest of your set), and surface (how skin, fabric, and light actually render). A prompt only reaches the first layer, and even then loosely. The other three are controlled by model choice, reference images, structural maps, and post-processing.
That distinction explains a common frustration. Someone writes a long, poetic prompt, gets one lucky image, then cannot reproduce it or match it with a second shot. They blame the model. The real problem is that they never built controls for layers two through four.
Treat each image as a small production with inputs and checkpoints rather than a lucky draw. The payoff is not just better single frames; it is a set of images that look like they came from the same photographer, lens, and lighting setup — which is what commercial work actually demands.
Choosing the Right Generator for the Job
No single tool wins every category. Portrait realism, product shots, architectural interiors, and action scenes each stress different parts of a model, and the fastest route to quality is matching the tool to the target rather than forcing one favourite to do everything.
Diffusion Generators Versus Unified Transformer Models
Diffusion-based systems, including Stable Diffusion derivatives and Flux variants, remain the most controllable option. They accept reference images, pose maps, depth maps, and custom style adapters, and they can run locally when privacy matters. Their weakness is that they need tuning: a good result often requires a sampler choice, a step count, and a guidance value that suit the subject.
Unified transformer-style generators tend to be stronger at language comprehension and one-shot composition. Describe a complex scene with several objects and relationships, and they usually interpret it more faithfully on the first try. They are weaker at surgical control — changing one sleeve, matching one face, or preserving an exact layout.
A practical split: use the language-strong generators for ideation and hero frames, then move to diffusion with structural controls when the brief hardens and the client wants specific framing.
Hosted Platforms Versus Local Pipelines
Hosted generators win on speed to first result, model variety, and zero hardware concerns. Local pipelines, typically built in ComfyUI or a similar node interface, win on reproducibility, batch processing, and fine control over every stage. If you deliver a handful of images per week, hosted is usually enough. If you deliver a hundred variations for a campaign, the ability to save and rerun an exact graph is worth the setup time.
Prompt Engineering That Actually Changes the Output
Prompting is not decoration; it is specification. Vague prompts hand creative decisions to the model, and the model's defaults are exactly the bland, over-lit look you are trying to avoid. Specificity narrows the distribution of possible outputs toward the frame you want.
The Five-Slot Prompt Skeleton
A prompt that renders predictably usually carries five slots: subject, action or pose, environment, lighting, and capture details. For example: a woman in her thirties in a linen shirt, leaning against a warehouse door, late afternoon, warm side light with soft shadows, 85mm lens, shallow depth of field. Each slot removes ambiguity, and each slot can be swapped independently when you iterate.
Order matters less than presence, but clarity matters a great deal. Write one concrete detail instead of three poetic adjectives. A model cannot render a melancholic mood, but it can render dim window light, a rain-streaked pane, and a downcast gaze — and the mood appears on its own.
Camera, Lens, and Film Language
Photographic vocabulary is the fastest realism shortcut available. Focal length changes perspective and facial compression: 35mm gives environmental context, 50mm feels neutral, 85mm flatters faces, 135mm compresses backgrounds into soft planes of colour. Aperture controls how much context dissolves: f/1.8 isolates a subject, f/8 keeps a street readable behind them.
Add a plausible capture reference — mirrorless body, natural light, slight handheld tilt — and the model tends to produce optics that behave like glass rather than a render. Be careful not to stack contradictory cues such as both a wide lens and extreme background compression; conflicting instructions produce mush.
Negative Prompts and What to Stop Writing
Negative prompts work best when they target rendering artefacts rather than ideas. Plastic skin, waxy texture, extra fingers, warped hands, blurry text, low contrast haze, and over-sharpened edges are legitimate entries. Long lists of stylistic negatives usually do nothing except dilute attention.
Equally important is what to remove from your positive prompt. Words such as beautiful, masterpiece, hyper-detailed, and award-winning rarely improve realism and often push output toward illustration. Replace them with measurable instructions about light, lens, and surface.
Controlling Composition with Structure Maps
Text cannot specify geometry precisely, and that is where structural conditioning earns its place. A depth map from a reference photograph, a pose skeleton, or an edge map tells the model where things must sit, leaving it free to invent texture and lighting inside those constraints.
Depth, Pose, and Edge Control
A depth pass is the single most useful control for realistic scenes because it defines foreground, midground, and background relationships. A pose pass is essential for people: it locks limb positions and prevents the anatomical drift that ruins otherwise good frames. Edge control handles architecture, products, and typography, where straight lines and accurate silhouettes matter more than organic variation.
In practice, you build a rough reference — a photo, a 3D blockout, or a sketch — extract the relevant map, then run generation with moderate control strength. Too high and the output looks traced; too low and the map is ignored. Start around the middle and adjust per subject.
Inpainting and Outpainting for Surgical Fixes
Never re-roll an entire image to fix a hand. Inpainting a masked region with a tight, local prompt preserves everything you already approved. Outpainting extends the canvas for wider crops, banner formats, and vertical social versions from a single approved frame.
The trick is matching grain and light in the patched area. Give the inpainting prompt the same lighting and lens language as the original, then compare at 100% zoom. Patches that look fine when zoomed out often reveal mismatched shadow direction up close.
Consistency Across a Set of Images
A single convincing frame is easy. Six frames of the same person, in the same wardrobe, under the same lighting, is where most workflows collapse. Consistency is a system problem, not a prompting problem.
Reference-First Character Workflow
Approve a reference image before generating anything else. That reference becomes the anchor: every later frame conditions on it through a character adapter, an identity-preserving reference input, or a lightly trained personal adapter. Faces are the hardest element, so lock them early and never regenerate them casually.
Keep the reference tight — a neutral expression, even lighting, no occlusion. A reference shot with dramatic shadows teaches the model to reproduce those shadows in every scene, including interiors where they make no sense.
Style Bibles and Locked Settings
Write down what you used: model version, sampler, step count, guidance value, seed, and reference strength. This is your style bible, and it is what makes a campaign reproducible weeks later. When a client asks for three more images in the same look, you are rerunning a recipe rather than guessing.
Lock seeds where variation is unwanted and unlock them where you need options. Store everything with the delivered file so future you, or a collaborator, can trace how a frame was built.
Pose and Emotion: The Subtlety of Human Realism
Uncanny faces usually fail on micro-expression, not structure. A model asked for happiness defaults to a symmetrical smile that reads as a stock photo. Instead, specify an asymmetric cue: a slight smile with eyes relaxed, a glance off-camera, a half-lidded expression in low light. Small asymmetries are what convince the eye that a person is present.
Hands remain the classic weak point. Keep them simple — holding a cup, resting on a surface, partially cropped — rather than articulated in complex gestures. Simple poses render reliably and read as natural rather than staged.
Finishing: Resolution, Texture, and Post-Production
Generators tend to flatten high-frequency detail. The finishing stage puts grain back, evens out tonal rolls, and fixes colour casts. Skipping it leaves images that look technically sharp but physically wrong.
An Upscaling Pipeline That Preserves Skin
Upscale in two modest steps rather than one large jump. A mild first pass (around 1.5×) keeps structure clean; a second pass brings you to delivery resolution. Aggressive single-pass upscalers add detail that was never there, producing the waxy, over-defined look that signals synthetic origin.
Add a controlled grain layer at the end, matched to your ISO reference. Film-like grain hides minor artefacts and gives digital frames the physical texture the eye associates with photographs. Then apply a light unsharp mask with a high threshold so only real edges sharpen.
A Five-Minute Post Checklist
Check white balance against a neutral reference, verify blacks are not crushed, confirm highlight roll-off is smooth, scan at 100% for warped hands and garbled background text, and compare the final image against the approved reference for skin tone and shadow direction. Five minutes at the end saves an awkward conversation at delivery.
A Repeatable Production Workflow
When a brief arrives, resist the urge to generate immediately. Spend the first ten minutes defining the target: aspect ratios, subject count, lighting direction, wardrobe, and the reference frame that will anchor the set. Everything downstream gets faster when the target is written down.
Step-by-Step From Brief to Delivery
- Write the five-slot prompt for the hero frame and generate a low-cost batch of thumbnails.
- Pick the composition that solves the brief, not the prettiest accident.
- Extract a depth map or pose map and rerun with structural control at moderate strength.
- Inpaint problem zones instead of regenerating whole frames.
- Lock the reference and produce the remaining shots in the set with the same recipe.
- Upscale in two passes, add grain, and colour-grade against the reference.
- Export in the required formats, including vertical and square crops via outpainting rather than awkward re-crops.
- Archive prompt, settings, and reference alongside the delivered files.
Batch Discipline and Asset Naming
Name files with a predictable pattern: project, scene, subject, shot number, version. Sorting then becomes automatic, and version confusion disappears. Keep a single working folder per scene so reference images never get mixed between projects — cross-contamination between characters is one of the most common consistency failures.
Common Mistakes and How to Fix Them
The same handful of problems appear in almost every review. Recognising the cause turns a vague sense that something is off into a single corrective action.
| Symptom | Likely cause | Fix |
|---|---|---|
| Plastic, poreless skin | Aggressive upscaling or heavy denoise | Reduce upscale ratio, lower denoise strength, add grain |
| Flat, even lighting | No lighting direction in the prompt | Specify side, back, or window light with shadow behaviour |
| Faces drift between frames | No locked reference | Condition every frame on one approved reference |
| Strange hands | Complex gestures requested | Simplify the pose or crop the hands out |
| Over-sharpened edges | Strong sharpening after upscale | Unsharp mask with high threshold, or none at all |
| Muddy background text | Model rendering typography | Remove or blur text, or composite real type later |
One meta-mistake sits above the table: generating before specifying. Ten minutes of written intent consistently beats an hour of random iteration, and it makes the difference between a lucky image and a deliverable set.
Ethics, Disclosure, and Client Expectations
Realistic synthetic imagery raises legitimate questions, and handling them well protects both your reputation and your client. If a generated image could plausibly be mistaken for a photograph of a real event or a real person, label it. Most platforms and many jurisdictions expect disclosure, and audiences increasingly appreciate transparency rather than resenting it.
Avoid depicting identifiable public figures in invented situations, avoid fabricating documentary evidence, and avoid synthetic likenesses of private individuals without consent. In commercial work, agree in writing on whether images may be used in advertising, on packaging, or on social channels, and confirm who owns the outputs.
A short line in your delivery notes — these images are AI-generated — costs nothing and removes ambiguity. Clients rarely object to the method; they object to discovering it later.
FAQ
How many attempts does one usable photorealistic image take?
With a structured prompt and a matched model, expect five to fifteen variations for a strong hero frame, and fewer once you have a locked reference and a working recipe. Random prompting can take fifty or more, which is why the pipeline pays for itself quickly.
Does higher resolution mean more realism?
No. Past a point, resolution only magnifies errors. Realism comes from correct lighting, plausible optics, natural skin texture, and consistent anatomy. A well-lit 2K frame with good grain beats a crunchy 8K frame every time.
What is the fastest way to keep the same face across images?
Approve one neutral, evenly lit reference image, then condition every subsequent frame on it using a character or identity-reference input. Lock the seed when variation is not needed, and avoid regenerating faces that already work.
Should I use a hosted generator or a local setup?
Choose hosted tools for speed, variety, and low maintenance. Choose a local node-based pipeline when you need exact reproducibility, large batches, structural controls, or privacy for client material. Many teams use both: hosted for exploration, local for production.
How do I avoid the plastic skin look?
Reduce upscale aggressiveness, lower denoise strength, add a grain pass, and soften sharpening. Prompt for visible skin texture and natural imperfection rather than flawless beauty, and compare results against real photographs of similar lighting at 100% zoom.
Can I fix a single bad element without regenerating everything?
Yes, and you should. Mask the problem area, inpaint with a prompt that matches the original lighting and lens language, then check shadow direction at full zoom. Regenerating a whole frame to fix one hand almost always costs you something that was already right.
