
Why Single Prompts Rarely Produce a Story
Almost everyone starts the same way. You open a generative video tool, type a vivid paragraph about a lone astronaut walking across a salt flat, and get back five seconds of something genuinely beautiful. Then you try to make a second shot, and the astronaut has a different face, a different jacket, and the desert has turned into a pine forest.
The model is not broken. The problem is that you asked one tool to do five jobs at once. A finished story needs a narrative spine, a visual identity, a shot plan, consistent generation, and a sound design. A text box cannot hold all of that, and a five-second clip cannot express it.
Three failure modes show up over and over:
- Drift. Faces, wardrobes, props, and locations shift between shots. Shot 12 looks like a different film than shot 1.
- Discontinuity. There is no spatial logic. Characters teleport, light sources move, and screen direction flips from left to right with no reason.
- Rhythm collapse. Every clip is roughly the same length and the same energy, so the piece feels like a slideshow rather than a scene.
The fix is not a better prompt. The fix is treating AI video as a production pipeline and giving each stage its own inputs and outputs. Once you separate the story layer from the generation layer, consistency stops being a matter of luck.
The Five-Layer Story Pipeline
Think of your project as five layers stacked in order. Each layer has a deliverable you can review and hand off, which means you can diagnose problems before they multiply.
| Layer | Deliverable | Typical tooling | Rough time share |
|---|---|---|---|
| 1. Story spine | Logline, 8–12 beats, beat sheet | Notes app, screenwriting tool | 10% |
| 2. Visual bible | Character sheet, palette, lens language, reference frames | Image generator, mood board | 20% |
| 3. Shot list | One row per shot with framing, action, duration, references | Spreadsheet | 15% |
| 4. Generation passes | Draft, consistency, hero clips | Video generators, image-to-video | 40% |
| 5. Assembly and sound | Edit, music, dialogue, captions | Editor, audio tools | 15% |
Layer 1 — Build the spine before you touch a generator
Write a one-sentence logline, then break the story into 8 to 12 beats. Each beat becomes a scene, and each scene becomes three to six shots. For a 60-second short, that is roughly 14 to 20 shots at 3–4 seconds each. Write this in plain language. No camera directions, no model names, no prompts. You are specifying intent, not execution.
Layer 2 — Lock the visual bible
This is the layer most creators skip and later regret. Your visual bible should contain:
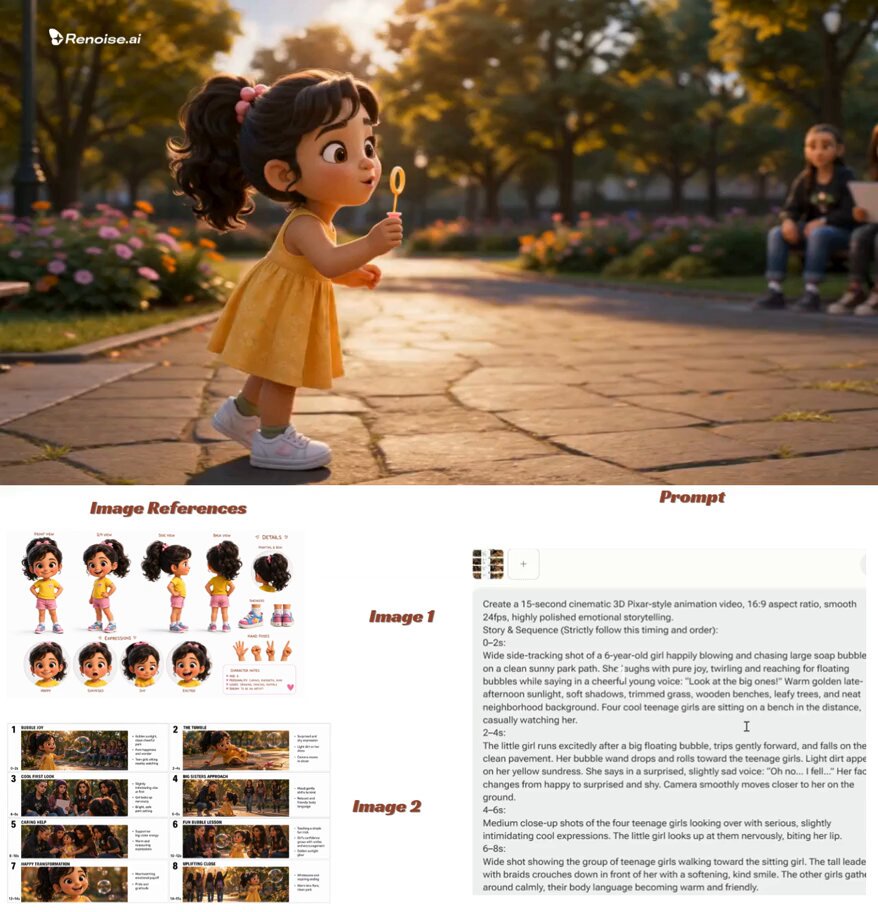
- A character reference sheet: front, three-quarter, and profile views, plus one full-body shot.
- A wardrobe description written in fixed wording you will reuse verbatim.
- A location reference per setting, ideally three angles.
- A palette with four or five named colors.
- A lens and film language note, such as "35mm anamorphic, shallow depth of field, slight halation, warm shadows."
Layer 3 — Turn beats into a shot list
Each row of the shot list should contain: shot ID, duration, framing, subject action, setting, camera move, reference image, and seed value if your tool supports it. The shot list is your contract with the generator. When a clip comes back wrong, you fix one row, not the whole scene.
Layer 4 — Run generation in three passes
Never try to make final-quality clips on the first attempt. Run a draft pass at low resolution to check blocking and timing. Then a consistency pass using reference images and locked seeds. Then a hero pass at maximum quality for the shots that survive the edit.
Layer 5 — Assemble and design sound
Edit first with temp music. Dialogue, foley, and ambience come after the picture is locked, because sound design should follow the rhythm you actually have, not the rhythm you planned.
Prompt Anatomy: The Six Slots That Survive Editing
A prompt that works is a structured record, not a poem. Use six slots in a fixed order so that only the parts you intend to change actually change.
- Subject — the person, creature, or object, described with fixed wording.
- Action — a single present-tense verb phrase.
- Setting — location plus one or two environmental details.
- Framing and lens — wide, medium, close-up, and a lens character.
- Light and color — time of day, source direction, palette.
- Motion and constraints — camera movement, speed, plus what to avoid.
Here is the same character across three shots of one scene, with only the intended slots changing:
- Shot 3: "A woman in a charcoal wool coat with a red scarf, walking slowly across a wet market street, medium shot, 35mm, overcast morning light, cool blue palette, slow lateral dolly, no text."
- Shot 4: "The same woman in a charcoal wool coat with a red scarf, pausing to look at a fruit stall, close-up on hands, 85mm, overcast morning light, cool blue palette, static camera, no text."
- Shot 5: "The same woman in a charcoal wool coat with a red scarf, turning to walk away from camera, wide shot, 24mm, overcast morning light, cool blue palette, handheld follow, no text."
Notice that the wardrobe phrasing is copy-pasted. That is deliberate. Any rewording — "dark coat" instead of "charcoal wool coat" — gives the model permission to reinvent the costume.
Keep a prompt library in the same document as your shot list. When a prompt produces a great result, save the exact text and the seed. Iteration on a strong base beats invention from scratch.
Locking Characters Across Shots
Character consistency is the single hardest problem in AI storytelling, and it is mostly solved by discipline rather than by any one feature.
Start with a casting pass. Generate 20 to 30 stills of your character before you generate a single video. Pick the three strongest and treat them as canon. Everything downstream references those three.
Use image-to-video wherever the story allows it. Generating a first frame as a still, approving it, and then animating it gives you far more control than text-to-video. You are effectively choosing the frame the audience will see.
Fuse multiple references when the tool supports it. Feeding a face reference plus a wardrobe reference plus a lighting reference usually beats feeding a single image, because each reference constrains a different axis.
Freeze the descriptor vocabulary. Write your character description once and paste it every time. Create a small table:
| Attribute | Locked wording |
|---|---|
| Hair | "shoulder-length black hair, centre part" |
| Coat | "charcoal wool coat, calf length, no belt" |
| Accent color | "faded red scarf" |
| Age read | "mid thirties" |
Regenerate ruthlessly. If a face drifts in the consistency pass, discard the clip rather than trying to rescue it in post. A mismatched face will break the illusion for the whole sequence, and no color grade hides it.
Avoid too many named characters. Two or three recurring people is the practical ceiling for a short piece. Beyond that, viewer attention and model reliability both degrade.
Style Synchronization Across Generators
Most creators end up using more than one generator, because each has strengths — one handles motion well, another renders faces better, a third produces stronger texture. The result is a film that looks like three different films.
Build a style recipe and treat it as the source of truth:
- Aspect ratio and resolution for every clip.
- Palette expressed as hex values for the grade.
- Grain amount and whether halation is present.
- Contrast curve: crushed blacks or lifted shadows.
- Motion feel: crisp, or with a slight shutter smear.
- Frame rate, kept identical across all sources.
The practical move is what editors have done for decades: normalize in post. Generate at the highest quality your tools allow, conform every clip to the same timeline, apply one grade to the whole sequence, and add one grain pass over everything. A single grade across mixed sources does more for perceived consistency than any prompt trick.
When choosing between generators for a specific shot, use these criteria:
| Situation | Better choice |
|---|---|
| Character face is central | The generator with the strongest reference-image adherence |
| Complex body motion | The generator with the most stable temporal coherence |
| Establishing landscape | The generator with the best texture and scale |
| Dialogue close-up | Image-to-video from an approved still |
| Fast insert | Whatever renders fastest — it will be on screen for under a second |
Shot Composition and Camera Language That Reads as Directed
Amateur AI video looks amateur because every shot is a medium shot of a person doing something. Real scenes have coverage. For each location, plan at least three of these:
- Establishing wide — where are we, what time is it.
- Medium — the standard conversational shot.
- Close-up — emotional emphasis, faces or hands.
- Insert — a detail that carries meaning: a phone screen, a key, a scar.
- Reaction — someone responding to what just happened.
Respect screen direction. If a character exits frame right in shot 6, they should enter frame left in shot 7, or you have implied a turn that did not happen. Keep the light on the same side of the face across a conversation. These two rules alone make a sequence feel professionally blocked.
Camera moves should be motivated. Use these as defaults:
| Move | Use it when |
|---|---|
| Static | The performance or the composition carries the shot |
| Slow push in | Tension is building or a realization is landing |
| Lateral dolly | Moving through space with a character |
| Handheld follow | Urgency, documentary feel |
| Crane or tilt up | Revealing scale |
| Whip pan | Fast transition between scenes |
Give each move a reason. A camera that drifts because the prompt said "cinematic camera movement" reads as noise.
Audio, Rhythm, and Pacing
Sound is where AI projects usually fall apart, because the picture is impressive and the audio is an afterthought.
Decide early whether the piece is music-driven or dialogue-driven. Music-driven shorts tolerate more visual abstraction and shorter shots. Dialogue-driven scenes need longer holds and room for performance, which means fewer generated clips and more careful lip-sync work.
Layer your sound bed:
- Ambience — one continuous bed per location so cuts do not feel like silence gaps.
- Foley — footsteps, cloth, doors, cup placement. Small sounds make generated motion feel physically real.
- Dialogue — generate or record lines, then cut them to picture rather than cutting picture to them.
- Music — pick a track early for temp, replace late.
Cut to the beat only in montage sections. In dramatic scenes, cutting on dialogue emphasis or on a physical action reads better. Use silence as punctuation: dropping all sound for half a second before a reveal is one of the cheapest, most effective tools available.
Target consistent loudness across the whole piece — around −14 LUFS for web platforms is a safe default — and check on phone speakers. Most viewers will hear your film through a two-centimeter driver.
Quality Control Checklist Before You Publish
Run this list on a full playback with a notepad, watching for one category at a time:
- Continuity — wardrobe, props, hair, and injuries consistent between shots.
- Screen direction — no unexplained flips in movement axis.
- Face check — every appearance of a recurring character reads as the same person.
- Hands and text — look for extra fingers and garbled signage.
- Camera jitter — any clip with unstable frames gets cut or stabilized.
- Color match — flip through the timeline at speed; no clip should jump in temperature.
- Audio continuity — no ambience dropouts at cuts.
- Loudness — consistent peaks and no clipping.
- Captions — burned-in or uploaded, legible at phone size.
- Aspect variants — export a vertical cut if the piece will live on social feeds.
- First frame — does the opening frame work as a thumbnail and a still?
- Ending — the final shot should resolve something, even quietly.
Validate on two devices: a phone and a large screen. Problems invisible on one are obvious on the other.
Common Mistakes and How to Fix Them
Overloading a single prompt. Nine adjectives fight each other and the model averages them into mush. Fix: cut to three visual descriptors and move the rest into your style bible.
Switching generators mid-project without a plan. Fix: finish a full pass in one tool, then re-render only problem shots elsewhere and match in the grade.
No shot list. Fix: even a five-row spreadsheet prevents reshoots. Write duration before you generate.
Changing wardrobe wording. Fix: lock the phrase and paste it. Never paraphrase your own character.
Rendering hero quality too early. Fix: block the whole edit at draft quality, then upgrade only what made the cut.
Ignoring the first frame. Fix: design shot 1 as a still image first. If it is not compelling frozen, it will not be compelling in motion.
Too many characters. Fix: consolidate roles. Extras can be silhouettes or backs of heads.
Adding music last. Fix: temp score from day one so you can feel the pacing while you cut.
Trusting the model for the story. Fix: the beats come from you. The model renders them.
FAQ
How long should an AI-narrated short be?
For a first project, 45 to 90 seconds. That is roughly 12 to 20 shots and it is achievable in a weekend. Longer pieces multiply consistency problems faster than they multiply payoff.
Do I need several video generators?
Not at first. Master one, learn its failure patterns, and add a second only when you hit a specific recurring limitation — typically face consistency or complex motion.
What is the fastest way to keep faces consistent?
Generate a strong still, use it as the first frame, and animate it. Approve the frame before you spend time on motion.
How much footage should I generate?
Plan on generating roughly three to five times the footage you need. A 60-second film usually consumes 3 to 5 minutes of usable-looking clips before editing.
Should I generate dialogue or record it?
Record it if you can. Real performance timing gives you a rhythm to cut against, and synced generated dialogue is easier to integrate when it matches an existing audio track.
What resolution do I actually need?
1080p is sufficient for most web distribution. Generate draft passes at lower resolution to save time, and reserve maximum quality for hero shots.
When should I use text-to-video instead of image-to-video?
Use text-to-video for abstract transitions, landscapes, and texture inserts. Use image-to-video whenever a specific character, prop, or composition must be reproduced exactly.
How do I stop the piece from feeling like a slideshow?
Vary shot length, vary shot size, and add one motivated camera move every three or four shots. Rhythm comes from contrast, not from constant motion.
Start with a 30-second scene, two characters, one location. Build the spine, lock the bible, write the shot list, run three passes, and finish the sound. The workflow scales to longer pieces, series, and client work — but only if the discipline starts at the smallest possible size.
