
Why AI clipping changed the editing floor
Editing a short clip used to be a manual craft measured in hours. You scrubbed the timeline, hunted for the usable moment, cut it, cleaned up the audio, burned captions, and exported three aspect ratios. A single 45-second vertical clip could easily eat ninety minutes of an editor's day, and most of that time went into mechanical work rather than creative judgment.
AI-assisted clipping redistributes the effort. Speech-to-text models surface the moments worth keeping. Shot-level generation models fill gaps that previously required a reshoot. Voice models repair noisy dialogue or replace a fumbled line. Auto-reframing tracks a subject and recomposes them for vertical, square, and widescreen delivery. The editor's job shifts from operating the timeline to deciding what the clip should be.
The practical upside is throughput. One editor can supervise a dozen variants of the same clip, test three different hooks, and ship whichever version holds attention. The risk is equally obvious: when generation becomes cheap, it is easy to publish footage that looks synthetic, sounds hollow, and contradicts itself from one shot to the next.
This guide lays out a neutral, tool-agnostic workflow for AI video clipping. It covers the order of operations, the decision points where automation genuinely helps, the places where human judgment still wins, and the checks that stop a fast pipeline from turning into a sloppy one.
What an AI clipping workflow should optimize for
Before you pick a single tool, decide what you are optimizing. Three goals pull in different directions, and most bad AI edits come from trying to satisfy all three at once without ranking them.
Volume. If the objective is to publish daily or to produce dozens of short-form variants from one long recording, then transcription quality and batch reframing matter more than photorealism. You want a pipeline where a 60-minute interview becomes 20 candidate clips in under an hour, even if a handful of those clips are only good enough to test.
Believability. If the clip carries a brand promise, a customer story, or a legal claim, then consistency and audio fidelity outrank speed. A slightly imperfect real take usually beats a seamless synthetic one, because audiences forgive lighting and forgive ums, but they rarely forgive a face that shifts shape mid-sentence.
Legibility. If the clip is going into a feed where people watch with sound off, then caption accuracy and framing are the whole game. A brilliant moment with a cropped forehead and drifting subtitles will underperform a mediocre moment that reads perfectly on a phone.
Write your priority down. In practice, the ranking looks like this for most teams: legibility first, believability second, volume third. Legibility is the cheapest to get right and the most damaging to get wrong.
The four layers of a modern clip stack
Every AI clipping pipeline, no matter which products it uses, decomposes into four layers. Knowing the layers helps you swap vendors without rebuilding your process.
Layer one: source and transcription
This layer ingests footage, normalizes formats and frame rates, and produces a timestamped transcript with speaker labels. Whisper-class models handle most languages reliably, and the transcript becomes your search index. Everything downstream — moment selection, caption generation, b-roll suggestions — reads from it. Invest here. A clean transcript with accurate speaker turns saves more time than any generation model ever will.
Layer two: generation and patching
This is where text-to-video and image-to-video models live: Runway, Kling, Luma Dream Machine, Pika, Veo, Sora, and the open-weight options built on Flux and similar bases. Their job in a clipping workflow is not to make the whole video. It is to make the two or three seconds you could not shoot: an establishing shot, a product close-up, a transition, a reaction that your source footage lacks.
Layer three: assembly and timing
Traditional editors — Premiere Pro, DaVinci Resolve, Final Cut, CapCut — still own this layer, and they should. Generation models are bad at rhythm. The difference between a clip that holds and one that sags is often 12 frames of trim. Nothing beats a timeline for that decision.
Layer four: audio, captions, and delivery
This layer handles noise reduction, loudness normalization, music bed ducking, caption styling, and multi-aspect export. Tools like Descript, ElevenLabs for voice repair, and the caption engines built into CapCut or Resolve cover most needs. If you only improve one layer this quarter, improve this one — it has the highest ratio of perceived quality to effort.
Step-by-step: from raw footage to a publishable clip
Here is the workflow in the order that avoids rework. Skipping a step usually costs you twice the time later.
1. Intake and normalize before you edit anything
Convert everything to a single working codec and frame rate. If your source mixes 24fps, 30fps, and 60fps footage, pick 30fps as the project base and conform the rest. Set audio to 48kHz. Name files with a date and a subject tag rather than camera defaults. This ten-minute step prevents a class of sync drift problems that are nearly impossible to diagnose after you have cut three minutes of timeline.
2. Do transcript-first moment selection, not timeline scrubbing
Run transcription, then read rather than watch. Highlight candidate moments in the text. For interviews, look for complete thoughts that stand alone, a clear setup and payoff, and a sentence that could serve as a hook in the first two seconds. Aim for three to five times more candidates than you need. Selection is cheap in text and expensive on a timeline.
3. Build a shot list before writing a single prompt
For each selected moment, describe what the viewer needs to see at every beat. Most clips need four to seven shots. Identify which shots exist in your footage and which need to be generated. Generated shots should be the exceptions, not the spine. When generation carries too much weight, the clip starts to feel like a slideshow of unrelated renders.
4. Generate patch shots with tight, boring prompts
The best prompts for clipping are specific and unglamorous: subject, action, camera, lighting, duration, and what must not appear. "Medium shot, woman in charcoal blazer seated at a pale wood desk, hands gesturing, soft window light from the left, static camera, four seconds, no text, no logos." Vague cinematic language produces beautiful shots that will not cut against your real footage. Generate several takes, keep the one that matches your color and grain, and treat the model's framing suggestions as a starting point rather than a final answer.
5. Assemble on a real timeline and cut to rhythm
Drop your source footage first, then weave in generated shots. Keep generated segments short — two to four seconds — and place them where the viewer needs a breath or a spatial reset. Cut on motion and on speech beats. If a generated shot feels even slightly off, it will read as a mistake when surrounded by real footage, so cut it shorter or drop it.
6. Clean up audio before you fall in love with the picture
Noise reduction, high-pass filtering around 80Hz, light compression, and target loudness normalization. If a line is unusable, try repairing it with a voice model rather than re-recording; if repair fails, consider replacing the line with a caption card or cutting the sentence. Audio problems are perceived as video problems by almost every viewer.
7. Reframe, caption, and export in one pass
Auto-reframing works well when your source is high resolution and the subject is well separated from the background. Caption with a maximum of two lines on screen, sentence case, and a stroke or shadow so text survives bright backgrounds. Export a master at high bitrate, then derive vertical, square, and widescreen versions from it rather than exporting each from the timeline independently.
Writing prompts that produce editable footage
A prompt that produces an impressive standalone clip and a prompt that produces a usable insert shot are different prompts with different goals.
Editable footage is characterized by a stable camera, a simple background, predictable lighting direction that matches your scene, and physical behavior that does not call attention to itself. Avoid elaborate camera moves unless the shot exists purely as a transition. Avoid crowds and complex hand interaction, which are still the most common failure points across models. Specify duration explicitly, since default lengths rarely match the beat you need.
A useful habit is to keep a personal prompt library organized by shot type: establishing exterior, over-the-shoulder, product macro, reaction close-up, abstract transition. Once a prompt reliably produces usable footage in your color space, save it with the seed and reuse it. Consistency across a project comes more from reusing prompts than from any single consistency feature.
Also write negative instructions. "No watermark, no on-screen text, no extra fingers, no camera shake, no lens flare" saves you from regenerating shots that are technically perfect and completely unusable.
Keeping characters consistent across clips
Character drift is the most visible failure in AI-assisted video, and it shows up in three places: face structure, wardrobe, and voice.
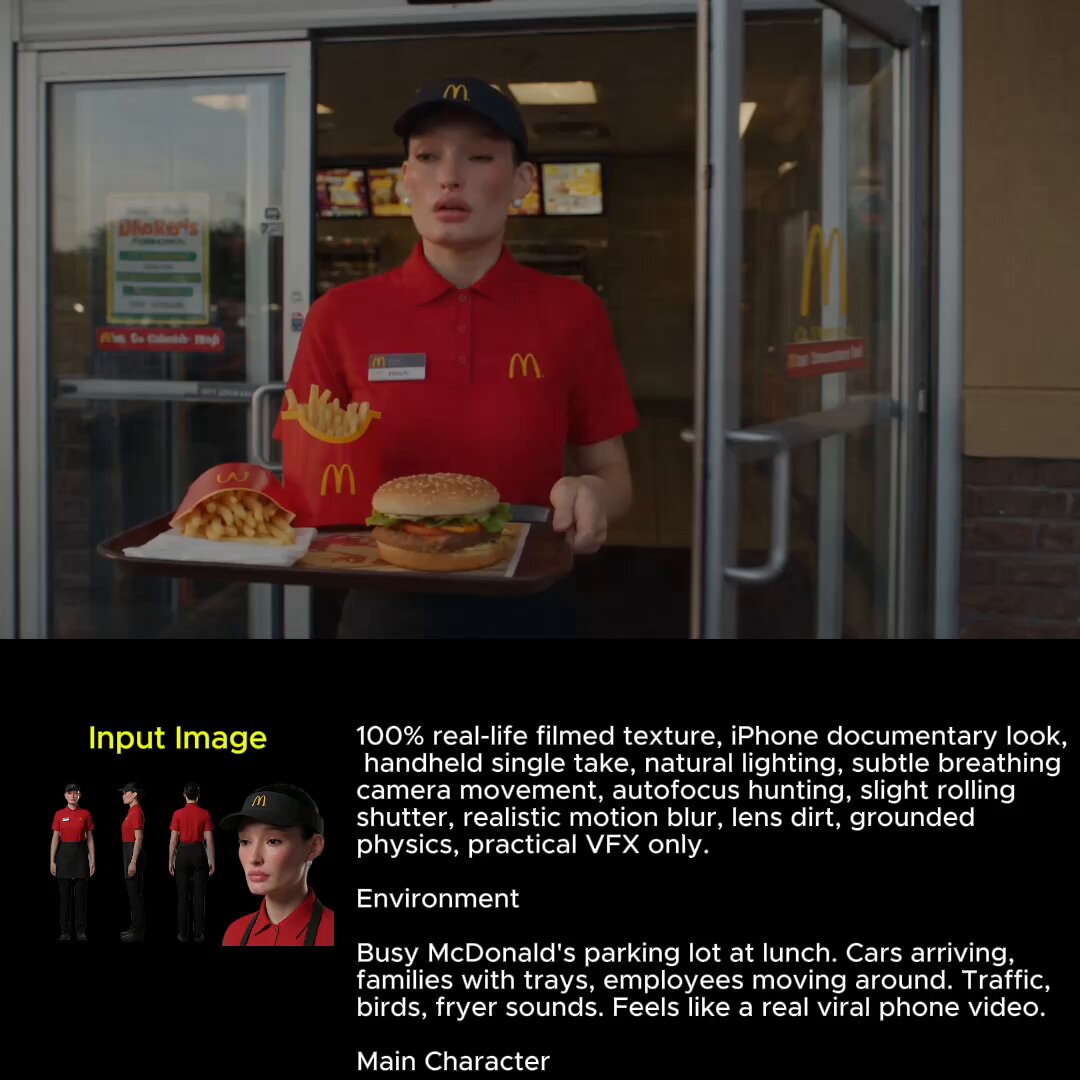
For face and wardrobe, start from reference images rather than text. Give the model three to five stills of the same person from different angles and under similar lighting, and keep those references locked for every shot in the project. Multi-image fusion features exist precisely for this. If your tool supports identity conditioning, use it; if not, generate one hero still and use image-to-video for every subsequent shot rather than re-prompting from text.
For voice, generate or clone once, then reuse the same voice profile across the entire project. Changing voice models mid-project creates an audible seam that viewers notice even when they cannot name it. Keep the delivery consistent too: a clone that is enthusiastic in one shot and flat in the next will feel like a different person.
Finally, plan your cuts around the weaknesses. If a generated shot drifts at second three, use two seconds of it. Consistency problems shrink dramatically when generated footage is treated as connective tissue rather than as the main performance.
Regenerate or repair? A decision framework
Every AI clipping session produces shots that are almost right. Deciding quickly whether to repair, regenerate, or cut saves hours.
Repair when the problem is superficial and localized: a slightly off color match, a missing caption, a small sync offset, a noisy syllable. Color correction, a trim, and a repaired word are all fast fixes. Repair is almost always the cheapest option.
Regenerate when the problem is structural: wrong wardrobe, wrong location, wrong action, a face that does not match. Structural problems cannot be graded away. Change one variable at a time — usually the reference image first, then the prompt — and cap yourself at three attempts. If three attempts fail, the shot concept is the problem, not the model.
Cut when the moment is not essential. This is the most underused option. Editors become attached to footage they have already generated, but a beat that does not serve the story is a beat that costs you attention regardless of how long it took to produce.
A simple rule keeps teams honest: if the fix takes longer than replacing the beat with a caption card or a different source shot, replace it.
Common mistakes that slow AI clipping down
Generating before writing. Producing shots before you have a shot list guarantees you will generate footage you cannot use. The transcript and the shot list are the real pre-production.
Mixing frame rates on the timeline. Sync drift and stutter are almost always a frame rate problem, not an AI problem.
Overusing generated footage. A clip that is 70 percent synthetic will feel hollow even when every individual shot is good, because the texture never varies.
Chasing perfection on a throwaway variant. If you are testing three hooks, two of them are supposed to lose. Do not polish a variant you already plan to discard.
Skipping caption QA. Auto-captions mangle names, numbers, and product terms. Ten minutes of proofreading prevents a correction post later.
Ignoring loudness targets. A clip that is 6dB quieter than everything else in the feed loses viewers in the first two seconds, no matter how good the edit is.
Not backing up project files and prompts. When a client asks for a revision three weeks later, a recoverable project with saved prompts is worth more than a fast first pass.
Quality control checklist before you publish
Run this list every time. It takes ninety seconds and catches most embarrassing errors.
- Watch the clip once with sound off. Does it read? Does the hook land in the first two seconds?
- Watch once with your eyes closed. Is the audio clean, level, and free of clicks?
- Check the first and last frame. No black frames, no half-sentences, no abrupt audio cutoff.
- Confirm faces are stable across cuts. Look specifically at the jawline, hairline, and hands.
- Proofread every caption, including speaker names and numbers.
- Verify loudness, and confirm the export matches the platform's preferred aspect ratio and duration.
- Confirm rights and consent for any real person appearing in generated or modified footage, and label synthetic media where the platform or jurisdiction requires it.
FAQ
Do I still need a traditional editor if I use AI clipping tools? Yes, for anything beyond simple repurposing. Generation handles filling gaps; rhythm, pacing, and story judgment still live in a timeline. Most teams use AI for the first 70 percent of assembly and a human for the final 30 percent.
How long should a generated shot be? Two to four seconds in most short-form work. Longer generated shots expose drift, unnatural motion, and lighting inconsistencies. If a beat needs more time, cover it with two shots rather than one long one.
Can I use AI clipping on footage I did not shoot? Only with clear rights. Licensing, talent releases, and platform terms all still apply to AI-processed footage. When in doubt, get permission in writing before you modify someone else's material.
What is the biggest quality bottleneck? Audio. Viewers tolerate imperfect visuals far more than they tolerate room echo, clipping, or mismatched levels.
How many variants should I produce per clip? Three is usually the useful ceiling: one safe cut, one with a punchier hook, and one with a different opening shot. Beyond that, returns drop sharply and review time grows.
Does AI clipping hurt reach on platforms? Platforms generally rank on watch time and engagement, not on how footage was produced. The practical considerations are disclosure rules and audience trust, not algorithmic punishment.
What should I learn next to get better at this? Basic sound design, color matching, and caption typography. Those three skills improve AI-assisted clips more than learning another generation model.
Where this workflow is heading
The direction of travel is clear: transcription, selection, generation, and assembly are converging into a single supervised pipeline. Instead of exporting from one tool to another, you will increasingly describe an outcome and review a draft.
The editors who thrive in that environment will not be the ones who know every model's strengths. They will be the ones who can define a shot list, judge a cut, catch a drift, and know when a real take beats a generated one. Build the workflow around those judgments, keep the tooling replaceable, and the specific products you use will matter far less than the process you run.
