
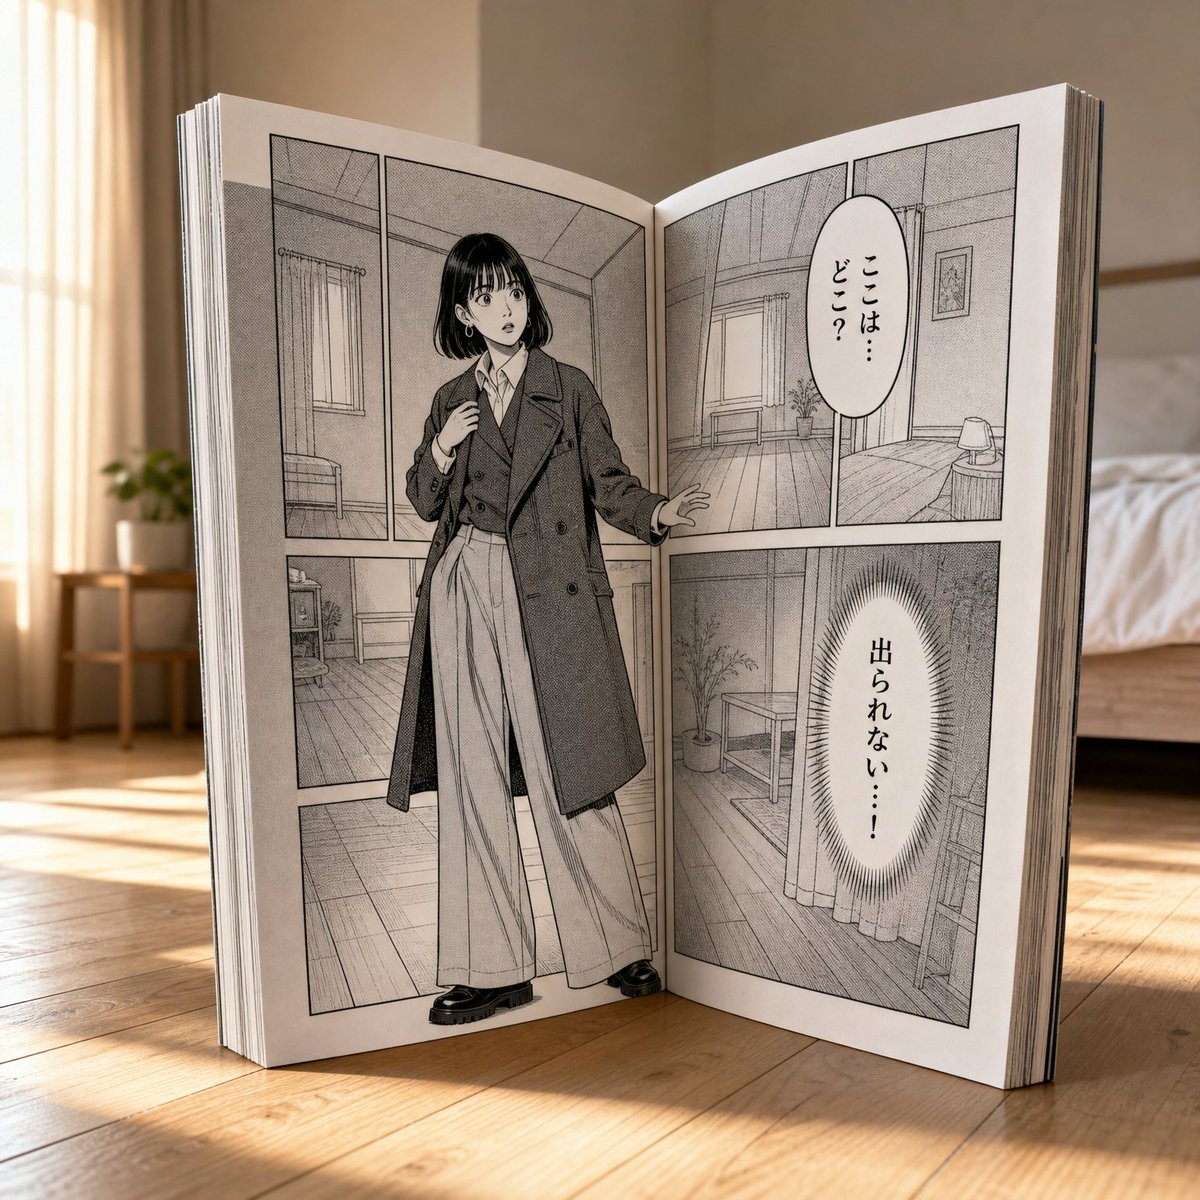
Start With the Shot, Not the Tool
Most disappointing AI video projects fail before a single frame is generated. The failure happens at the very first step, when someone opens a text-to-video tool, types a poetic sentence, and hopes the model will infer the story, the pacing, the camera language, and the edit. It rarely does. The tools are astonishing, but they are generators, not directors. They respond to specificity and punish vagueness.
The alternative is a shot-first workflow. Before you touch any model, you write a shot list the way a director and an editor would: what is on screen, how long it lasts, where the camera sits, how it moves, what the light does, and what the audience should feel at the cut. That list becomes the contract you hold every generation against. When a clip comes back wrong, you can name exactly which variable failed instead of guessing.
A useful shot brief is almost boringly concrete. For example: Shot 3 — 2.5 seconds, medium close-up, protagonist reads a letter beside a rain-streaked window, slow push-in, soft overcast key light, muted teal palette, ambient rain, no music. That single line tells you which model family to reach for, how many variations to render, and what the editor needs to receive. Multiply it by twenty shots and you have a production plan rather than a pile of experiments.
The rest of this guide covers how to build that plan into a repeatable pipeline: which layer of the workflow each tool belongs to, how to select a generation model by shot type, how to structure prompts that survive iteration, and how to run quality control so the final export does not embarrass the team.
The Five Layers of an AI Video Pipeline
Amateur workflows treat AI video as one big button. Professional workflows treat it as five distinct layers, each with its own tools, review step, and failure modes. Separating them is what makes a project reproducible instead of lucky.
Concept and script layer
This is where the story, the beat structure, and the shot list live. Output: a script, a shot list, and a style reference board. No generation happens here, and that is intentional. Every hour spent clarifying the shot list saves several hours of re-rendering later.
Keyframe and reference layer
Still images define look, character, wardrobe, and composition. Modern image models handle this layer far better than video models handle motion and consistency simultaneously, so it pays to lock the look as stills first. A locked keyframe gives the motion model something to interpolate from instead of inventing from nothing.
Motion generation layer
This is the layer most people mean when they say "AI video": text-to-video, image-to-video, and video-to-video generation. Motion models vary enormously in how they handle camera movement, human anatomy, text rendering, and shot length. Matching shot type to model is the single highest-leverage decision in the whole pipeline.
Assembly and edit layer
Generated clips are footage, not a film. They need trimming, speed ramps, transitions, colour matching, and rhythm. A conventional timeline editor still does this best; the AI layer simply replaces the camera crew.
Sound and finishing layer
Dialogue, voice synthesis, ambience, foley, music, and mixing. Audio is where low-effort AI videos most often reveal themselves, because the visuals move like cinema while the sound sits flat and unmotivated.
Choosing a Generation Model by Shot Type
No single model wins every category. The professional habit is to keep two or three options in rotation and route each shot to the one that fits.
Cinematic realism and camera control
When a shot depends on believable physics, natural lens behaviour, or a specific camera move — a slow dolly, a handheld follow, a rack focus — reach for the cinematic-realism class of tools, the group that includes Runway and Sora-style generators. These models tend to render depth, light falloff, and material detail convincingly, and they respect camera instructions inside the prompt. They are usually the most expensive and slowest options, so reserve them for hero shots that carry the story.
Character consistency and dialogue-driven scenes
Shots that must hold a face, a costume, or a prop across several cuts need a model with strong reference conditioning. Kling-class and PixVerse-class tools are often the better fit here, especially when you can supply a reference image or a first frame. If a scene requires a speaking character with synchronised lip movement, look for native audio or lip-sync support rather than trying to fake it in post.
Fast iteration and budget shots
Establishing shots, inserts, background plates, texture passes, and anything that will be heavily blurred or sped up do not need the premium tier. MiniMax Hailuo-class and Luma Ray-class models deliver excellent value for iteration, and their speed makes them ideal for exploring composition before committing to an expensive render.
Still image models that feed motion
A Flux-class image model or a comparable diffusion model handles keyframes. This is where you lock character design, wardrobe, colour palette, and composition. Generating ten keyframe variations costs far less than generating ten video variations, so do your visual exploration in stills and only animate the winners.
| Shot need | Best-fit model class | Why |
|---|---|---|
| Hero shot, cinematic camera move | Cinematic-realism class | Best physics, lens behaviour, and motion fidelity |
| Recurring character across cuts | Reference-conditioned class | Holds identity, wardrobe, and props |
| Establishing shot, insert, plate | Fast economy class | Cheap, quick, good enough under motion or blur |
| Dialogue with visible speech | Audio-native class | Lip sync without manual post work |
| Keyframe and look lock | Still image class | Cheapest way to explore composition |
Prompt Layering: The Structure That Actually Works
Free-form prompting produces inconsistent results because the model has to guess your priorities. A layered prompt removes that guesswork. Write in a fixed order so you can change one variable at a time and know what caused the difference.
The order that holds up across most generators is: subject, action, camera, lens and format, lighting, mood and palette, continuity anchors, and negative constraints. Here is a filled example:
A woman in her thirties in a charcoal wool coat, reading a folded letter. She looks up slowly, eyes moving left to right. Slow push-in from medium shot to close-up. 35mm lens, shallow depth of field, 24fps cinematic cadence. Soft overcast daylight through a rain-streaked window, cool key from the left. Muted teal and grey palette, quiet melancholy. Same coat, same window, same overcast light as the previous shot. No on-screen text, no extra people, no fast camera shake.
Three habits make this structure work in practice. First, keep continuity anchors in every prompt for a sequence — same coat, same window, same light — because generators drift between shots otherwise. Second, state negative constraints explicitly; most models honour them better than you would expect. Third, change only one layer per iteration. If you alter the lighting and the camera at once, you learn nothing from the result.
A Practical End-to-End Workflow
Here is the sequence that a small team can run repeatedly without renegotiating the process each time.
- Lock the script and shot list. Assign each shot a duration, a purpose, and a priority tier: hero, supporting, or filler.
- Build a reference board. Collect ten to twenty stills that define palette, lens feel, and production design.
- Generate keyframes. Use a still image model to produce two or three composition options per hero shot. Get approval before animating.
- Write layered prompts. One prompt per shot, in the fixed order described above, saved in a shared document so anyone can reproduce it.
- Route shots to models. Hero shots to the cinematic class, consistency-critical shots to the reference-conditioned class, filler to the economy class.
- Generate three to five variations per hero shot. Never accept the first output; variation is how you find the one that cuts cleanly.
- Select with the edit in mind. Judge clips by how they cut against their neighbours, not in isolation. A shot that looks weak alone often lands perfectly in sequence.
- Assemble on a timeline. Trim hard. Generated clips are usually too long and too slow; cutting two seconds often saves a shot.
- Layer sound. Record or synthesise dialogue first, then ambience, then foley, then music. Mixing in that order prevents music from masking problems.
- Grade and finish. Match colour across clips, add grain or a subtle grade to unify sources, and check the export at the target viewing size.
Audio, Dialogue, and Lip Sync
Audio is the fastest way to make AI video look amateur, or to make it look finished. The most common mistake is generating visuals first and trying to fit sound afterwards, which forces compromises on timing. Work in reverse when a scene has speech: write the line, generate or record the voice, set the timing, and only then generate the visual performance to match.
For characters who speak on camera, decide early whether you are using a model with native synchronised audio or a separate lip-sync pass. Native audio is simpler and more coherent but limits your model choices. A separate pass gives you flexibility but introduces a handoff where identity drift creeps in.
For non-dialogue scenes, treat sound as three beds. Ambience establishes place — rain, traffic, room tone, wind. Foley establishes physicality — footsteps, fabric, a cup set down. Music establishes emotion. If a shot feels flat despite good visuals, the problem is almost always a missing ambience layer, not a weak image.
Quality Control: The Pre-Export Checklist
Run the same checks on every project. Consistency beats cleverness.
- Anatomy and hands. Check every visible hand, especially at the first and last frames.
- Eye direction and blinking. Unnatural gaze is the most common tell in close-ups.
- Text and signage. Regenerate or replace with a graphic overlay; most models still struggle with legible lettering.
- Motion continuity. Watch the cut points: does movement flow across the edit or restart awkwardly?
- Colour consistency. Compare clips side by side, not sequentially. Drift is invisible one at a time.
- Frame edges. Generated backgrounds often warp at the borders; crop or mask if needed.
- Duration discipline. Cut every clip to the shortest version that still reads.
- Audio sync. Check lip sync at half speed, where errors are obvious.
- Loudness. Normalise dialogue, then let ambience and music sit beneath it.
- Export settings. Confirm resolution, frame rate, and bitrate against the delivery platform's recommendation.
Mistakes That Waste the Most Time
Generating before designing. Jumping into motion generation without locked keyframes multiplies your spend and your revision count, because you are exploring look and motion at the same time.
Using one model for everything. Premium cinematic tools are wonderful and expensive. Using them for background plates is a straightforward waste.
Changing multiple prompt variables at once. You lose the ability to diagnose failures and end up rerunning shots you had already solved.
Ignoring the edit during generation. A clip that looks impressive alone can be uncuttable in sequence. Always generate with the neighbouring shots in mind.
Accepting the first output. The first generation is a draft, not a shot. Budget for variations on anything that carries the story.
Skipping sound design. Silent drafts hide audio problems until the final review, when fixes are most expensive.
Team Handoff and Versioning
AI video projects generate enormous numbers of files quickly, and disorganisation costs more time than rendering does. Establish a naming convention on day one: project, sequence, shot number, model used, version. Something like ep02_sc04_sh012_kin_v3 tells an editor everything they need without opening the file.
Keep a shot tracker with five columns: shot number, assigned model, prompt version, selected take, and status. Status should be a small vocabulary — drafted, generated, selected, cut, approved. When someone asks what is left, the answer takes ten seconds instead of an afternoon.
Finally, archive the winning prompt next to the winning clip. The prompt is the most valuable asset a team produces, and the easiest to lose.
Planning Effort Before You Generate
Budget by shot tier rather than by total runtime. A ninety-second piece might contain four hero shots, ten supporting shots, and a dozen filler shots, and each tier needs a different amount of iteration. Hero shots may take five to eight generations and a round of keyframe refinements. Supporting shots usually need two or three. Filler shots can often be accepted on the first or second pass.
Estimate time per shot, not per minute, and add a fixed allowance for regenerating anything that fails quality control. Teams that plan this way finish predictably; teams that estimate by total runtime spend their last day re-rendering a single shot.
FAQ
Do I need multiple generation models to make a good video?
No, but almost every professional workflow ends up with two or three. Different models handle camera movement, character consistency, and speed differently, and routing shots accordingly is the simplest quality upgrade available.
How many generations should I plan per shot?
Three to five for hero shots, two to three for supporting shots, and one or two for filler. If you consistently need more than eight, the problem is probably the prompt or the keyframe, not the model.
Should I generate video or start from still images?
Start from stills whenever look and composition matter. Locking a keyframe is cheaper, faster, and gives the motion model a much stronger starting point.
How do I keep a character consistent across shots?
Lock a reference keyframe, repeat continuity anchors in every prompt, keep wardrobe and lighting descriptions identical, and route those shots to a reference-conditioned model rather than a generic one.
Is AI video good enough for client work?
For many short-form, advertising, and explainer formats, yes — provided the edit and sound design are handled properly. The remaining weak points are long continuous takes with complex motion, legible on-screen text, and highly specific physical interaction.
What is the biggest quality lever?
Editing discipline. Ambitious teams lose more quality to loose cutting and unfinished sound than to any limitation of the generation models themselves.
How do I keep the pipeline repeatable as tools change?
Document the workflow, not the software. If your process is defined by shot tiers, layered prompts, and a fixed review order, swapping one generator for another becomes an afternoon's work instead of a rebuild.
